Amazon’s best MacBook Air deals deliver prices as low as $1,199 for M5 models, with discounts of up to $150 off.
A 30-day low price is in effect on Apple’s M5 13-inch MacBook Air in your choice of Silver or Midnight, bringing the cost down to $1,199. This standard configuration has a 10-core CPU, 8-core GPU, 16GB of memory, and 512GB of storage, but you can also save triple digits on higher-end retail models during Amazon’s laptop sale.
Another Y Combinator Demo Day took place on Thursday, but this batch looked a little different. While every cohort brings a fresh wave of founders, the startups presenting this week skewed far more toward deep tech than in past years.
As we do every quarter, TechCrunch asked early-stage VCs to name the hottest startups in this batch — both their top picks and the deals everyone was talking about. And as usual, we put together a list of startups flagged by at least two investors as the buzziest in the batch.
The tech in this batch felt “like science fiction,” as one investor put it. But beyond the wild ideas, the consensus was that valuations were far more grounded than in recent cohorts.
What it’s building: Nuclear-powered data centers floating at sea
Why it’s a fav: Power is in short supply and local communities are increasingly opposing the buildout of new data centers. Atomarine — co-founded by an MIT computer science and naval engineer and an MIT PhD in nuclear engineering — wants to solve the compute shortage by putting data centers on barges at sea, where seawater could provide near-free cooling. The startup plans to launch a gas-powered pilot by 2028 and plans to transition to floating nuclear power ships in 2032. Atomarine claims it has already secured over $4 billion in customer interest through letters of intent. That revenue potential has helped make it one of the highest-valued startups in the batch, one VC told TechCrunch.
What it’s building: Effective and energy-efficient high-speed optical networking hardware for AI data centers
Why it’s a fav: The idea is that GPU clusters waste a lot of compute time simply waiting for data to move between each chip. Within the networking layer, data is converted from light to electricity and back again in a process that burns lots of power and yields lots of heat. But Dipole Labs says it built an optical switch that skips the conversion so the data can stay as light and go directly where it needs to go. It’s a timely problem to tackle as GPUs are crazy expensive and data centers want the most out of their compute hardware without leaving any time to spare.
What it’s building: Locally producible, jet-powered strike and counter-drones
Advertisement
Why it’s a fav: Isengard aims to mass-produce jet-powered attack and counter-drones directly within allied countries, at a fraction of what prime contractors charge to build them in the U.S. Co-founded by a former Australian Army officer and a defense entrepreneur who previously scaled another Ukraine-focused drone startup to $60 million in revenue, Isengard is already generating $10 million in revenue itself. The startup has generated strong VC buzz, garnering one of the loftiest valuations in this YC batch, according to two investors.
What it’s building: Custom inference chips with hardcoded AI model weights
Why it’s a fav: Traditional AI chips burn massive amounts of energy during inference, fetching model weights from memory. Co-founded by an Imperial College London AI Ph.D. and an Oxford theoretical physicist, Lamb Labs wants to build ultra-efficient chips by hardcoding AI model weights directly into silicon. Dubbed “Model Processing Units” (MPUs), these custom chips eliminate memory-bandwidth bottlenecks.
What it’s building: Collecting real-world data on which to train robots
Why it’s a fav: This company partners with businesses to collect videos and data of humans doing work, which it then turns into training material for companies building robots. It says it’s already working with publicly traded companies and has captured video data in more than 150 different environments. This company could become important as businesses start experimenting more with which tasks are best for humans — and, as AI continues to refine itself, which tasks are better left to a robot.
What it’s building: Creating affordable robots to handle everyday tasks
Why it’s a fav: Launched just six weeks ago, this company already touts almost half a million in sales. That’s not shocking — it’s a humanoid robot that is promising to help clean and fold clothes. Users can also operate their robot via a laptop app. It’s priced at around $1,600, which is a steal compared to other humanoids like Neo, priced around $20,000. One of the biggest questions in robotics is if it is possible to create an affordable at-home robot that can actually stack a dishwasher and do everyday home tasks. Nori is another swing at taking on the task.
What it’s building: Autonomous robots that can lift heavy objects
Advertisement
Why it’s a fav: The founders of this company want to build a city on Mars. The first step to that? Building robotic technology that performs heavy-duty tasks. It says its tech is already installing solar panels across the U.S. and that it has $25 million in contracts through 2027. The vision is that this technology can help automate construction for colonizing Mars. The startup is racing with SpaceX’s timeline for building on Mars, as it hopes to begin an exploratory mission by 2028.
What it’s building: Training human brain cells to one day power compute
Why it’s a fav: Another company trying to find the best way to tackle how much power and energy is needed to run models. This time, Parasma is looking at using human brain cells as an effective, more energy-efficient alternative to today’s AI computing hardware.
What it’s building: An API layer that writes robot control code
Why it’s a fav: Investors and tech enthusiasts are hoping that the ChatGPT moment for robots is around the corner. That excitement is driving different approaches to creating a general robotics model. Instead of training foundation models on raw video or human teleoperation data, Waddle Labs uses a layer of LLM agents to write code and control robots directly. The startup, founded by Harvard graduates, is positioning itself as “Claude Code for robotics.” The startup claims that by plugging any hardware into Waddle’s API, developers will be able to tell the robot what to do in natural language, and its AI agents will autonomously generate executable control code, check that it worked, and set up the robot in about 20 minutes.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
Apple recently unveiled the Apple Watch Series 12, its latest flagship smartwatch. The Apple Watch Series 12 isn’t too different from its predecessor, the Apple Watch Series 11, but that’s not necessarily a bad thing. The most important thing that didn’t change is its price. The starting price still remains at $399.
If you’re looking to save money, however, it’s worth looking at Apple’s more economical smartwatch offering, the Apple Watch SE 3, which starts at just $249. It doesn’t have the same level of features as its pricier siblings, but if all you want is a capable fitness wearable, the Watch SE 3 is a pretty solid option.
Here’s a more detailed breakdown of how these two Apple wearables compare.
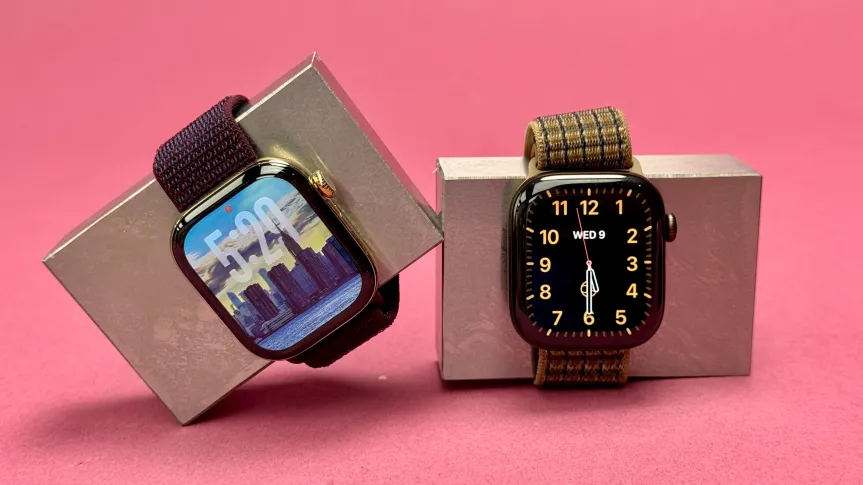
The Apple Watch Series 12, in gold titanium (left) and bronze aluminum.Vanessa Hand Orellana/CNET
Design and display
The Apple Watch Series 12 looks and feels very similar to its predecessor, the Apple Watch Series 11. It has a rectangular OLED Retina display (up to 2,000 nits of brightness), rounded edges, and it comes in 42mm and 46mm sizes. In addition to aluminum and titanium, the Apple Watch Series 12 now also comes in ceramic, a callback to the Apple Watch Series 5 in 2019.
It’s worth noting that the ceramic version is quite a bit heavier. While the 42mm aluminum model is 32.2g, the titanium is 36.5g, the pearl white ceramic is 41.7g (interestingly, the night blue hue of the ceramic is 42.8g).
Advertisement
Speaking of which, the Apple Watch Series 12 comes in a variety of colors depending on the case. The aluminum comes in dark bronze, light gold, black and space gray, the titanium comes in radiant gold and natural hues, while the ceramic comes in the aforementioned pearl white and night blue.
The Apple Watch SE 3 also has a rectangular display design with rounded edges, but it comes in 40mm and 44mm sizes instead. Rather than an OLED Retina display, the SE 3 uses an always-on LTPO OLED display that gets up to 1,000 nits of brightness. It doesn’t refresh quite as often as the Series 12, however.
The SE 3 comes in 100% recycled aluminum in either midnight or starlight colors. It’s also very lightweight compared to the Series 12; it weighs only 26.4 grams (40mm) or 33 grams (44mm).
Both watches are IP6X-rated for dust and water resistance up to 50 meters. The Series 12 has Ceramic Shield 2 glass, while the SE 3’s cover glass is made out of Ion-X and is four times more resistant to cracks than the SE 2.
Advertisement
Sleep tracking on the Apple Watch SE 3.
Vanessa Hand Orellana/CNET
Health and fitness features
The Series 12 has many of the same sensors as the Series 11, including a second-generation electrical heart sensor, an always-on optical heart sensor, and a temperature sensor. Though it doesn’t have on-the-spot blood pressure monitoring, it can analyze data and detect signs of hypertension, which can help your doctor make a diagnosis.
The SE 3, on the other hand, lacks the electrical heart sensor found on the Series 12, so it can’t take heart readings using the ECG app or detect signs of atrial fibrillation. It does, however, have a second-generation optical heart sensor that can track heart rate during exercise or sleep. In other words, if all you want is a wearable that will track your heart rate during a workout, the SE 3 could be good enough.
Though both watches are water-resistant, the SE 3 lacks a water temperature sensor and a depth gauge, whereas the Series 12 does. The Series 12 is therefore a better option if you want to track swim workouts or dives more effectively.
Both watches offer emergency features like fall detection, emergency SOS and crash detection.
Advertisement
Battery life and specs
Both watches have a decent battery life. The Apple Watch Series 12 offers 24-hour battery life and fast charging from 0% to 80% in just 30 minutes. The Apple Watch SE 3, meanwhile, has an 18-hour battery life but can fast-charge to 8 hours of normal use in just 15 minutes.
The SE 3 ships with an S10 chip with a 64-bit dual-core processor and a W3 Apple wireless chip, plus 64 gigabytes of storage. It doesn’t have Apple’s second-generation Ultra Wideband chip, which supports precise location tracking, but you can still use Find My on an iPhone to see if it’s with you. You just won’t be able to pinpoint its location exactly by getting closer to it.
The Series 12 has an Ultra Wideband chip and Apple’s new S11 chip with a 64-bit dual-core processor, which enables features such as heart rate readings every 5 seconds.
Check out the chart below to further compare the Apple Watch Series 12 and the Apple Watch SE 3.
Aluminum: Dark bronze, Light gold, Black, Space Gray Titanium: Radiant gold, Natural, Ceramic: Pearl white, Night blue
100% recycled aluminum, midnight and starlight
Durability
IP6X dust resistant, water resistant to 50 meters, Ceramic Shield 2 glass
Cover glass is 4X times more resistant to cracks than the SE 2; made of Ion-X glass. Water resistant up to 50 meters.
Battery life
24-hour battery life; Fast-charge capable 0% to 80% in 30 minutes
All-day, 18-hour battery life; Fast charging with 8 hours of normal use in just 15 minutes on the charger.
Sensors
Health sensing system, second-generation electrical heart sensor, always-on optical heart sensor, temperature sensor, water temperature sensor, depth gauge and depth app to 6m, speaker, microphone with voice isolation, always-on altimeter, high dynamic range gyroscope, compass, waypoints, backtrack and elevation view, ambient light sensor
Emergency SOS, Fall detection, Crash detection, Check-in and Backtrack
Fall Detection, Crash Detection, Emergency SOS, and Check-In
AI & coaching
Apple Intelligence, Siri AI; Workout Buddy
Siri (voice assistant); Workout Buddy
Processor
S11 chip with 64-bit dual-core processor
S10 SiP with 64-bit dual-core processor, W3 Apple wireless chip
RAM/Storage
64GB (storage)
64GB (storage)
Payments
Apple Pay
Apple Pay
Price (US)
$399 to $949
$249 to $329
I started my career with CNET all the way back in 2005, when the (original) Motorola Razrs were all the rage. Since then, I’ve written about everything from consumer electronics to internet culture for outlets like CNET, Engadget and Yahoo. Outside of work, I’m a big fan of baseball, board games, tabletop RPGs and improv comedy.
See full bio
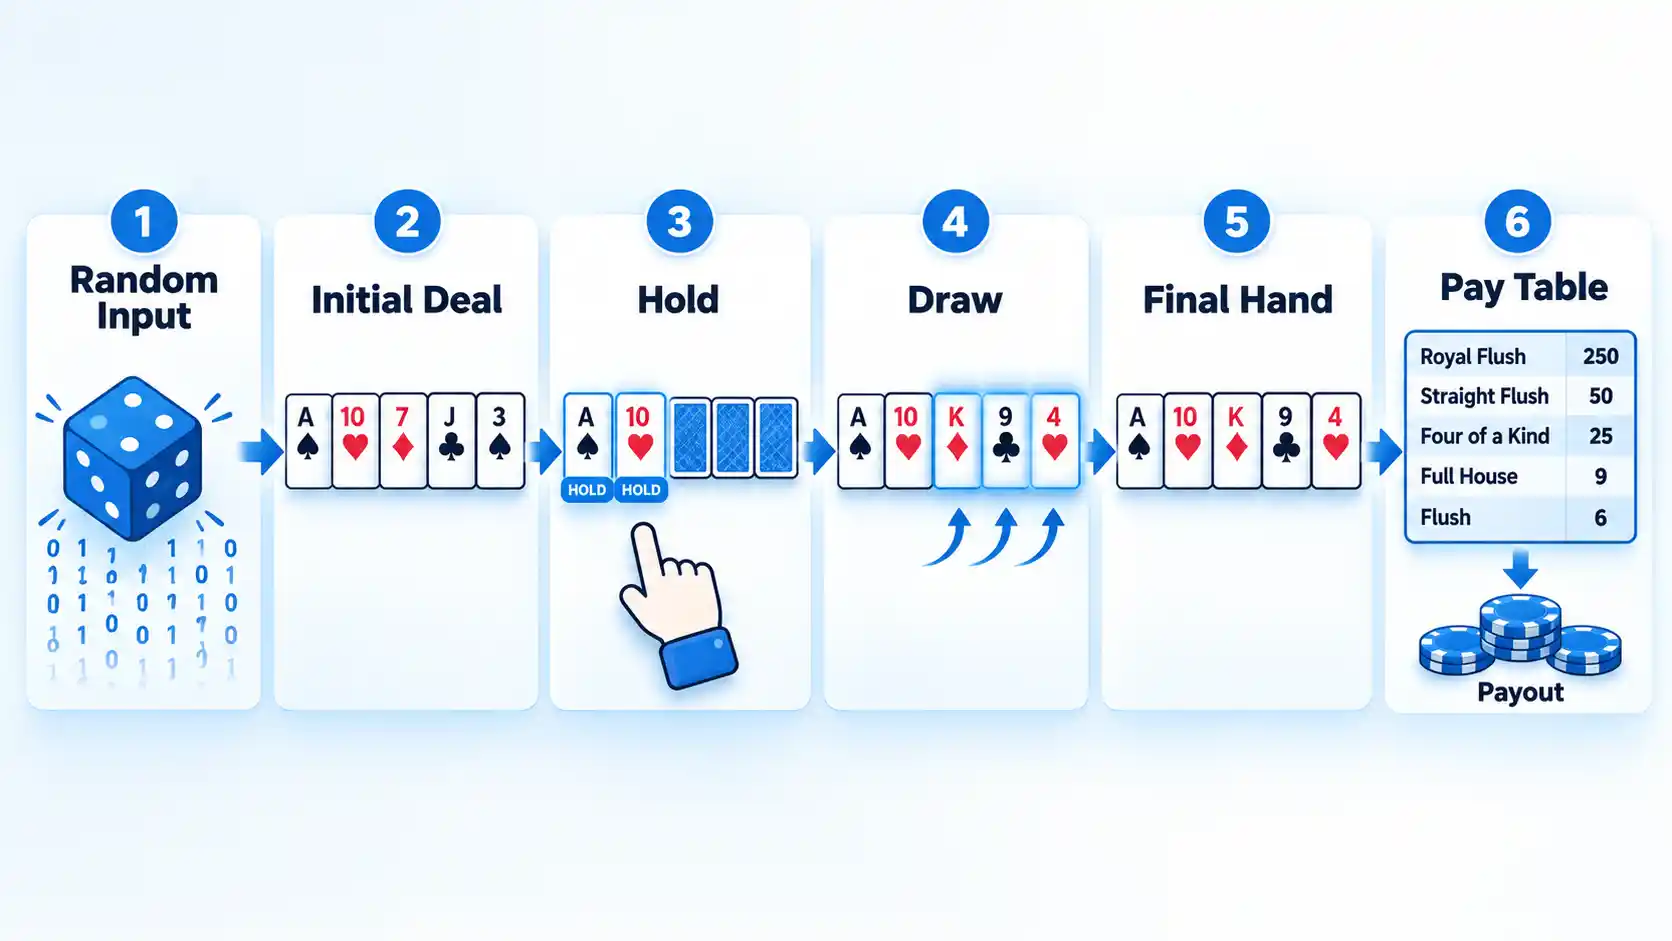
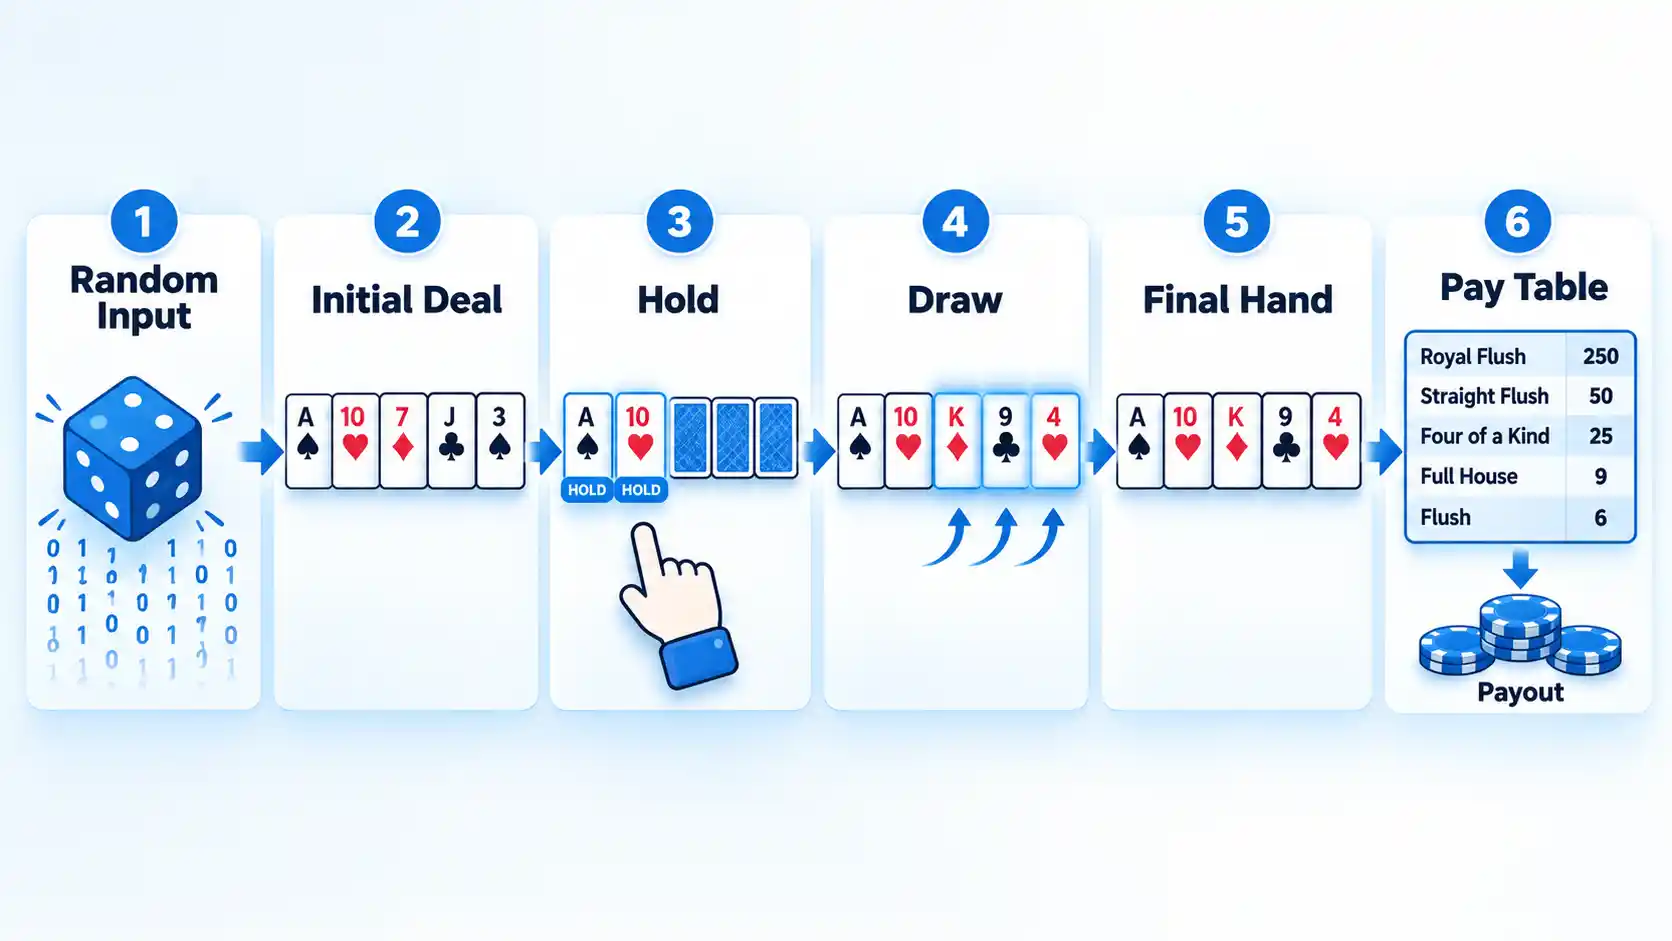
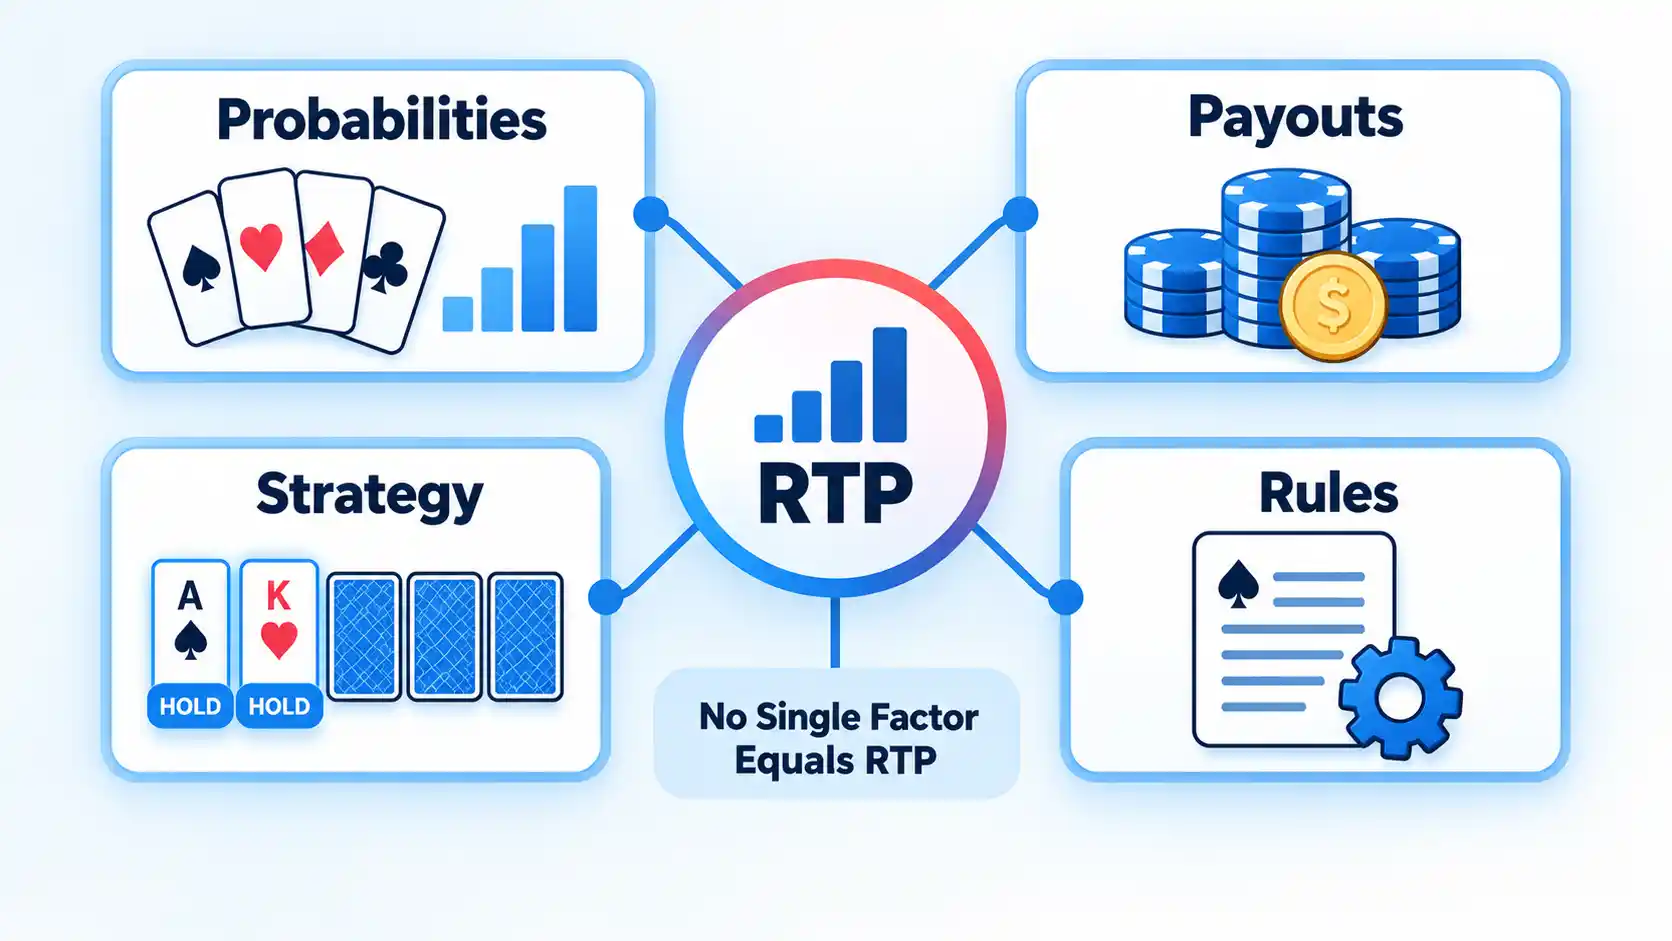
Video poker RNGs, pay tables and return to player (RTP) describe different parts of the same mathematical system. The RNG supplies random input, the game rules turn that input into cards and outcomes, the pay table assigns payouts, player decisions change which final hands remain possible, and theoretical RTP summarizes the long-run result under a stated strategy.
The Four Parts People Commonly Mix Up
The easiest way to understand video poker is to separate four mechanisms that are often treated as if they were the same thing: random number generation, game rules, player strategy, and the pay table.
A random number generator (RNG) produces unpredictable random inputs. Those inputs do not, by themselves, mean “win,” “lose,” “flush,” or “full house.” The game software maps the random inputs to cards or other game outcomes according to its rules.
A pay table specifies how much each qualifying final hand pays. A pair of Jacks may pay one amount per unit wagered, a full house another amount, and a royal flush much more. Changing those payouts can change the game’s theoretical return even when the random-selection process remains valid.
Advertisement
Strategy enters between the initial deal and the final result. You choose which cards to hold and which to discard. That decision changes the collection of final hands that can be reached from the current position.
Return to player, or RTP, is the designed long-run return under the game’s stated rules and assumptions. It is not a separate mechanism inside the machine that decides whether an individual hand wins.
The UK Gambling Commission makes an important distinction in its random-outcome technical standard: random inputs must be mapped to game outcomes according to prevailing probabilities and pay tables. That separates random generation from the rules that convert random inputs into meaningful game results.
The same distinction matters when common video poker myths are evaluated. A belief about streaks concerns randomness, while a claim about 9/6 versus 9/5 Jacks or Better concerns payouts. Mixing those layers produces misleading explanations.
Advertisement
What the RNG Actually Does
An RNG generates unpredictable random values. In a regulated implementation, the resulting random output and game outcomes must behave consistently with the probabilities the game claims to use.
The UK Gambling Commission requires applicable remote games to produce results that are “acceptably random.” Its standard says RNG output should be appropriately distributed and unpredictable, and that seeding or scaling methods should not introduce predictability. It also prohibits adaptive behavior that changes outcome probabilities during ordinary play.
That last point matters because the game is not permitted under that standard to become more generous after a losing streak or less generous after a win simply because of previous outcomes. Properly defined bonus or special features can use different disclosed rules, but that is different from secretly changing the probability of ordinary results.
The RNG is only one layer. A random value still has to be mapped to something meaningful in the game. In video poker, that mapping contributes to the selection of cards or outcomes under the game’s defined rules. The exact implementation can vary, which is why it is safer to explain the regulatory requirement than to claim that every machine uses one particular algorithm, sampling rate, or shuffle process.
Advertisement
The broader role of random number generators in digital casino games follows the same general principle: random generation supplies unpredictable input, while game-specific logic determines what that input means.
How a Video Poker Hand Moves From Deal to Draw
In conventional draw-style video poker, the visible sequence is straightforward. The game presents an initial hand, you choose which cards to hold, you initiate the draw, discarded positions receive replacement cards, and the final hand is evaluated against the pay table.
For example, suppose the initial hand contains two Jacks and three unrelated low cards. Holding the pair leaves three positions to replace. The replacement cards are selected according to the game’s random-selection process, and the resulting five-card hand is then evaluated for a payout.
One regulatory example makes the timing especially clear. Nevada Gaming Control Board Technical Standard 1 states that video poker games must not determine replacement cards before the player selects hold cards and initiates the draw. The same standard requires the RNG and random-selection process to be protected from outside influence.
Advertisement
That Nevada requirement should not be turned into a claim that every video-poker-style product worldwide uses an identical internal architecture. It establishes a documented rule for that regulated model. Other jurisdictions or nonstandard products may use different technical implementations while presenting a similar interface.
What a Pay Table Controls
The pay table answers a different question from the RNG: how much does each final hand pay? It does not determine which random cards arrive. Instead, it assigns value to the final outcome after the hand has been completed.
Jacks or Better provides a useful example because the same game family can use several payout schedules. The shorthand “9/6” means the referenced schedule pays 9 units for a full house and 6 for a flush per unit wagered under that structure. Other schedules change one or both of those payouts and therefore change the calculated return.
The table below uses figures from the current Jacks or Better return analysis. It illustrates how payout changes alter theoretical return rather than ranking one version as a recommended game.
Advertisement
Selected Jacks or Better pay tables and calculated optimal-strategy returns
Pay Table
Full House
Flush
Calculated Return
9/6
9
6
99.5439%
9/5
9
5
98.4498%
8/6
8
6
98.3927%
The relationship is visible immediately. The card game can still be called Jacks or Better, but a lower full-house or flush payout changes the weighted value of the outcomes and therefore changes theoretical RTP.
This is why reading the complete video poker pay table is more reliable than identifying a game only by its title. Even familiar shorthand describes only part of the payout structure, so the remaining rows still need to match the calculation being cited.
Why Strategy Changes RTP Even Though the Cards Are Random
Randomness and strategy are not opposites. The RNG controls which cards become available, while strategy controls what you do with the cards you have already been dealt.
Suppose an initial hand offers both a low pair and four cards to a flush. Keeping the pair creates one set of possible final outcomes. Discarding the pair and drawing to the flush creates another. The random draw remains uncertain in either case, but the probabilities and average value of those two decisions are not equal under the referenced 9/6 Jacks or Better pay table.
Advertisement
Expected value is the average mathematical value of a choice across many repetitions of the same situation. A play with the higher expected value is not guaranteed to win on the next hand. It simply performs better on average under the model’s assumptions.
The optimal strategy analysis for 9/6 Jacks or Better illustrates this directly. Its strategy ordering ranks four cards to a flush above a low pair for the relevant situation because the former has the higher average return under that pay table.
This relationship also appears in regulatory RTP guidance. The UK Gambling Commission’s RTS 3 rules on likelihood-of-winning information state that when a non-peer-to-peer game contains an element of skill, theoretical RTP should be calculated using either an auto-play strategy or a standard or published strategy.
That qualification is important. A published RTP for a skill-influenced game is tied to an assumed way of playing. Using a different strategy can produce a different player return even if the RNG and pay table remain unchanged.
Advertisement
How Theoretical RTP Is Calculated Conceptually
Theoretical RTP is better understood as an output of the game’s mathematics than as a setting controlled directly by the RNG.
At a conceptual level, each possible final outcome has two important properties: how often it occurs under the stated rules and strategy, and how much the pay table awards when it occurs. The contribution from an outcome is its probability multiplied by its payout. Add those contributions across the complete set of outcomes and you obtain the expected return.
In plain text, the idea is:
theoretical RTP = sum of each outcome’s probability × its payout
Advertisement
Video poker adds an extra layer because the player’s hold-or-discard choices influence the probabilities of the final hands. That means the theoretical calculation depends not only on the pay table but also on the assumed strategy.
For full-pay 9/6 Jacks or Better, Wizard of Odds calculates a total optimal-strategy return of 0.99543904, or approximately 99.54%. That figure is the combined contribution of all final outcomes under the stated rules and optimal strategy. It is not produced by instructing the RNG to “return 99.54%.”
This is the central relationship: the RNG supplies randomness, but theoretical RTP emerges from probabilities, payouts, rules, and player decisions working together.
Theoretical RTP Is Not Your Session Return
A theoretical RTP of 99.54% does not mean that wagering $100 produces exactly $99.54 in returned winnings during a particular session.
Advertisement
The UK Gambling Commission distinguishes theoretical RTP from actual RTP. Actual RTP can be measured by dividing recorded wins by turnover over a defined period. Its RTP calculation guidance gives a worked example in which a game designed for one theoretical percentage records a different actual percentage over a limited sample.
Volatility describes how widely results can vary around the mathematical average. A volatile game can produce substantial short-run deviations because outcomes do not occur in a perfectly even sequence.
The Commission’s guidance explains that the statistical tolerance around theoretical RTP is wider when only a limited amount of play has been measured and decreases as the volume of play grows. Larger samples therefore provide a more stable basis for comparing actual performance with the theoretical design.
That does not mean a particular person’s balance must converge to the published RTP after a specific number of hands. Statistical convergence describes behavior across large samples, not a repayment schedule for an individual session.
Advertisement
Why the Same Game Name Can Produce a Different RTP
A familiar name such as Jacks or Better identifies a game family, not necessarily one exact mathematical configuration.
The pay table can differ. The treatment of special hands can differ. Wild-card rules can differ. Maximum-wager payouts can differ. Even the handling of discarded cards can differ in an unusual implementation.
That is why an RTP figure should always be attached to a specific rule set and pay table. Saying “Jacks or Better returns 99.54%” without qualification is incomplete. The approximately 99.54% figure belongs to the full-pay 9/6 configuration under optimal strategy described by the cited mathematical analysis.
The same principle applies when comparing video poker with slots. Both categories can use random generation, but the way player choices, outcome probabilities and payout structures contribute to theoretical return differs by game design.
Advertisement
Important Exception: Not Every Video-Poker-Looking Game Uses the Same Draw Rules
Conventional Jacks or Better analysis assumes that discarded cards stay out of the draw pool for the remainder of that hand. That assumption matters because changing which cards can return on the draw changes the final-hand probabilities.
A documented nonstandard example analyzed by Wizard of Odds instead returned discarded cards to the deck before the replacement draw. Under those rules, a single 52-card deck is used, the player receives five cards, discarded cards are placed back with the remaining undealt cards, and replacement cards are then drawn.
The mathematical consequence is substantial. Using the listed 9/6 pay table, the with-replacement analysis calculates an optimal-strategy return of about 96.60%. On the same source page, conventional Jacks or Better with the same pay table and no replacement is calculated at about 99.54%.
Warning!
Advertisement
Do not assume that a familiar video poker name guarantees familiar draw mechanics. Check the game’s rule screen, pay table, treatment of discarded cards, wild-card rules and jurisdiction before applying an RTP or strategy figure calculated for another implementation. Some online gambling systems also use provably fair verification, which is a different transparency model from conventional regulator-tested game implementations.
This edge case is a useful reminder that RTP is inseparable from the rules used in the calculation. Identical-looking payout numbers do not guarantee identical probabilities if the draw mechanics are different.
How to Evaluate an RTP Claim Correctly
You do not need to reproduce the entire probability model to tell whether an RTP claim is properly specified. Check whether the figure identifies the assumptions that materially affect the calculation:
Exact game or variant: Jacks or Better, Deuces Wild and bonus variants do not share one universal model.
Complete pay table: small payout changes can alter theoretical return.
Wager assumptions: some schedules change payouts at specific wager levels.
Strategy assumption: a skill-influenced game’s theoretical RTP may assume optimal or another published strategy.
Draw and card rules: replacement, wild-card and special-feature rules can change outcome probabilities.
Type of figure: theoretical RTP and measured actual RTP are not interchangeable.
A common failure is copying the approximately 99.54% return associated with full-pay 9/6 Jacks or Better and applying it to a game that has a 9/5 or 8/6 schedule. Another is using a strategy designed for one pay table while quoting the optimal return for another.
The UK Gambling Commission’s rules reinforce this need for specificity. Applicable games must make information about their rules and likelihood of winning available, and for skill-influenced games the RTP calculation must be tied to an identifiable strategy basis.
Advertisement
Bottom Line
Video poker RTP is not something the RNG independently chooses. The RNG supplies unpredictable random input, the game rules map that input into cards, your hold-or-discard decisions affect the probabilities of final hands, and the pay table assigns value to those outcomes.
Combine those probabilities and payouts under a defined strategy and you get theoretical RTP. Change the pay table, strategy or draw rules and the result can change even when the random-number process remains valid. That is why a useful RTP figure always belongs to a specific game configuration rather than to a game name alone.
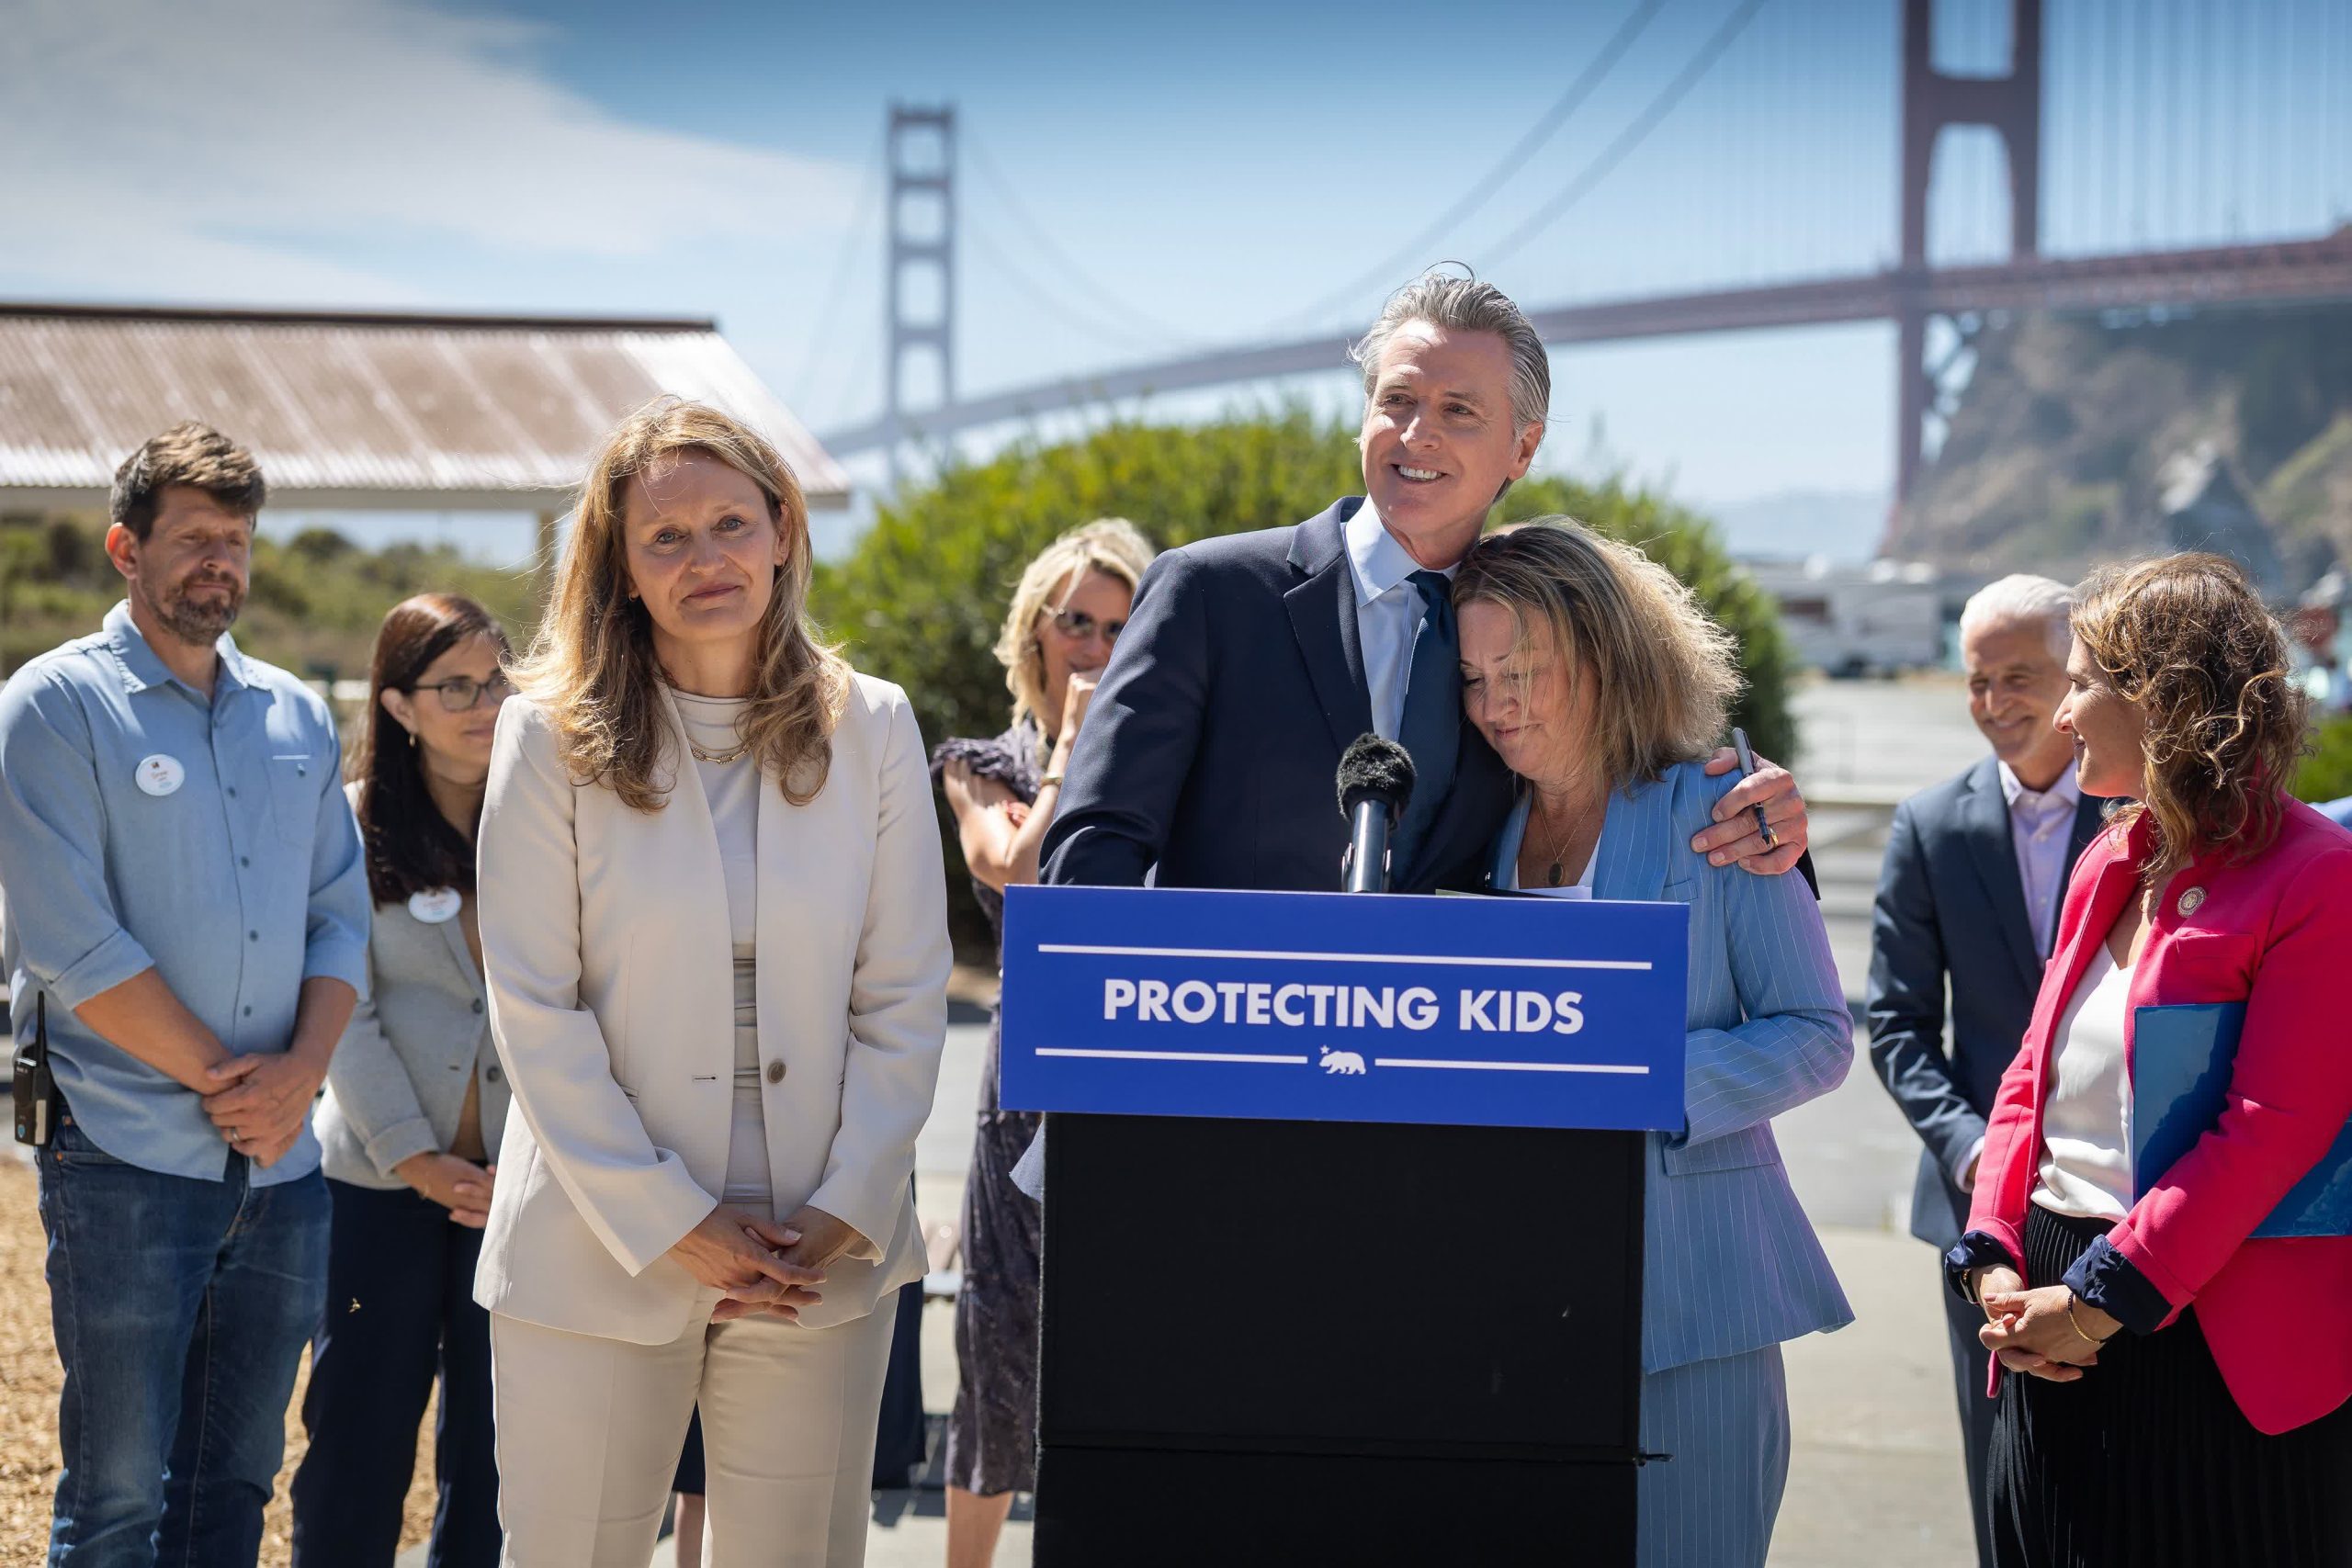
What just happened? California is tightening the rules on how tech companies keep children glued to their screens. Governor Gavin Newsom has signed a package of laws targeting addictive social media features and potentially harmful AI companions, with large platforms facing penalties of up to $1 million per child for negligently causing harm.
Newsom’s office describes the chatbot and social media protections as the strongest in the country, including the nation’s first requirements for independent child safety audits and annual risk assessments for companion chatbots.
The measures, which were signed on September 10, include AB 1709, which prohibits social media companies from offering addictive features to users under 16. That covers autoplay and algorithmic feeds built around a user’s history and profile.
“Innovation comes with responsibility and protecting our children comes first,” Newsom said.
Advertisement
The chatbot centerpiece is SB 1119, also known as Adam’s Law. Named after teenager Adam Raine, whose parents sued OpenAI over claims ChatGPT encouraged his suicide in 2025, it requires risk assessments before new or substantially modified companion chatbots are released, alongside independent compliance audits.
According to the bill’s authors, operators must use age-bracket signals supplied through operating systems. Default protections include usage limits, disabled notifications, and restrictions on persistent conversational memory, with changes reserved for parents.
Companies also face liability if they fail to take reasonable measures against harmful outputs, including sexual content, romantic roleplay, and emotional manipulation that encourages children to withdraw from friends and family. Crisis support and parental notification requirements address credible threats of imminent self-harm.
Families harmed by violations of specified protections can seek legal action. Operators must also implement incident reporting, while independent audit findings will be submitted to the California Attorney General.
Advertisement
“We cannot make the same mistakes that were made with social media,” said Senator Steve Padilla.
Last year, 44 attorneys general warned AI companies they would be held accountable for harm to children. That followed revelations about Meta’s internal chatbot guidelines permitting romantic exchanges with minors. Meta said the offending sections had been removed and were inconsistent with its policies.
Unsurprisingly, Meta isn’t happy about the new feed restrictions. The company argues that personalization helps it provide teenagers with relevant, age-appropriate content, according to the Associated Press.
“Personalization is also how we deliver age-appropriate content for teens that is relevant to them – all with the proper guardrails in place,” spokesperson Jim Cullinan said.
Advertisement
The package also restricts targeted advertising to children and the use of school pupil data in AI systems. Families will be able to opt out of school-issued laptops, too.
The signing follows two AI oversight laws approved on September 9. SB 813 establishes a framework for independent organizations to assess AI systems’ compliance with state law, while AB 1405 creates a registry of AI auditors and standards for their independence.
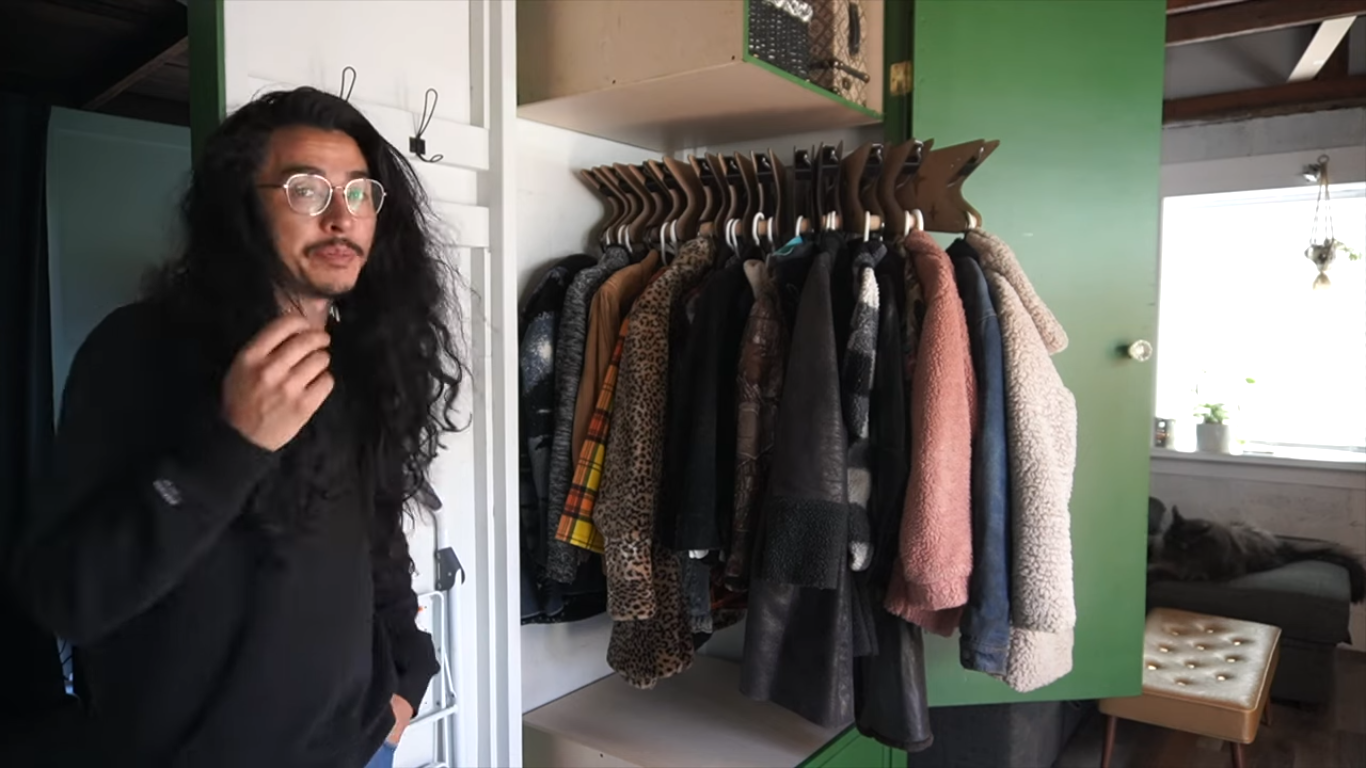
As any science YouTuber or first-year physics student is quick to point out, the universe is mostly empty space. Not just space itself, but the amount of “empty” space between nuclei and their electrons is also huge. Getting rid of this empty space results in all kinds of interesting phenomena like degenerate matter and black holes. But the concept can be extrapolated into our daily lives as well; many things are so filled with air that we can get a lot more usable storage space by compressing them down a little bit. [Super Valid Designs] took this concept to a coat closet, building one that can hold an impressive number of coats.
He started by looking at an existing closet, which could hold around 21 coats but only if someone used two hands to cram the coats into the space. After a trip to a store which sells rugs, he saw a much better design that lets all the rugs pivot like the pages on a book, and took this idea to his closet using a similar mechanism designed for storing large blueprints instead of rugs. The closet he built around this mechanism has two hinged doors which allow a person easy access to the coats, and when opened the blueprint hangers pivot out like a book, allowing the coats to not only be easily accessed without disrupting the other coats, but also allow them to be compressed down by the closet door for storage.
For comparison, the original closet could only hold 10 coats when restricted to single-hand operation and 21 when using both. The new closet design is smaller, and can hold 24 coats with a single hand and over 30 when using both, a dramatic improvement of closet efficiency. To top it off, a set of cupboards on top and bottom allow for storing shoes and hats as well, and there’s even a garage for a robotic vacuum cleaner. Surprisingly, we don’t see many closet optimization builds around here. The closest we can come is another traditionally small space, a college dorm.
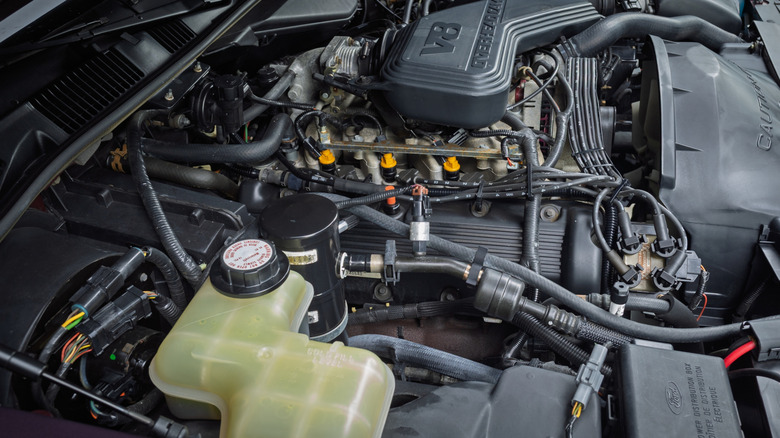
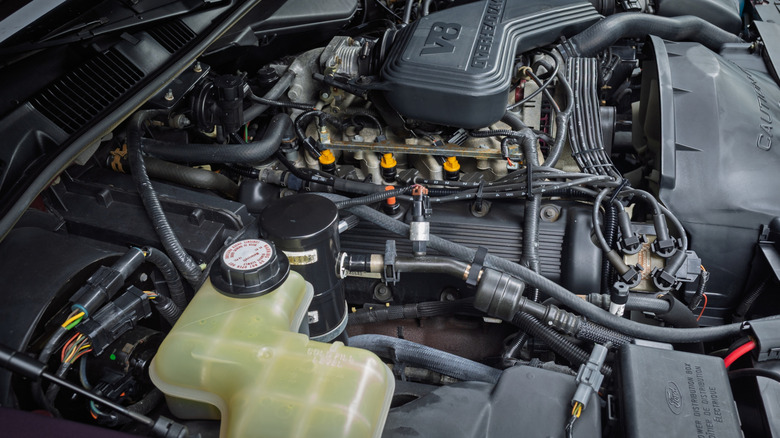
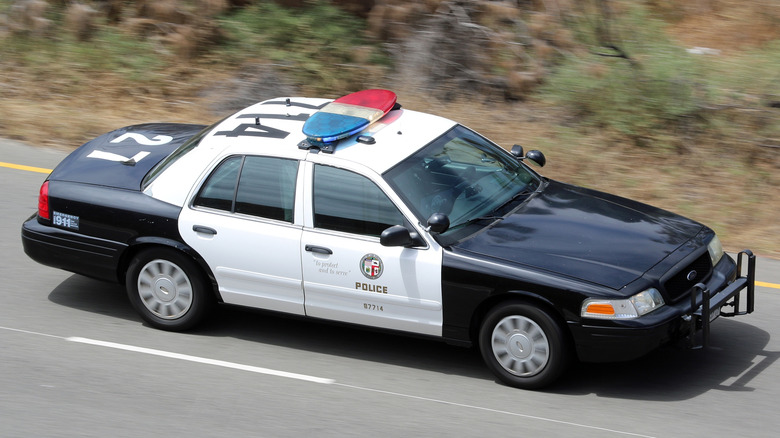
The Ford Crown Victoria is an American icon, instantly recognizable due to its prominence as a police car. In the 1990s, 85% of police cars in the United States and Canada were Crown Vics. That’s because this sedan is known for its body-on-frame build, simplicity, and reliability, making fleets affordable to run, fix, and replace. One reason for the Crown Victoria’s reliability was its engine, the Ford 4.6-liter V8.
This V8 was initially released in 1991 for the Lincoln Town Car and was used in later models like the Mustang GT and Crown Victoria. It was recognized throughout the years for its durability and solid construction until it was discontinued in 2014, replaced by the 5.0-liter Coyote V8. The 4.6-liter V8 was the first in Ford’s modular camshaft engine line — modular meaning the engine assembly was simplified, efficient, and easy to swap. While the engine gets a lot of respect now, it was actually a bit ridiculed back in the 1990s for its lack of power, as the 1992 Ford Crown Victoria only had 190 horsepower — 220 hp for police who equipped a dual exhaust.
Advertisement
Why did police use the Ford Crown Victoria?
A. Viduetsky/Shutterstock
Ford vehicles have been used by law enforcement since the 1910s, prompting Ford to even create police packages for some of their vehicles by the 1950s. These police trims came with modifications focused on speed, comfort, and safety. By 1961, 58% of police cars in the largest cities across the United States were using Ford vehicles. When the Mustang entered the service in 1982, Ford highlighted its fast acceleration, warning drivers that it could even catch exotic sports cars.
In 1983, police started adopting the LTD Crown Victoria, with its 5.8-liter V8 engine and police package. The Crown Victoria became its own model in 1992 and the police-focused Interceptor variant quickly became the majority of police cars in the U.S. and Canada by 1998. It continued to serve in the police force until 2012, not long after Ford discontinued the Crown Vic in 2011.
Even though police have used plenty of other vehicles — Ford and otherwise — since then, the Crown Victoria still gets respect for its time thanks to its speed, handling, good crash rating, pretty roomy cabin space, and ability to serve well past 200,000 miles with minimal and cheap maintenance. The 4.6-liter V8 also has plenty of endurance, making up for it not being the fastest in cars like the P71. For these reasons, you’ll still see some police departments using Crown Victoria sedans to this day.
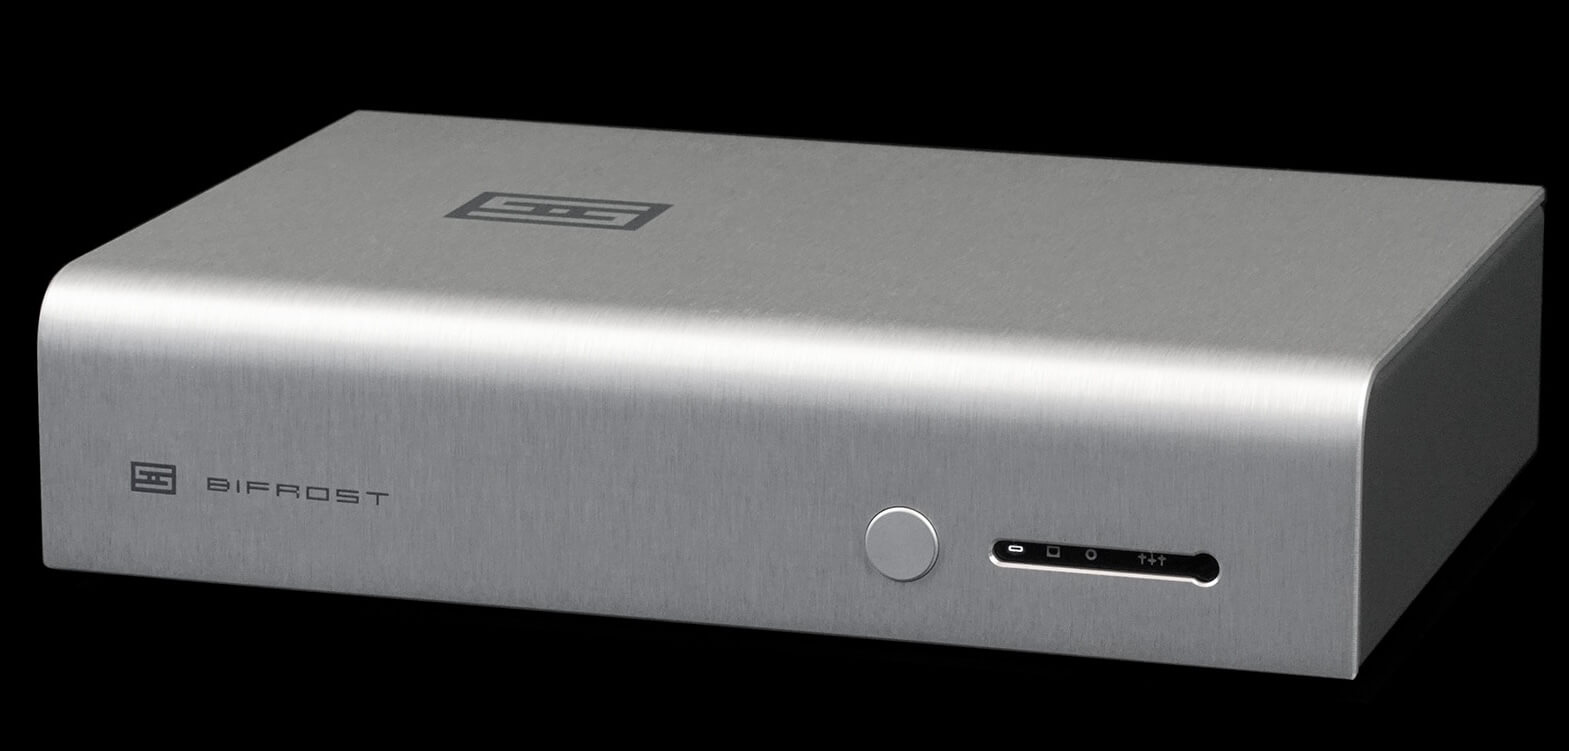
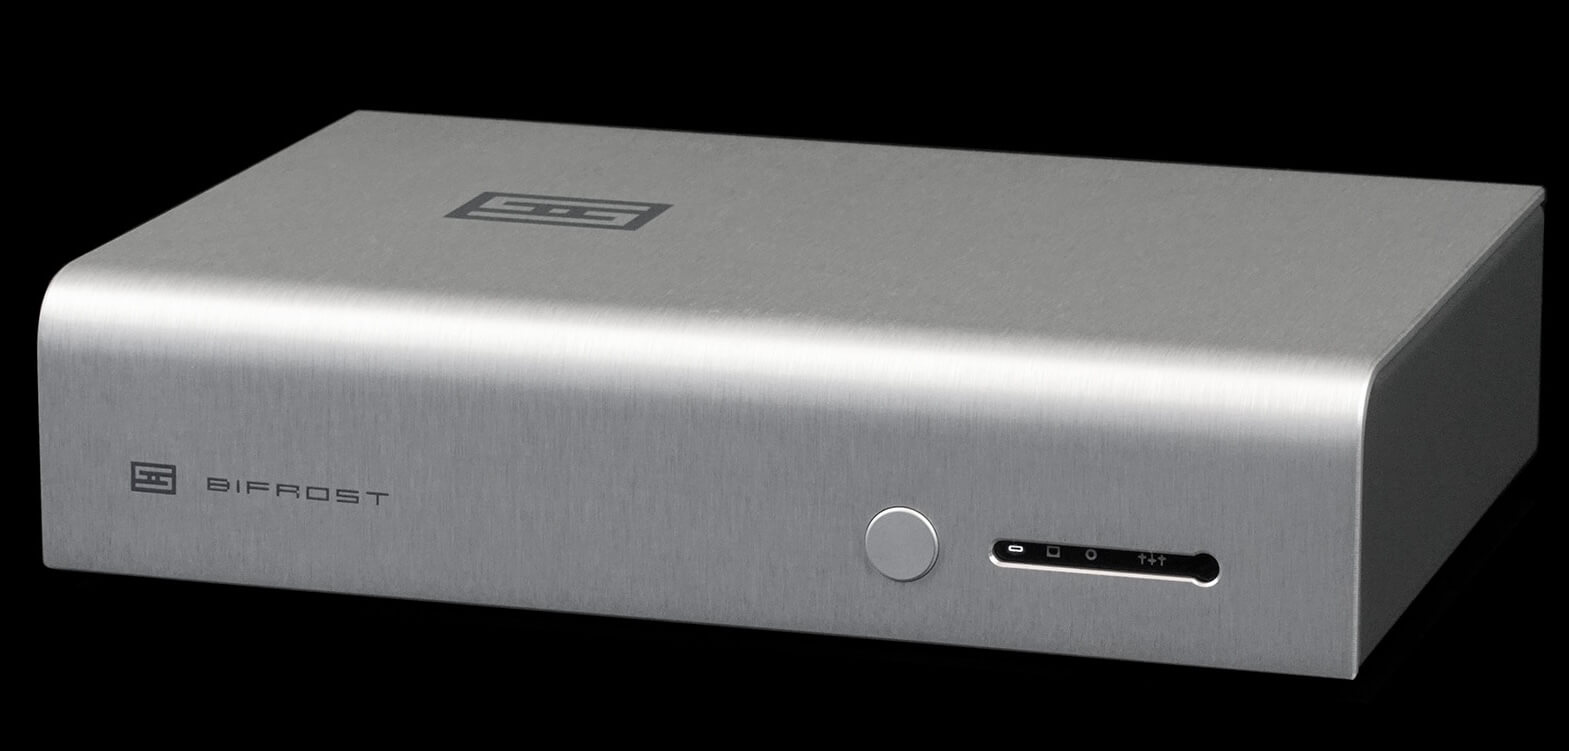
Schiit Audio has spent years convincing audiophiles that multibit DACs, proprietary digital filtering, modular hardware, and refusing to chase every new format were all perfectly sensible ideas. With the new Bifrost 3, the Texas manufacturer is keeping three of those ideas and making a rather significant change to the fourth.
Priced at $699 in black and $729 in silver, Bifrost 3 replaces the $799 Bifrost 2/64 as Schiit’s midrange standalone DAC. It adds 32-bit/384 kHz USB playback, Forkbeard control, parametric EQ, digital preamplifier functions, over-the-air firmware updates, and a new Mesh conversion architecture. Preorders require a refundable $10 deposit, with shipping expected around the end of October 2026.
And yes, it costs $100 less than the model it replaces. Somewhere an accountant has been asked to leave the audiophile industry.
What Happened to True Multibit?
Bifrost 2/64 used Schiit’s True Multibit architecture with four Texas Instruments DAC8812 converters in a hardware-balanced configuration. Bifrost 3 instead uses Schiit’s Mesh 8×39 architecture, combining the company’s proprietary time- and frequency-domain optimized digital filter running on an Analog Devices SHARC DSP with ESS ES9039 devices operating as delta-sigma modulators.
Advertisement
That does not mean Schiit has abandoned Multibit. Gungnir 2 and versions of Yggdrasil continue down that path, and the company says it intends to keep developing both multibit and hybrid approaches.
What has changed is Schiit’s belief that Mesh can now meet or exceed the subjective performance it has achieved from True Multibit while delivering stronger measured performance at a lower manufacturing cost. Schiit specifically credits its own SMD production line for helping reduce the price.
Translation: Schiit found another way to make a DAC it likes, and apparently decided ideological consistency was less important than whether the thing actually sounds good. How disappointingly rational.
Bifrost 3 Specifications
Price: $699 black; $729 silver
Conversion: Schiit Mesh with ESS ES9039 delta-sigma modulation
Digital processing: Proprietary Schiit filter on Analog Devices SHARC DSP
USB: Unison 384
USB resolution: Up to 32-bit/384 kHz PCM
Coaxial/optical: Up to 24-bit/192 kHz
Inputs: USB, coaxial S/PDIF, optical S/PDIF
Outputs: RCA and balanced XLR
Maximum output: 2V RMS RCA; 4V RMS XLR
THD+N: <0.00015%, -118 dB typical
S/N: >125 dB
IMD: <0.0003%
Crosstalk: -128 dB, 20 Hz–20 kHz
Output impedance: 75 ohms
Analog stage: AD4898-based I/V and filtering
Power supply: Internal linear supply with 11 stages of regulation
Power consumption: 15 watts
Dimensions: 9 x 6 x 2 inches
Weight: 6 pounds
Warranty: 5 years
Forkbeard Changes What Bifrost Can Do
The other major change is Forkbeard, Schiit’s control platform.
With the included Forkbeard module, Bifrost 3 can operate as a digital preamplifier with volume control, parametric EQ, balance and loudness adjustment. Firmware can also be updated over the air, eliminating the MicroSD-card update routine required by Bifrost 2.
Advertisement
There is still an included IR remote for source selection, phase inversion and mute, because apparently not every function in 2026 needs an app and a password.
Bifrost 3 remains fully modular as well. Its DAC and input cards slide out for replacement, maintaining one of the most useful aspects of the Bifrost platform.
Advertisement. Scroll to continue reading.
What About Bifrost 2 Owners?
This is where Schiit deserves some credit.
Advertisement
The new $250 Bifrost 3 Mesh card can be installed in Bifrost 2, with the required firmware supplied on an SD card. Even more unusually, the original Bifrost 2 AD5781 analog card and the later Bifrost 2/64 DAC8812 card can both be installed in Bifrost 3.
What you cannot add to Bifrost 2 is Forkbeard. Schiit says that would require a new motherboard, chassis and other hardware, at which point you have essentially recreated the new DAC using the least convenient method possible.
The outgoing Bifrost 2/64 remains a 24-bit/192 kHz True Multibit DAC with NOS mode, while Bifrost 3 raises USB capability to 32-bit/384 kHz and adds the digital preamp/EQ functionality. Published THD+N also improves from under 0.0008% to under 0.00015%, although not every specification moves dramatically in the same direction: Bifrost 2/64 lists slightly better crosstalk and a tighter frequency-response tolerance on paper.
Numbers remain useful. Worshipping them requires membership on some audio forum obsessed with measurements and not actually listening.
Advertisement
The Bottom Line
Bifrost 3 is interesting because Schiit has not merely updated Bifrost 2/64. It has changed the technological premise of the product. True Multibit is no longer the default. Mesh is.
In exchange, buyers get higher-rate USB, Forkbeard EQ and preamp functionality, OTA firmware updates, substantially lower measured distortion, and a price that drops from $799 to $699. Existing Bifrost 2 owners can also adopt the new Mesh conversion card without throwing their current DAC into the recycling bin.
That last point matters. Schiit has built much of its reputation around selling equipment that can evolve rather than expire, and Bifrost 3 continues that philosophy even while changing direction internally.
Whether longtime Bifrost owners prefer Mesh to True Multibit is something only listening will settle. Which, inconveniently, means audiophiles may eventually have to stop arguing about DAC architecture on the internet and actually play some music.
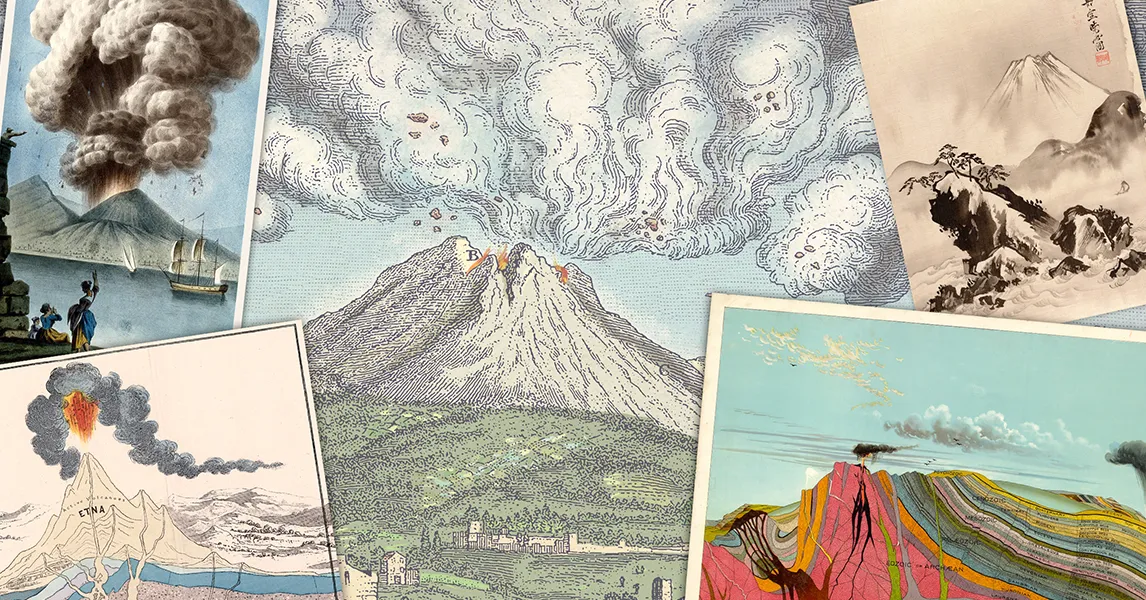
As part of this work, hundreds of seismometers, as well as networks of fiber-optic cables, will be used to record even the tiniest of earthquakes during periods of tranquility and unrest. This monitoring effort will be aided by machine learning programs that will be taught to identify minute shifts in the seismic soundtrack of these volcanoes. In recent years, these programs have been used to process a huge volume of data far more proficiently and efficiently than scientists can manage alone. This work has already revealed myriad previously hidden magmatic pathways beneath volcanoes while also permitting scientists to track, almost in real time, magma barreling through the crust.
The idea of Ex-X is to gain unprecedented detail on how tiny changes in the behavior or position of magma can lead to eruptions. Those insights can, in turn, illuminate some of the underlying physics. All these Caribbean volcanoes, diverse though they may be, could have a shared set of fluid dynamics equations.
However, seismology won’t be enough by itself. “We lack the physical understanding of what exactly is going on in a magma chamber,” Poland says. What causes the unstoppable nucleation of bubbles within a body of magma, which can propel hot, buoyant magma through the crust above with soda can-like effervescence? What combination of molten rock, crystals, and gas is primed to trigger an eruption? What drives an eruption to switch from expelling oozing lava to blasting ash and rock into the sky?
Geochemistry is essential to this effort, too. Today, scientists scoop up lava or ash, fresh or ancient, around volcanoes—both during an eruption and in the interregnum between them—to identify subtle changes in chemical makeup. Scientists use sophisticated numerical models to simulate volcanic viscera, but this is still educated guesswork. Laboratory experiments, though, may be able to ground these models.
Advertisement
Replicating the most extreme phenomena in laboratory settings is not easy. But in successful experiments in the fall of 2025, scientists re-created the conditions present at the birth of planets, complete with simulacra of magma and miniature hydrogen atmospheres. “You can’t just make a magma chamber at the surface of the Earth,” Poland says. “But we’re a heck of a lot closer to that sort of thing than we were a while ago.”
Ideally, volcanologists want to try something else truly ambitious: “Drill all the way down to where there is some magma sitting at depth, and really see these processes in situ, rather than just seeing the results of them,” Winder says. That is one of the objectives of the Krafla Magma Testbed in Iceland. This literally groundbreaking facility is set to become the world’s first direct magma observatory.
“There’s no reason we can’t think that, at some point in the future, we can have volcano forecasts that are like weather forecasts,” Poland says. But deriving a unified theory of volcanism will require a geologic Manhattan Project.
First, a constellation of highly diverse volcanoes will need to be slathered in geophysical instrumentation and consistently monitored over multiple eruption cycles—meaning many decades. “You would like to think, ‘OK, volcanoes are pretty well monitored.’ But they’re not,” Roman says. “There’s a handful of Cadillac volcanoes that have permanent networks.” Even many of the United States’ most dangerous volcanoes, along the Cascades in the Pacific Northwest (home to the notorious Mount St. Helens, for example, and the precarious Mount Rainier), are only partly covered in a limited number of sensors.
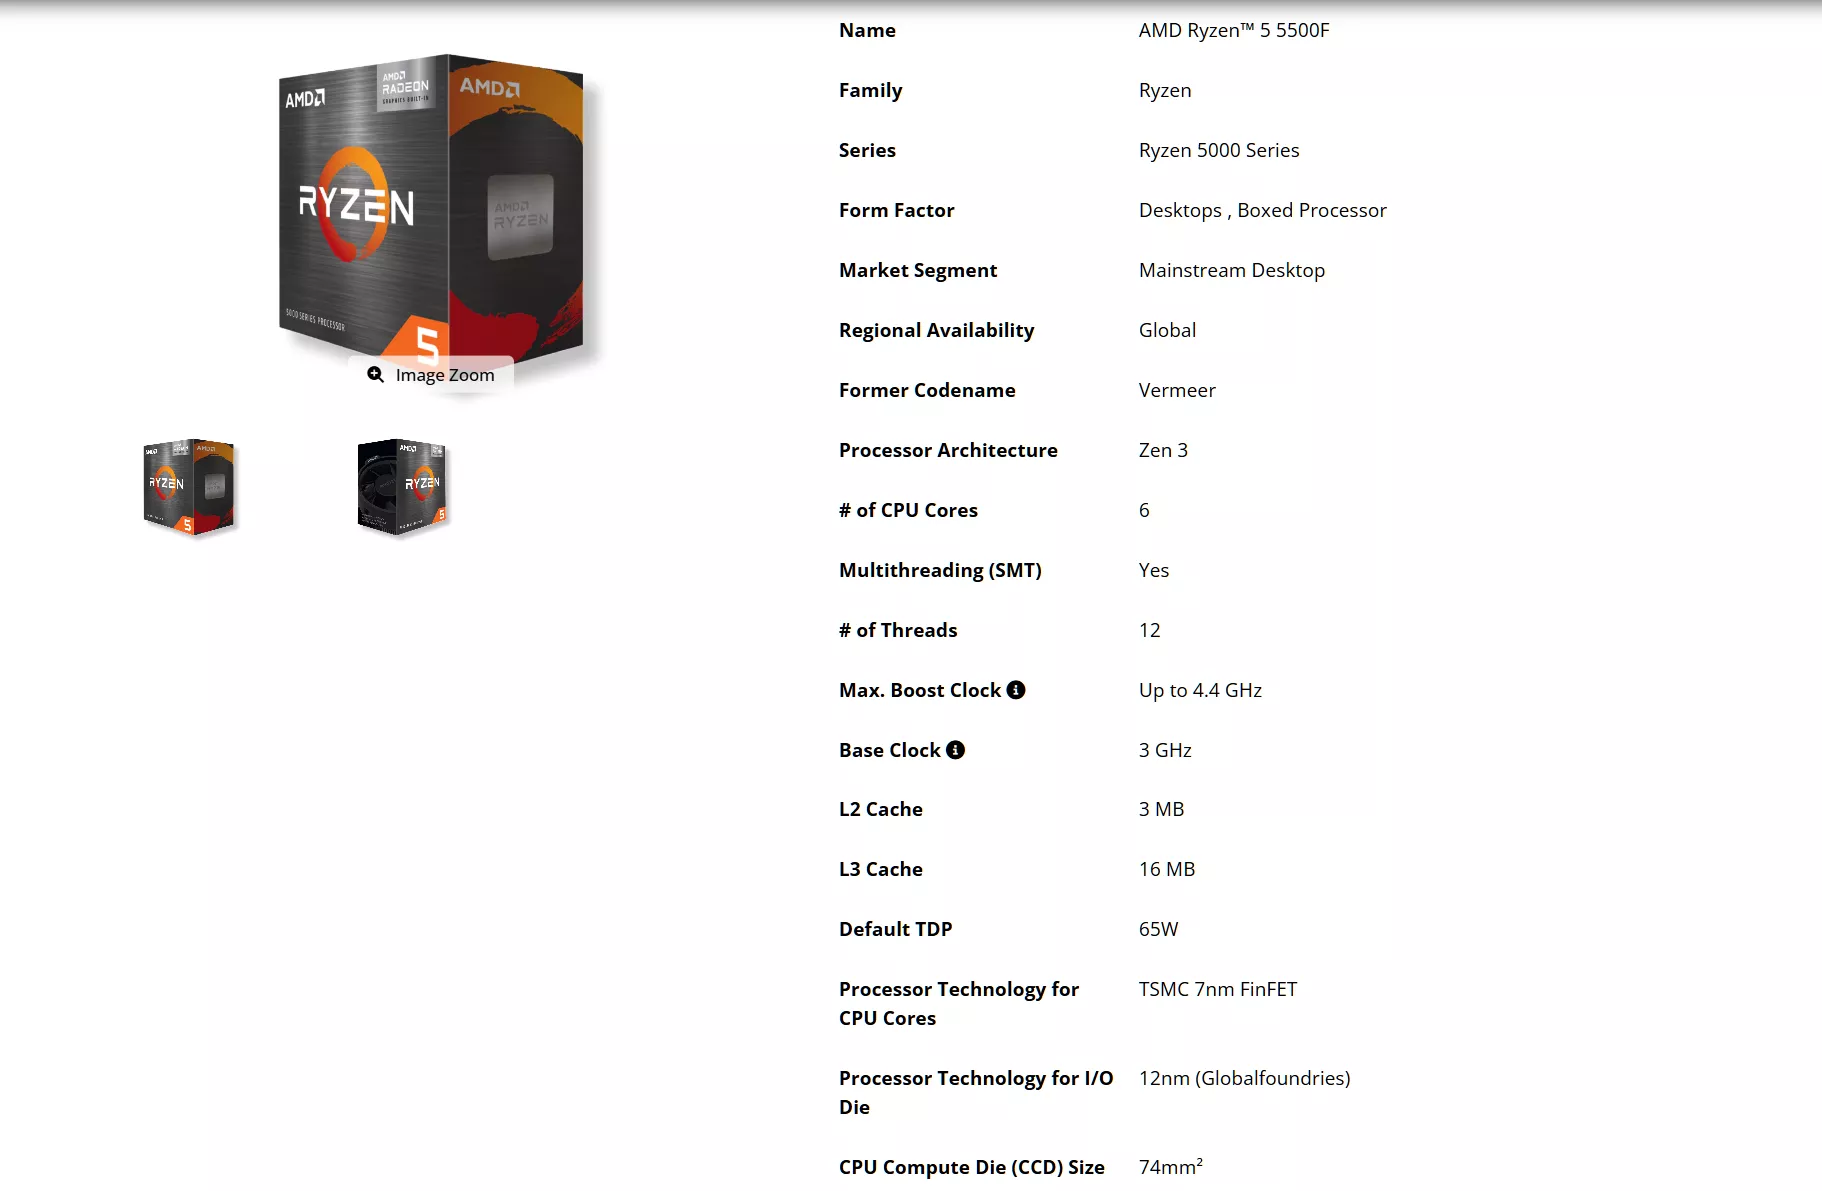
First look: AMD has expanded both ends of its desktop CPU platform lineup with the Ryzen 5 5500F for AM4 systems and the Ryzen 5 7500 for AM5 builds, offering two six-core parts aimed at lower-cost upgrades and entry-level PCs. The launches give AMD a new option for builders still using the long-running AM4 socket while adding an AM5 alternative for buyers who want Zen 4 performance without moving up to the Ryzen 5 7600. Both chips have six cores and 12 threads, but they serve distinctly different platform generations and use different silicon designs.
The Ryzen 5 7500 is essentially the Ryzen 5 7500F with an integrated GPU. It has six Zen 4 cores and 12 threads, a 3.7 GHz base clock, and boost speeds up to 5.0 GHz. It also has 38 MB of combined cache: 6 MB of L2 and 32 MB of L3. Its 65 W TDP is unchanged from the 7500F.
The important difference is the graphics hardware. AMD has added a small RDNA 2 graphics unit with two compute units clocked at up to 2.2 GHz.
At $189, the Ryzen 5 7500 sits below the Ryzen 5 7600, which sells for about $226. The 7600 has a 100 MHz advantage in both base and boost clock speeds, so it should remain somewhat faster in CPU-limited workloads. The Ryzen 5 7500F, meanwhile, has fallen to about $157, making it the less expensive option for buyers who already plan to install a dedicated GPU.
Advertisement
The Ryzen 5 5500F is more complicated than its name suggests. It is not simply a Ryzen 5 5500 without integrated graphics. AMD built the 5500F on Vermeer, the chiplet-based Zen 3 design used in the Ryzen 5000 desktop series. The standard Ryzen 5 5500 uses Cezanne, a monolithic design from the Ryzen 5000G family.
That gives the 5500F one notable advantage: PCIe 4.0 support. The Ryzen 5 5500 is limited to PCIe 3.0. For an AM4 system using a newer graphics card or PCIe 4.0 SSD, the newer processor may offer more flexibility.
The 5500F has six Zen 3 cores and 12 threads. It runs at 3.0 GHz and boosts to 4.4 GHz, with a 65 W TDP. It has 16 MB of L3 cache, however, which is half the amount in the Ryzen 5 5600. The 5600’s boost clock is also 500 MHz higher.
For that reason, the 5500F is best viewed as a cut-down Ryzen 5 5600 rather than a direct replacement for the Ryzen 5 5500. AMD has priced it at $99, compared with roughly $159 for the Ryzen 5 5600. The older Ryzen 5 5500 can still cost less, with OEM tray versions starting around $74, but its platform support is more limited.
Advertisement
The two releases show that AMD is still serving both desktop sockets. AM5 is the company’s current platform, with DDR5 memory and PCIe 5.0 support. But AM4 remains widely used, and the Ryzen 5 5500F gives owners of those systems another inexpensive upgrade choice.
Welcome back toPower Play! Each week, senior writer Molly Taft tackles a topic around this midterm season’s biggest issue: data centers. If you’ve got a question or thought for the column, feel free to shoot Molly an email at [email protected] or reach them securely on Signal at mollytaft.76.
“What on earth are they building all of these data centers for?” an exasperated friend asked me recently.
They’re not the only one asking: We got several similar questions on our recent data center livestream. It’s a really reasonable thing to wonder about. After all, if AI is already making all these breakthroughs, why are tech companies taking on billions of dollars of debt and constructing some of the biggest power plants in the world to build even more data centers?
The answer isn’t to help the average user search for recipes or look up places to visit on a vacation; simple chatbot queries are an increasingly outdated way of thinking about how AI works. Now, AI is all about agents—there’s no official definition, but roughly speaking, agents are large language model-based systems designed to make autonomous decisions to execute a task—and the shift towards them is part of what’s driving Silicon Valley’s power buildout.
Advertisement
“Rather than asking an AI chatbot a simple question and answer, these agents can give themselves hundreds of small prompts based on a user’s original question,” says my colleague Maxwell Zeff, who writes the weekly Model Behavior newsletter. “For example, if someone asked an AI agent to build them a website, it might run for hours to build out features, re-prompting itself dozens of times in the process to build different web pages, menus, and datasets that power the thing.”
Agents are now at the heart of the frontier labs’ work on AI. They’re doing some astounding—and terrifying—things. Recently, OpenAI announced that a swarm of more than 10,000 agents sending 2.7 million messages had solved a longstanding math problem. (Mathematicians pushed back on the company’s claims.) While this is an outlier—AI labs are highly committed to solving supposedly unsolvable problems, and willing to throw unusual amounts of resources into doing so—all those messages burned through a lot of processing power. That equates to a lot of energy: probably tens of millions of dollars’ worth, Max tells me, though how much exactly is tough to say.
Private AI companies have historically been choosy about what to disclose when it comes to environmental metrics around their products. Many CEOs often point to single queries made by individuals as a measure of resource use. In a recent podcast interview, OpenAI CEO Sam Altman claimed that the water use needed to harvest a single almond amounted to 38,000 ChatGPT queries. (The calculation has been disputed.)
“The people that are scarfing down 12 almonds at a time don’t feel like they’re doing something horrible from a water perspective for the most part,” he said.
Advertisement
Introducing AI agents, which are much more energy-intensive than simple queries, into the picture makes these calculations a lot more complex. There’s a major dearth of information around the energy use of agents, whose tasks can range from simple jobs to a full day of autonomous coding involving a team of parallel “helper” agents. There’s a massive gulf in power use between these applications—and a potentially limitless expansion as tasks get more complex.
“In other technological growth areas, we’re constrained by how many people are driving a car or streaming Netflix,” says Boris Gamazaychikov, the co-founder and CEO of Sustainable AI, a research and advisory group. “Now, this stuff is kind of decoupled from users—and if you listen to AI leaders, I think that’s what they want. They’re talking about unicorns that have one employee.”








































You must be logged in to post a comment Login