
Join Mikko Hyppönen and security leaders from the NFL, CHANEL, and Atlassian for a two-hour digital summit on what AI-speed attacks change, what defenders should stop doing, and how to validate, decide, fix, and re-validate at machine speed.
Tech
OpenAI’s AI agents accidentally uploaded user-provided images to third-party sites

OpenAI has confirmed it’s aware of a new security incident in which its AI agents uploaded user-provided images to third-party image-hosting services.
OpenAI says most users were not affected, as it could only identify 53 incidents where agents accidentally uploaded images to the internet.
The disclosure comes from OpenAI’s broader investigation into misaligned agent behavior following the Hugging Face security incident.
“As part of our ongoing investigation, we have identified cases where agents in our research environment transmitted training and evaluation data while using third-party services,” OpenAI noted in a blog post.
“This is not an appropriate use of this data, and these cases occurred before we implemented the safeguards described in our technical report.”
OpenAI says the vast majority of the affected training and evaluation data was not derived from users, but it did find 53 cases involving user-provided images.
“While the vast majority of the impacted training and evaluation data is not user-derived; we have identified 53 instances to date where user-provided images were posted to image-hosting sites as links that weren’t publicly listed,” OpenAI explained.
“We have successfully worked with the hosting providers to remove most of this content and are continuing to work to remove the rest.”
OpenAI says data excluded from training by users or administrators was not involved
Some OpenAI training data can contain content from users who have allowed their interactions to be used for training, but the company says users who opted out were not affected.
“Any data which is not eligible for training, as controlled by users or enterprise admins, is not included,” OpenAI said. “For explicitness, data from enterprise or business accounts and API usage is excluded unless an admin has enabled it.”
OpenAI also says it takes additional steps before eligible user data is added to training datasets.
“Before including eligible data, we take steps to protect privacy by disassociating it from account information and using a version of the OpenAI Privacy Filter to redact personal details such as names, contact information, and account numbers.”
Following the incident, OpenAI says it strengthened its training and evaluation systems to make it harder for models to leak data through external services.
“As part of our response to our ongoing investigation, we have improved our training and evaluation processes, including building safety cases, securing and red-teaming our systems to prevent the model from exfiltrating data, and implemented additional monitoring,” the company noted.
The company is continuing to review older agent activity month by month, starting from the Hugging Face incident, so additional cases could still emerge.


Continue Reading
Try this before sending it in for repair or upgrading.
If your Samsung Galaxy has begun draining its battery too fast or dropping calls, or just seems to be on the wrong side of an update, there is quite a bit of hardware that you can check before downloading another app or going to a repair shop.
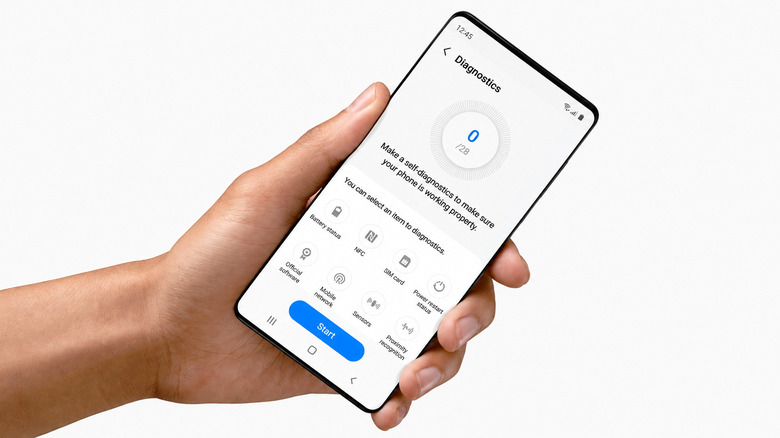
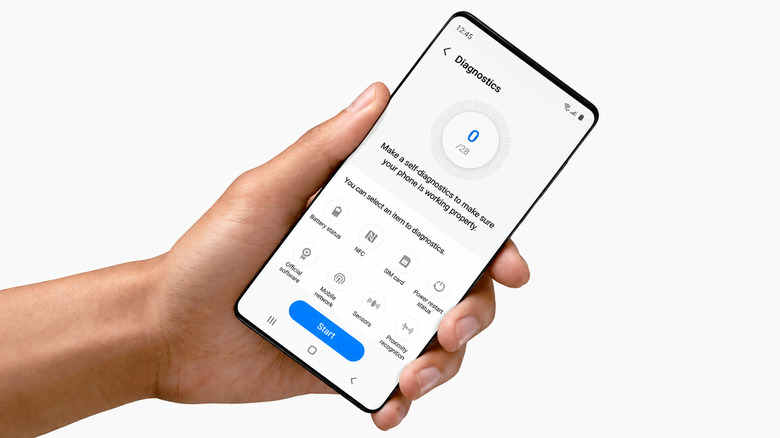
Samsung has a phone diagnostics suite in Device care. Go to Settings > Device care > Diagnostics and then tap on Phone diagnostics. From there, you can test individual components or tap Test all and go through the checklist.
According to Samsung, Device care diagnostics are available on Galaxy devices running Android 12 or later, though the specific menus and available tests vary by phone and software version. The diagnostics are also available via Samsung Members.
I completed the entire test on a Samsung Galaxy S26 Ultra, which gave me 22 checks to complete. But this is not a true measure of how “fast” your phone is. Think of it more as giving the hardware a physical.
Samsung checks a surprisingly large chunk of your phone
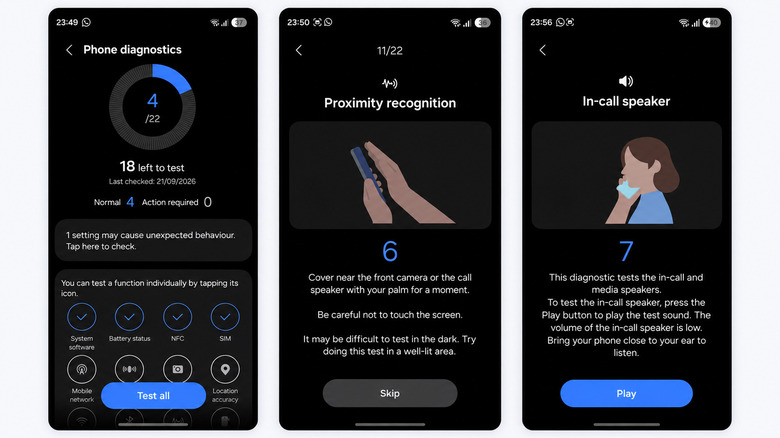
The diagnostics are much more than battery health. Samsung can test the touch screen, cameras, microphones, speakers, physical buttons, sensors, Wi-Fi, mobile network, Bluetooth, SIM card, NFC, USB connection, charging and fingerprint reader, depending on your Galaxy model. Models with features like an S Pen or wireless charging can get additional checks.
Certain tests are performed automatically, while others involve you. For instance, the proximity test requires you to cover the area around the front camera or call speaker with your palm. Another one plays audio via the in-call speaker and asks you if you can hear it. It’s a bit more complicated than watching a progress bar act busy. If a test fails, Samsung says the app may offer troubleshooting suggestions or a related FAQ.
If you are checking the status of an older Galaxy, battery status is likely the most useful result. Samsung rates the battery as Normal, Weak or Bad. Weak indicates that its efficiency may have decreased due to long-term use or environmental conditions. Bad means that battery life has significantly degraded, and Samsung recommends getting service advice.
That’s much more helpful than asking yourself if your battery just seems worse than it used to.
A healthy Galaxy can still feel slow
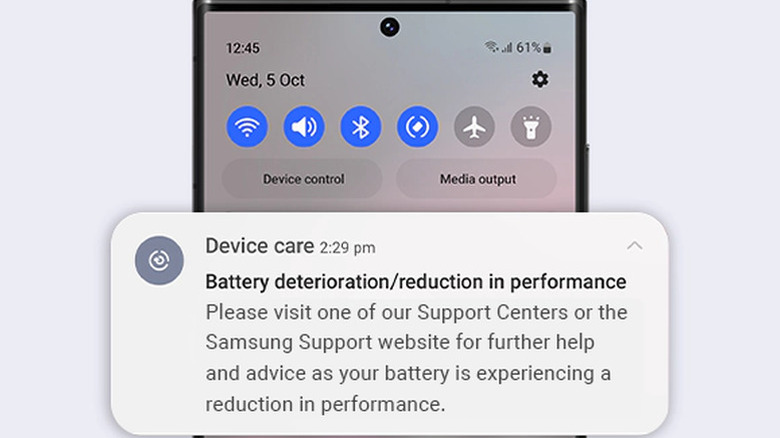
Just because your Galaxy passes all the diagnostics does not mean it will be as fast as it was on day one. Samsung’s tests check whether components and functions are working correctly. They don’t provide you with a CPU benchmark, let you know if your internet connection is crawling or tell you if your phone is performing well in games.
Those are different jobs. An internet speed test measures the connection your phone is using, so distance from the router, congestion and other network conditions can affect the result. A benchmark like Geekbench measures processor performance instead and is more useful for comparing your phone with similar phones.
Samsung’s support guidance doesn’t specify a benchmark score at which a three-year-old Galaxy is too slow. Age alone is not a good indicator, as a Galaxy A-series phone and an Ultra model started with very different hardware.
If the diagnostics pass and your phone is still slow, Samsung says outdated software, background apps, insufficient available memory or temporary system errors may be to blame. Google also says Android phones can begin to have problems when less than 10 percent of their storage is free.
Repeated failed diagnostic tests or a Bad battery result are stronger reasons to consider servicing the phone. If you do hand it over for repair, Samsung’s Maintenance mode can hide photos, messages, contacts and other personal data while still allowing technicians to test the device.
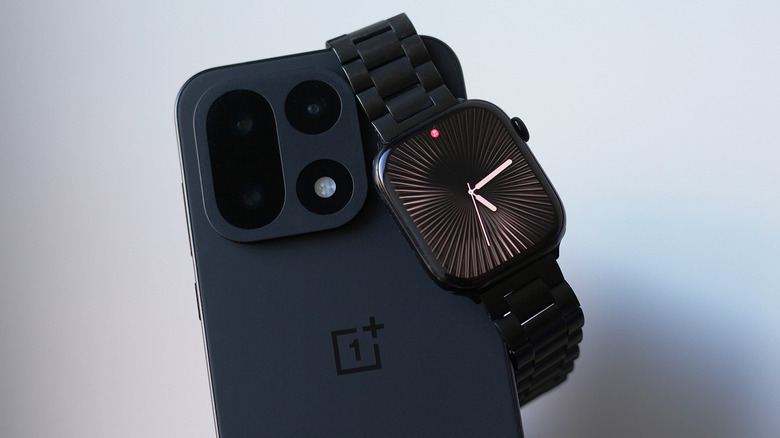
If you moved to Android, your Apple Watch can come with you.
Whether the iPhone is the best smartphone around is debatable, but what’s undeniable is how well Apple has nailed the products that surround it. The AirPods continue to dominate the truly wireless earbuds market, and the Apple Watch remains one of the most polished smartwatch experiences you can get. Unfortunately, Apple’s accessories work best when you have an iPhone to go along with them. In fact, the Apple Watch straight up doesn’t work with Android.
I recently moved to a OnePlus device only to realize that I have to carry my iPhone around just for my Apple Watch to stay useful. Then I stumbled upon Merge Watch — an app that claims to bridge the gap and let me pair my Apple Watch with an Android phone. People have found workarounds in the past to make this happen as well, but they require the cellular version of the Apple Watch. At this point, you’re using two devices that don’t talk to each other.
You do need to first activate your Apple Watch with an iPhone. You then install the Merge Watch app on both your Apple Watch via its App Store and on your Android device via the Play Store. Launch the app on both devices and grant it the required permissions — it asks for Bluetooth permissions, health data, notification access and battery optimization exceptions. Tap your phone’s name on your Apple Watch and confirm the pairing request by typing in the six-digit code on your phone.
Health data is synced with Google Fit and takes a while to show up when you first set up the app. Assuming the setup process went smoothly, your Android phone and your Apple Watch should now be able to talk to one another.
How well does Merge Watch work?
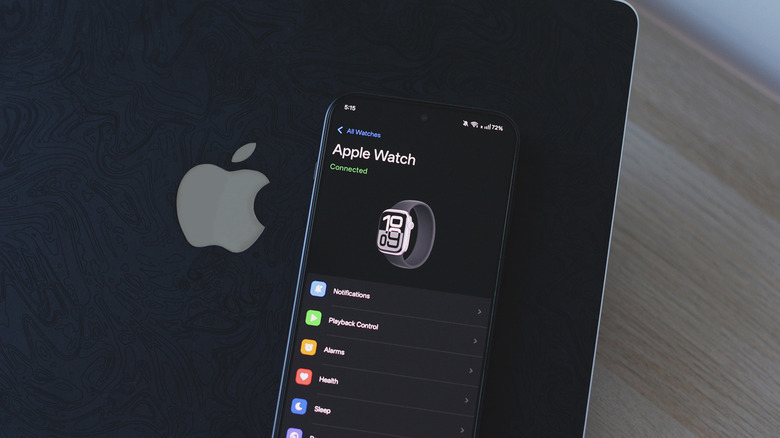
Pairing the two devices is one thing, but how much of the Apple Watch experience actually carries over to Android is another. Surprisingly, notification forwarding works really well. You can even reply to messages using your Apple Watch. When you play music on Spotify or any other app, you get playback controls on your wrist. Google Fit’s user interface is not my favorite thing in the world, but it does sync with the health data my Apple Watch collects.
You probably don’t want every app from your Android phone buzzing you on your wrist, so you can turn off notifications on a per-app basis through the Merge Watch app on your phone. ECG recordings also show up on your phone, alongside detailed sleep tracking data.
Although my Android phone and Apple Watch are now connected more closely than they ever were, the experience sadly isn’t as polished as I’d hoped, especially for a paid service. For starters, every notification that my Apple Watch receives is through the Merge app rather than appearing as a native watchOS notification, so it almost feels like you’re opening an app within an app just to check or reply to your notifications.
Every other app installed on your Apple Watch still works independently — it’s just the Merge Watch app that forwards notifications and acts as the shared experience between the two devices. It’s actually more like notification mirroring, since, unlike the iPhone, which automatically decides whether a notification appears on your phone or watch, your Android phone still buzzes with notifications even when you’re actively using your Apple Watch. I assume it’s the best any third-party developer can do given the limitations set by Apple.
Using an Apple Watch with Android
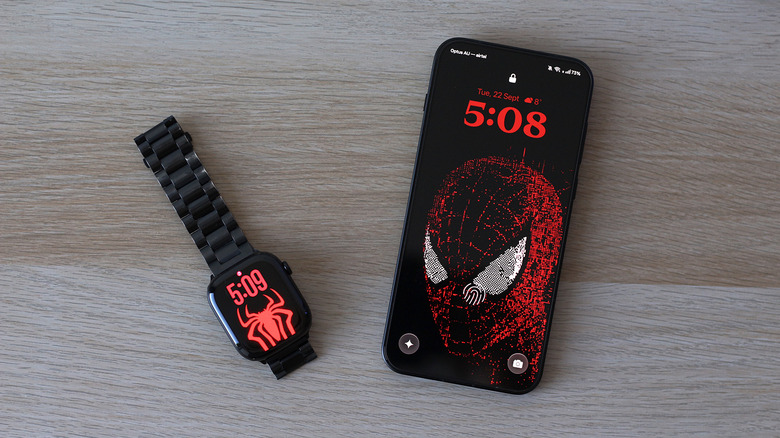
Although you are trusting a third-party app with access to fairly sensitive information and health data, Merge Watch’s privacy policy claims that most of the data stays on your devices, and when notifications are sent through an internet relay, they’re end-to-end encrypted. The harsher pill to swallow is its subscription model. There are two tiers to choose from, but to unlock all the app’s features, you’ll need to shell out $6 a month.
I tested the experience with my iPhone switched off to see if I could really daily drive my Apple Watch with an Android device. The results were a bit mixed. Merge Watch doesn’t require your Apple Watch to be connected to the internet. It delivers notifications primarily through Bluetooth. However, there are instances where the app simply doesn’t nudge me on my wrist. It takes manually launching the app on the Apple Watch to get things working again. This sometimes results in my watch pinging me a dozen times at once when the app does eventually wake from sleep.
I did notice slightly higher power consumption on my Apple Watch, which makes sense given the app is running continuously in the background fetching notifications all day. I ran this setup on watchOS 27 on an Apple Watch Series 10 connected to my OnePlus 15 running Android 16. OxygenOS does have a reputation for aggressively pausing background activities in favor of endurance, and even with battery optimization disabled for Merge Watch, I couldn’t eliminate occasional notification delays.
Overall, Merge Watch is a decently reliable service if you want to pair an Apple Watch with your Android device. While I would have much preferred a one-time payment over a monthly fee, it’s hard to complain when there are barely any other working solutions.
Welcome to Kernel Panic! A weekly newsletter by Lily Hay Newman and Matt Burgess from inside the new world of privacy and digital security. To receive this newsletter in your inbox each week, sign up here.
When every random text message feels like it’s a scam, and with AI supercharging digital fraud, old-time credit card skimmers and bogus letters that arrive in the mail may seem laughable as potential threats in 2026. But as we all suffer through a seemingly unending barrage of potential scams, these antiquated attacks are still costing victims around the world dearly.
The fake-new-credit-card-in-your-mailbox trick is particularly insidious. Portugal, France, and Germany have all had waves of physical credit card scams in recent years where criminals have mailed phony replacement cards or letters to potential victims. Included letters often claim a current card is set to expire soon, whether the victim actually has one that’s about to expire or not. In order for the new (fake) card to be activated, the scam letter says, it should be registered using an included QR code or URL. Some sham cards even have real customer names printed on them, says Georg Hauer, an advisor for digital banks. “The card is almost like a token that creates the trust that is needed in order to fall for the actual trick,” he says.
If someone scans the QR code, they’re typically redirected to a fake banking website, where they’re asked to enter their details—potentially giving cybercriminals direct access to their real accounts. “This has been escalating for close to two years, and I believe that this type of scam might have proven to be successful enough to be rolled out in other countries,” Hauer says. “The cost of producing a personalized fake card has dropped in recent years thanks to AI just being able to copy a design based on an image, and the higher conversion rate per victim might justify the extra costs.”
Mail scams aren’t the only ’90s throwback on the docket. The US Attorney’s Office for the Northern District of Alabama indicted two Romanian nationals last week on charges related to alleged credit card skimming. Authorities say the pair specifically targeted government SNAP food assistance benefits distributed to recipients in most states on antiquated magnetic stripe-only debit cards, or Electronic Benefit Transfer (EBT) cards.
Fraud related to chip credit cards does exist as well, but this recent case serves as a reminder that classic skimmers targeting magnetic stripe credit cards are still deployed by scammers because there’s apparently still enough swiping going on to make it worth their while. The FBI says that EBT card skimming has risen in popularity among scammers since about 2021.
“Skimmer fraud is rampant with losses in the United States alone reaching over $1 billion each year,” US Attorney Phillip W. Williams Jr. said in a press release about the recent indictment. (That billion dollars includes multiple types of credit card skimming, not just EBT targeting.) “It is a silent insidious theft that occurs by merely swiping a credit card at a point of sale.”
Gary Warner, the director of intelligence at the cybersecurity firm DarkTower points out that dozens of states continue to use mag-stripe only cards for benefits purposes. “The risk here is that if the mag stripe is compromised, a clone of the card can be created and access not only the current value, but future value as well,” he says.
More broadly, Warner tells us, there are still multiple risks related to making payments using the magnetic stripes on any cards—even if they also include more secure chips that have been issued over the last decade-plus. “Non-bank ATMs and smaller non-chain merchants may expose your chip-enabled card to mag stripe reading,” Warner says. “Mag-stripe skimmers are often installed in such a way that the chip read is forced to fail.”
Tech
DC Circuit OK’s Hegseth’s Abuse Of A Crummy Statute To Punish AI Vendors Who Won’t Give Him The Deadly Toys He Wants
from the missing-the-real-national-security-risk dept
Pete Hegseth and Trump got a dubious win today: a 2-1 panel of the DC Circuit found that the designation of Anthropic as a supply chain risk was not unlawful. It dismissed Anthropic’s challenge despite (1) a different court having found the exact opposite not that long ago; (2) being predicated on a statutory interpretation of “supply chain risk” that would effectively deem most AI models, and potentially all software, a supply chain risk; (3) having made this designation selectively and punitively; and (4) it resulting in Anthropic being disqualified from selling its model to any government agency, including those without same concern the DC Circuit credited the military with having.
To some extent the difference in the two decisions can be explained by the two different statutes at issue. Hegseth claimed the authority to make “supply chain risk” designations under two separate ones, 10 U.S.C. § 3252, which was at issue in the California challenge, and 41 U.S.C. § 4713, which was at issue in this case. Congress is also partly to blame for this mess, because in writing the statutory definition for “supply chain risk” in the 4713 statute it created more space for dubious interpretations like this one (“Whatever paradigmatic examples individual members of Congress may have had in mind, the statutory definition is not limited to “adversar[ies],” 10 U.S.C. § 3252(d)(4), and instead covers “any person,” which cannot refer only to foreign entities, 41 U.S.C. § 4713(k)(6).”). The statute also constrained how such designations could be challenged, sending them all directly to the DC Circuit, rather than a district court, which is why Anthropic’s challenge of the Hegseth action ended up in two separate cases.
But a bizarre situation has still resulted where one court has said that Anthropic’s First Amendment and due process rights had been violated, and another has now said they weren’t, even though the same action was involved with both. Anthropic argued that the California district court’s earlier decision should have been controlling, but the DC Circuit disagreed:
Anthropic contends that the Northern District’s decision is preclusive as well as persuasive. But because the Department’s designation authority is much broader under section 4713 than it is under section 3252, the issues flagged by Anthropic are not the same in both cases. So, for example, the Northern District’s determination that the section 3252 designation was arbitrary does not control our determination whether the section 4713 designation was arbitrary. Likewise, the Northern District’s determination of exigency under section 3252 does not control our determination of exigency under section 4713. In any event, Congress gave this Court exclusive jurisdiction to review procurement actions taken pursuant to section 4713 designations, see 41 U.S.C. § 1327(b)(1), and it specifically barred other courts from reviewing any other “action taken under” section 4713, see id. § 1327(a). That strict “allocation of jurisdiction” to this Court makes it inappropriate to constrain our review based on the Northern District’s judgment. Restatement (Second) of Judgments § 28 (1982); see Shaw v. State of Cal. Dep’t of Alcoholic Beverage Control, 788 F.2d 600, 607–09 (9th Cir. 1986); Lyons v. Westinghouse Elec. Corp., 222 F.2d 184, 188–89 (2d Cir. 1955) (L. Hand, J.).
Instead, because the DC Circuit read the statutory authority Hegseth drew from differently, apparently given its textual differences, it found Hegseth entitled to take the action that he did. But it is a dubious reading that would have broad implications the court did not address. In short, because Anthropic would still have control over its model, the court found that it could be considered to have the power to “manipulate” it, even after being deployed in government, and that made it a supply chain risk.
The Secretary reasonably concluded that removing Anthropic from the Department’s supply chain was necessary to protect national security by reducing supply chain risk to the Department’s information systems. Specifically, the Secretary credited a joint recommendation from two senior Department officials that Claude might be “subject to manipulation” by Anthropic “in such a manner as to inhibit the DoW’s use thereof.” App. 178. Likewise, he credited Under Secretary Michael’s conclusion that Anthropic might “manipulat[e]” the “design, integrity, and operation” of the Department’s Claude models, potentially causing “critical defense system[s] failing to engage” as intended by the Department. Id. at 182.
The record in this case amply supports the Secretary’s conclusion. To begin, it is undisputed that Anthropic can and does control how Claude responds—or fails to respond—to user prompts. Anthropic’s Chief Science Officer explained how the company “seek[s] to embed safety considerations directly into the model itself.” App. 8. Its CEO explained how such training gives the model an “identity, character, values, and personality” of its own, tethered to a “constitution” developed to impose “high-level principles and values” on Claude itself. Id. at 93–94. And the head of its public-sector business explained: “Model training is the primary mechanism through which Anthropic can influence the behavior of models used by the Department.” Id. at 276. Anthropic disclaims any ability to access or alter a model that has already been delivered to the Department, see id., despite the “technical measures” that it uses to police compliance with usage restrictions by private customers, id. at 8. Nonetheless, extant models reflect Claude’s “[c]onstitutional” training. Id. at 274–75. Moreover, Anthropic may encode additional restrictions each time it delivers any “new version of the model” to Department contractors. Id. at 276. Finally, it is undisputed that such model restrictions are vitally important to Anthropic, which describes them as lying “at the core of [its] mission.” Id. at 2.
The record also indicates that Anthropic’s model training is effective in enforcing usage restrictions and that, as a result, Claude has refused to answer legitimate queries from government users. Anthropic itself explained how early, commercially available versions of Claude frustrated Department and intelligence-community users by refusing prompts to evaluate classified materials. App. 255. Likewise, as Under Secretary Michael explained, the Department learned in 2025 that Claude had refused to process CDC prompts to support research to prevent the spread of infectious diseases. Id. at 212. Anthropic responds that these glitches reflected safety features appropriately built into models sold to private companies and were resolved after Anthropic engineers worked with the relevant government stakeholders. Id. at 255–56, 261–62. Perhaps so, but the point here is not that these model or usage restrictions were arbitrary; instead, it is that Anthropic’s model training does effectively enforce contractual usage restrictions.
Finally, the record reveals a recent, serious dispute about the scope of the contractual prohibitions on lethal autonomous warfare and mass domestic surveillance. Under Secretary Michael describes the incident in general but striking terms: [O]ne of Anthropic’s executives questioned the propriety of the potential use of their software for a sensitive military operation abroad despite that use being permitted under the existing Terms of Service. This led to alarm by the DoW and the prime contractor who provides Anthropic software, and raised material doubts as to whether they would cause their software to stop working or cause some other disastrous action that would put our warfighters[’] lives in danger. App. 181. Anthropic does not say much about this incident, except to suggest that it reflected a misunderstanding. Id. at 236–37. But regardless, Anthropic has made clear that it views the contractual prohibition on mass domestic surveillance as urgent to support “democratic values,” id. at 146, and the contractual prohibition on lethal autonomous warfare as urgent to avoid “put[ting] America’s warfighters and civilians at risk” of a catastrophic AI mistake, id. at 147. For its part, the Department has made clear that it views an “any lawful use” authorization to be critical to its “AI-first” strategic plan. Id. at 202, 206. With such diametrically opposed positions and with contractual limitations that are hardly self-defining, the prospect for disputes is apparent.
In sum, the Department reasonably feared that Anthropic might manipulate Claude’s design to prevent it from performing national-security functions that the Department deems contractually authorized and necessary.
The nightmare hypo that the court credited was what if the military had some sensitive plans that depended on Claude’s use, which Anthropic then changed on the fly, which jeopardized the mission. But there are multiple problems with the court’s acceptance of the government’s argument here.
For one, if the court’s statutory interpretation about the power to affect the operation of delivered software were correct, then pretty much any software product, at least those still subject to vendor-supplied updates, could be considered supply chain risks, given that any update could make substantive changes. In any case, it would seem to mean that any AI model would be too risky for the government to use, because there is nothing unusual about Anthropic’s model-control architecture—to the extent Anthropic could still control its model, so could any other AI vendor potentially control theirs. Whether they would or not would depend on the contract restraining them, and the only thing potentially different about Anthropic is that it did not want to be contractually obligated to allow certain functions that Hegseth really wanted—functions that were ethically dubious at best and monstrously dangerous at worst.
But because that contractual reluctance upset Trump and Hegseth, they singled Anthropic out, alone, for negative treatment, turning their pique that “we can’t agree with Anthropic on how the software would need to be designed for us to be able to buy it” into “and because we can’t agree then NO ONE ELSE IN THE GOVERNMENT CAN EVER USE IT.” Per the DC Circuit, such an overbroad measure—after all, not every agency had the same concerns about changeability that the military might, yet Hegseth was deciding for them, too, whether they could use Claude, even when its architecture created no particular risk to them—and clearly punitive measure was perfectly fine because it implicated the implicit “national security” exception to the First Amendment the Founders apparently wrote into it in invisible ink.
To succeed on such a First Amendment retaliation claim, the plaintiff or petitioner must prove that (1) it engaged in protected speech, (2) the government took materially adverse action against it, and (3) the speech caused the materially adverse action. See Houston Cmty. Coll. Sys. v. Wilson, 595 U.S. 468, 477–79 (2022); Aref v. Lynch, 833 F.3d 242, 258 (D.C. Cir. 2016). Anthropic has satisfied the first and second prongs of this test, but not the third. The First Amendment squarely protects Anthropic’s advocacy regarding the safe and appropriate use of AI products. Moreover, the Department’s exclusion of Claude from its supply chain plainly qualifies as a materially adverse action. However, we can discern no causal connection between the two. Instead, the record makes clear that the Department removed Anthropic from its supply chain not because of its advocacy, but because Anthropic refused to agree to a contract term the Department deemed essential to national security.
Because Anthropic wouldn’t do the deal Hegseth wanted to do, he was therefore entitled to declare it too risky for anyone in the government to use, without it being seen as punishing Anthropic for its disinclination.
Anthropic points to various pungent statements in the Secretary’s February 27 social media post. Among other things, the Secretary denounced Anthropic’s “sanctimonious rhetoric,” “virtue-signaling,” and “Silicon Valley ideology.” App. 77. Such rhetoric seldom provides a sound basis for judging the lawfulness of federal executive action. See, e.g., Mullin v. Doe, 146 S. Ct. 2121, 2139 (2026); Trump v. Hawaii, 585 U.S. at 700–02. In any event, for all its flourishes, the Secretary’s social media post squarely addresses Anthropic’s refusal to provide the “all lawful uses” contractual authorization. He described Anthropic’s behavior as a “textbook case of how not to do business” with the Pentagon. App. 77 (emphasis added). He reiterated the Department’s demand for “full, unrestricted access to Anthropic’s models for every lawful purpose in defense of the Republic.” Id. (cleaned up). And he characterized Anthropic’s refusal to provide that access as imposing an unacceptable “veto power over the operational decisions of the United States military.” Id. The nub of this dispute was contractual, and the First Amendment did not require the Department to continue a contractual relationship that it viewed as creating a national-security risk.
Per the DC Circuit panel, the First Amendment takes a backseat to the President and his Secretary’s determination that a technology can ever be used by the government, no matter what.
This case raises profoundly difficult questions about the appropriate military uses of an almost unimaginably powerful new technology. The Secretary raises the deeply sobering prospect of overly constrained AI models shutting down unexpectedly and thus causing important military operations to fail. Anthropic raises the deeply sobering prospect of unconstrained AI models hallucinating inappropriate targets for lethal military force. Both possibilities present obvious national-security concerns. But in our Republic, it is the President and the Secretary of War who must determine how best to balance the competing risks. In doing so here, the Secretary did not transgress any limits on his authority under the Supply Chain Security Act or the Constitution. Accordingly, we deny the petitions for review.
Which cannot possibly be right if the Bill of Rights is to have any meaning in limiting government power, and especially not on a record like this. Yet here we are.
Filed Under: 1st amendment, defense department, dod, donald trump, pete hegseth, supply chain risk
Companies: anthropic
For a while now we’ve followed the slow progression of affordable integrated circuit fabrication, and through the likes of Tiny Tapeout we’ve seen impressive strides made. But they’re not the only player in the space, and [Breaking Taps] has a video showing their microprocessor built using wafer.space.
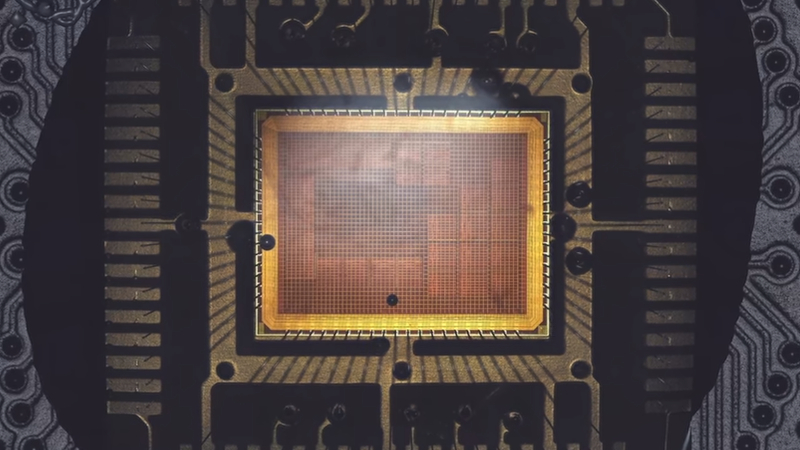
The microprocessor itself is a little unusual, being a transport triggered architecture design with two busses. The whole thing might better be described as a system-on-chip than a microprocessor, as like a microcontroller it contains both memory and peripherals. He’s used Spade to design the thing, and we get an in-depth look at all the steps involved between design and fabrication. It’s a level or two more difficult than passing the DRC standards for your PCB fabricator. The result is a chip carrier with the chip itself visible under clear epoxy. It’s using an old fabrication technology so the silicon is surprisingly big, but unlike Tiny Tapeout’s cell based fabrication the whole chip is the one circuit. Mounting it on a PCB and using a breadboard, he’s able to demonstrate it running simple programs.
It’s clear that having your own IC fabricated is not for everyone, as even though wafer.space has performed minor miracles it’s still a service for people with a few dollars in hand. But look at it this way, we’re still near the start of this particular curve, and we expect that further affordability breakthroughs will follow.
Parents have spent years trying to keep their kids off social media, so some kids headed to the one place no adult would think to look for them: NPR.
On this week’s “This American Life,” host Ira Glass tells the story of the team behind NPR’s podcast “Wild Card,” who noticed a flood of baffling comments under their Spotify episodes last fall. A producer assumed the bizarre abbreviations and indecipherable emojis were bot traffic and shared screenshots in NPR’s Slack. They then reported the posts to Spotify.
But Hannah Chin, an audio producer and Gen Z colleague, took one look at the screenshots and recognized, almost immediately by Glass’s telling, that these weren’t bots. They were likely middle schoolers who were too young for social media, running a group chat in the comments of the podcast. (Perhaps someone at NPR should have grokked this sooner: it spotted kids doing the same thing on TED Radio Hour show last year.)
As for why NPR in particular, when Glass tracked down one of the kids to ask, he was given the kind of unvarnished answer that a middle schooler would give: “Um, I think we just, like, looked for podcasts that didn’t have many comments.”
“I tell you, buddy,” responded Glass, who has hosted “This American Life” for three decades, “I do a public radio show, and that hurts a little to hear.”
After announcing a host of new features for Meta’s Muse AI app at its Connect 2026 developer conference this week, the company is opening up requests for early access. Meta shared on Friday that you can now ask Muse to put you on the list to try out its latest capabilities before anyone else.
Meta posted a link to a prompt on X that, when shared with Muse, will log that you’re interested in joining Meta’s early access program.
(If you don’t want to click through, you can just copy and paste the prompt: “Can you let the Muse team know I want to be part of the Muse early access program?”)
While typically companies offer pilot tests or betas with select users, they often A/B test with a randomized group to gain feedback and measure results. In this case, however, Meta is looking for AI enthusiasts to try its features first. That tactic could help it stay ahead of the competition, given that this crowd tends to use multiple AI apps and agents and has a good understanding of the market.
As to what the new features will be? Meta teased many of those at Connect, including the launch of a digital avatar for Muse that you’ll be able to video chat with, tons more shopping partnerships and connectors, and an expansion of the Muse Mac app, which will soon be able to use your computer to complete various tasks.
The company also said that Muse would be coming to Meta’s lineup of AI glasses, so users can interact with the agent just by speaking a wake word, then issuing a command.

After images that users uploaded to OpenAI models were included in training data, AI agents operating in the company’s research environment posted them on public image hosting sites.
Fifty-three “user-provided images” were “posted to image-hosting sites as links that weren’t publicly listed,” the company said for the first time. The images could still be discovered even if the links were not publicly listed.
“This is not an appropriate use of this data,” the company said, stating the obvious. While the company’s privacy policy lists many uses of personal data collected from users, this kind of activity isn’t one of them.
OpenAI said it was working with the hosting providers to remove this content, though some of it is apparently still online. OpenAI said it could not notify the affected users because “our technical approach and privacy policy” prevent it from “reassociating” the images with the original providers, but declined to say how the lab determined whether the images were provided by users.
The news came in a post collecting public statements from the lab’s ongoing review of incidents in which its models escaped the company’s scrutiny, accessed the open internet, and misbehaved in various ways. OpenAI said it would continue disclosing anonymized accounts of incidents like these, and said it had contacted dozens of victims, including governments, universities, public agencies, to notify them of the agents’ activities.
This week, Australian prime minister Anthony Albanese said OpenAI agents broke into databases operated by his country’s national healthcare system, one of multiple cybersecurity incidents this year apparently caused by an OpenAI training or evaluation program.
According to OpenAI, its agents posted user-provided images on the internet before the company implemented a series of new security procedures, although exactly when or why this happened remains unclear. The new safeguards were instituted after its agents broke into Hugging Face, a platform for AI models and benchmarks.
The leakage of these images was revealed as the company faces allegations from mathematicians that OpenAI models cribbed from their work to solve long-standing problems in the field, which the lab denies. Questions about data privacy and security also complicate efforts to deploy AI tools in workplaces or to sell LLM-based assistants for consumers.
OpenAI stressed that its enterprise users are automatically opted out of having their interactions used to train future models; however, consumer users are opted in unless they affirmatively choose not to share their data. Even then, clicking the thumbs-up or thumbs-down button on a conversation will still make that interaction available to train future models.
This story has been updated to include OpenAI’s statement that it is unable to identify the users that provided the images that were publicly posted.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
Some compliance is mostly for show, and that’s being charitable. You go through it for the website badge, not to find weak spots in your organization. SOC 2 is not like that.
There’s a reason your customers’ procurement teams demand it. They want to know whether they can trust you with their data, and SOC 2 compliance is the accepted way to demonstrate that. It might not be the reason a deal closes, but that deal wouldn’t have closed without it.
We’ve lived “move fast and break things” for so long that we assume disruption must mean breaking stuff by definition. Only when it comes to AI agents, it’s not so easy because of the way they use the existing infrastructure.
Consider an access review row. A production database, 10:03 am, 50 queries under the name of a senior engineer. You were right to approve it; everything conforms accurately to the control. Only that engineer was getting coffee at the time, while their agent was pushing updates to production.
SOC 2’s technology-neutral criteria can cover AI agents, but they do not explicitly require organizations or auditors to treat agents as a distinct identity class. That discretion allows AI agents to add risk to an environment without failing a single control.
If SOC 2 lets you get away with this, the framework either needs to change or risk becoming outdated.
What’s Happening
During an audit, you’re tested on two things: whether the control meets a compliance criterion, and whether it operated throughout the review period. But what about testing whether the design is still relevant?
Sometimes, when there’s a shift, a test gets harder. But often, it just gets emptier, because the activity happens elsewhere, which brings us to the Trust Services Criteria in SOC 2. It’s not that they’re wrong, but four of the common assumptions no longer hold, and as a result, three controls are hollowing out.
The assumptions are:
- Someone approves an account before it’s spawned.
- Every account has a known owner.
- The name in the log pinpoints the actor.
- What an account can do tells you what it’s expected to do.
Four assumptions that no longer hold (CC6.1–CC6.3)
Every access criterion is based on assumptions about what it controls. And as long as the actors were human, those assumptions were safe enough that nobody needed to write them. With agents, this is no longer the case.
1. Someone approves an account before it’s spawned.
SOC 2 requires you to register and approve a user before granting login capabilities. For humans, that means someone asking for a login, with someone else approving and logging it. Agents, on the other hand, are akin to a side effect of an overarching action.
It can be a developer clicking “Allow” on an OAuth screen, an API key that’s pasted into a config file, or an MCP server added to a JSON file. No one was asked to approve the creation of an agent; it just happened.
2. Every account has a known owner.
In access review procedures, a named human confirms that the reviewed account should still have access. For agents, it’s common not to have a named owner. You need to piece that together after the fact, from circumstantial evidence and conjecture, by examining the agent’s artifacts associated with humans, such as keys and repos.
At scale, agent ownership is an educated guess rather than a deterministic record. SOC 2 doesn’t account for this: a guessed owner and a recorded owner look the same in a review spreadsheet.
3. The name in the log pinpoints the actor.
This is the expensive one, which we already mentioned in our 10:03 am example. Often, agents work with borrowed credentials: a logged-in session, a dev token, or a service account. That’s the person who will appear in your logs and in your access review. This will pass the review, while absolutely ignoring the security differences between people and agents.
On the one hand, the access review will be completely accurate. On the other hand, it won’t tell you what you actually need to know. A recent study with Cloud Security Alliance found more than two-thirds of organizations cannot clearly distinguish AI agent actions from human ones.
4. What an account can do tells you what it’s expected to do.
Least privilege operates under the assumption that an account has a permanent job, and the list of things it can do tells us what it’s for. And for people, that’s usually correct. Unless your CEO wants to be an admin everywhere, access levels are tailored to the job.
For agents, the access limits the blast radius, but it doesn’t tell you what the agent is expected to do at any given moment. That depends on the instructions received, the context absorbed, and the decisions the agent makes. So, checking permissions gives you the widest possible view of what can happen without providing context for the agent’s actions.
Your SOC 2 report says the controls worked, but it never says what they missed. Agents run on borrowed credentials, with no owner and no off switch.
Token Security finds every agent, assigns an identity, and remediates its access to the job it was made to do.
Three controls that pass without covering anything
Here’s how the assumptions we’ve mentioned reduce the effectiveness of three SOC 2 controls.
Nothing ever says an agent should stop (CC6.3)
Every SOC 2 audit tests offboarding, and for human employees, companies have gotten very good at it. HR systems, IdP, and SaaS systems work in tandem when the HR department flags a person for offboarding, thereby exercising its unquestionable authority. Even the evidence writes itself.
There aren’t any HR systems for agents. There’s no centralized, agreed-upon body that’s in the position to say a specific agent should stop. It’s not a broken control, but one that just doesn’t encompass agents and the identities they use.
What makes it worse is that agents are mostly tied to humans, so when a person leaves, the agents set up in their name might keep running using OAuth grants or API keys, unless this scenario is accounted for.
Vendor review starts at purchase (CC9.2)
SOC 2 manages processes relating to vendor relationships. You contract, assess, collect a report, and review it annually; it works well for vendors who arrive on a purchase order. An MCP server is a vendor in every way that matters: it receives your data, acts on your behalf, and runs code nobody in the company reads.
Instead of a purchase order and a data agreement, it arrives in a config file. Often, there’s no company at the other end at all.
About three in ten names in our registry cannot be matched to an existing company. That’s a naming-space figure, not a specific environment, but it points to a fundamental compliance issue for many MCPs: you can’t receive a SOC 2 report from an unnamed vendor.
The same problem appears for AI agents. When we find them on employee machines, only some are safe to block; the rest are held back because the program’s name can collide with something the customer built. Identifying an agent is harder than identifying a person. If you’re ready to explore the AI Agent Security controls, book a demo with Token Security to see what’s hiding in your environment.
Segregation of duties between two instances of the same policy (CC8.1)
When implementing change management, changes should be authorized, tested, approved, and implemented. In most implementations, the author and the approver must be different people due to segregation of duties.
When an agent makes a change and a second agent reviews it, the separation is only nominal, even though two identities were involved.
Meanwhile, the authorization moved beyond the scope of the audit. The decision about the change can happen in a prompt, in a tool that appears nowhere in the system description. The only evidence is a pull request.
The strongest argument against all of this
It’s worth noting that nothing in the Trust Services Criteria says “human”. CC6.2 uses “internal and external users,” whereas CC6.1 uses “protected information assets.” The criteria were written to avoid naming technologies and to describe results rather than methods. So there’s no reason not to cover agents.
You treat machine accounts as users, list agents in the system descriptions, and test them properly. It’s a thing that happens in the real world.
That said, given the current level of disruption, the ambiguity might not be enough. With no specific mentions of agents in the criteria, what gets covered is agreed between you and your auditor.
Both of you have a reason to prefer a scope that’s easy to evidence. As long as you can leave agents out without recording a single exception, some people will do it.
What a clean report has never meant
A clean report means your controls behaved the way you said they would, not that the description was complete. The gap used to be small enough to ignore, but it is no longer.
It is now entirely possible to hold an unqualified Type 2 report and be unable to answer, on the day it is issued, four questions about your own production environment.
|
Question
|
The control that covers it
|
Why it’ll pass
|
|
What is running in there?
|
User registration and authorization (CC6.2)
|
The agent was never registered, so nothing looked missing
|
|
Who authorized it?
|
Change authorization (CC8.1)
|
The decision happened in a prompt, upstream of the evidence
|
|
Whose credentials are they carrying?
|
Access review (CC6.1)
|
A real employee’s credentials, with an approved role
|
|
Who could switch it off?
|
Access removal (CC6.3)
|
Offboarding ran correctly and never flagged agents
|
SOC 2 is not wrong. It is accurate about a world that moved. So treat machine accounts as users, and go further than the report asks. The permission list can tell you what an agent can reach; it does not tell you what an agent is there to do.
Closing this gap is what we mean by intent-based security: you establish what each agent is meant to do, then you make its access match. Identity is the layer where that control actually holds because it spans every system the agent touches.
The report will not change, but these controls are there for a reason, and attackers don’t care about checklists.
Every environment has an access review line that looks approved but says nothing. Token Security shows you the agent behind it: who owns it, whose credentials it uses, and whether what it can reach still aligns with what it’s there to do.
Book a demo and we’ll walk your environment together.
Sponsored and written by Token Security.
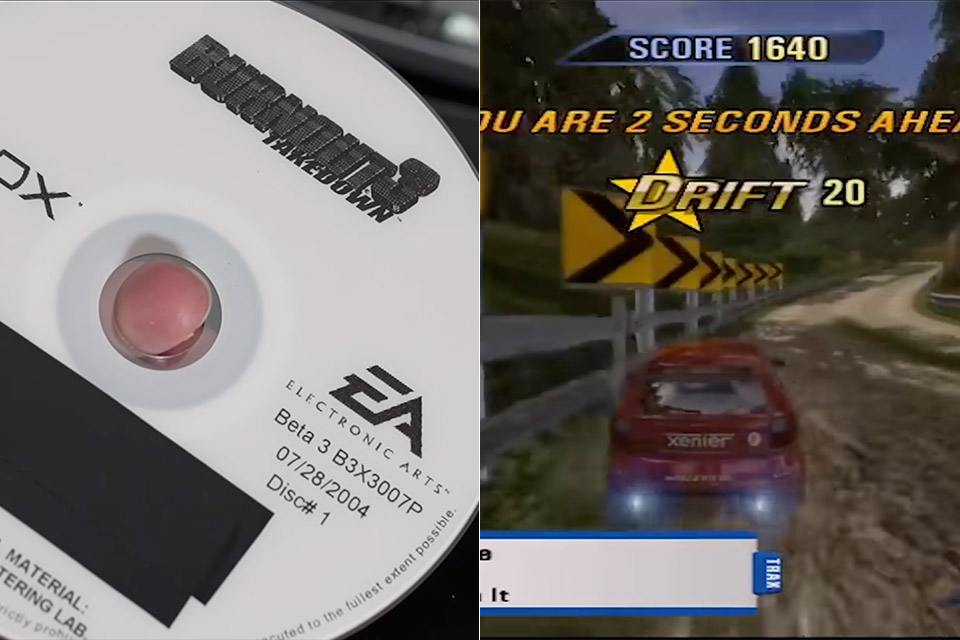
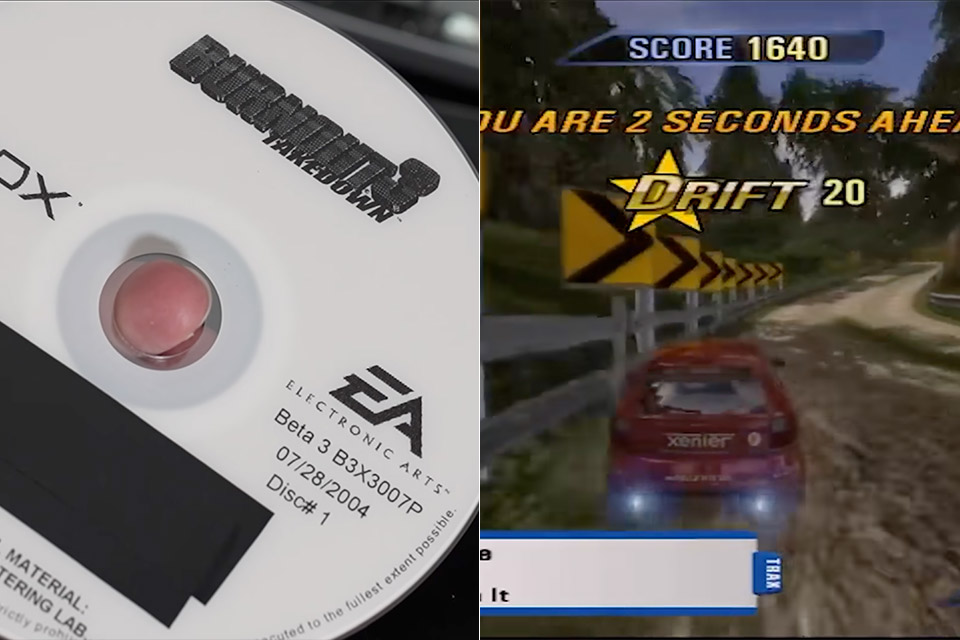
Game preservationist MattKC spotted an undocumented original Xbox copy of Burnout 3 on eBay this summer and paid a steep price to have it shipped from Australia. Printed on the face is July 28, 2004, the words Beta 3, and a warning that reads Confidential material: return to mastering lab. A name on the label, blurred in the video for privacy, belonged to a product manager at EA Australia, which fits the moment Electronic Arts bought Criterion and took the series in-house. How the disc left that office and landed on a public auction remains a guess.
Retail Xbox games normally put their data under a DVD-Video wrapper to prevent a PC drive from accessing them after a brief warning, but this DVD-R disk was an exception. It was a purple-tinted consumer DVD-R that had been used for a development kit. So, when connected to a normal drive and ran through DiscImageCreator, it produced a clean 3.7 GB image in just a few minutes. XDVDMulleter then unpacked the data, and after a bit of a tussle, the build was booted up by the emulator Xemu. There was no program database file on the disk, which would have been extremely unlikely for a late master.
Sale

Lenovo Legion Go S – 2025 – Mobile Gaming Console – AMD Radeon graphics – 8″ PureSight IPS Display…
- ALL GAMES, ALL PLACES, ALL YOURS – Get ready to game on the 8″ 120Hz Lenovo PureSight display and launch any title using Legion Space. The AMD Ryzen…
- SEE EVERY DETAIL – Make every scene pop with 500 nits of stunning brightness and 100% sRGB color accuracy. And with 10-point touch support, your…
- PLAY YOUR WAY – Play hundreds of high-quality PC games with your complimentary 3 months of PC Game Pass and EA Play. With new games added all the…
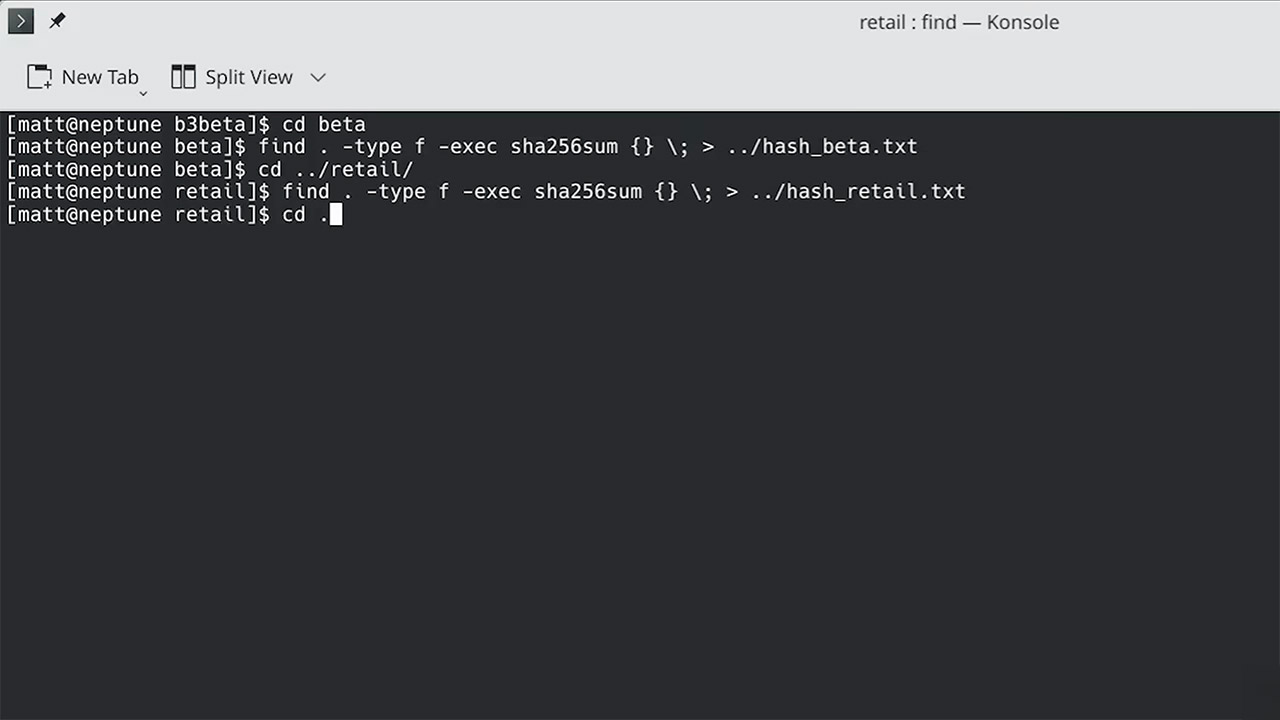
Running a hash check on all the files against a PAL retail dump revealed eight changes, one of which was the main executable. Signing accounts for a portion of the difference. Criterion had created this particular copy as a debug binary for a development console rather than a retail-signed XBE for a store disk. The English in-game play appears almost identical to the finalized game. However, changing the language triggered the appearance of a few strings that had been written to run too long for the UI. The retail version of the game just condensed those sentences. References to a generic server for online play were replaced with an EA server in later files. You also lose Xbox Live and Insignia hosting Burnout 3, as those strings would never appear in a live session anyhow.
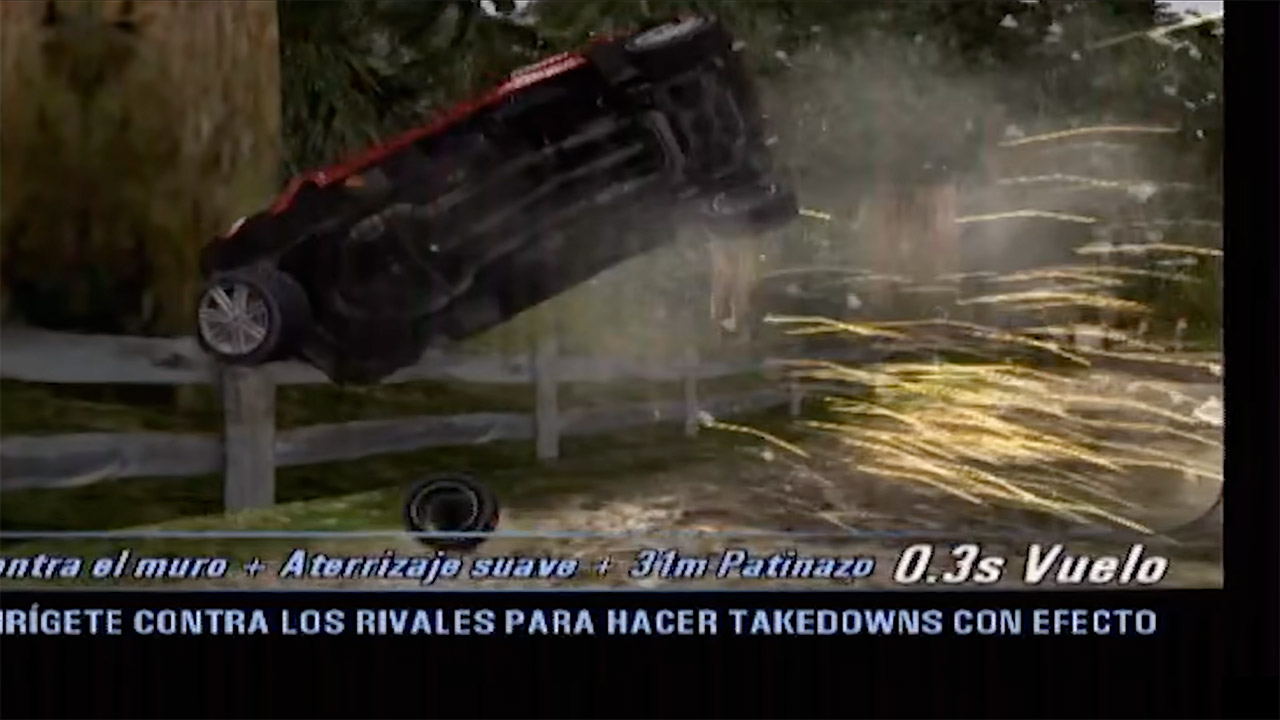
Crash mode contains the most significant code modification discovered by MattKC. After getting some considerable air in a wreck, the beta simply outputs out the height using a standard sprintf function and one decimal point. A few European languages, however, use a comma to mark that point, so the retail executable includes a bespoke formatter to ensure that local punctuation is respected. That’s about the extent of the differences; no leftover cars, no cut tracks, and no debug menu sticking about in the menus. Criterion had evidently finished the US executable about an hour before this disk was released, and the European one approximately 6 days later, which explains why the remaining work appears to be copy fitting rather than any meaningful new features.
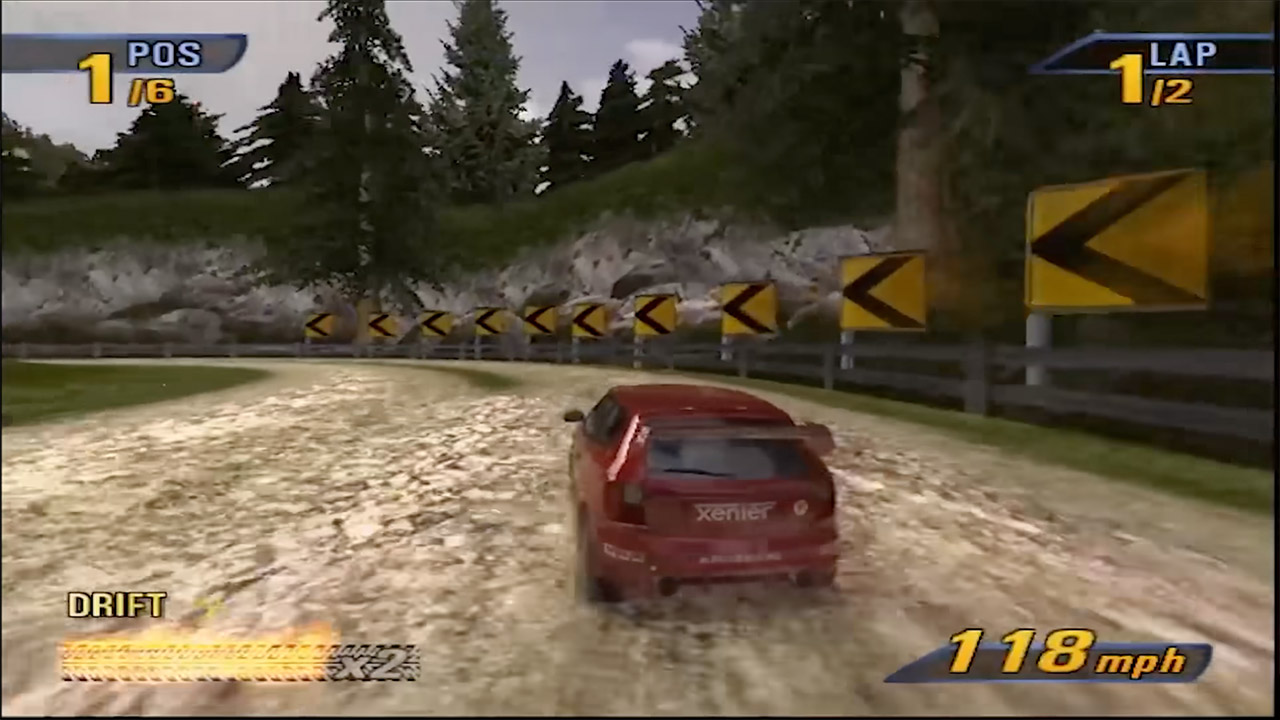
MattKC thought this buy was a poor source of hidden material but an excellent shelf piece. He did, however, submit the ISO to the Internet Archive as Burnout 3: Takedown, Xbox Beta 3, 07/28/2004, so that anyone can look without having to search for another one of those burned DVD-Rs. For a game so close to being ready for release, the archive is the real treasure. You now have a late PAL localization pass out in the open, dated and hashed, which is more than most corporate disks receive even after 22 years.
[Source]

Tech4 minutes ago
You Can Check Your Samsung Galaxy’s Health With A Built-In Test

Crypto World9 minutes ago
Bitcoin price faces $85,000 resistance as oscillator turns negative

NewsBeat10 minutes ago
Haxby Road in York to close overnight for highway works





-

 Crypto World4 days ago
Goldman Sachs and Deutsche Bank Agree: The S&P 500 Rally Isn't Over
-

 Tech6 days ago
Researchers escape OpenAI Codex sandbox to run commands on host
-

 Fashion2 days ago
8 iPhone Accessories That Add Personality
-

 Crypto World6 days ago
Who Needs CLARITY Anyway? ARB Could See 70X Increase: Hodler’s Digest
-

 Tech7 days ago
Trump suggests rebranding AI with a new name, says he’s also creating an AI Force
-

 Entertainment3 days ago
These 17 Fall Amazon Dresses Seriously Look Like Anthropologie
-

 Business6 days ago
Analog Devices (ADI) Bets $1.35 Billion on Chips that Let Machines Think for Themselves
-

 Crypto World6 days ago
Coinbase, Robinhood, Circle Seen as Tokenized-Stock Winners
-

 Crypto World3 days ago
This Bearish Netflix Stock Trade Can Cash In On Video Streaming Giant’s Woes
-

 Tech5 days ago
Google’s $899 Googlebook is a bet that you’ll buy a new laptop for Gemini
-

 Crypto World4 days ago
Trump-Xi Polymarket Odds for Handshake Hit 50%
-

 Crypto World3 days ago
Crude Oil Prices Pressured by Diplomatic Hopes in the Middle East
-
 Business3 days ago
Oil Price Today (September 23): Crude oil below $100 on hopes of US-Iran talks. What did Trump say?
-
 Crypto World3 days ago
Bitcoin price tests $83,600 Supertrend support after $87K rejection
-
 Fashion20 hours ago
Weekend Open Thread: J.McLaughlin – Corporette.com
-

 Crypto World3 days ago
Bitcoin Threatens Sub-$84,000 Breakdown as Long Liquidations Spike
-

 Crypto World4 days ago
Meta Jumps 11% As Muse Shines and Investors Show an Appetite for Advancing AI
-
 Crypto World4 days ago
Did Jim Cramer Just Give GameStop Stock the Kiss of Death When He Said the Turnaround Is Working?
-

 Crypto World5 days ago
Bitcoin price holds above $81K as key catalysts line up
-
 Crypto World6 days ago
ARB Price Signals Spur Speculation of 70x Upside in Hodler Digest
You must be logged in to post a comment Login