Hope there’s extra room in your pockets. A new rumor says Apple’s iPhone 20 Pro and Pro Max could have the largest displays in iPhone history, alongside a quad-curved, nearly all-glass exterior.
Digital Chat Station, a prominent anonymous tech insider on the Chinese social media platform Weibo and a reliable source of Apple news in the past, posted over the weekend that the iPhone 20 Pro screen would be 6.41 inches and the Pro Max 6.96 inches, measured diagonally. The iPhone 18 Pro and Pro Max, which hit stores last Friday, measure 6.27 inches and 6.86 inches (which Apple rounds up to 6.3 inches and 6.9 inches). The iPhone Duo, Apple’s long-awaited first foldable phone, which reaches stores on Oct. 23, has a diagonal 7.6-inch inner display when open.
A representative for Apple did not immediately respond to a request for comment.
CNET Senior Reporter Abrar Al-Heeti said that larger screens are great for watching videos and working on the go, but bigger displays also mean higher costs for consumers, serving as an “excuse for companies to charge you more.”
Advertisement
“Along with the commemorative angle of the iPhone’s 20th anniversary, it’s likely Apple could use design elements like a bigger screen and an all-glass design to hike prices,” Al-Heeti said.
More glass, smaller Dynamic Island
Digital Chat Station backed Bloomberg reporter Mark Gurman’s August report that the exterior of the new flagship phones would be nearly all glass in what’s called a quad-curved design. That means the glass will wrap around all four sides of the phone, making it look as if there is no bezel.
In his report last month, Gurman said that the glass on the front and back of the phones would “curve into the sides of the devices, with a metal band in the middle.”
The exteriors of the iPhone 18 Pro and Pro Max are made of aluminum and ceramic glass.
Advertisement
The iPhone 20 Pro and Pro Max will also have a smaller Dynamic Island and a tiny punch-hole selfie cutout on the front, according to Digital Chat Station.
The Dynamic Island is the capsule-shaped region at the top of the front screen that houses the selfie camera. It also expands and contracts to display notifications, system alerts and background activities.
The iPhone 20 Pro and Pro Max are expected to launch in September 2027 as the next iteration in the series. Apple is widely expected to skip over the iPhone 19 name and jump straight to iPhone 20 next year, marking the 20th anniversary of the first iPhone launch in 2007.
Ever since being admittedly fascinated by the Cambridge coffee webcam from the 1990s, I’ve written about VPNs, the NFL, smartphones, living wages, over/unders and everything in between.
See full bio
Ripple effect: Microsoft may be backing away from the Copilot+ PC branding, but it’s doubling down on the bigger idea behind it: turning AI into a layer that actively runs your computer and gets work done for you. Its latest Copilot overhaul pushes that vision further than before, combining Office, coding tools, and autonomous agents into what CEO Satya Nadella calls a “new OS for work.” Public testing begins in the coming weeks.
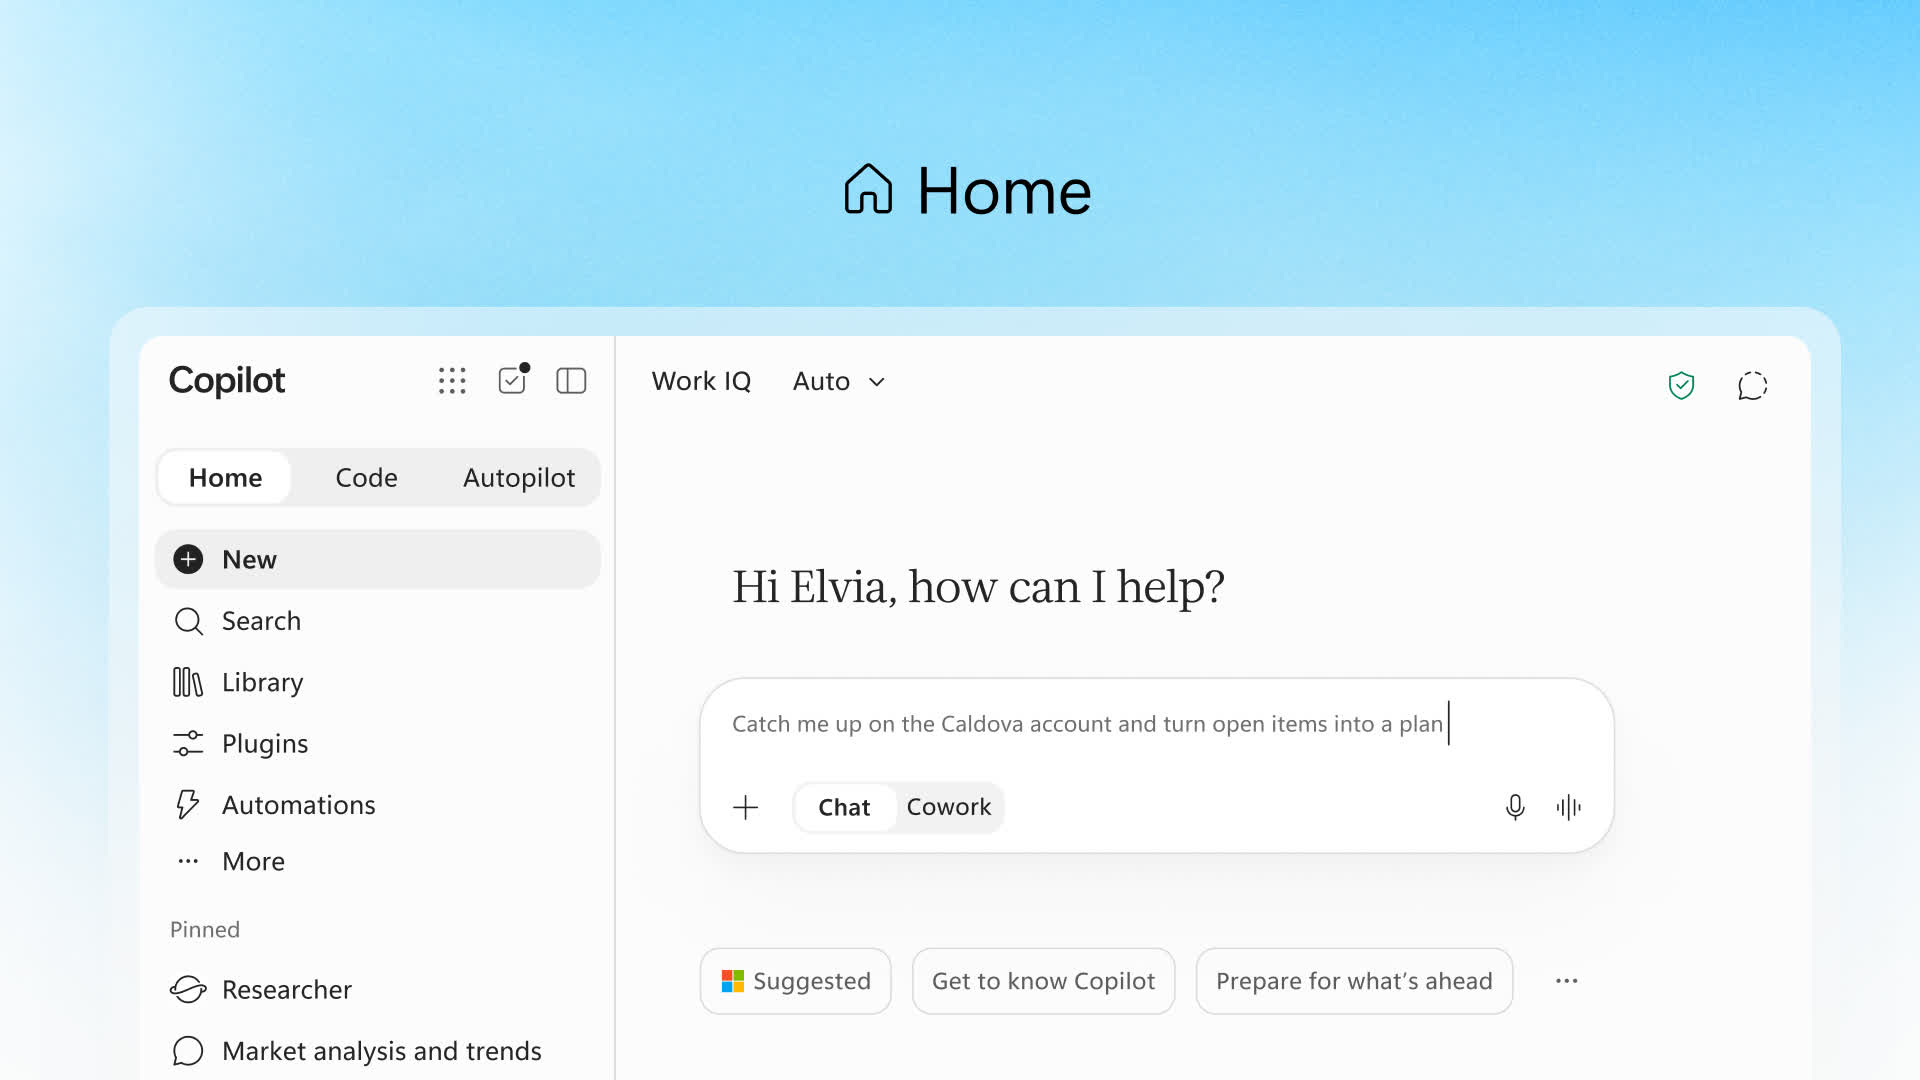
Microsoft recently unveiled a major overhaul for Copilot’s business tools. The new suite hands the AI assistant more control in Office, embeds GitHub Copilot’s functionality into professional toolchains, and automatically coordinates tasks between team members.
The new Copilot implementation, which Microsoft CEO Satya Nadella calls a “new OS,” consists of several parts. One of them, simply called Home, lets users chat with Copilot as it examines files to offer recommendations on how it can help. Home can also take over Office 365 apps such as Word, Excel, and PowerPoint to automatically draft files for users to edit.
Another tool, Code, builds apps based on natural-language prompts using the same tools as GitHub Copilot. Microsoft claims that Code uses Microsoft IQ to maintain contextual knowledge of users’ work environments beyond what it currently sees onscreen.
Advertisement
Lastly, Autopilot, a rebrand of Scout, offers the highest level of automation. After users provide it with a role and an objective, Autopilot handles various tasks such as scheduling meetings, following up with contacts, watching channels, starting and resuming projects, and more, all without further human input. The cloud-hosted feature also works 24/7, working across Teams, Outlook, documents, and other programs while remaining in constant contact with teammates.
Home and Code will enter Microsoft’s Frontier program in the coming weeks, while Autopilot will be available in private preview at the end of this month. Another aspect of Home, called Today, will enter private preview in October. Today aims to show users a unified information space with details from emails, Teams chats, meetings, and other sources while also drafting documents and proposing schedules.
Nadella’s “Copilot OS” claim sounds a lot like the supposedly defunct Project Aion, which would have become a separate OS built around Copilot running within an Edge shell. Users would operate apps and create documents by chatting with Copilot instead of controlling them directly. Although Microsoft might have shelved Aion, a video demonstration of the new Copilot update closely resembles certain aspects of it.
Advertisement
Notably, this latest push to embed Copilot in users’ systems follows an admission from Microsoft and Qualcomm that the Copilot+ PC brand has been abandoned, with the companies acknowledging that consumers simply don’t care about “AI PCs.” It remains unclear whether Home, Code, and Autopilot will be next in a growing trail of shelved AI initiatives such as Copilot+ PCs and Recall.
Oxford has let OpenAI use old texts from its Bodleian Library to train its AI models, according to internal papers seen by the Guardian. Ethan Penny and Dan Milmo broke the story on Saturday.
The papers say texts that OpenAI scanned at the library went into the firm’s training data.
Oxford made its deal with OpenAI public in March 2025. At the time, it said OpenAI’s tools would help scan rare texts so more students and scholars could read them. It did not say the texts would be used to train AI.
By June 2025, the Bodleian had sent OpenAI 125,000 scans of old PhD theses, the Guardian reported. They include theses written at European and US universities in the 19th and 20th centuries.
Advertisement
Notes from staff meetings, which the Guardian got through a freedom of information request, show some staff had doubts. They worried about harm to Oxford’s name and about the energy use of AI.
However, Oxford said the scans were small in scale, out of copyright and not exclusive to OpenAI. The library keeps the rights and will start to post the scans online in the next few months, a spokesperson said.
The spokesperson also said the AI training side had not been hidden. Scanning was Oxford’s main goal, but staff had been open that the texts would also be used to train models.
“With more than a billion people using this technology in everyday life, it’s important it reflects different cultures, histories and perspectives,” an OpenAI spokesperson told the Guardian.
Oxford is the only UK member of OpenAI’s NextGenAI group. Other members include Boston Public Library, Caltech, MIT and the University of Michigan.
Advertisement
The deal comes as AI firms buy printed books for slop-free training data, since the web is now full of AI-made text. Some buyers cut books apart to scan them, which has upset secondhand booksellers.
In August, 404 Media tracked a box of rare books to an Amazon site that scans and destroys books for AI. The Bodleian’s books stay whole under its deal, the Guardian reported.
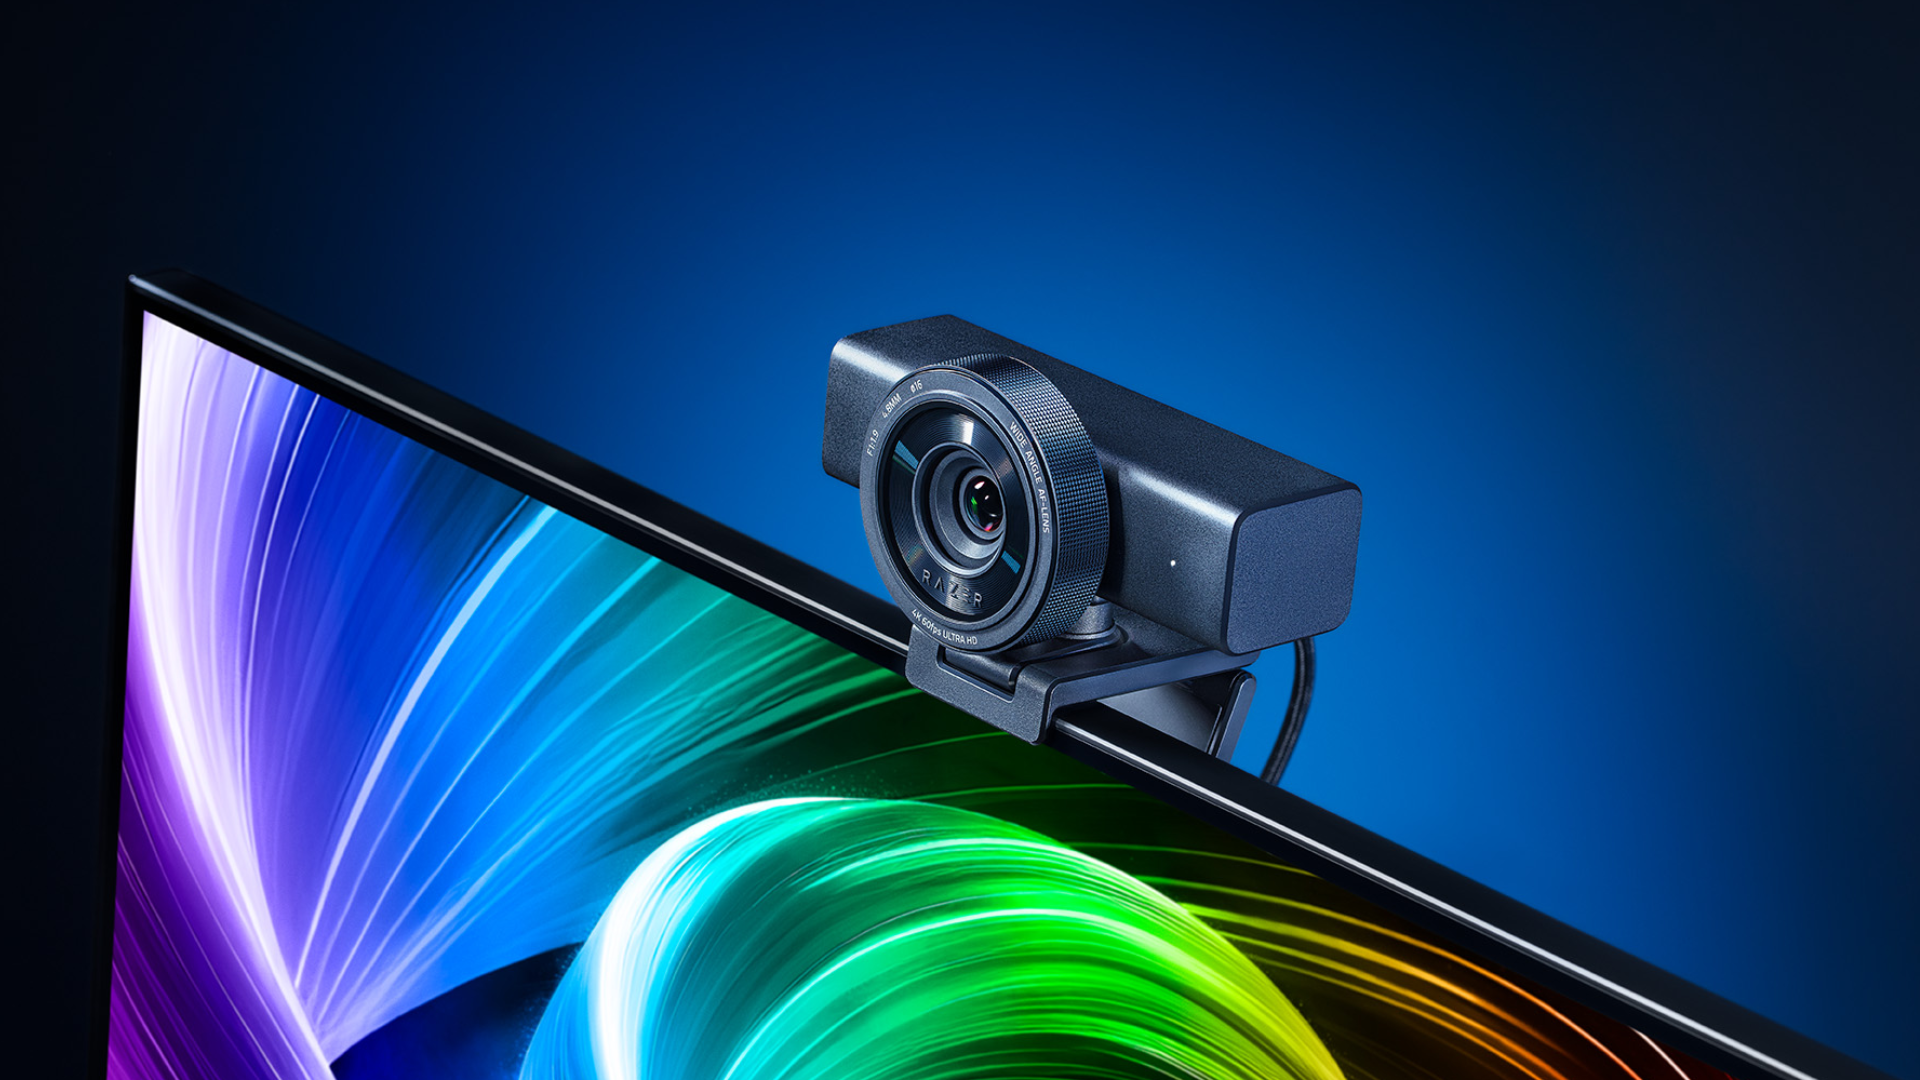
Razer’s new Kiyo V2 Pro webcam uses Sony’s 8.3-megapixel STARVIS 2 sensor and costs $300.
Sony’s STARVIS 2 sensor also enables the headline feature here: 4K video capture at up to 60fps, a specification most consumer webcams still limit to 1080p or 1440p once frame rates climb above 30fps.
Razer pairs that sensor with a lens capable of an f/1.9 aperture, a wider opening than most webcams offer and one that should improve low-light clarity while producing a stronger background blur behind the subject.
AI and imaging features
Beyond the optics, the Kiyo V2 Pro introduces automatic framing, a feature that uses pan, tilt and zoom to keep a speaker centred in the frame, similar to the tools Apple already offers on recent iPhones during FaceTime calls.
Advertisement
Razer has also carried over the one-click output enhancement feature from its microphone lineup, and the camera automatically adjusts exposure, white balance and noise levels to match whatever environment it sits in.
Advertisement
The Kiyo V2 Pro also captures ultra-high dynamic range footage that pulls out more shadow and highlight detail, and Razer has narrowed the field of view from 93 degrees on the original V2 to 86 degrees on the Pro model.
That narrower angle helps the sensor maintain sharper detail at the full 4K resolution and reduces the fisheye distortion that often appears at the edges of a wide-angle frame during video calls.
Advertisement
Software support for the webcam extends to Razer Synapse, which lets users manually fine-tune settings such as ISO and shutter speed rather than relying solely on the automatic modes built into the camera itself.
Razer ships the Kiyo V2 Pro with both a clamp for monitors and laptop lids and a universal tripod mount, alongside an integrated privacy shutter built to resemble a camera’s own shutter mechanism.
Availability and pricing
The webcam is available now through Razer.com and other retailers, and its $300 price places it among the pricier options in the current webcam market.
Razer has not confirmed a UK release date or local pricing for the Kiyo V2 Pro, though the webcam’s US launch suggests a wider rollout is likely to follow in the coming months.
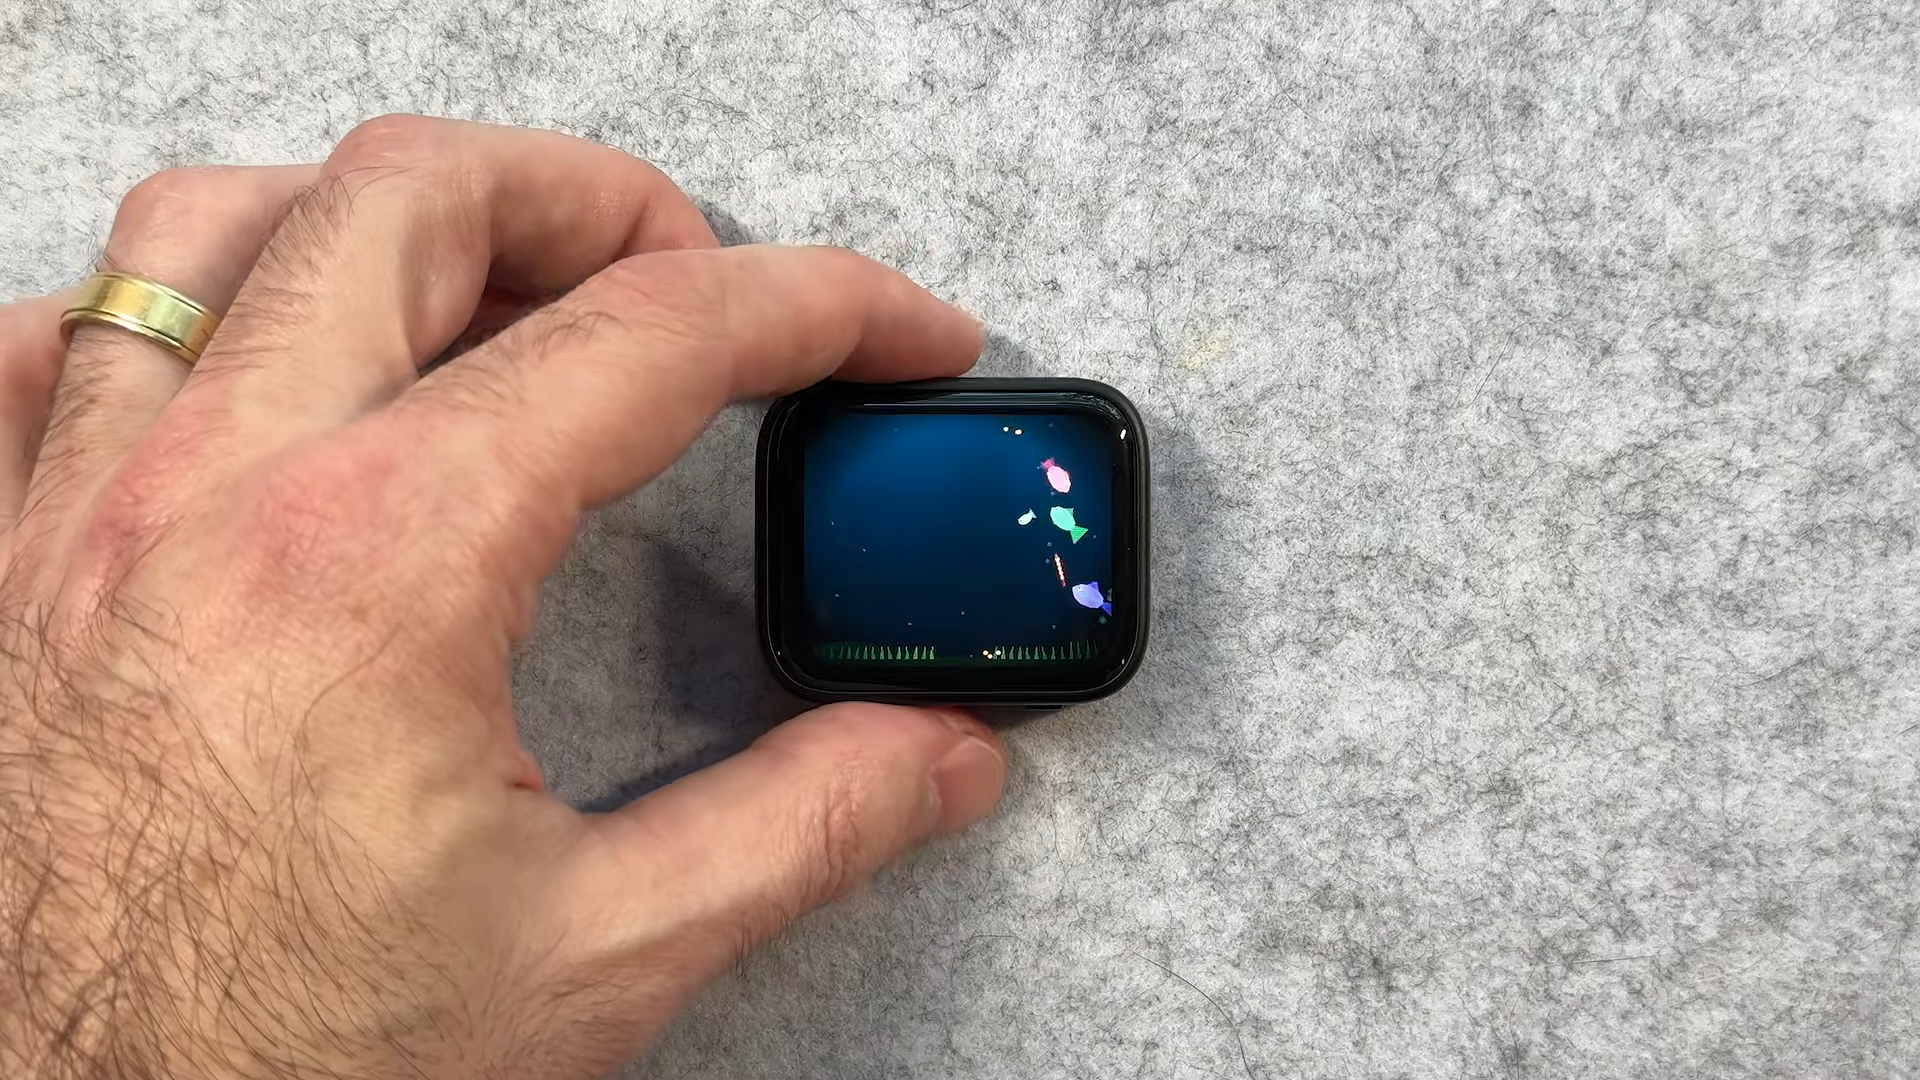
The concept behind Pocket Tank is relatively simple—it’s a small device that displays a virtual tank with a bunch of little fish swimming around inside. It’s based on the Waveshare ESP32-S3-Touch-AMOLED-1.8, which, if you’re wondering, is an ESP32-S3 with a 1.8″ screen attached, all wrapped up in a convenient plastic housing.
Thanks to the powerful microcontroller, there’s plenty of grunt on tap to run and display a small simulated fish tank. [StratoBuilds] whipped up a system wherein fish movement and animations are handled by regular code running at 25-30 fps, while the fish’s decision making is handled by a custom large language model that was condensed down to run on the ESP32 itself. As the fish swim around the tank, the situation is observed by the LLM and the fish’s current goals are changed accordingly depending on what’s going on. Much like a Tamogotchi, there are regular maintenance tasks for the user to handle, too, like cleaning the tank and feeding the fish to keep them alive.
Advertisement
The blog post and YouTube video do a great job of explaining the project; files are on GitHub for those that wish to tinker more directly. It’s funny, because when we normally look at fish tanks, we’re talking about real ones.
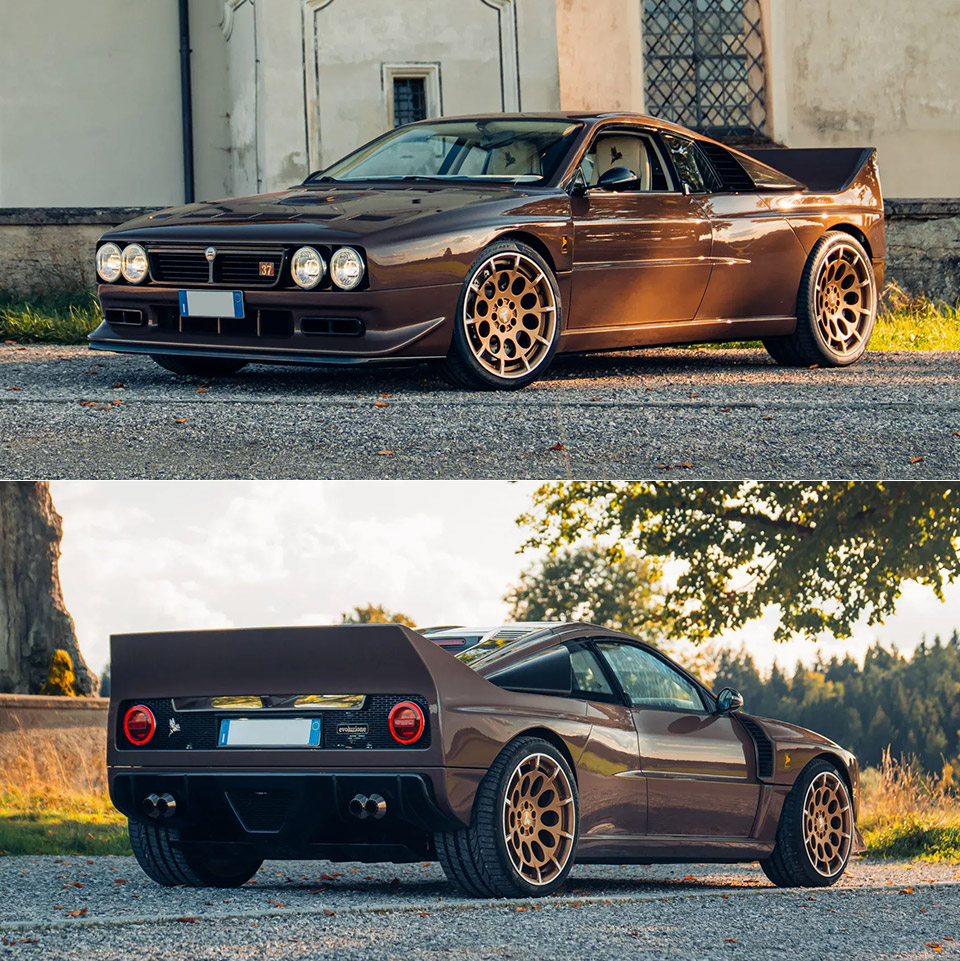
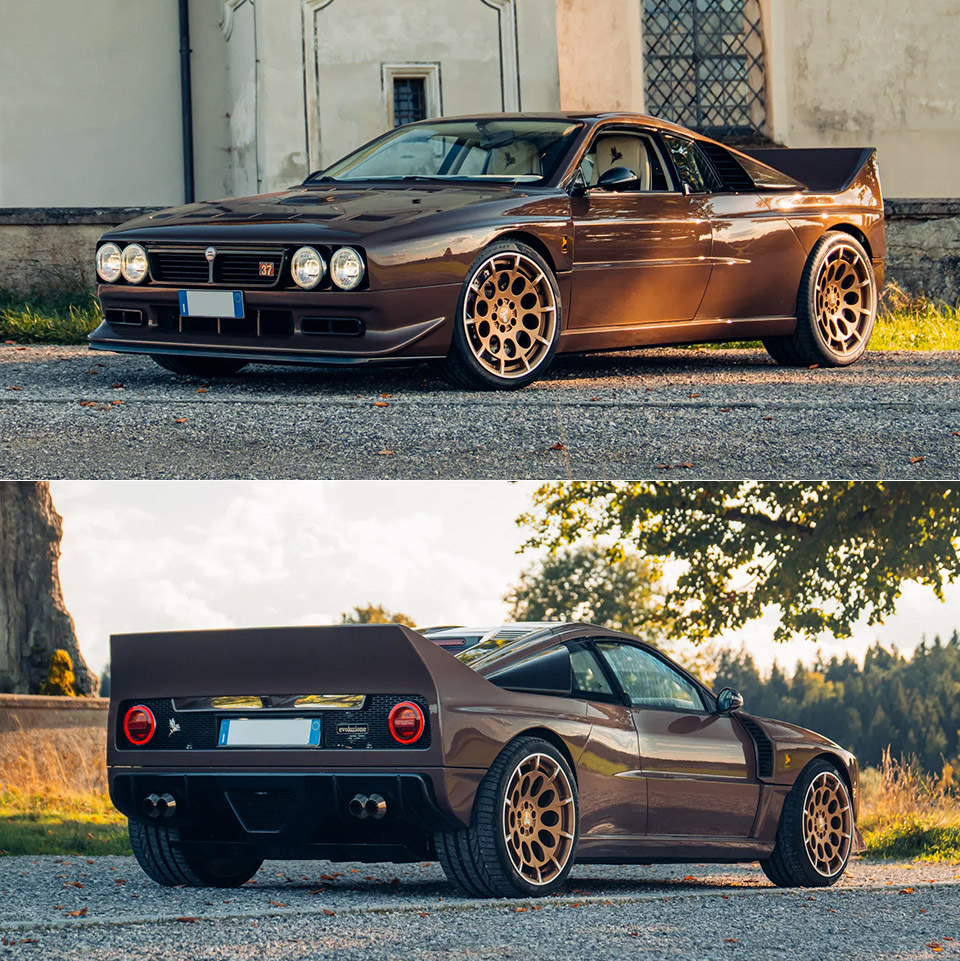
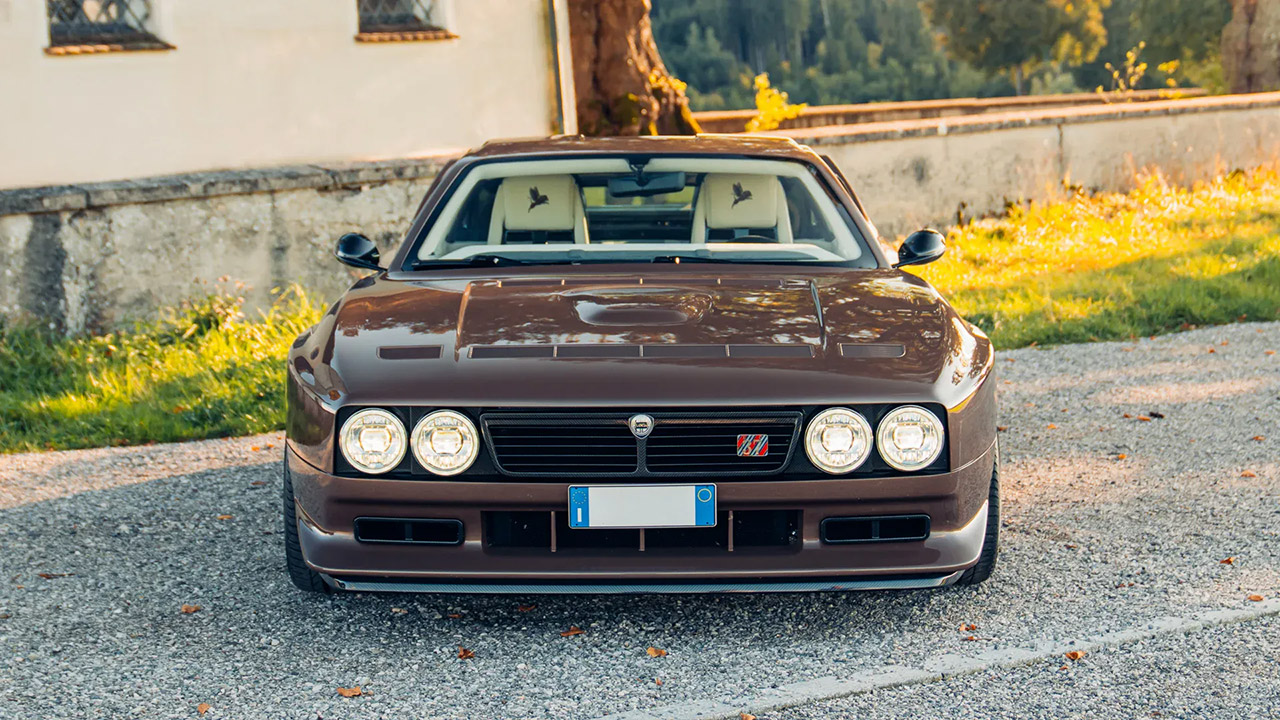
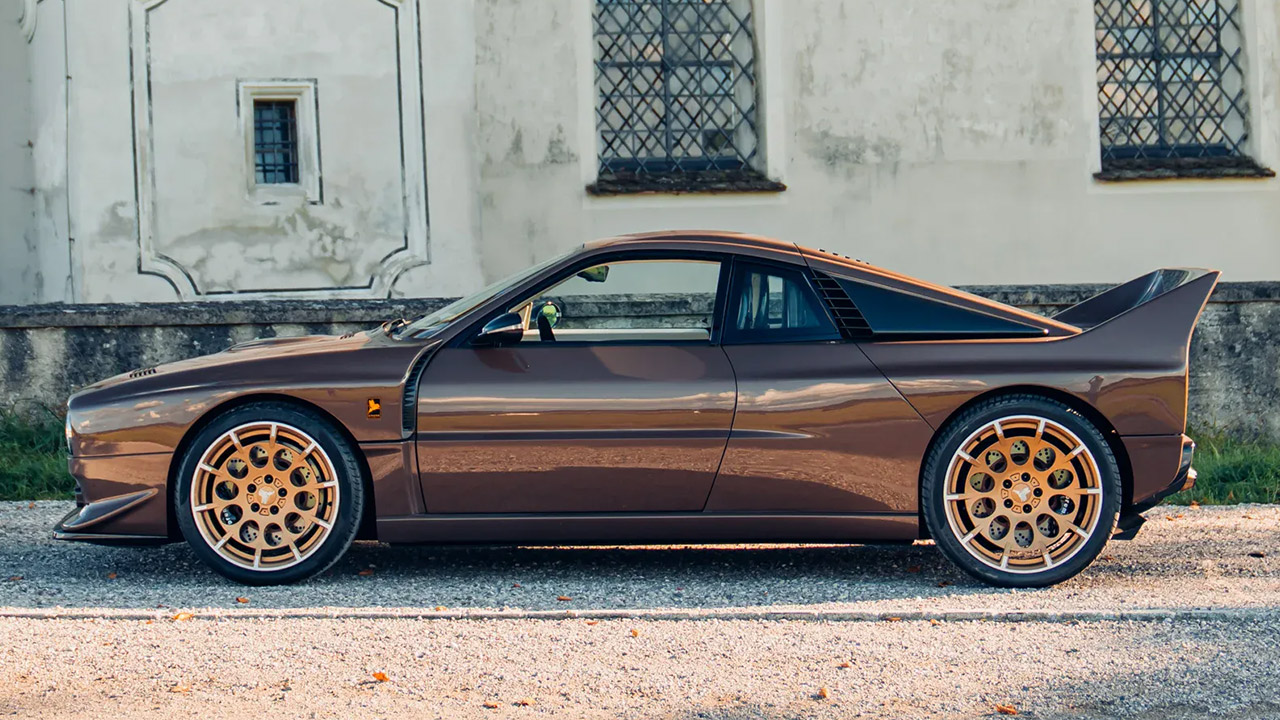
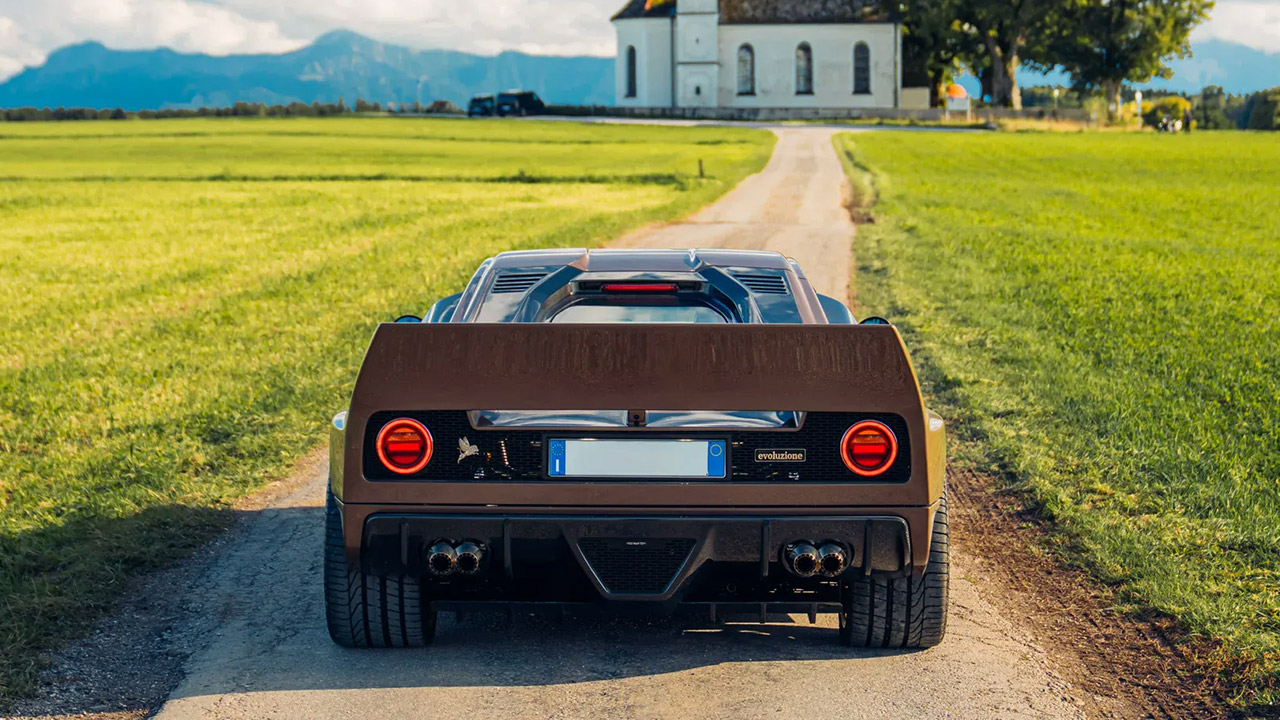
Four decades after Walter Röhrl and Markku Alén drove Lancia’s Rally 037 to the 1983 World Rally Championship, a small Italian workshop in Cuneo has given that last rear-drive title winner a second life. Kimera Automobili, run by former rally driver Luca Betti from Villa Kimera about 100 kilometers south of Turin, limited the EVO37 to 37 cars. Number 018 now sits in Broad Arrow’s catalog as lot 158 for the Zoute Concours Auction on Friday, October 9, 2026, at Approach Golf in Knokke-Heist, Belgium.
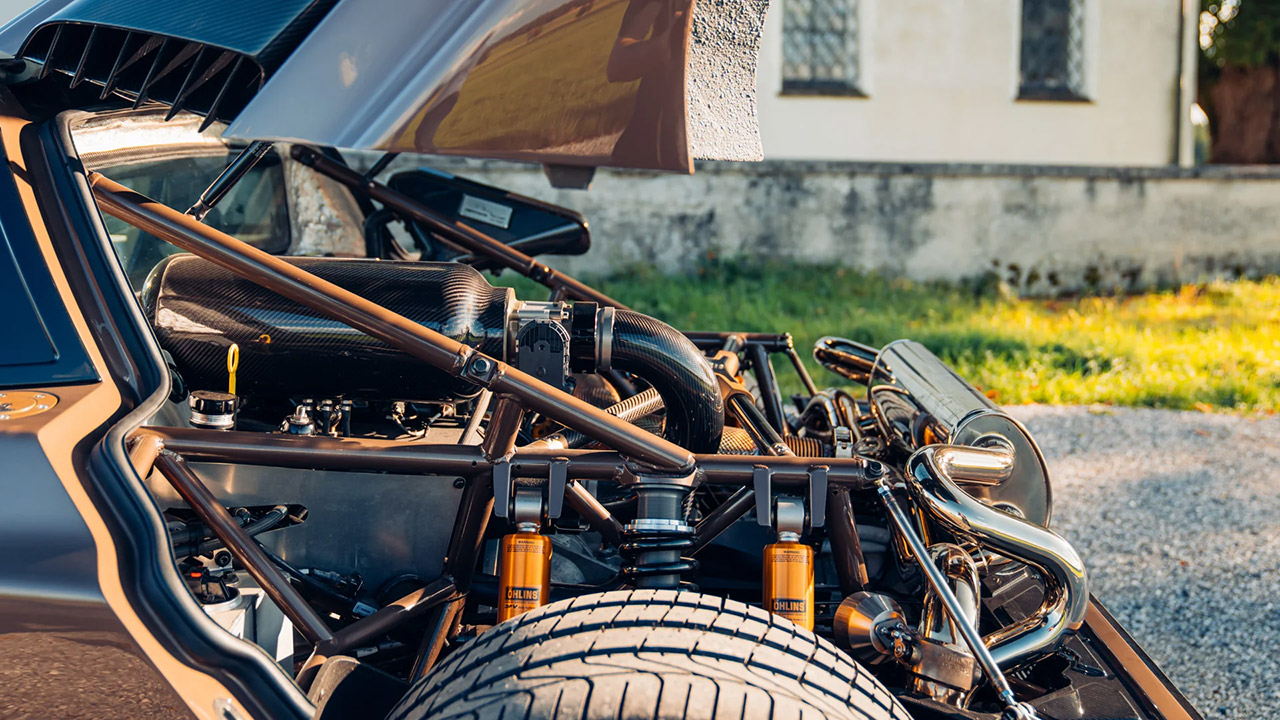
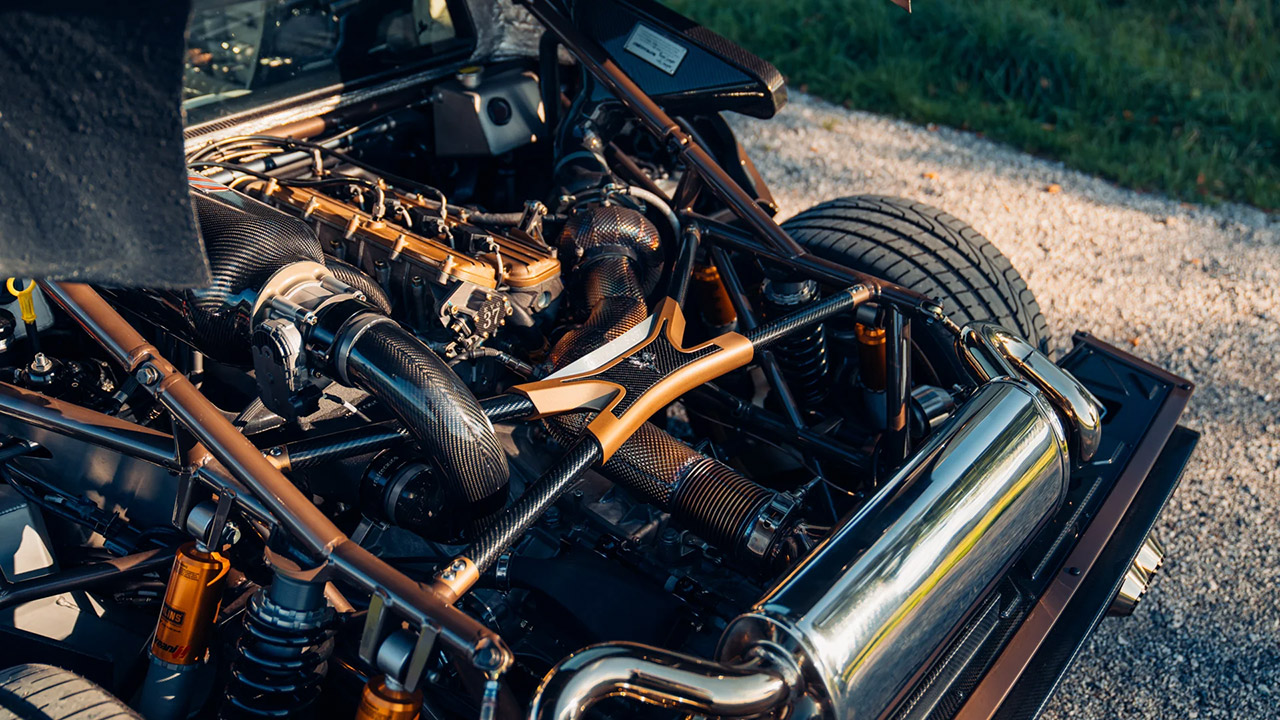
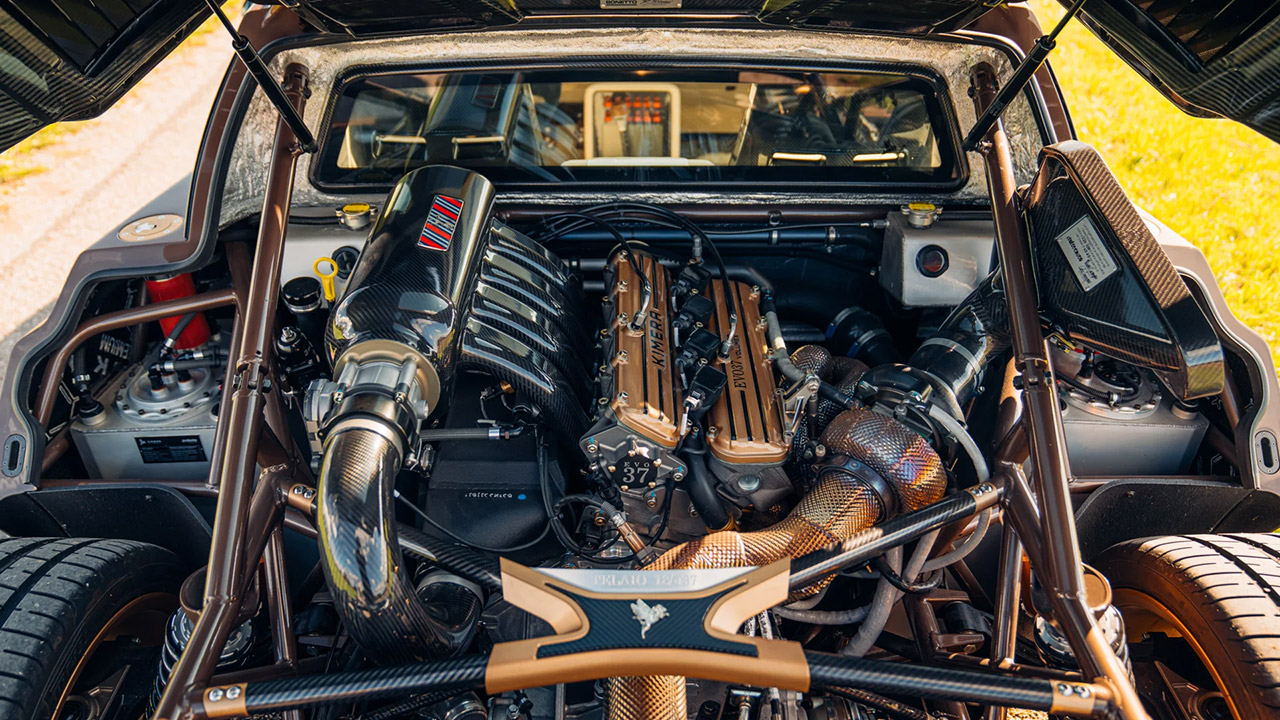
Kimera used the same starting point as the original manufacturer and ran with it: the donor Lancia Beta Montecarlo center section was stripped, reinforced, and improved with a glossy new carbon-fiber shell. Behind all of this was a crew that knew what they were doing, including Sergio Limone, the man who had led the 037 and Delta S4 to great success, and Claudio Lombardi, Lancia’s former rally engine designer who had gone on to do the same for Ferrari in F1, both of whom gave the project their approval. The bodywork was then bolted to the chassis, and Italtecnica created a brand new 2.1 liter, 16 valve four-cylinder engine from the ground up. They preserved the 037’s supercharged configuration but added a turbocharger, resulting in a snappy 505 PS and 550 Nm of torque sent to the rear wheels via a fast six-speed Dana Graziano manual gearbox. The top speed is rated as 310 km/h, with a 0-100 km/h time of just 3 seconds, which is not bad. The vehicle features Öhlins double-wishbone suspension and Brembo carbon-ceramic brakes with four-piston calipers for stopping power.
CUSTOM MUSTANG RACE CAR – This LEGO Speed Champions Ken Block’s ’65 Ford Mustang Hoonicorn V1 (77262) building toy for boys and girls ages 9 years…
AUTHENTIC DETAILS – Builders will recognize cool features from the car’s debut in the 2014 Gymkhana SEVEN film, including exposed velocity stacks on…
KEN BLOCK MINIFIGURE – The included Ken Block minifigure features a Hoonicorn hat and jacket, plus an extra helmet accessory for added play value
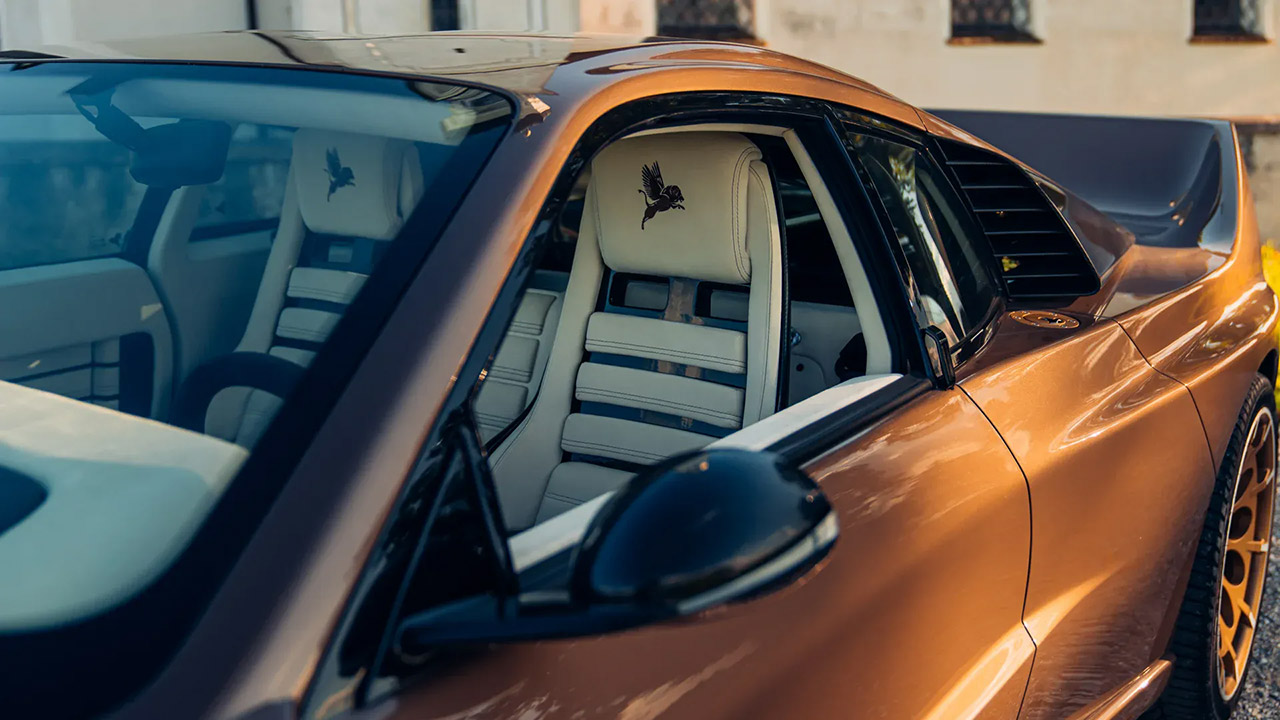
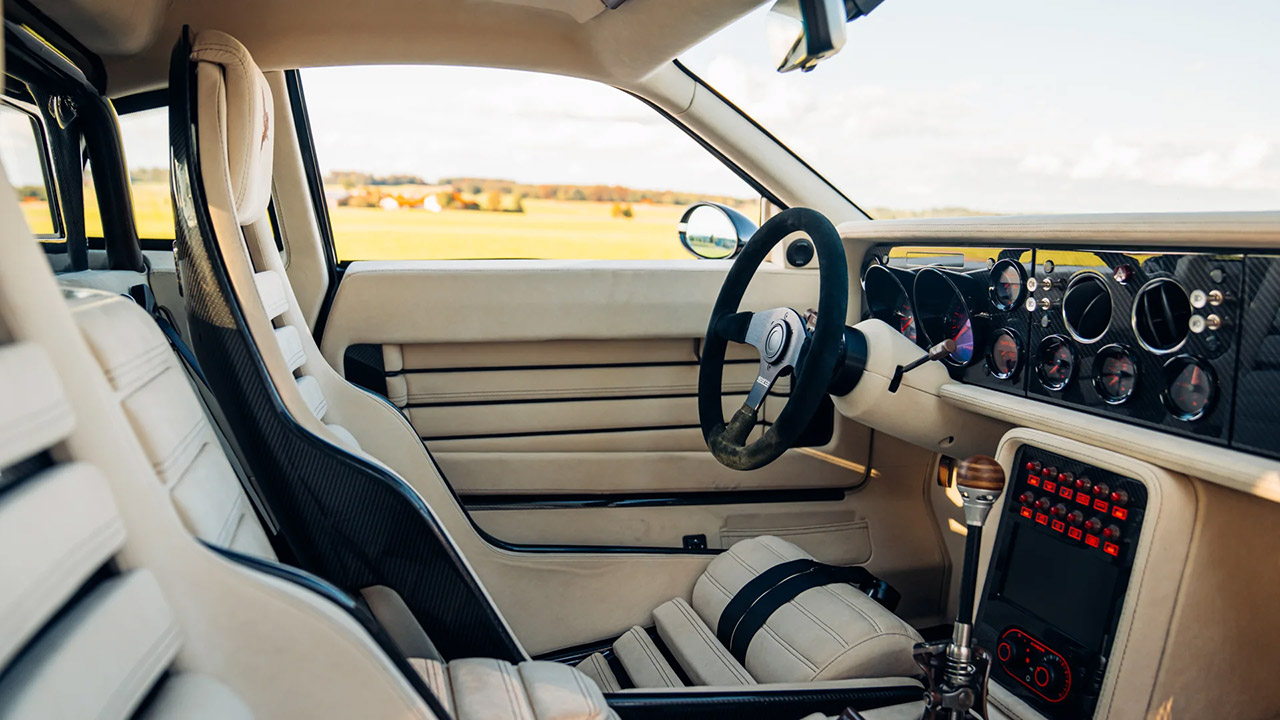
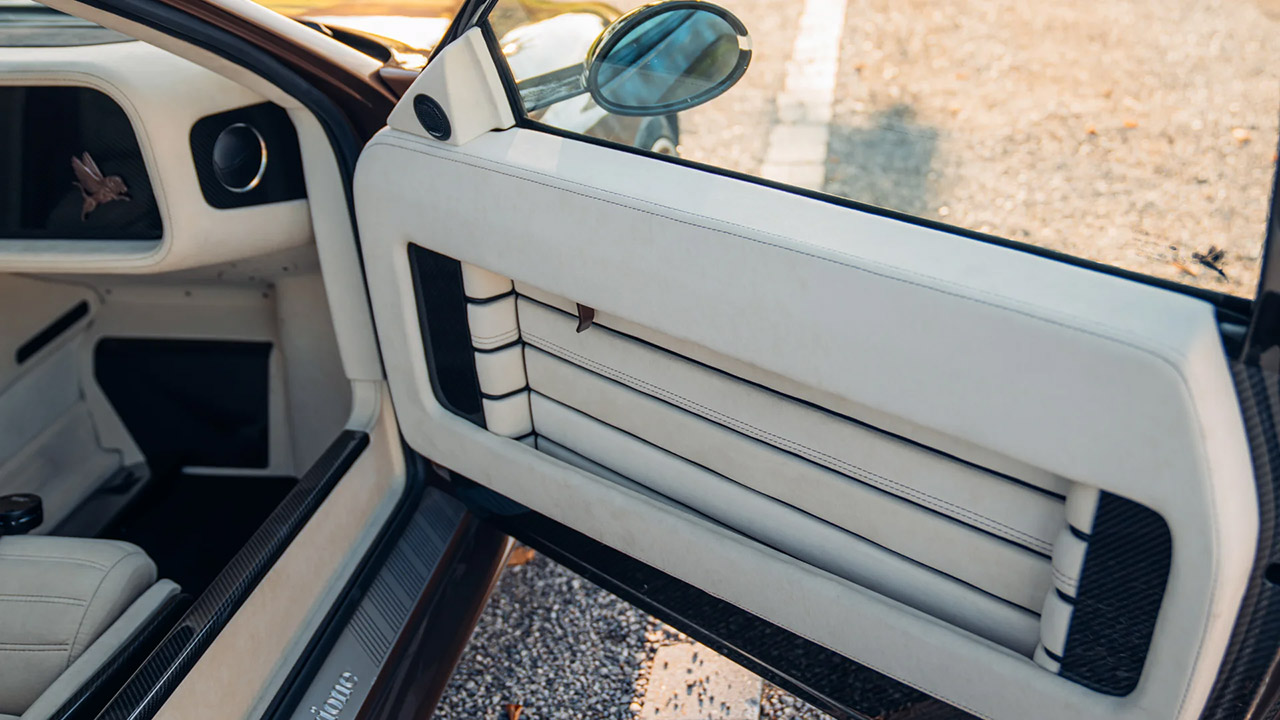
This vehicle left the workshop in March 2025 and has since traveled a total of 237 kilometers. Kimera’s Luci del Bosco paint job is a deep, rich metallic brown inspired by the old Lamborghini Miuras and Countachs. The gold wheels and beige leather upholstery over carbon fiber chairs give the cabin a relaxed feel, while the exposed gearlever is adorned with a wooden gear knob. LEDs light the road up front, and there’s air conditioning, ABS brakes, a digital rear view camera, and parking sensors to keep things polite without interfering with the exposed carbon, which is exactly what you want to see.
When this project first got off the ground in 2021, the asking price ranged between €450,000 and €480,000. Since then, the market has moved on, and Broad Arrow thinks that this particular specimen, number 018, is now valued between $950,000 and $1,150,000. Kimera has informed the Broad Arrow team that they will gladly assist with import and registration if the future owner is in Europe or the United States, and will even adjust the specifications to suit the buyer if they prefer something different. The tax issue is equally easy; because this is a VAT-qualifying sale, both the hammer price and the buyer’s premium are subject to tax.
The auction of this car will take place on October 9, 2026 as part of the Zoute Grand Prix Car Week, with a public viewing on the 7th and 8th and bidding beginning in the afternoon of the ninth. It’s a rare opportunity to own an original 037 Stradale that is this new and in this condition, and if that’s not enough, Kimera is still willing to re-spec the thing if the buyer has any other ideas. [Source]
Renault is bringing one of its most recognisable performance cars into the electric era with the Renault 8 Gordini Concept, a two-seat electric coupé inspired by the rear-wheel-drive icon that debuted in 1964.
The concept combines the visual language of the original R8 Gordini with a much more aggressive modern design. It has a low, wide stance, motorsport-inspired proportions and a 270hp electric motor. Renault says the project is part of its wider effort to revisit important models from its 128-year history through one-off creations.
Renault unveiled the concept on September 24 at Renault Carwalk, and it is scheduled to appear at the Paris Motor Show from October 12 to 18.
The classic Gordini gets a radically different electric makeover
The original Renault 8 Gordini arrived in 1964 with a 95hp rear-mounted engine and rear-wheel drive. It became known for delivering racing-inspired performance in an affordable package and served as a training ground for drivers including Jean Ragnotti. Its distinctive double white stripe eventually became a defining visual feature.
Advertisement
The new concept keeps the rear-wheel-drive character but replaces the petrol engine with a 270hp electric motor. Measuring 4.12 metres long, 1.88 metres wide and 1.27 metres tall, the coupé sits on 19-inch front and 20-inch rear wheels. Its proportions are deliberately closer to a modern rally car than the four-door original.
Renault 8 Gordini Concept
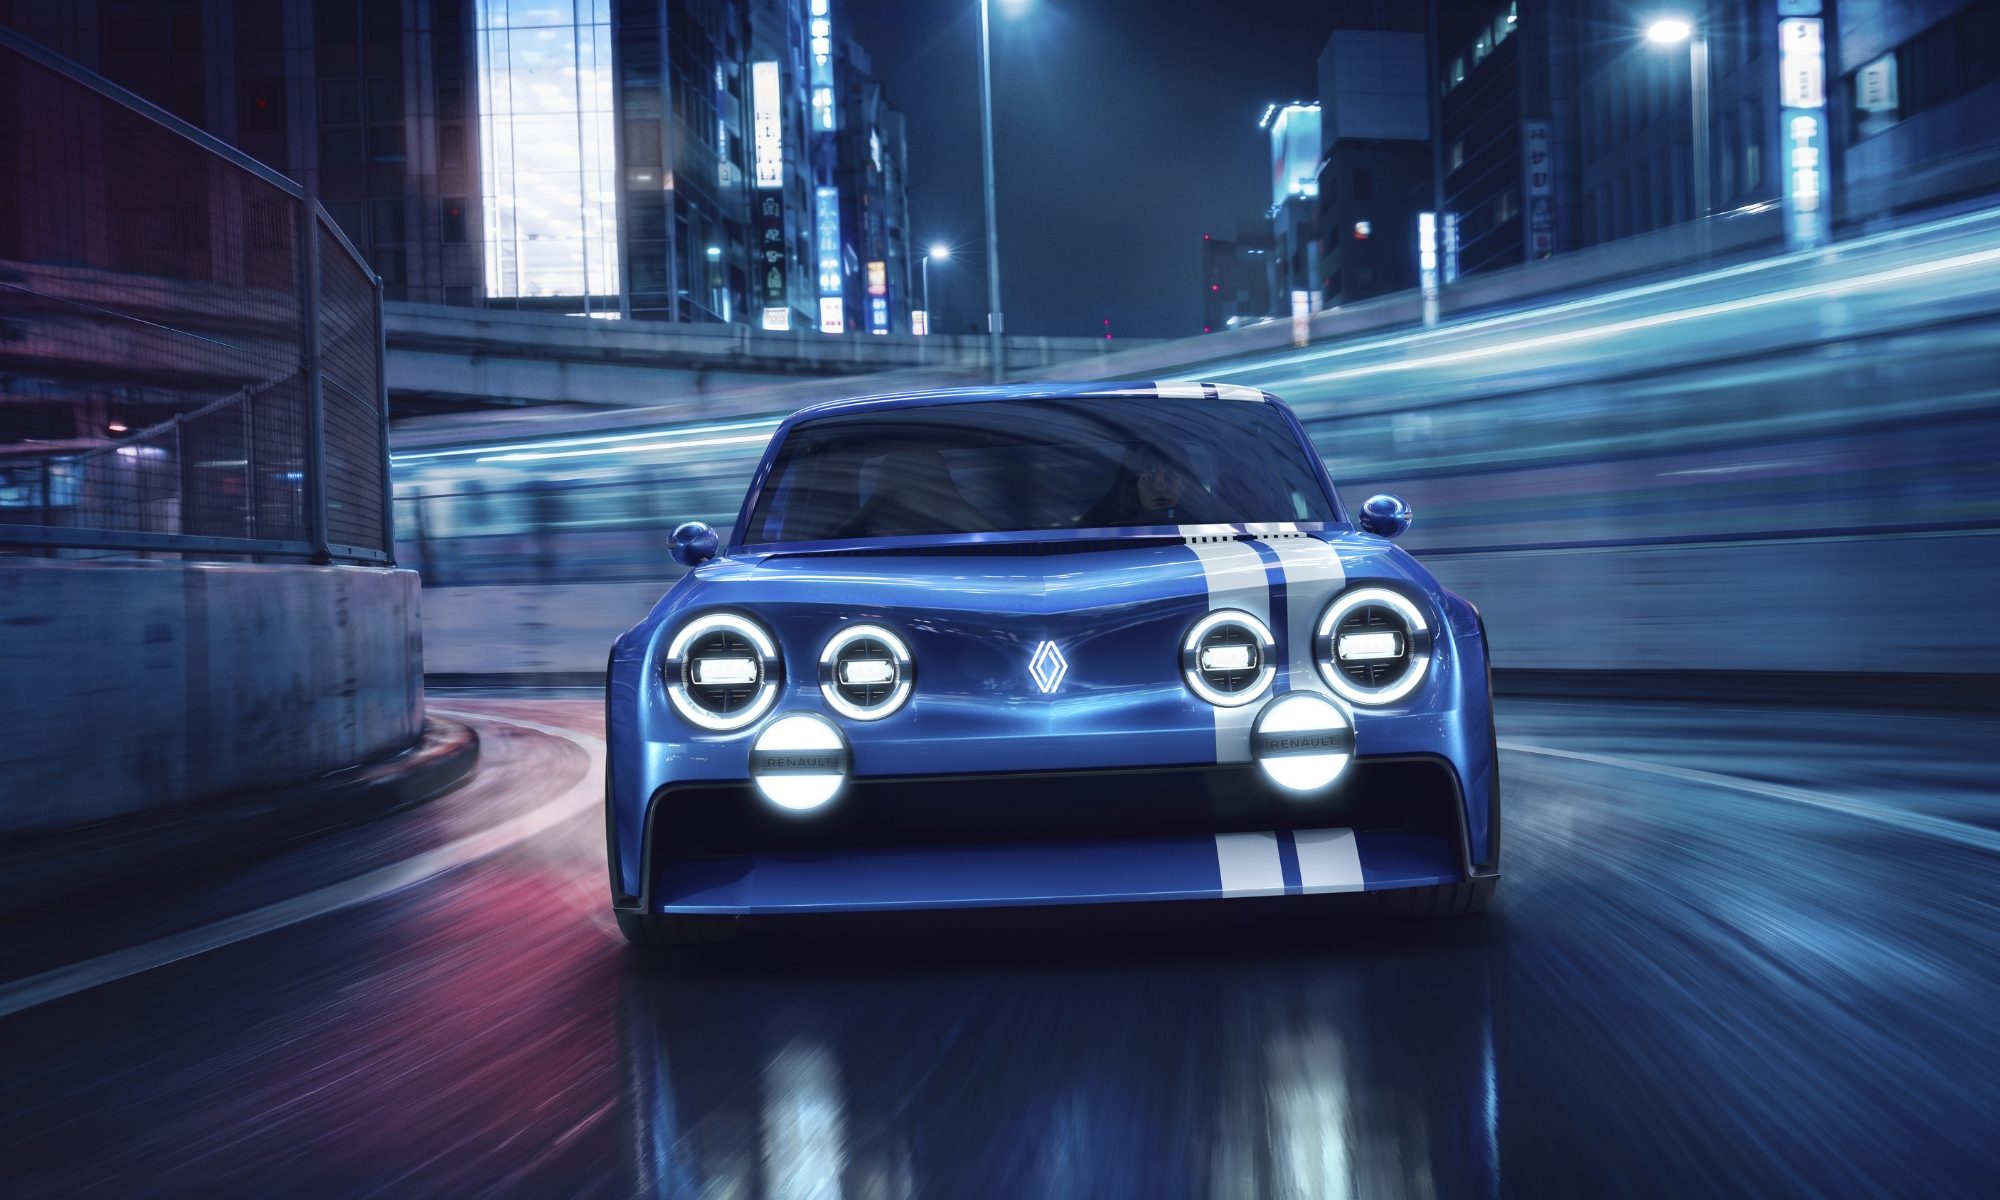
Renault has also carried several familiar details into the new design. The car gets six round headlights, squared-off wheel arches, a modernised Gordini badge and the iconic double white stripe. The stripe is no longer simply decorative, with Renault incorporating it into various structural and design elements of the car.
The design was created entirely in-house. More than 300 sketches were submitted during an internal Renault Design competition before two proposals were developed into scale models and combined into the final concept.
A two-seat EV focused on driving rather than practicality
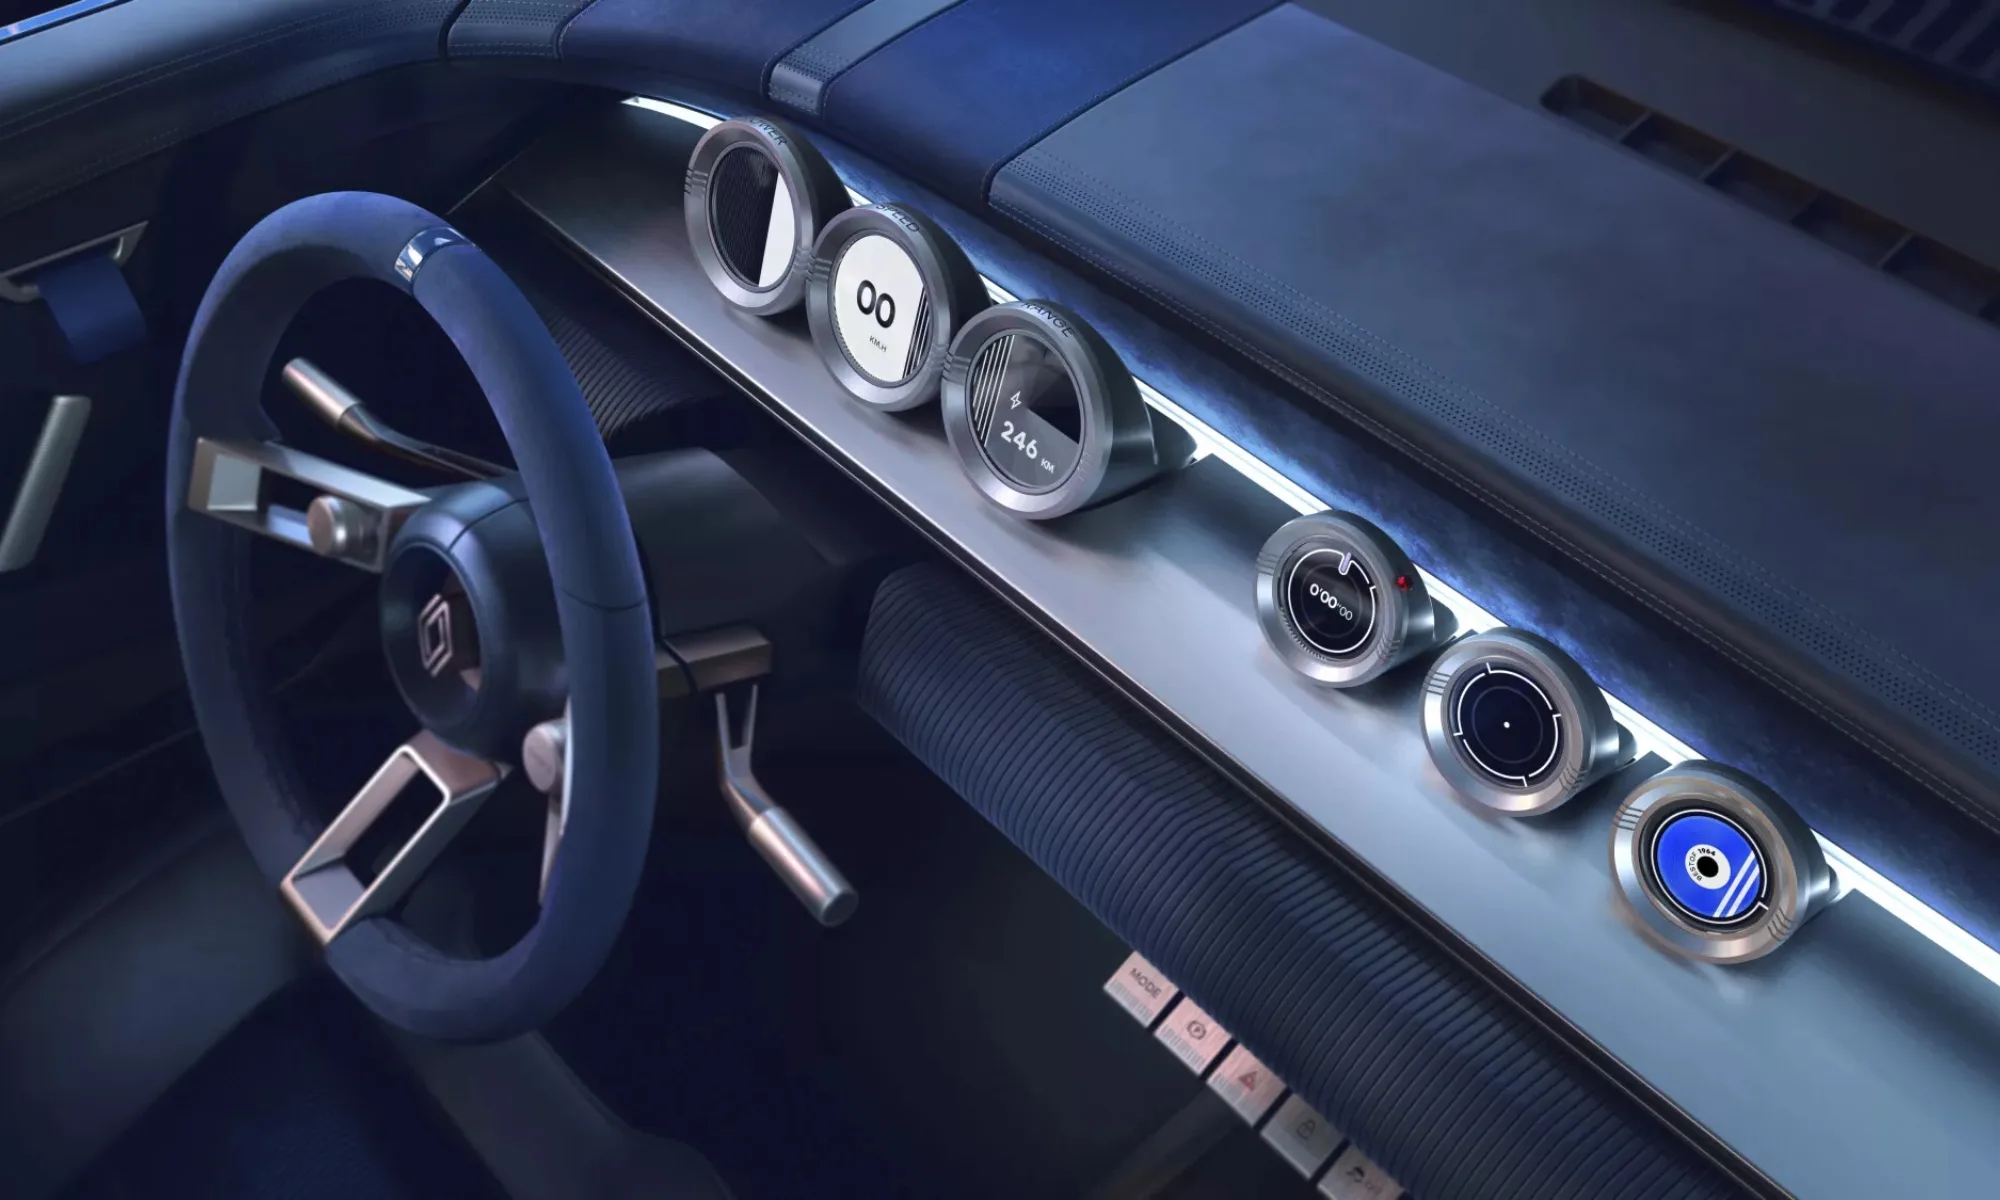
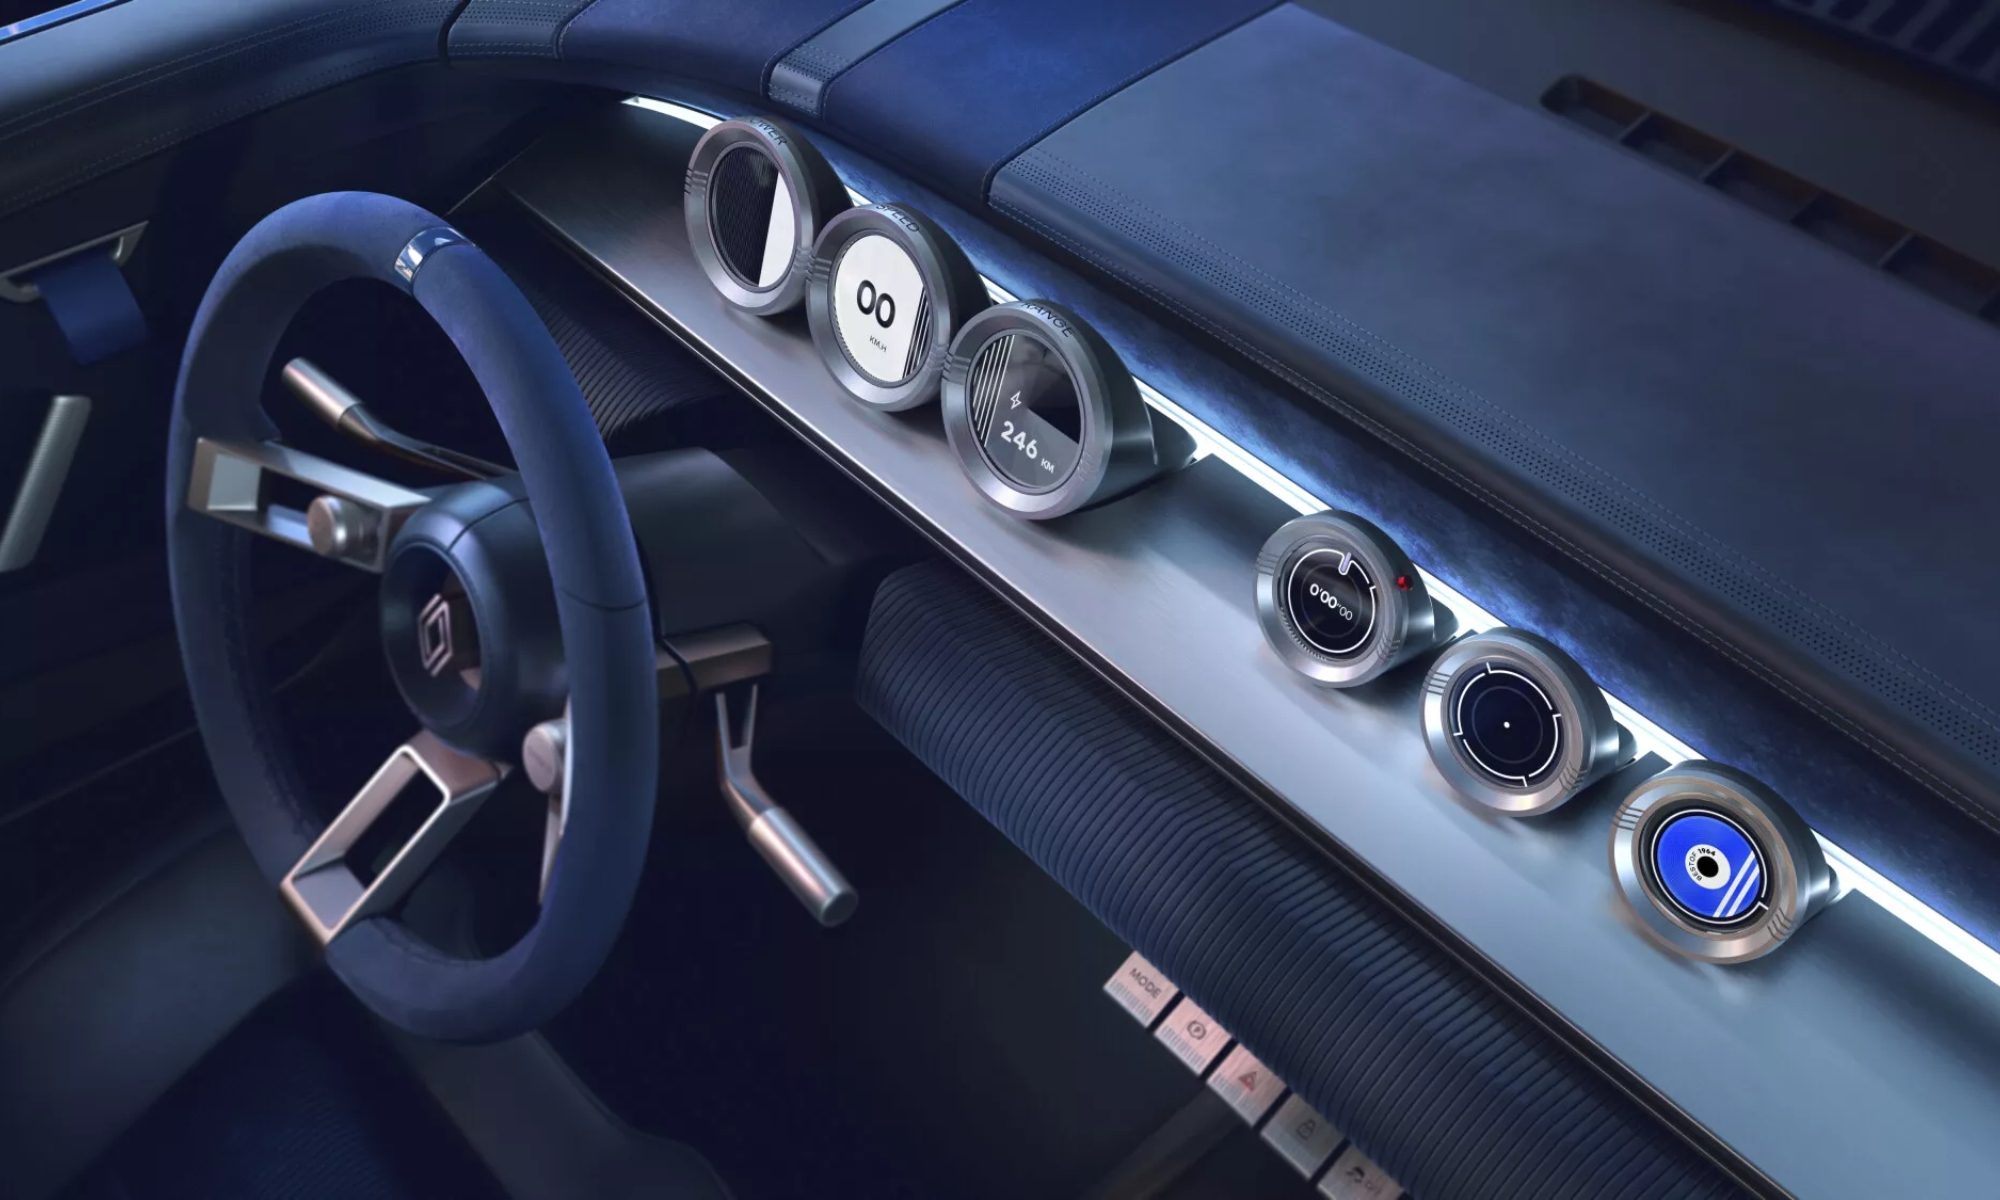
Inside, Renault has taken a similarly minimalist approach. The cabin features brushed aluminium across the dashboard and controls, contrasted with Alcantara upholstery. Digital round displays echo the circular headlights, while bucket seats and a prominent stopwatch button reinforce the car’s motorsport-inspired character.
Renault describes the concept as part of its effort to connect its heritage with future design rather than simply recreate old cars. The R8 Gordini follows previous projects including the R17 electric restomod x Ora Ïto and Renault 5 Diamant.
Advertisement
Renault 8 Gordini Concept
For now, this remains a concept car, and Renault’s media page does not confirm that it will enter production. The company does say the concept will become part of its historical collection, alongside other vehicles and archive material at the future Renault Collections museum in Flins, expected to open in around 15 months.
So while you probably won’t be ordering one from a Renault showroom anytime soon, the electric R8 Gordini shows how Renault is imagining its performance heritage in an EV era.
PCB circuits are cool, but you know what is cooler? Terminator circuits that’s what! And what if the same material that makes Terminator circuits could also be used for smart heat sinks, flexible circuits, and self-healing material properties? Well, that is exactly what the lab at Virginia Tech’s VT MADE Lab has created, presented by Joel from [3DPrintingNerd].
So what does a Terminator circuit actually entail? Well, just like in Terminator 2, the circuits are made of liquid metal. Specifically, small drops of liquid metal alloy made of gallium and indium. These drops are contained within a matrix of PDMS polymer, which contains the magical liquid for conductivity, thermal and electrical . This makes a flexible and stretchy composite which can even self-repair when punctured or cut by bridging the
Little “bubbles” of liquid alloy form a composite that will pop when applied over a threshold of force or puncture.
broken circuit with the liquid alloy. Having a polymer matrix allows this self-repairing property but also makes the material insulating by default, only allowing current to flow after selectively “popping” the matrix bubbles.
To create something with the composite material, you’ll find it similar to many other resin-based materials. You can pour, mold, and even 3d print a custom geometry. A short bake later and you get a solidified model made for whatever custom flexible circuitry you have in mind.
While this process requires chemicals, polymerization reactions, and a taste for liquid alloys, that shouldn’t stop you from trying out flexible electronics. For a more hands on method to flexible electronics check out this glove with circuits running throughout!
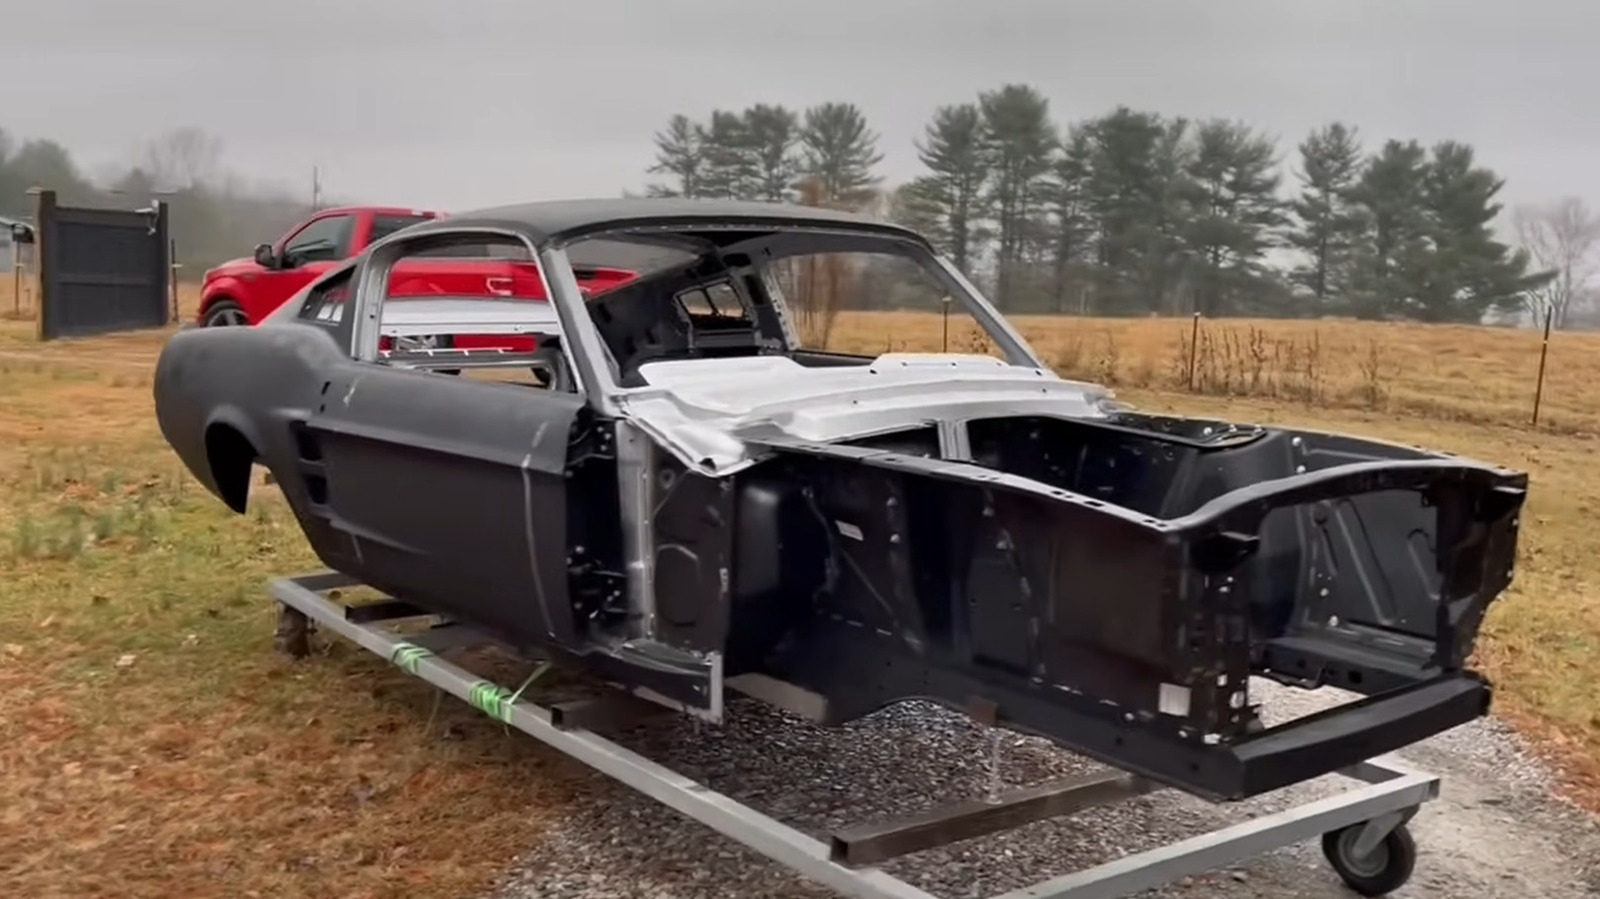
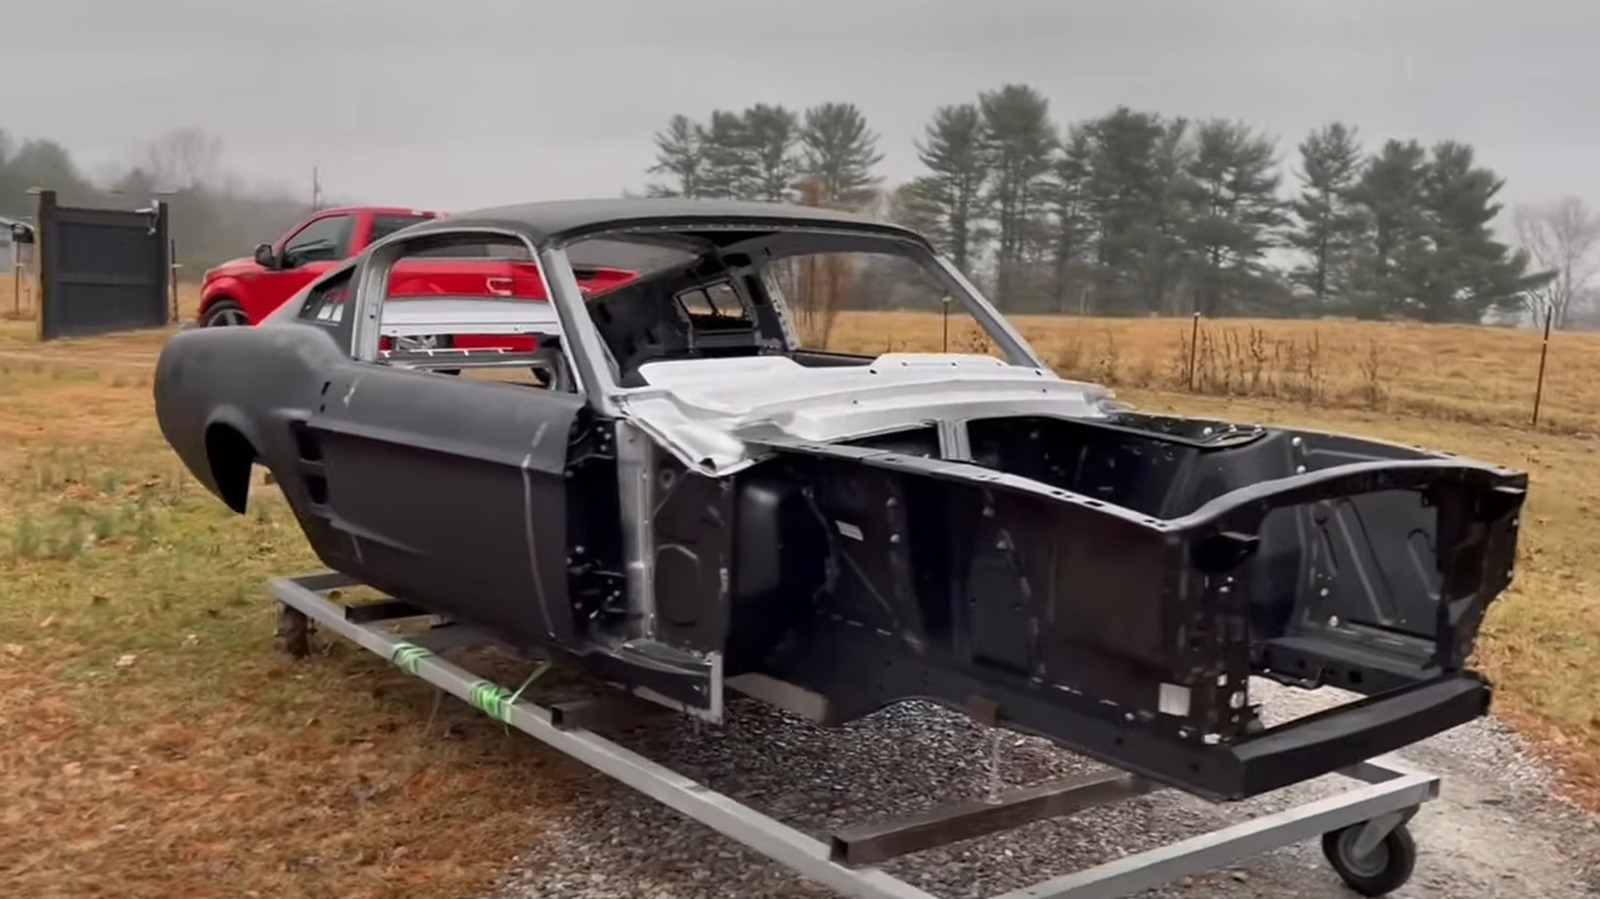
If you want the styling of a 1967 Ford Mustang without the complications of owning an older car, you could always build it yourself. That’s what YouTuber 1194video did, anyway. Using all new components and materials, he got all the measurements of an original 1967 Mustang and began a tough assembly process.
1194video started with the structure and floor by using stamped-in bevels as alignment guides. He then hole-punched and screwed the side panel before welding. Before committing to any welds, he made sure to carefully measure everything, making sure the quarter panel, roof line, and B-pillar all lined up. Getting the body squareness right was one of his biggest challenges, requiring him to strap and pull the body straight before welding.
Advertisement
When it came to the roof structure, 1194video installed front and rear roof braces, then set the roof skin on top to ensure it sat correctly against the body side rails. At this stage, he noticed a bend in the roof skin that had to be corrected. He then screwed and clamped the tail light panel, quarter panels, and other parts of the fastback rear structure into place, trimming off excess metal. This was followed by welding the inner and outer wheel tub sections, then installing the doors and trunk lid. Safe to say, it was not an easy process.
Advertisement
One of the most important and overlooked parts of building a new 1967 Mustang
One of the biggest focuses of building a brand-new 1967 Ford Mustang was rust protection. 1194video felt he had to be proactive, coating various welding points and panels with primer and high-heat paint before enclosing them. He noted that wheel tub welds and cowl panels are common rust points for this model. At one point he said: “It could settle up in between these two pieces of steel and then cause rust and rot out like all the others in the world do.”
Classic Mustangs are known for falling victim to rust – an unfortunately common problem with classic cars – and the wheel wells are a common spot to find hidden damage. This is because this component sits so close to the ground, especially if you drive on roads with snow, salt, and loose stones. Snow and rain can also splash upwards and get the Mustang’s lower body. If you see faded or chipped paint in that area, it could be prone to rusting.
After the initial body work video, 1194video posted a follow-up video tackling a step most home-built Mustangs never have to deal with: getting a legitimate title and VIN for a car assembled entirely from new reproduction panels. This entailed meticulous photography and receipt compilation, heading to the clerk’s office, and then having a state inspector verify the car was legal and contained no stolen parts. A week later, the title showed up in the mail. This specific Mustang isn’t ready for the road just yet, but one surprising obstacle is now out of the way. If you plan on building a custom vehicle yourself — or even swapping engines — you’ll need to check your state’s regulations.
Anthropic’s Claude Opus 5.5 appears to be changing how it writes, with new analysis showing fewer obvious AI writing patterns, shorter sentences, and simpler wording compared with Opus 5.
Claude Opus 5.5 is not only one of the best models for coding, but it also appears to be a bit better at writing, as Anthropic appears to be changing how AI writes.
According to Arena, an AI benchmarking tool, Opus 5.5 has fewer obvious AI writing patterns, so you’re less likely to create AI slop content with this model.
It also found that sentences are now shorter, which means you have fewer long sentences and simpler wording compared with Opus 5.
Advertisement
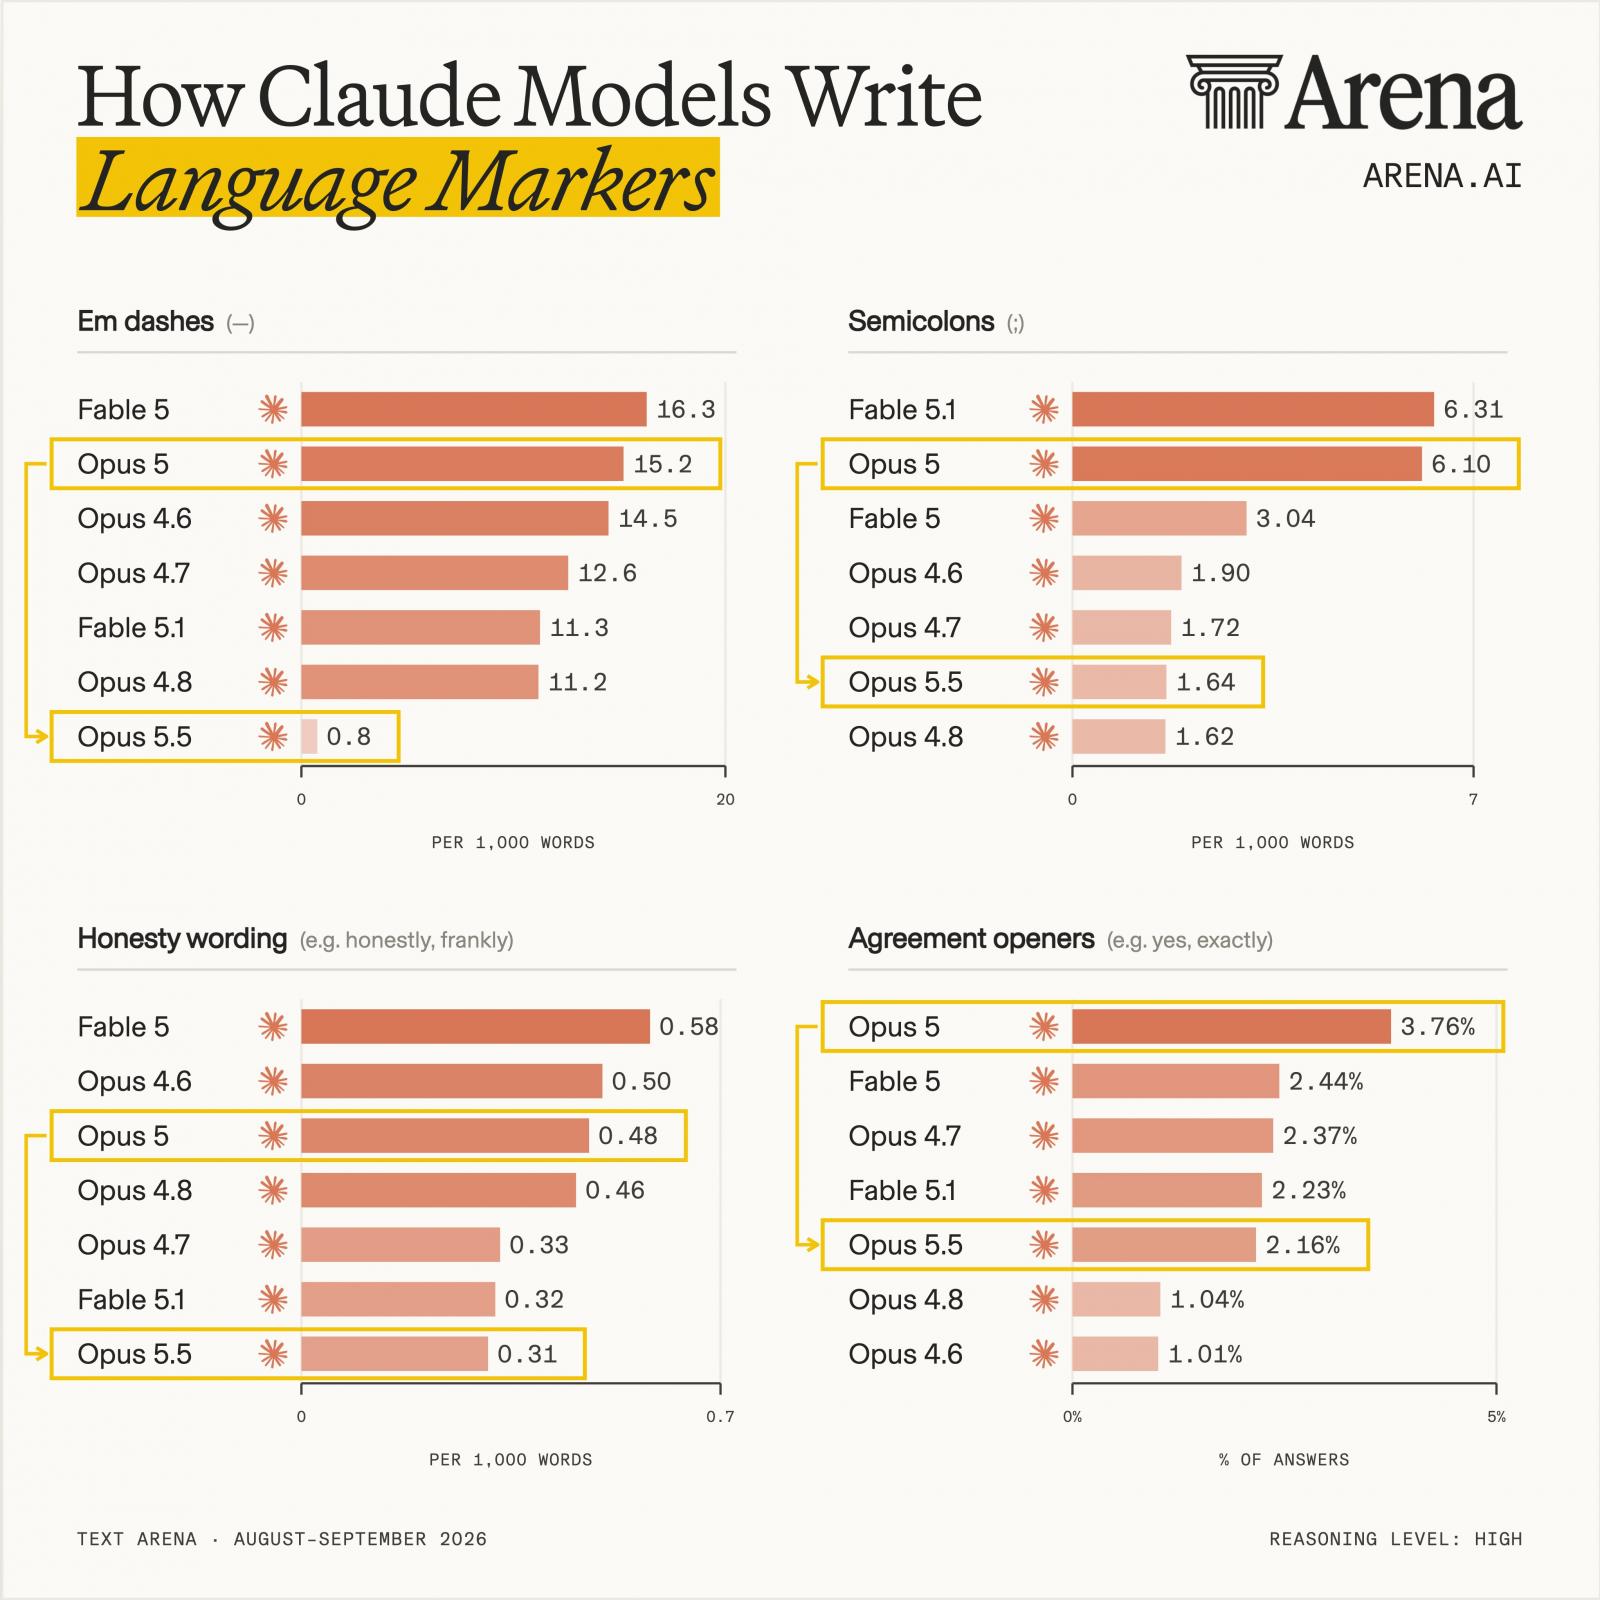
Arena analyzed high-reasoning Text Arena responses from August and September 2026 and observed that 10 of 12 writing measures moved in what it considers a better direction.
Interestingly, Arena’s data confirms that Opus has almost stopped using em dashes, which was one of the biggest signs of AI-generated content.
Claude writing pattern has changed
Source: Arena
Opus 5 used 15.2 em dashes per 1,000 words, while Opus 5.5 dropped that figure to just 0.8, a reduction of roughly 95%. It also found that semicolon usage fell sharply from 6.10 to 1.64 per 1,000 words.
The newer model writes shorter sentences, averaging 10.03 words compared with 12.14 for Opus 5. However, there is one obvious tradeoff, and that is that Opus 5.5 is more verbose.
In other words, average answers increased from 453 to 481 words, making it the longest-writing Opus model in the comparison.
Advertisement
More lately, AI models have focused mostly on the coding side of things, so it’s quite interesting to watch Anthropic change how Claude writes, and if anything, you’ll see fewer em dashes on the internet.
Join Mikko Hyppönen and security leaders from the NFL, CHANEL, and Atlassian for a two-hour digital summit on what AI-speed attacks change, what defenders should stop doing, and how to validate, decide, fix, and re-validate at machine speed.
Across the infrastructure layer that powers AI applications, Markdown has been emerging as a new standard. More providers are turning to it as the default output for anything a model needs to read, and moving beyond JavaScript Object Notation (JSON) as the go-to, one-size-fits-all format.
This real, ongoing shift reflects how large language models are trained, how chat interfaces render answers, and how developers actually build with tokens, context windows, and cost in mind. And there is good reason for this adoption.
Markdown fits how models work
Large language models have been trained on enormous amounts of Markdown. Think of documentation sites, README files, technical blogs, forum threads, knowledge bases and so on. That exposure means models already speak Markdown fluently; they know how to analyze its headers, lists, tables, and code fences, and treat them as semantic signals rather than noise.
At the same time, user-facing chat interfaces can already render answers from Markdown. When a model outputs Markdown, the front end can display it cleanly without extra transformation. When the same model ingests Markdown, it receives information in a form that mirrors its training distribution and the way it is expected to respond. The result is a more natural input-output loop than feeding models dense, nested JSON that must be mentally unpacked before use.
Advertisement
If you look at things from a token perspective, Markdown is also the leaner approach. It strips away structural overhead and keeps the informational payload. For AI agents that must fit large amounts of context into a limited window, that efficiency translates directly into more relevant content per request and lower cost per inference.
A visible trend
The move to Markdown isn’t speculative either. It’s already being encoded in best-practice guidance from major model providers. OpenAI’s prompt engineering documentation explicitly recommends structuring developer messages with Markdown headers, bullet lists, and tables where helpful. The guidance advises using ‘##’ for major sections, inline backticks for code, and clear hierarchical formatting to improve model compliance and readability.
Third-party prompting guides are echoing this same pattern. They use Markdown headings to create section breaks, lists for enumerations, and tables for comparisons. Several analyses note that Markdown is more token-efficient and more naturally understood by models trained on documentation, which makes it a preferred formatting tool for complex prompts, especially with newer GPT-5 series models.
Infrastructure providers agree
API and data providers have also been won over by Markdown. Where JSON once ruled as the universal interchange format, many are now offering Markdown variants optimized for LLM consumption. The rationale is exactly the same: they want to reduce token bloat, simplify parsing for agents, and align with how models are prompted and how answers are displayed.
Advertisement
SerpApi, a nine-year-old, search-data API company, recently launched Markdown output across all 100+ of its APIs at no extra cost. SerpApi serves developers, researchers, and Fortune 500 companies with structured insights from Google, Bing, YouTube, and other sources. The feature lets developers request search results in a token-light Markdown format instead of JSON, aimed specifically at AI agents and LLM-powered applications. No new endpoint is required, and the format is requested via a query parameter, route extension, or header on existing integrations.
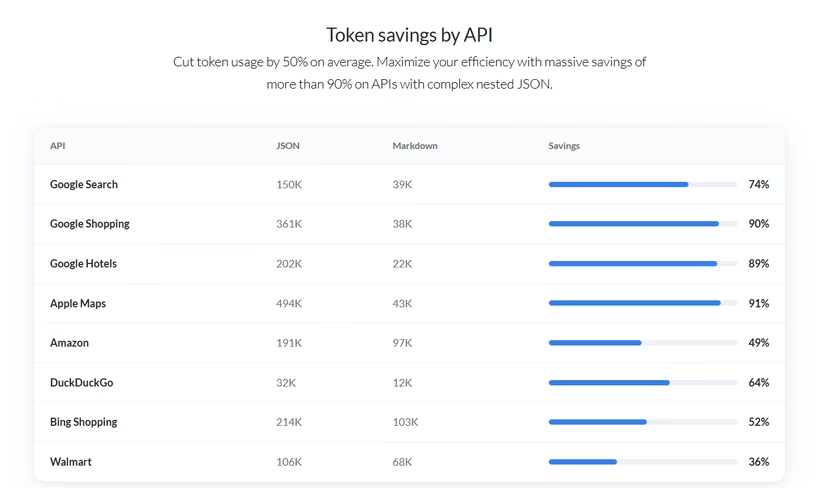
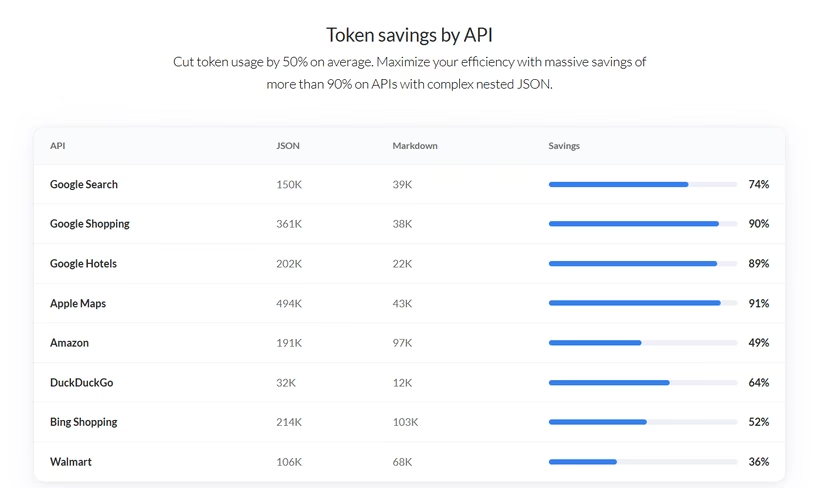
In a real-world example from SerpApi’s own benchmarks, a single Google search for “coffee” costs 24,723 tokens as JSON and 6,435 tokens as Markdown, adding up to a 74% reduction. When combined with field filtering, the same response dropped further to 1,298 tokens. Across its APIs, SerpApi reports average token savings of roughly 50%, with some endpoints seeing reductions of up to 90%.
Token savings across eight APIs, according to figures published by SerpApi. — Credit: SerpApi
These numbers matter because search results are among the noisiest, most nested payloads that agents ingest. JSON responses carry redirect links, favicons, tracking parameters, and deeply nested metadata that models do not need to reason over. Markdown output, in contrast, preserves the core information, such as titles, snippets, links, prices, and ratings in tables and lists while automatically stripping much of the internal tracking noise and duplicate fields.
Developers can access the new Markdown format by adding ‘output=md’ to the query string, calling the ‘/search.md’ route, or setting an ‘Accept: text/markdown’ header. The responses include YAML frontmatter for metadata, structured Markdown tables for result sets, and native inline links, all designed to be dropped directly into prompts or agent memory.
What this all means
As more of the web gets consumed by agents instead of humans, the infrastructure layer will increasingly optimize for machine readability over human-friendly nesting. JSON remains essential for programmatic manipulation and strict schema enforcement, but for the context ingestion phase of AI workflows, Markdown is emerging as the new default.
Advertisement
In the coming months, one should therefore expect more data providers to offer Markdown variants of their responses, especially for search, e-commerce, maps, and content APIs where token efficiency has an immediate impact on cost and performance. Prompt templates and agent frameworks are also likely to standardize on Markdown sections, tables, and lists as the canonical way to present retrieved context to models. Tooling should also evolve around measuring and minimizing token footprint, with Markdown as a primary lever.
For developers building with LLMs today, the writing is on the wall. When feeding external data into models, one should prefer formats that match how models are trained and how they output. Markdown is no longer just a documentation tool. It’s becoming the new lingua franca between search data and AI models.
















































You must be logged in to post a comment Login