This post is brought to you in paid partnership withMSI
Not every AI task needs the scale of the cloud. An employee searching company documents, a retail kiosk answering product questions, or a digital sign reacting to customer behavior all need fast responses, but they don’t necessarily need to send every prompt to a remote data center. Running those workloads locally reduces latency, keeps sensitive information closer to where it’s generated, and can lower the ongoing cost of AI deployments. As a result, many organizations are moving toward hybrid AI architectures that handle routine requests on-device while reserving cloud models for tasks that genuinely need more processing power.
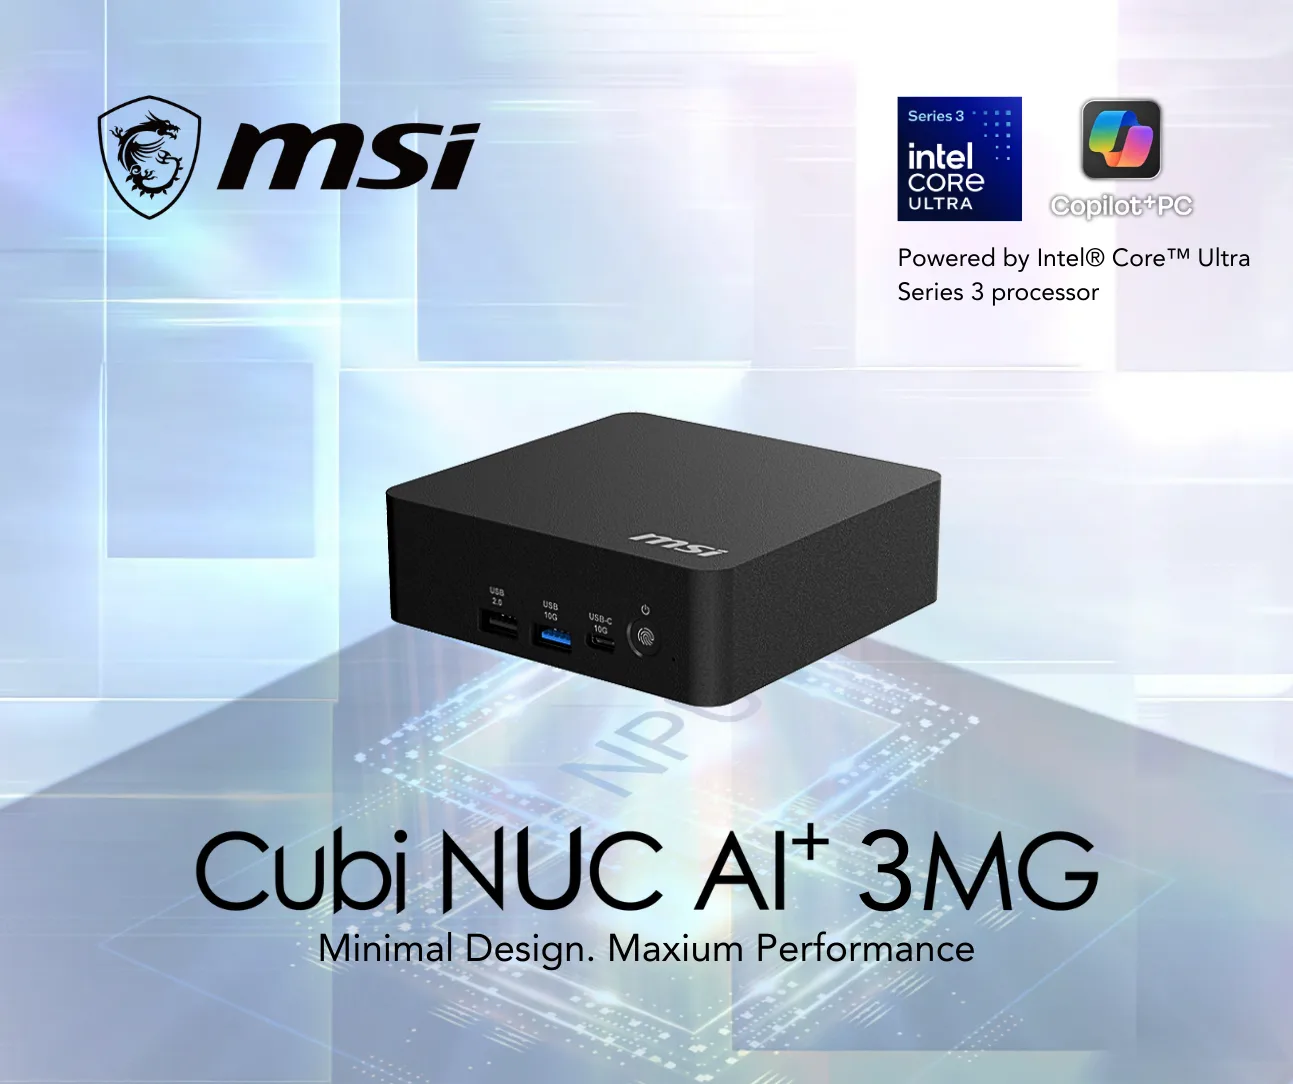
Hardware has evolved alongside that shift. Systems like the MSI Cubi NUC AI+ 3MG, powered by Intel’s Core Ultra Series 3 platform, combine a CPU, Xe3 GPU, and dedicated Neural Processing Unit (NPU) in an ultra-compact chassis. Instead of relying on one processor to do everything, each component handles the workloads it’s best suited for, making it possible to run quantized language models, retrieval pipelines, and AI workflows locally before reaching for cloud resources only when necessary. The platform delivers up to 100 TOPS (Tera Operations Per Second) of theoretical AI performance across the CPU, GPU, and NPU, although real-world performance depends on the model, workload, and configuration.
Building a local AI agent, in practice, means pairing that hardware with a software layer that can plan a response, retrieve the right information, and decide in real time whether a request stays on-device or gets escalated to something bigger. It isn’t about replacing the cloud altogether, rather it’s about deciding which workloads benefit from staying at the edge and which are better served by larger models. Getting that balance right starts with understanding how local AI differs from cloud AI, what role hybrid deployments play, and what kind of hardware is required to support them.
Advertisement
Why businesses are bringing AI agents to the edge
Cloud AI transformed how businesses adopted generative AI because it removed the need to invest in expensive infrastructure. Teams could access powerful language models through an API and start building applications almost immediately. Cloud models still make the most sense for complex reasoning, large-scale content generation, and workloads that demand the latest frontier models.
Many day-to-day AI interactions, however, don’t require that level of processing power. Searching internal documentation, summarizing meeting notes, helping customers navigate a store, answering policy questions, or monitoring connected devices are repetitive tasks that benefit more from low latency and predictable performance than from the largest possible model. Sending every request to the cloud also means paying for every interaction while moving information outside the local environment, even when the task could have been completed on-device.
Privacy is another factor driving the move toward edge AI. Organizations working with financial records, healthcare data, intellectual property, or confidential business documents often need tighter control over where information is processed. Running an AI agent locally allows sensitive requests to remain inside the organization’s network by default, reducing unnecessary data transfers and making it easier to meet internal governance and compliance requirements.
Hybrid AI has emerged as the middle ground. Routine requests can be answered locally, while more demanding queries are escalated only when additional reasoning or specialized knowledge is required. Instead of choosing between local AI and cloud AI, organizations can combine local and remote resources and let routing policies decide which environment is best suited for each request.
Advertisement
Local AI vs. cloud AI: Which deployment model makes sense?
Hybrid deployments are becoming increasingly common because they offer the best of both approaches. Local hardware handles predictable, high-frequency tasks with minimal delay, while more powerful models remain available for requests that exceed the capabilities of the local system. The result is faster responses without losing access to more capable models when a request genuinely needs one.
The hardware behind a local AI agent
Running an AI agent involves far more than generating text. Every interaction passes through multiple stages, including understanding the request, retrieving relevant information, deciding whether external tools should be called, generating a response, and maintaining context for future interactions. Those workloads place very different demands on the hardware.
Modern AI PCs distribute those tasks across three different processing components instead of relying entirely on the CPU. The CPU manages orchestration and system logic, the GPU accelerates parallel AI workloads such as inference and embeddings, while the NPU is optimized for sustained, power-efficient AI processing using quantized models. Working together, they allow multiple AI tasks to run simultaneously without overloading a single component.
The MSI Cubi NUC AI+ 3MG follows that design philosophy. Intel’s Core Ultra Series 3 architecture combines CPU, GPU, and NPU resources within the same platform, giving developers the flexibility to distribute AI workloads instead of forcing every task through a single processor. Expandable memory, NVMe storage, support for up to four 4K displays, and high-speed networking also make the system suitable for edge deployments where AI often runs continuously rather than in short bursts.
Advertisement
Choosing capable hardware is only one part of the equation, though. The software stack determines how requests flow through the system, how documents are retrieved, when tools are called, and whether a query should stay on the device or be handed to a larger model. Understanding that architecture is the foundation for building a local AI agent that is both responsive and scalable.
MSI
Start with the tasks the local system can handle
Building an agent starts with defining the work it’s expected to perform. A system such as the MSI Cubi NUC AI+ 3MG can be configured for smaller, repeatable tasks where a lightweight local model has enough capability to deliver the required result.
An employee could use the system to proofread a document before sending it out, prepare a response to a routine email, summarize information from a set of files, or work through a simple office process. These tasks don’t necessarily require the largest available AI model, making them suitable candidates for a local agent.
The distinction between a chatbot and an agent becomes important here. A chatbot primarily responds to what a user types. An agent can take an instruction and work through the steps needed to complete it. If the task involves retrieving information, using an approved tool, processing a file, or carrying out several actions in sequence, the agent can coordinate those steps rather than leaving the user to perform each one manually.
In this type of configuration, the Cubi can consequently serve as the first layer in the workflow, taking care of routine requests directly on the machine.
Advertisement
Adding the agent layer
The hardware provides the foundation, but the agent itself comes from the software stack. A local language model can generate text, but an agent needs additional capabilities to interpret instructions, manage steps, interact with tools and return a completed result.
Tools such as Hermes Agent can be used to build this kind of lightweight agentic setup on the Cubi. The exact configuration will depend on the tasks involved and the software environment, but the basic principle remains the same: the local model becomes one component within a system that can act on an instruction rather than simply answer it.
A typical workflow might begin with a request such as asking the agent to review a document. The agent can process the instruction, work with the relevant file, apply the required task and return the result. A similar setup can support routine email assistance or other structured office workflows, provided the necessary tools and permissions have been configured.
Keeping the initial workload focused is useful during deployment. Starting with a handful of predictable tasks makes it easier to evaluate response quality, resource requirements and the boundaries that should be placed around the agent.
Advertisement
Choosing the right local model
The language model is another important part of the setup. A compact AI PC is better suited to appropriately sized and optimized models than to treating every available model as an option.
Quantized models can reduce the resources required for local inference, making them a practical starting point for a mini PC. Models such as Mistral 7B, Llama 3 8B, or Phi can be evaluated according to the quality, speed and capabilities required by the particular workflow.
The model doesn’t have to perform every possible task. The objective is to find a model that’s capable enough for the jobs assigned to the local system while leaving sufficient resources for the agent framework and other applications running on it. Tools such as Ollama, LM Studio and Text Generation WebUI can also simplify the process of testing local models and configurations before settling on a deployment.
Give the agent access to the right tools
Agentic AI becomes more useful when it can work with the information and applications involved in an actual workflow. A local assistant intended for office tasks, for example, may need access to documents or other approved resources rather than relying entirely on information contained within the language model.
Advertisement
Retrieval-Augmented Generation (RAG) can be used to connect the agent with an organization’s own information. Instead of relying solely on what the language model learned during training, the agent can search internal documents, retrieve relevant information, and use it to generate a grounded response. This can help keep answers aligned with current policies, product documentation, or internal knowledge bases.
The same principle applies to permissions. An agent should have access only to the files, applications and actions it needs. Businesses can define which workflows are automated and what information the agent is allowed to use, creating a more controlled environment for everyday AI assistance.
Making the mini PC the edge agent
The next step is to give the mini PC a defined position within a larger AI architecture. Rather than expecting it to handle every possible workload, it can operate as the edge agent.
Routine requests remain with the local system. A proofreading task, a straightforward email response, a document-based question or another lightweight workflow can be processed by the local agent. More demanding requests can follow a different path when the local configuration isn’t sufficient.
Advertisement
The agent can be configured to consider factors such as workload complexity and the resources required before deciding where a request should be processed. If the Cubi isn’t equipped to handle a particular task, for example, it can route the request to a larger local system, allowing the workload to be completed without sending the organization’s information outside its own environment.
Connect the edge agent to a more powerful local AI system
A local AI deployment doesn’t necessarily have to choose between a mini PC and the cloud. A more powerful on-premises AI system can provide another layer for workloads that exceed what the edge system is configured to handle.
MSI’s wider AI PC portfolio provides examples of how that type of setup can work. The MSI EdgeXpert, powered by the NVIDIA GB10 Grace Blackwell platform (DGX Spark), can serve as a more powerful local inference system alongside the Cubi. The MSI PRO MAX EDGE AI+, powered by AMD Ryzen AI Max+ (Strix Halo), provides another example of the kind of higher-performance local system that can complement an edge mini PC.
Together, these systems can form a two-level architecture. The Cubi NUC AI+ 3MG acts as the edge agent, handling smaller and more frequent tasks, while EdgeXpert or PRO MAX EDGE AI+ can take on workloads that require substantially more processing power. This allows the organization to scale its local AI capabilities without making the cloud the automatic destination for every request.
Advertisement
For example, an employee could send a routine proofreading request to the Cubi and have it completed locally. A more demanding request involving a larger model or heavier inference could be routed onward to EdgeXpert or PRO MAX EDGE AI+. The user still interacts with the same overall AI workflow; the infrastructure underneath simply assigns the task to the system better suited to handle it.
The case for keeping AI processing local
The strongest argument for this architecture is control over information.
Reducing latency and cutting ongoing token and API costs are important reasons to process more AI workloads locally. For many organizations, though, privacy can matter even more. A cloud or hybrid architecture may offer greater convenience and access to larger models, but some environments require tighter control over where sensitive information is processed and whether it ever leaves the organization’s network.
That can include government agencies working with restricted information, schools responsible for protecting student data, law firms handling confidential case materials, and healthcare organizations managing sensitive patient information. In these environments, keeping appropriate AI workloads local can reduce unnecessary data transfers and give organizations greater control over how information is handled.
Advertisement
A routine task involving confidential material can therefore be handled by an edge system without automatically sending the underlying information to an external AI provider. If the task requires more processing power, the request can instead be directed to an approved local AI system, allowing the organization to preserve a local-first architecture even as workloads become more demanding.
The arrangement also changes how organizations think about AI costs. A business that sends thousands of small requests to an external API is effectively paying for every interaction. Moving appropriate routine workloads to local hardware can reduce the number of external token and API requests, while larger local systems can provide additional capacity for workloads that outgrow the mini PC.
Cloud AI can still have a role when a task genuinely requires capabilities that aren’t available locally. The advantage of the architecture is that the cloud becomes one option in the workflow rather than the unavoidable destination for every request.
What is the best way to scale a local AI agent?
A practical deployment can begin with the edge system alone. Install the local AI environment, select a suitable model, add the agent layer, and configure a small number of clearly defined workflows. Once those tasks are working reliably, the organization can identify which requests require more processing power.
Advertisement
A second, more powerful local AI system can then be introduced as the higher-performance layer. Routing rules can determine which tasks remain on the edge system and which are passed to the larger system. The organization can refine those rules as workloads become more varied.
A staged approach avoids turning a simple AI deployment into an infrastructure project from day one. The edge system remains useful as the everyday local layer even after additional processing resources are introduced.
Local, cloud, or both?
Building a local AI agent isn’t about abandoning the cloud. It’s about using local hardware where it offers the greatest advantage and treating cloud AI as an extension rather than the default destination for every request.
Modern mini PCs have reached the point where they can support that approach. Systems such as the MSI Cubi NUC AI+ 3MG combine CPU, GPU, and NPU resources in a compact form factor that can run language models and agentic workflows locally. Software such as Hermes Agent can provide the agent layer, while more powerful local systems can take over when a workload demands additional processing power.
Advertisement
For organizations exploring agentic AI, this creates a practical path toward a hybrid architecture. Routine tasks can stay close to where they’re generated, sensitive information doesn’t have to be sent to an external service by default, and cloud or higher-performance local resources remain available when they’re genuinely needed.
Frequently Asked Questions
Can a mini PC run a local AI agent?
Yes. Modern AI-focused mini PCs can run quantized language models, Retrieval-Augmented Generation (RAG), tool calling, and workflow orchestration locally. A system such as the MSI Cubi NUC AI+ 3MG can also be configured with an agent layer such as Hermes Agent to handle routine AI workflows directly on the PC.
What tasks can a local AI agent handle?
Suitable tasks include proofreading, routine email assistance, document processing, summarization, searching company information, and other basic office workflows that don’t require a large frontier model.
What is the advantage of hybrid AI?
Hybrid AI combines the speed and privacy of local inference with the flexibility of additional processing resources. Routine requests can stay on-device, while more demanding tasks can be routed to a larger local system or cloud model when needed.
Advertisement
Why is an NPU important for AI workloads?
An NPU is designed to perform sustained AI inference efficiently while consuming less power than relying on the CPU or GPU alone. It’s particularly well suited to running quantized AI models over extended periods.
Can local AI agents access company documents?
Yes. By adding a Retrieval-Augmented Generation (RAG) layer, AI agents can search internal documents stored in vector databases and use that information to generate grounded responses.
What happens when a workload outgrows a mini PC?
Hybrid routing can send it to the cloud or to a more powerful on-premises system. In a local-first architecture, a system such as the MSI Cubi NUC AI+ 3MG can handle routine requests at the edge while more demanding workloads are routed to systems such as MSI’s EdgeXpert or PRO MAX EDGE AI+.
Does local agentic AI eliminate the need for cloud AI?
No. Cloud AI can still be useful for workloads that require capabilities or processing power beyond the local environment. The advantage of a local-first setup is that routine requests don’t have to be sent to the cloud by default.
Advertisement
How does local AI reduce API or token costs?
Routine requests processed locally don’t need to generate an external API request. For organizations handling large volumes of smaller AI tasks, reducing those cloud interactions can lower usage-based token and API costs.
This content is paid for by the brands indicated. Digital Trends works closely with advertisers to highlight their products and services to our readers. Although this article is informational and not opinionated, it reflects thorough fact-checking by our team to ensure accuracy. Our dedicated partnerships team, not external advertisers, crafts all branded content in-house. For more information on our approach to branded content, click here.
Automate your Mac with ease using Shortcuts and Apple Intelligence.
Filipe Espósito for Engadget
Shortcuts has been available on Mac since macOS Monterey, but it’s one of those utilities many Mac users have never explored. At first, it can seem too complicated. You have to know which actions to choose and how to connect them, then hope it all works.
But macOS 27 Golden Gate changes that with Describe a Shortcut, which lets you type exactly what you need and have Shortcuts do the heavy work for you with AI. It doesn’t always work, but it makes the app much easier to use — especially if you’re not an expert.
If you’re not familiar with Shortcuts, it’s an automation tool where you create scripts to handle tasks on your devices. Apple’s own example is a shortcut that texts your spouse with an estimated arrival time based on traffic when you’re leaving work. But you can get much more complex, like a shortcut that checks your calendar and the weather to give you a summary of what to expect today.
Advertisement
There are many possibilities, and now with macOS 27, it’s much easier to master the app.
Creating shortcuts on your Mac is easy
Filipe Espósito for Engadget
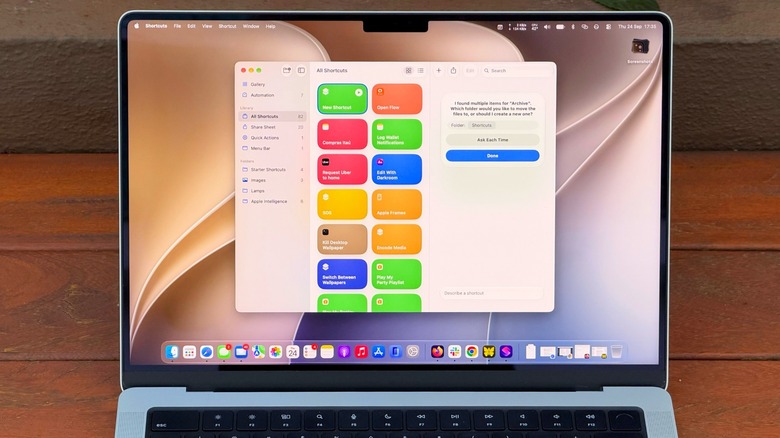
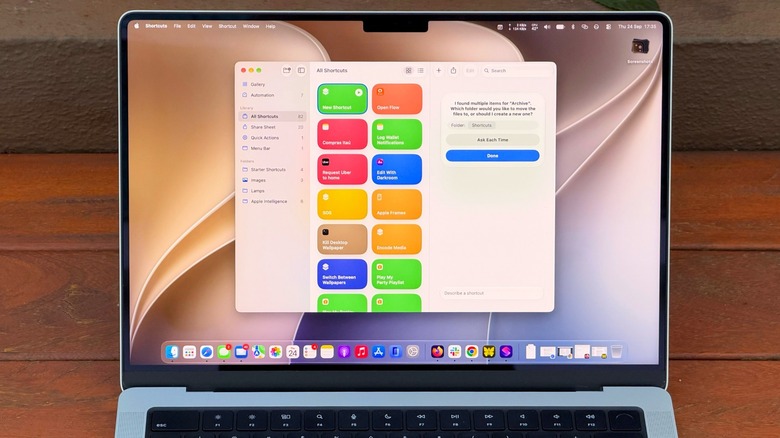
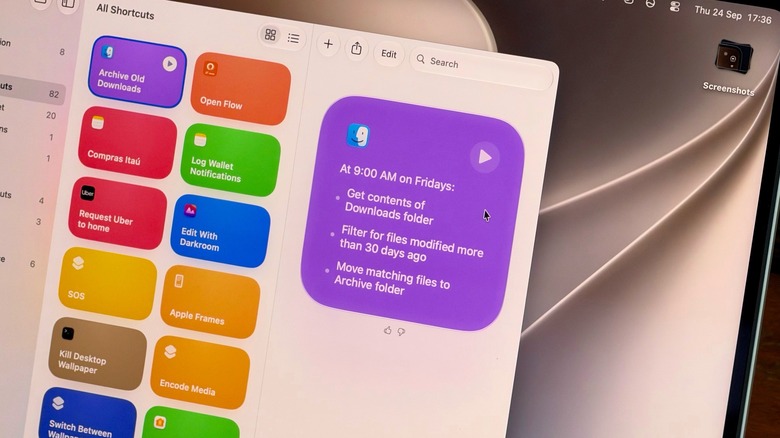
Creating a new shortcut takes a few seconds. Open the Shortcuts app on your Mac and click the Plus button to enter a prompt. The more details you provide, the more likely the app is to get your shortcut right. A command like “Clean up my Downloads” might be too vague for the app to understand what you really want. Instead, try something like “Every Friday, move anything in my Downloads folder older than 30 days into a folder called Archive.” You’re more likely to end up with a working shortcut when you provide clear details.
This is a good example of how Shortcuts are helpful for tasks you often forget to do; no one really cleans out their Downloads folder unless they’re trying to free up space. Plus, you can check the result right away by opening the folder and looking at what moved. If the shortcut moved too much, re-enter the prompt with even more specific details.
Advertisement
A shortcut can also be great for summarizing long text with Apple Intelligence. Try something like “Take the text on my clipboard, summarize it in three sentences and save it to a new note.” Then copy a long article or an email, run the shortcut and you’ll have the short version in Notes.
Make your shortcuts easier to reach
Filipe Espósito for Engadget
If a shortcut isn’t part of your normal routine, chances are you’ll forget about it after a while. Thankfully, you can assign a keyboard combo to a shortcut, or pin it to the menu bar, so you’ll never forget it.
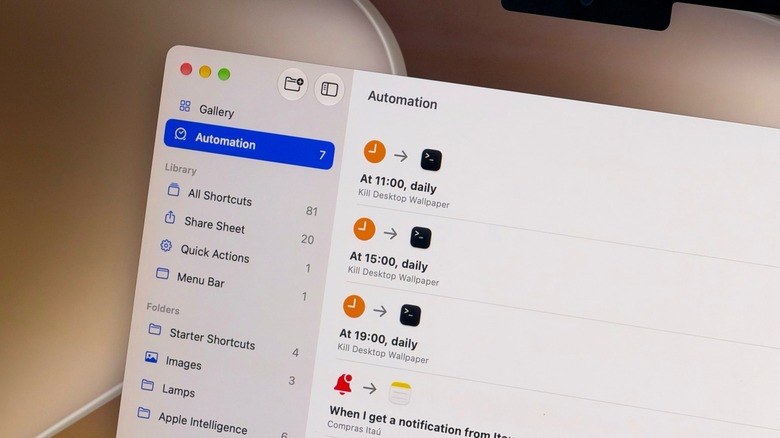
Choose the shortcut you want to adjust and click Edit. Go to the Shortcut Details menu (the one with the information icon) and select Add Keyboard Shortcut. To add it to the Control Center or menu bar, open Control Center on your Mac (at the top-right) and select Edit Controls. There, all you have to do is add the action from the Shortcuts app, and you’re all set. Exploring the Automation tab is also a good idea for creating a seamless workflow of shortcuts that run on their own when you need them.
Advertisement
Shortcuts isn’t the only element in macOS 27 that acts on your behalf. Visual Intelligence has its own key combo: Shift + Command + Space. After pressing this, select a window on-screen and have Siri answer questions about it or take action, like adding an event to your calendar. Try it on an email with a date buried in it, for example. Siri can also run your shortcuts via voice, speaking of which.
Shortcuts and Siri AI require Apple Intelligence, which means you need a Mac with an M1 chip or later — Intel Mac users are out of luck. Also, some limits may apply when using Apple’s AI models in Shortcuts. More complex prompts could reach a limit faster.
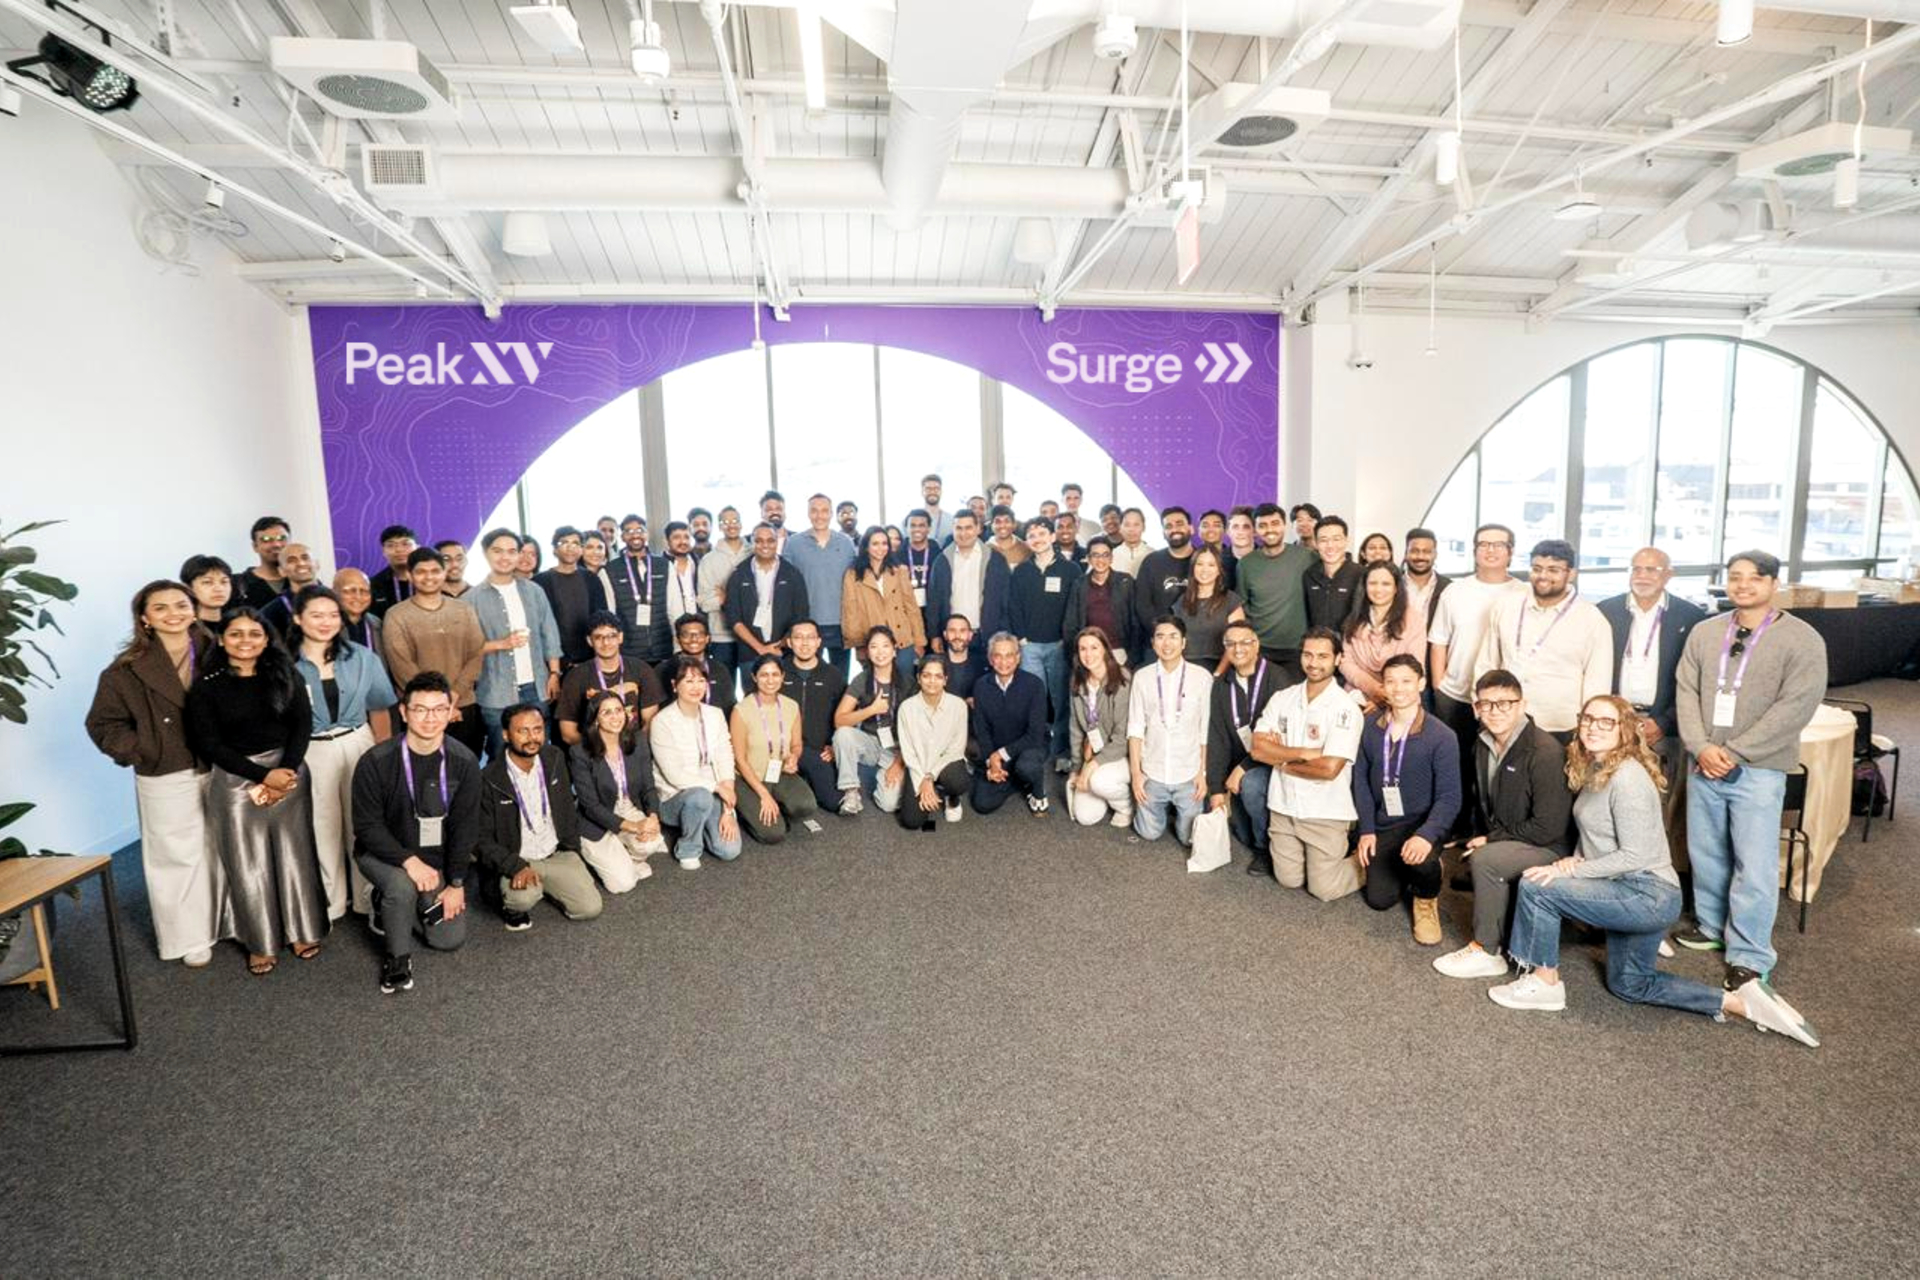
Peak XV Partners, one of the largest venture capital firms investing in markets including India and Southeast Asia with more than $10 billion in assets under management, has increased how much it invests per startup through Surge, its seed-stage investing platform, as it unveils a new cohort of 18 companies.
At least three of the companies in this cohort had already raised outside funding, in some cases from Peak XV itself, before joining Surge.
The new batch, called Surge 12, is the first to operate under Peak XV’s higher investment ceiling of up to $5 million per company, up from $3 million previously. The venture firm invested more than $50 million across the cohort, which has collectively raised over $90 million in seed funding, according to Peak XV. Its median investment per company has also increased, though the firm declined to disclose the figure.
“The bar to raise a Series A has gone up pretty significantly,” Rajan Anandan (pictured above), managing director at Peak XV, said in an interview. He added that the firm is also seeing more capital-intensive companies, particularly in deeptech, that are raising larger rounds at the seed stage.
Advertisement
Surge has become more global with each cohort, Anandan told TechCrunch, with its latest group spanning founders and companies from San Francisco to Sydney. Just five of the 18 startups in Surge 12 are focused on the Indian market, while more than half of the companies are based in India. The remaining 13 target global markets, highlighting the difference between where the companies are built and where they expect to find customers.
Since its launch in 2019, when Peak XV operated as Sequoia Capital India and Southeast Asia, Surge has backed more than 180 startups founded by entrepreneurs representing more than 18 nationalities. Peak XV says the 10 largest companies to emerge from those cohorts now generate more than $1 billion in combined annual revenue.
Surge founders at the Peak XV U.S. Immersion 2026Image Credits:Peak XV Partners
Anandan described Surge as one way Peak XV invests at the seed stage, alongside its standard seed investing, while the firm still remains an investor as companies progress through later funding rounds. The founders it backs typically include repeat entrepreneurs, experienced operators, and highly specialized technical founders, he said, with about 50% to 60% of a typical cohort made up of people coming from operating roles at established technology companies.
This cohort’s startups span AI, robotics, space, consumer products, healthcare, music, and fintech, ranging from AI safety and personal computing to autonomous robots built for underground pipes and satellites designed to detect radio-frequency signals from orbit.
The Surge 12 cohort
Alma — founded by Nischith Shadagopan M N and Vinod Ganesan — is building a personal computing platform focused on making computer use faster and more affordable. Its founders previously worked at Microsoft Research and were founding engineers at Sarvam AI, a Bengaluru-based startup building AI models for Indian languages.
Advertisement
August AI — founded by Anuruddh Mishra, an IIT-BHU alumnus who started the company in 2022 after a personal medical misdiagnosis — provides a healthcare platform that combines AI with physician-led care, reaching over 9 million users across 160 countries.
Ditto — founded by UC Berkeley dropouts Allen Wang and Eric Liu — works as an AI dating matchmaker inside iMessage, aimed at helping college students turn digital introductions into in-person connections. (TechCrunch wrote more about this one last month.) The company had already raised $9.2 million in a Peak XV-led seed round announced earlier this year.
GameStock — founded by Antoine Mistico, Easton Dana, and Vivek Indlebele Narasimha Prasad — brings competition mechanics to financial markets, turning investing and trading into a more competitive experience. Mistico is a two-time founder and former professional baseball player.
HiLoop — founded by Jad Ghalayini, Karan Brar, and Thomas Boser — helps AI companies adapt general-purpose open-weight models for specific applications using its post-training platform. Its founding team includes former Reducto engineers and a Cambridge computer science PhD who completed his doctorate at 24.
Advertisement
Hoola Health — founded by Deeksha Senguttuva — focuses on care for children and their families, providing consultations, vaccinations, medicines, diagnostics, developmental therapy, and dental services on a single platform. Senguttuvan grew up around healthcare, as her family built and operated a hospital group.
Kello — founded by Mona Gandhi and Subramanya Jingade — is building an AI-powered talent-discovery platform focused on identifying a candidate’s potential and trajectory rather than relying primarily on conventional credentials. Gandhi says she was Airbnb’s first female engineer and she previously founded Upraised, while Jingade previously co-founded AmbitionBox.
Kindling — founded by Adam Miller and Sachin Shah — is building what it calls a “storytelling operating system” for technology startups, using AI to help companies develop and produce their communications and content.
Puralink — founded by Harrison Crowe-Maxwell, Shyeon Delnawaz, and Thien “Long” Tran — is developing autonomous robots that can navigate underground pipe networks. Crowe-Maxwell has been building robots since childhood and turned university research into the patented drive technology behind the startup.
Advertisement
Reinforce Labs — founded by Anish Das Sarma — is developing tools to evaluate, red-team, and remediate enterprise AI systems. Sarma previously founded a company acquired by Airbnb and later served as a director at Google, where he led AI and machine-learning teams.
Riffle — founded by Anurag Choudhary and deo — is building a browser-based platform where musicians can create, collaborate on, and share music, reducing the need to move between separate tools during the creative process.
Rosella — founded by Chris Dwyer and Sean Stuart — is building an AI-native commercial insurance brokerage for U.S. businesses, using AI to automate parts of the traditionally manual process of finding and placing business insurance. Rosella raised a roughly $2.5 million pre-seed round led by Peak XV and Intact Private Capital earlier this year.
Tribe Money — founded by Himanshu Arora and Nikhil Shanker — gives an AI-powered personal finance platform that helps users track their money, research investments and make investing decisions.
Advertisement
ULOOK — founded by Adheesh Boratkar and Siddhesh Ravindra Naik — is building autonomous satellite systems for radio-frequency sensing and spectrum intelligence, targeting customers globally. Its founders have worked on more than 12 satellite missions. The company had already raised roughly $2.3 million in seed funding from growX Ventures and InfoEdge Ventures before joining Surge.
Wingit — founded by Nikunj Kothari and Saksham Khandelwal — is building a beauty platform aimed at India’s growing premium-consumer market. It is focused on how consumers discover and shop for higher-end beauty products.
Three other startups in the cohort have yet to publicly reveal their names or products. Peak XV said they are working in education, applied AI, and medical products.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
The Metric Is Not the Mission is a ten-part examination of how Big Tech moved from building and expanding the open internet to increasingly shaping it around its own metrics, incentives and assumptions. Across the series, the argument follows the evolution of the platform economy—from the optimism of the early internet to the growing tensions around power, prediction, geopolitics, accountability and the future of digital life.
The series will be published in two parts each week over five weeks, with each installment building on the one before it. At the end of the series, the complete essay will be brought together in a single PDF edition, providing the full argument in one place.
Part III: When the Maps Became the Territory
In Part II, the story turned on a crucial distinction: measuring behavior is not the same as understanding people. Part III takes that idea further, examining what happens when the platforms’ representations of the world begin to substitute for the world itself.
There is a curious tendency among successful technologies to disappear. Not physically, of course, but cognitively. Once they become sufficiently embedded in everyday life, they cease to be experienced as technologies at all. Electricity is no longer a marvel of engineering but an expectation. We do not admire the plumbing each time we turn on a tap, nor do we reflect on the extraordinary complexity of global logistics every time fresh fruit appears on supermarket shelves in the middle of winter. The greatest infrastructures become invisible because they succeed so completely that we mistake them for part of the natural order.
Advertisement
The internet reached that point sometime during the second decade of the twenty-first century. Yet something else happened along the way that proved far more consequential. As the network itself faded into the background, the platforms through which most people experienced it moved decisively into the foreground. Increasingly, users no longer spoke about “going online.” They spoke about opening an app.
That linguistic shift deserves more attention than it usually receives. Language often reveals structural change before statistics do. To “browse the web” implied movement across an open landscape whose boundaries were undefined. One followed links, discovered obscure websites, stumbled upon ideas that had not been recommended by anyone, and occasionally became gloriously lost. The experience resembled wandering through an unfamiliar city with no particular destination in mind. Serendipity was not a flaw in the architecture; it was one of its defining virtues.
Applications altered that relationship almost without anyone noticing. They replaced geography with destination. Instead of entering a network whose possibilities remained unknown, we entered environments that had already been organized on our behalf. The internet did not disappear, but it became increasingly hidden beneath layers of interface, recommendation and curation. Like passengers traveling through an airport without ever seeing the city beyond the terminal, we continued moving through digital space while encountering only the carefully managed environments that had been prepared for us.
This transformation is often described as an inevitable consequence of convenience. While accurate in its own right, this explanation offers an incomplete narrative. Convenience was certainly the language through which the platforms justified many of their design choices. Friction was treated as the great enemy of the digital age. Every additional click became an obstacle to be eliminated. Every decision that users might otherwise make for themselves could instead be anticipated by software. Recommendation replaced search. Autoplay replaced choice. Infinite scrolling replaced endings. The future, we were told, belonged to experiences so seamless that they would feel almost effortless. And they did.
Advertisement
It is difficult to criticize convenience because convenience is genuinely valuable. Few people wish to return to an internet in which finding information required memorizing obscure web addresses or navigating labyrinthine directories. The platforms did not succeed by forcing people into inferior experiences. They succeeded because, for many years, they built better ones.
Yet convenience has always carried an intellectual cost. Every technology that removes friction also removes moments of deliberation. The elevator spares us the staircase but also the awareness of distance. Satellite navigation ensures that we rarely become lost, while quietly diminishing our ability to construct mental maps of the places through which we travel. Streaming services relieve us of searching for entertainment, but in doing so they also shape the boundaries of what we are likely to discover. Every act of technological simplification transfers a small measure of agency from the individual to the system.
The internet had originally been built on a different assumption. Its underlying protocols did remarkably little. They did not decide which website deserved prominence, which ideas should travel furthest, or which communities ought to flourish. Their genius lay precisely in their restraint. They created conditions under which others could innovate without first requesting permission. The web itself functioned less like a product than like a constitutional order: a simple framework within which extraordinary diversity could emerge.
Platforms gradually adopted the opposite philosophy. They did not merely provide the rules of the game; increasingly, they became active participants in every interaction taking place within it. They selected what deserved attention, inferred what users might prefer before users themselves knew it, prioritized certain relationships over others and determined, through millions of microscopic computational decisions, the contours of everyday experience. The architecture became less constitutional than managerial.
Advertisement
There is an illuminating parallel here with the history of cities. The most enduring cities are rarely the ones that have been planned in every detail. They are those that accumulated layer upon layer of human activity over centuries, adapting continuously to changing needs without ever fully surrendering their unpredictability. One finds unexpected bookshops beside cafés, workshops hidden behind apartment blocks, public squares appropriated for demonstrations one week and festivals the next. Their vitality emerges not from perfect organization but from the freedom they grant people to appropriate space in ways that planners never anticipated.
Shopping malls operate according to an altogether different logic. They are meticulously designed environments in which every entrance, corridor, sightline, and seating area has been carefully considered. Music, lighting, and architecture work together to produce an experience that feels spontaneous while being anything but. There is comfort in their orderliness. They are clean, efficient, and reassuringly predictable. Yet no one mistakes a shopping mall for a city. Its purpose is not to cultivate civic life but to optimize a particular set of behaviors within a privately governed space.
The analogy is imperfect, as all analogies are, but it captures something essential about the transformation of the internet. The early web invited participation because it remained fundamentally unfinished. It assumed that users would contribute to shaping it. Today’s dominant platforms present themselves as complete worlds. Participation still exists, but it takes place within boundaries established elsewhere. Users generate the content while the architecture remains firmly in corporate hands.
Perhaps this is why the language of “community” has begun to feel strangely hollow. Communities, in the classical sense, are rarely designed. They emerge through shared experience, mutual obligation, and a degree of unpredictability that no algorithm can fully reproduce. Platforms, by contrast, increasingly treat community as an engineering problem to be optimized. They recommend friendships, suggest conversations, rank relevance, suppress friction, and amplify interaction according to models whose objectives are necessarily commercial because the organizations that develop them are commercial enterprises.
Advertisement
None of this should be understood as an accusation of bad faith. Many of the engineers responsible for these systems genuinely believed they were improving people’s lives. The difficulty lies elsewhere. Every large institution eventually begins to confuse the optimization of its own internal metrics with the fulfillment of its original purpose. Universities sometimes mistake publication counts for scholarship. Hospitals occasionally confuse efficiency with care. Governments become preoccupied with administrative process rather than public service. Technology companies are no different. The indicators that make sense within an organization slowly become proxies for the world outside it. The metric is not the mission. This is the point at which the maps begin to replace the territory.
The extraordinary quantities of behavioral data collected by digital platforms produce an understandable confidence. When one can observe billions of interactions each day, it becomes tempting to believe that society itself has become legible. Human behavior appears measurable, predictable and, increasingly, governable. The platform begins to resemble reality because so much of reality passes through the platform.
Yet the map is never the territory. It captures what can be measured, not everything that matters. A map records roads but not the reasons people travel. It identifies cities without conveying the lives unfolding within them. Likewise, recommendation systems observe behavior with astonishing precision while remaining largely indifferent to experience itself. They recognize patterns without necessarily understanding meaning.
That distinction mattered little while the platforms continued solving the problems that had made them indispensable. It becomes far more consequential once they begin confronting a world that no longer resembles the one for which they were originally designed. Because societies have changed; politics has changed; and, the internet has changed. The question is whether the companies that grew powerful by interpreting one era have noticed that another has already begun.
Advertisement
Konstantinos Komaitis, PhD, is a veteran of developing and analysing Internet policy to ensure an open and global Internet.
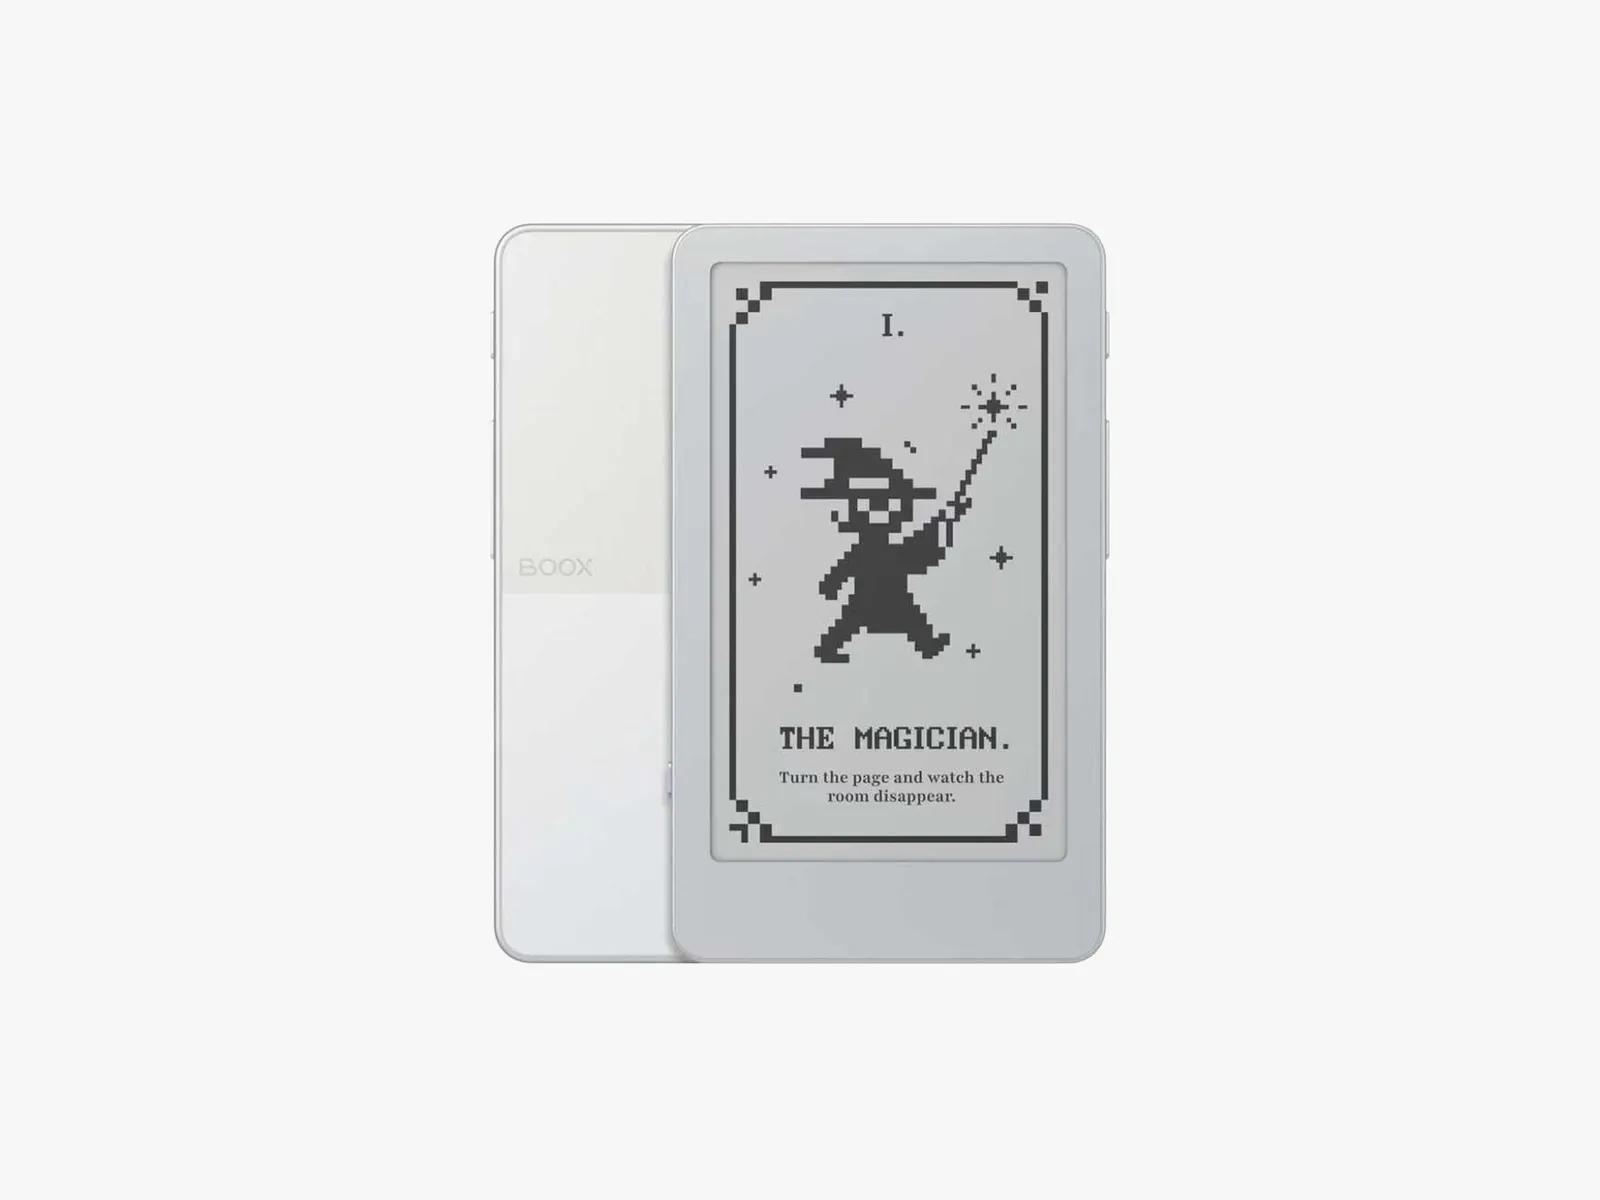
While smartphones won’tstop getting bigger, e-readers seem to be getting smaller. Boox has been at the forefront with one of the most popular small e-readers, the Boox Palma, and now it is adding an even smaller model.
Boox announced the Picco, with preorders opening today. Its screen is just under 4 inches (3.97 to be exact), making it about the size of a playing card. It’s even smaller than the Xteink X4 Pro I tested earlier this year, which has a 4.3-inch screen (but just slightly larger than the 3.7-inch Xteink X3), and considerably smaller than the upcoming Boox Palma 3’s 6.19-inch screen. I liked the size of the Xteink in my hand, but navigating the interface and getting books were challenging, so I’m excited to see another option in that smaller size from a maker with more accessible ebooks (though still not as convenient as a Kindle or Kobo with their built-in stores).
The Picco will cost $100 and is expected to ship in November. I’ll be testing it soon, but in the meantime, here are the details if you’ve been eyeing a tiny e-reader.
An E-Reader for Productivity
Courtesy of Boox
The Boox Picco has a monochrome screen with a resolution of 235 pixels per inch and an adjustable front light that switches between warm- and cool-toned lighting. The microSD card slot supports up to 2 TB of flash memory storage (a 16 GB card is included). There are both a touchscreen and physical page-turning controls, thanks to the buttons on the side of the device. The case has a magnetic ring so you can attach it to the back of a smartphone, though I’ll have to see how well it fits when I test it, as I had mixed results attaching an Xteink to my phone due to both fit and magnet strength.
Advertisement
Courtesy of Boox
Boox says the Picco will have a streamlined operating system focused on reading and digital utility tools. It’s also the first in what Boox calls its Tiles lineup, which is how you’ll access ebooks on this device. You can also use web and USB-C file transfers (the Picco has Wi-Fi and Bluetooth connectivity) to get ebooks onto the Picco. The Picco also has the Pomodoro, Todo, and Countdown apps, so you can use it as both an e-reader and a productivity gadget—handy, and a bigger motivation to keep it attached to the back of your phone even when you aren’t reading.
I’m intrigued to see it in action. Boox’s most popular e-reader could become the Picco over the Palma 3, but we’ll have to wait for both devices to become available to see which is the better buy. Stay tuned for my reviews of both when they come out.
But a Chromium-based design means it can only be so efficient.
Discord
Discord is working on a new mode for its social platform that it says might be less resource-intensive. Screenshots of an option called Game Mode began circulating on social media over the weekend. The description shown for the Game Mode toggle states that it will “Reduce Discord’s CPU and GPU usage while a game is running.” By making the chat platform less resource-intensive, concurrently running software should be able to run more smoothly.
Today, the company confirmed on X that this experimental mode will begin rolling out to its users next week. The brief official announcement about Game Mode added that Discord is “aiming to add more resource-saving features over time.”
Discord is based on the Electron web app framework, which uses Javascript and Chromium for creating software. The open-source Chromium, which is the basis for Google’s Chrome and several other browsers, is not known as the most efficient tool for web development. A feature like Game Mode could offer some performance improvements, especially while also running a beefy AAA game on the same machine, but there may only be so far that Discord will be able to streamline on its current architecture.
Six of the nine independent experts on the advisory board of the Global Internet Forum to Counter Terrorism—a consortium run by several of the biggest US tech companies—resigned on Monday, according to a letter seen by WIRED and interviews with three of the people.
The tensions between the independent advisory committee and the GIFCT date back to an email the counterterrorism and free speech experts received in July from Meta’s Nell McCarthy, a vice president overseeing content policy. For years, the group had advised the GIFCT on how to prevent platforms from becoming havens for the radical organizations and individuals blamed for some of the world’s worst mass violence.
But McCarthy wrote that while the consortium welcomed the experts’ insights on violent trends, it no longer desired their scrutiny on the effectiveness of Big Tech’s efforts to curtail violence. Meta and other leaders wanted to “refresh” the 6-year-old independent advisory committee the experts sat on, she wrote. Meta currently serves as chair of GIFCT’s operating board, giving it outsized influence over policy changes, though other companies on the panel must ultimately approve.
New additions to the rotating advisory committee had previously been elected by current members; under the plan laid out in July, they would instead be picked by tech companies. The committee would be barred from weighing in on key topics such as the consortium’s performance and making recommendations together as a group. Its role as a watchdog would be neutered, advisers believed.
Advertisement
In their resignation letter, the departing members of the committee wrote that their appeals against the plan had been “ignored” and that, in turn, they had “lost confidence in the GIFCT’s ability to deliver effectively on its founding mission” to prevent terrorists from exploiting online services. “We all know that a body that cannot scrutinise, take a position, or evaluate is not an advisory body at all,” the letter stated. “It is decoration and accountability theatre.”
Meta deferred comment on the resignations to the GIFCT. An unsigned statement sent to WIRED by a GIFCT spokesperson on behalf of the consortium’s leadership and the Meta-chaired operating board says the proposed changes have been “informed by several rounds of feedback” and are not yet final. They came out of discussions on “how to more effectively engage civil society and governments for substantive input” as “multi-stakeholderism is a core principle” for the GIFCT.
The consortium has about 35 members; other long-time board members include Microsoft and YouTube. A small staff alerts members to violent content, helps them exchange threat intelligence, and commissions research on countering extremism. While the coordination has helped some platforms combat problematic content, critics believe the group isn’t living up to its potential.
A WIRED investigation in 2024 uncovered several issues with GIFCT, including Meta delaying TikTok’s membership bid and poor relations between the companies at the helm and the unpaid independent advisory body. It also revealed failures in the tip-sharing database the consortium oversees to coordinate takedowns of problematic content.
Advertisement
The dismantling of the advisory group threatens to deteriorate the organization’s work further at a time when balancing free expression and online safety has become more challenging. Generative AI tools have simplified content creation but imposed limited guardrails.
The experts who resigned include university researchers and representatives of civil society organizations. They had agreed with McCarthy on the need for changes to improve the results of the decade-old anti-terrorism consortium. But they believe the proposal, which could be finalized soon, amounts to a step backward.
“There won’t be critical voices raising concerns about what GIFCT is doing or is not doing,” one of the departing experts says. “It may seem politically convenient for them to abolish the independent advisory committee, but they are going to regret it in the longer term.”
The successful mission also deployed 26 of SpaceX’s latest Starlink satellites.
SpaceX
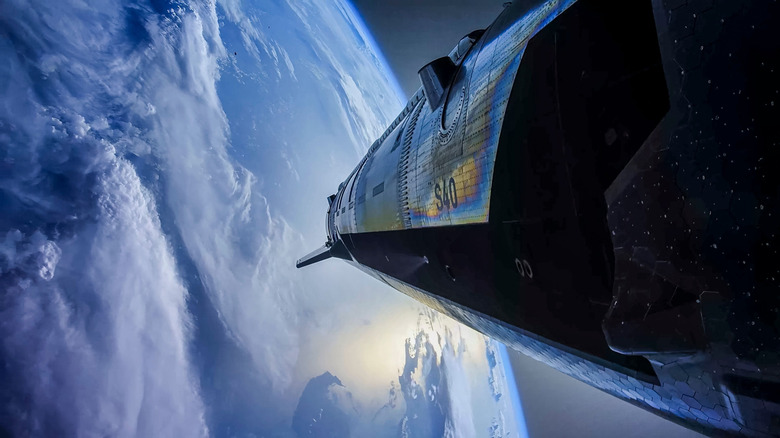
For its 14th flight, SpaceX’s Starship powered by its Super Heavy megarocket has entered low-Earth orbit for the first time. SpaceX kicked off this major undertaking early Monday morning but had to deal with some hiccups on the way, including losing one of its six Raptor engines. Ultimately, SpaceX decided to push on with the mission and successfully reached orbit albeit with some compromise.
SpaceX originally planned to have Starship orbit Earth six times over a span of nearly 10 hours for the Flight 14 mission. With one of the engines offline, the plan changed to only spend approximately three hours in orbit before reentering the Earth’s atmosphere and landing in the Pacific Ocean. As part of the same mission, SpaceX managed to deploy 26 of its Starlink V3 satellites into orbit. SpaceX said that its Starlink team has made contact with all newly-deployed 26 satellites in orbit, which will eventually be used to improve Internet speeds for customers. While previous Starship missions also carried several V3 satellites, they only remained in suborbital space and served as test flights to see if the new satellites would connect to the existing Starlink constellation.
While Starship’s flight 14 marked a major milestone of reaching orbit, the mission also served as a test of the reusability of its Super Heavy rocket. After providing the necessary boost to Starship, Super Heavy landed in the Gulf of Mexico, where it will eventually be retrieved, but not by a launch tower‘s “chopsticks” as previously demonstrated.
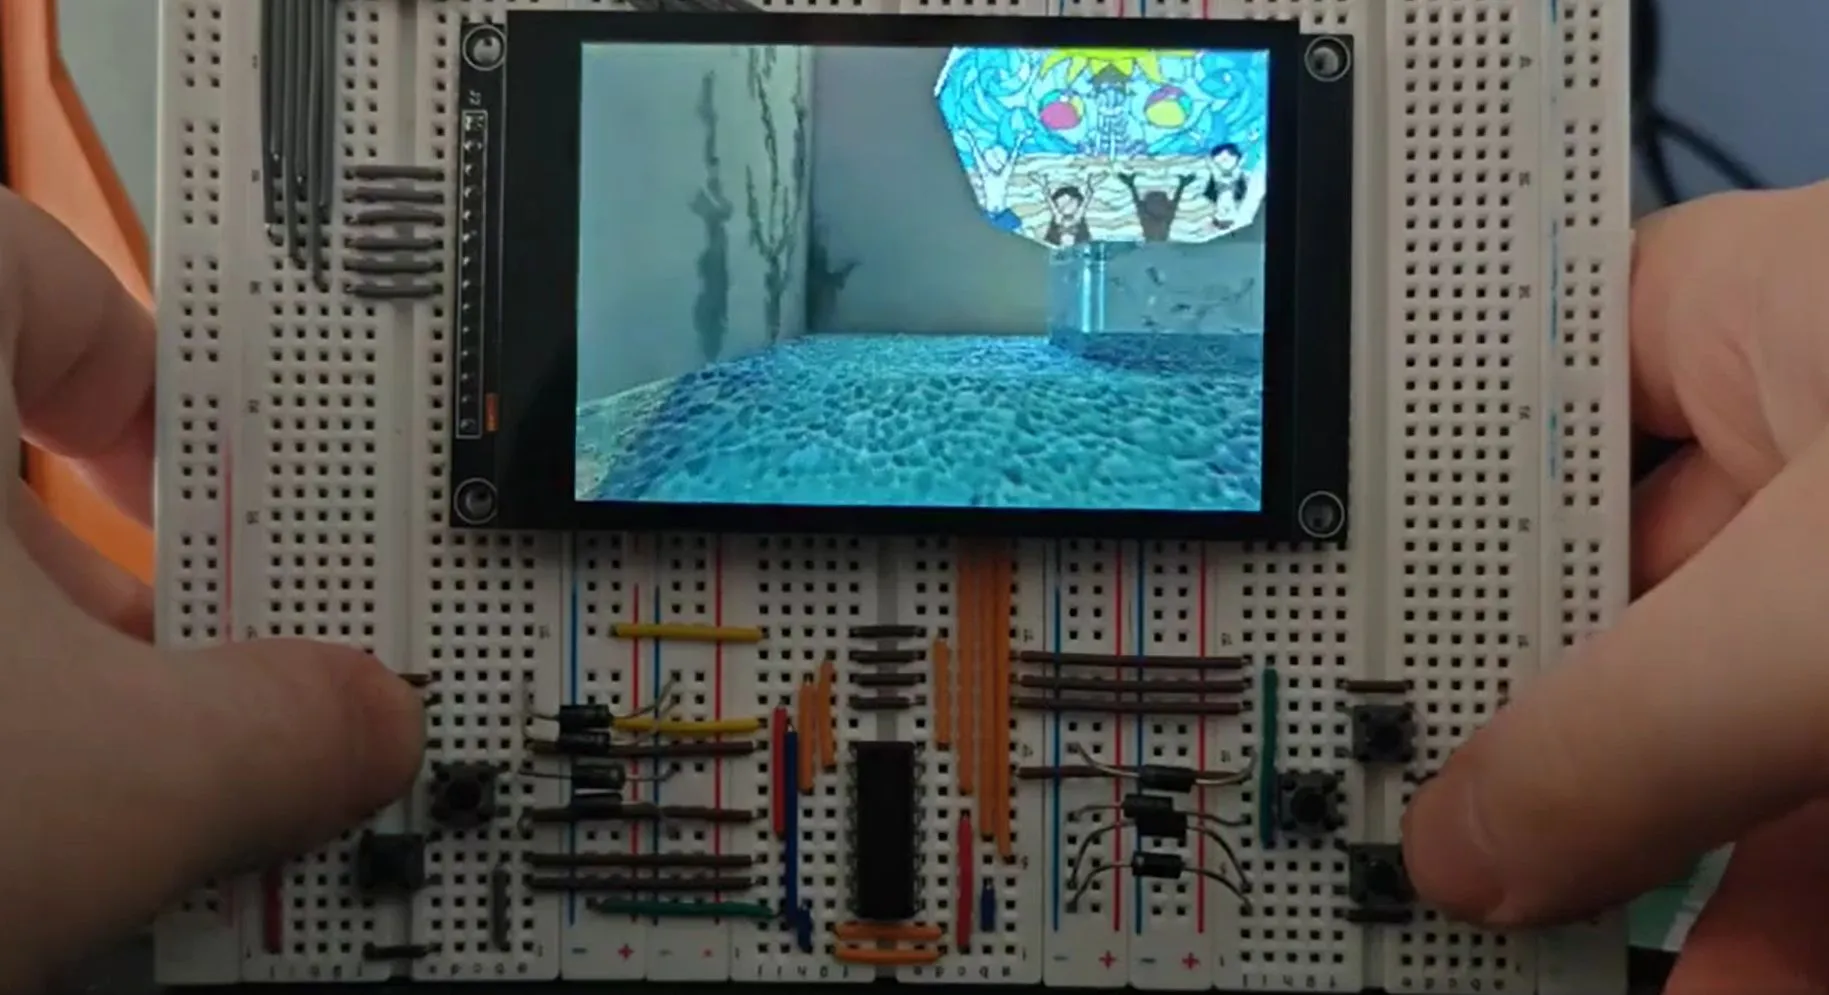
Mipmapping is a good way to add a lot more detail to a 3D scene without overburdening the rendering hardware with detail that won’t be seen by the user. This level-of-detail rendering technique was demonstrated on the N64 console hardware a few years ago by [James Lambert] with [Michael Biggins], also known as [PhonicUK], now demonstrating it on the ESP32-S3 using his own Jet rendering engine.
Although level-of-detail rendering really speeds things up, it does also require far larger texture sizes, with [James]’s N64 demo taking up 40 MB of a 64 MB cartridge. To fit it on an ESP32-S3 with 16 MB of PSRAM and no SD card expansion or such the textures were further compressed to use 8-bit indexing, resulting in a mere 5.01 MB of textures.
There’s a demonstration video over on the associated Reddit thread, which shows the camera moving through the scene. Even if not as exciting as the Wipeout port by [Michael] that we previously covered, it does make clear that even without a proper 3D GPU the ESP32-S3 is already a pretty capable gaming machine that can go toe-to-toe with some 1990s consoles.
There are five weeks left until the midterm elections, and extremism is on the ballot in much of the US. A WIRED review of candidates running for statewide and federal positions in November, along with exclusive data on candidates running for state-level positions, reveals hundreds of Republican candidates who openly express virulently hateful ideologies, share racist content online, have close ties to white supremacist and antisemitic figures, and are members of far-right groups online. President Donald Trump and his administration have openly embraced, endorsed and defended many of these candidates.
At a local level, over 500 candidates running for state legislator positions in November are members of far-right groups on Facebook that promote militias, gun rights, and Christian nationalism, according to data collected by the Institute for Research and Education on Human Rights and shared with WIRED.
“The candidates are taking a page out of the Trump administration’s playbook,” Luke Baumgartner, a former research fellow at George Washington University’s Program on Extremism, tells WIRED. Baumgartner claims that many of the candidates running in November have been inspired by those in the White House. “In essence, the executive branch has handed them a permission slip to say and do what would have been unthinkable during the George W. Bush, McCain, or [Mitt] Romney eras of the GOP,” he says.
Advertisement
Extremist rhetoric has led to real world political threats. In 2025, terrorism and targeted violence incidents rose 19 percent compared to 2024, according to researchers at the University of Maryland; the US Capitol Police reported an increase in “threat assessment cases” against members of Congress for the third year in a row, with a 58 percent increase from 2024; and the US Marshals Service documented threats against almost 400 judges, a roughly 5 percent increase from the previous year.
Here are five races involving candidates who have shared extremist ideologies or have close ties to extremist figures, that WIRED is watching ahead of the November midterms.
The Texas Railroad Commissioner Race
Photo-Illustration: WIRED Staff; Getty Images
Bo French, the GOP candidate for Texas Railroad Commissioner, is so extreme that Republican strategist Karl Rove has said he would vote for a Democrat rather than supporting a “bigot.”
We spend hours testing every product or service we review, so you can be sure you’re buying the best. Find out more about how we test.
Roborock Qvero 2 Pro: 30-second review
The Qrevo 2 Pro is the latest robot vacuum and mop combo cleaner from Roborock and includes detachable mop plates to help ensure it doesn’t get carpets wet while cleaning.
Cleaning performance is a match for some of the most expensive options on the market with its mopping being as good as I have ever tested making it a fantastic pick for the price.
Advertisement
It is relatively tall so it can’t clean under low furniture and its hard floor cleaning isn’t flawless but it is an excellent option, especially when on sale.
Latest Videos FromTechRadar
Advertisement
Roborock Qrevo 2 Pro: price & availability
List price: $799.99 / £649.99 / AU$1,199
Launch date: August 2026
Availability: worldwide
The Roborock Qrevo 2 Pro sits right on the line between premium and mid-range robot vacuums, with a list price $799.99 / £649.99 / AU$1,199. However, almost immediately after launch I have already seen it get a significant discount to $549 / £549.99, tipping it firmly into the more affordable category — especially considering the features and performance.
Even at full price it sits below the Roborock’s Curv models and produces similar results (although it doesn’t have the AdaptLift chassis for getting over higher thresholds between rooms) making it an excellent value pick. If you’re looking to spend less, the Roborock Q7 is a good alternative although it has much lower suction power and doesn’t have an auto-empty dock.
A branded floor cleaner compatible with the Qrevo 2 Pro is available on Roborock’s website but they don’t push this hard and after testing it without it, it’s definitely not required.
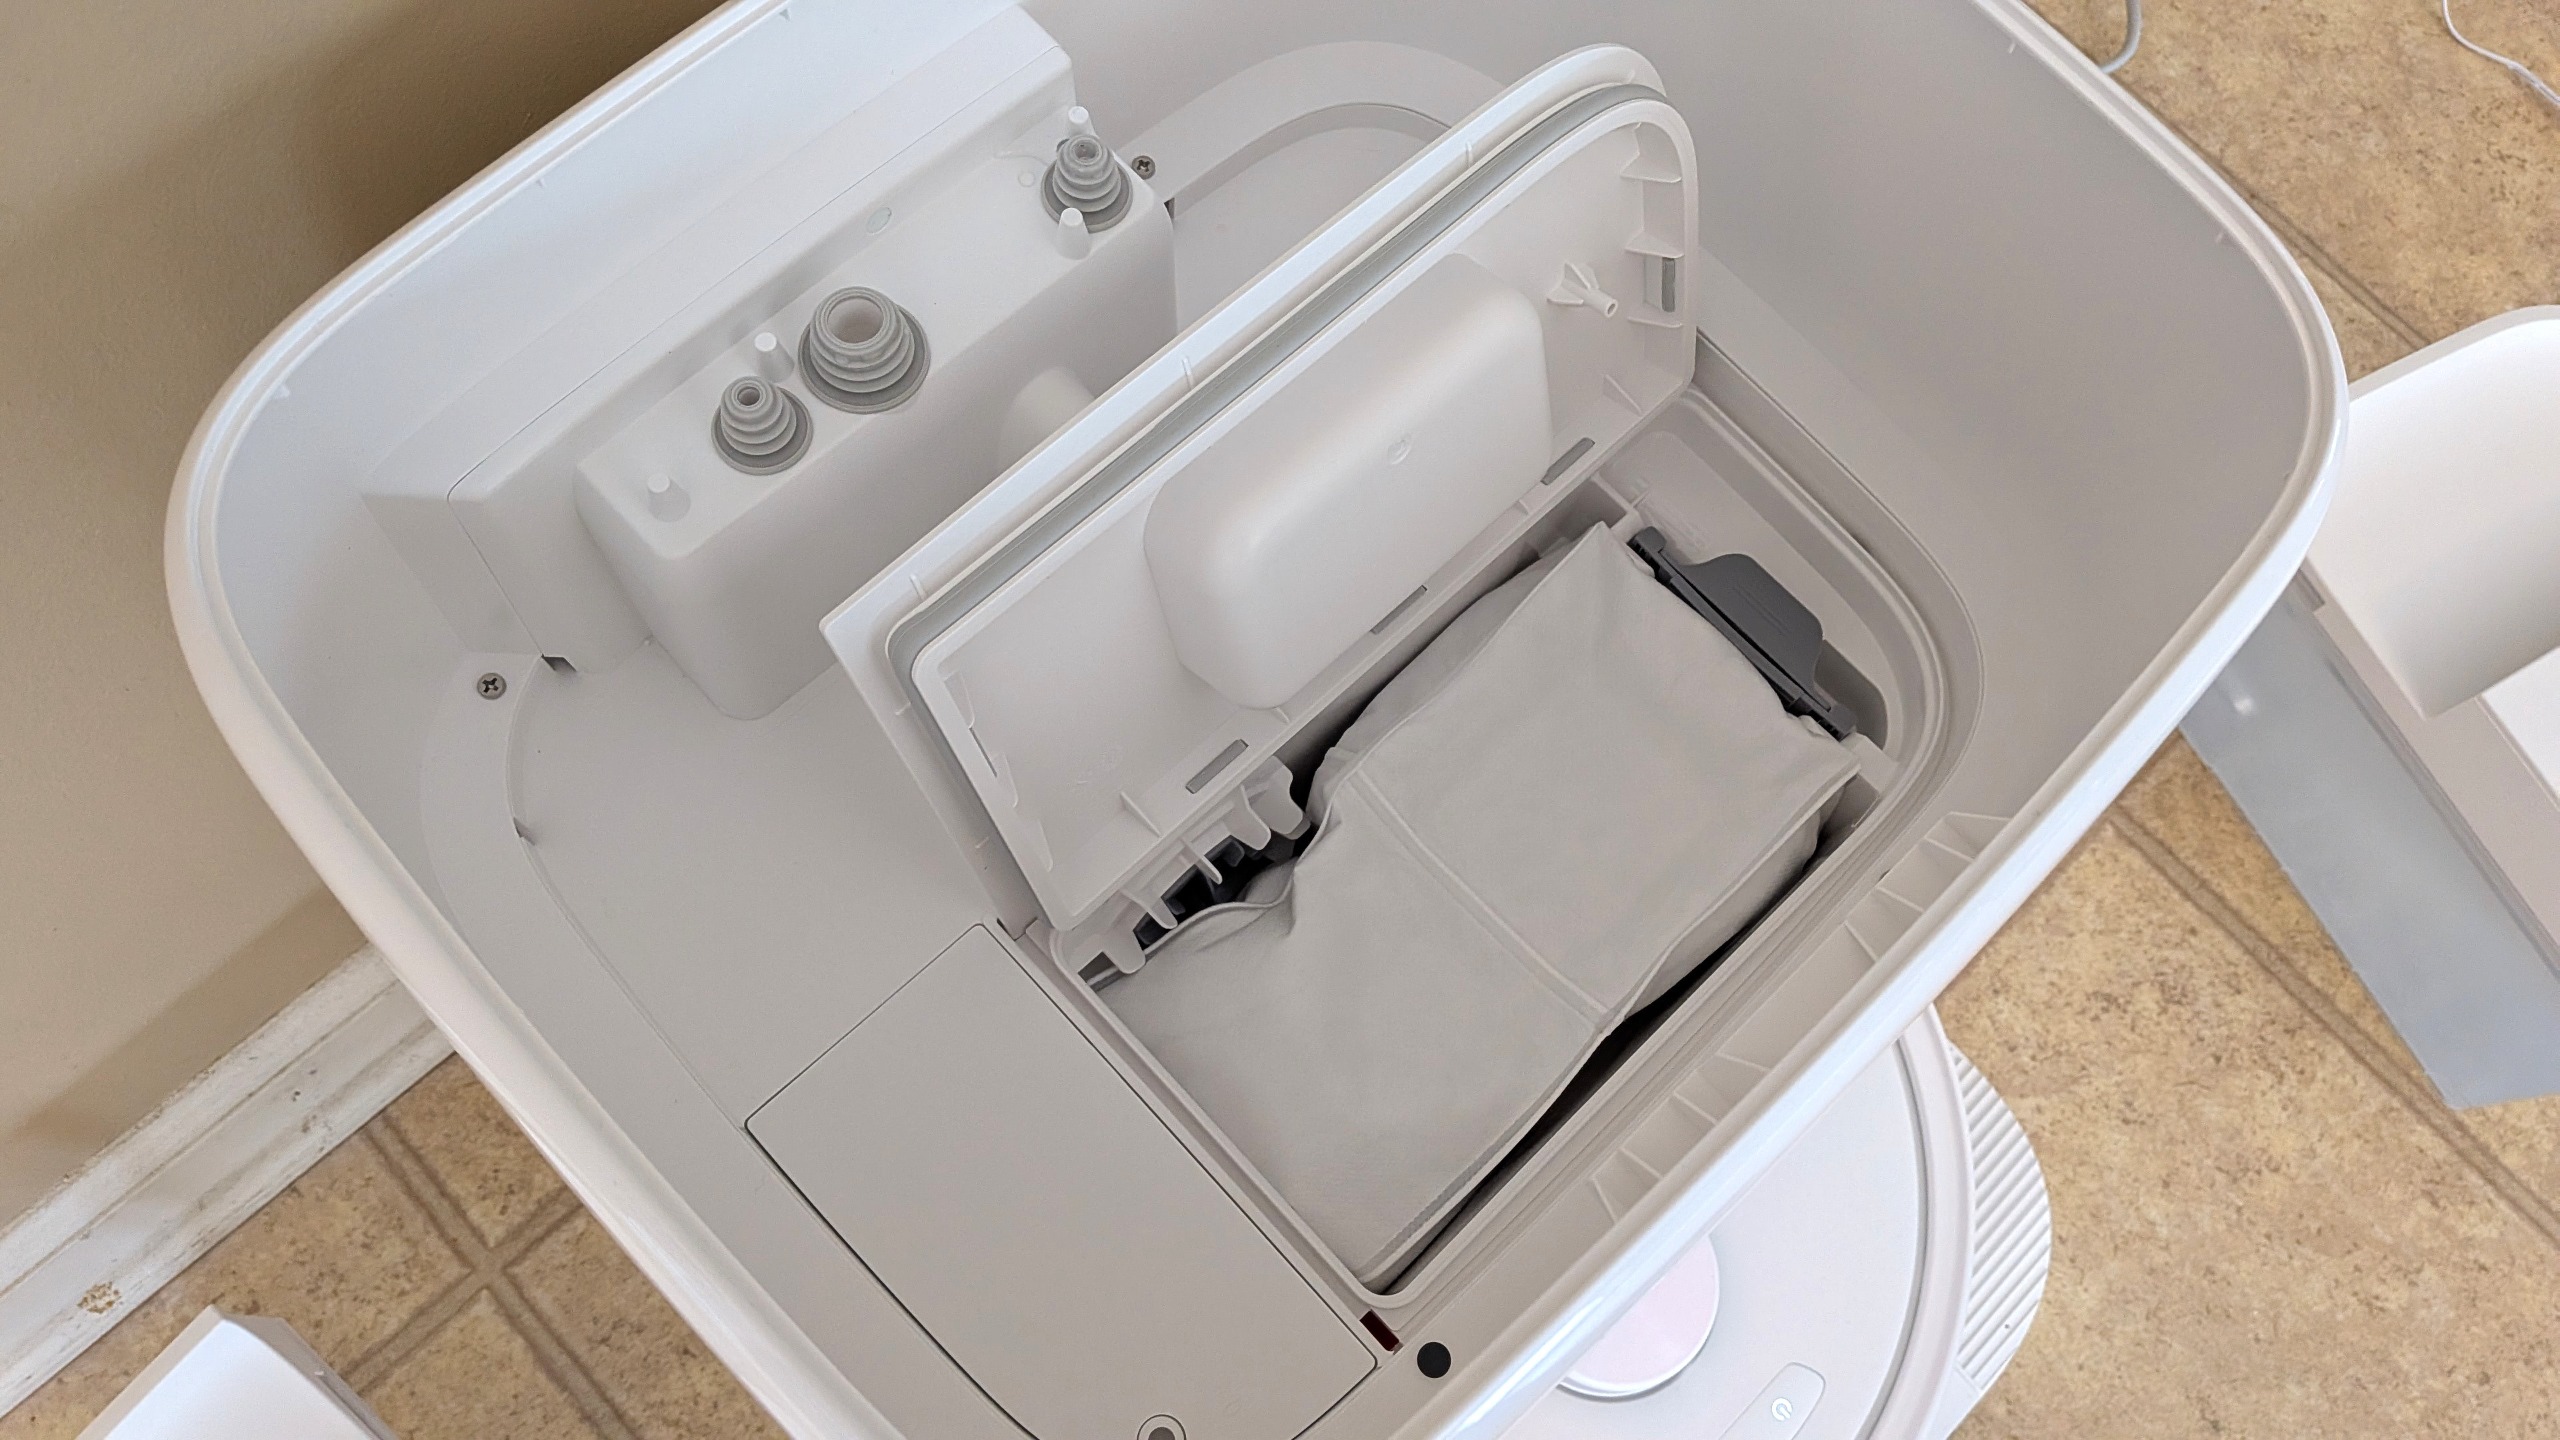
You don’t have to use Roborock’s own floor cleaner, but you will need to buy disposable dust bags (Image credit: Future)
What you will need to buy are disposable dust bags as these are thrown away once full. A three-pack costs $39.90 in the US, and a six-pack is £31.99 in the UK, so this needs to be considered in the running costs. I have tested Roborocks with cheaper unbranded dust bags in the past and not encountered problems, but check model compatibility before ordering.
Sign up for breaking news, reviews, opinion, top tech deals, and more.
Advertisement
You can also buy replacement brushes, mop pads, filters and other parts in case anything breaks.
Roborock Qrevo 2 Pro review: design
Smart-looking robot and dock
Can’t get under low furniture
Smart home integration
Available in all white or black (currently only available in white in the UK and Australia) it is pretty unfussy in terms of design with the dock a bit squarer than the slightly bulbous base stations of Roborock’s Curv series.
The robot is circular, measuring 14 inches wide with a 6-inch cleaning opening underneath for picking up dirt.
The lidar scanner the robot uses to navigate sits in a cage on top of the robot, increasing its height and reducing its clearance so it won’t be able to vacuum under low furniture like a sofa, unlike Roborock’s Qvrevo CurvX with its retractable lidar scanner.
Advertisement
Image 1 of 2
The robot’s lidar scanner doesn’t retract, so it can’t fit under low furniture
(Image credit: Future)
The dock is easy to set up, provided you have sufficient space
(Image credit: Future)
Setting the dock up is easy, involving just attaching the ramp to the front of the dock, filling the clean water tank and plugging it in. The more difficult part may be finding a place for it as it needs to sit on a hard floor with at least 1.5 inches either side and 27.5 inches of clear space in front of the dock. It also needs to be within reach of a power socket and somewhere you won’t trip up over it or mind looking at it everyday.
Set up is simple, you will need to find an appropriate spot for the dock on a hard floor with plenty of space either side. You then download the app, pair the robot and then you can send it on a discovery run around your house to build a map.
Once it has scanned the space you can then edit the map to combine or divide spaces into rooms, mark areas as no-go zones, manually designate floor types and mark things like curtains and furniture. I found that aside from ensuring the rooms are divided correctly I didn’t have to make any changes to get it to work well, with the carpeted areas successfully detected.
Advertisement
The robot has detachable mop pads, which it leaves in its dock after mopping your floors (Image credit: Future)
After setup you can use the app to kickstart cleans of the whole map, one or more selected rooms or a designated zone clean you can mark on the map. As well as ad hoc cleans you can set routines for different types of cleans from deep intensive cleans, to specific after dinner cleans of smaller zones or light maintenance vacuuming without mopping.
As the Qrevo 2 Pro has detachable mops, rather than vacuuming and mopping room by room it first goes around the carpeted areas of the whole space you are cleaning first. Once that is complete it returns to the dock to reattach the mop heads before cleaning the rest of the hard floors.
Obstacle detection was generally good, though the Qrevo 2 Pro did get caught on a USB charging cable (Image credit: Future)
Cleaning performance is OK on hard floors, although it can lead to some spreading of larger debris as the edge cleaning arm sent rice grains skittering across the floor. It did better with fine particles, although there was still some tea visible on a pass on the standard cleaning settings.
It handled larger particles much better on carpet, picking up almost every single grain of rice, although there was some tea left after the first pass.
Advertisement
As with most robot vacuums, its edge cleaning wasn’t great on carpet, but the sweeping brush does well to move material into the vacuum’s path on hard floors..
During the obstacle avoidance tests it did well to identify the shoe and sock, staying clear as it cleaned around them but it did go over the charging cable, getting it stuck in the cleaning brushes and needing me to rescue it before it could continue cleaning.
During my mopping tests on first pass it did a reasonable job taking up a fair bit of the ketchup although there was a hint of the soy sauce remaining. Trying a second clean on maximum water flow and cleaning settings it did a fantastic job cleaning off even the dried on patches of ketchup.
While the most intensive cleaning took some time and left the floor relatively wet, it was some of the best mopping I have ever seen from a robot. You do need to delve into the settings to get the best performance and it probably is only practical for small zone cleaning but it’s still a lot less effort than getting out a mop and bucket.
Advertisement
On regular cleaning settings it can manage around five regular rooms before needing recharging so depending on your home it may need to recharge before completing a full clean. Recharging takes around four hours.
It’s not loud in operation, registering around 60db while cleaning on carpet. The dock emptying is a little louder, topping out at 69db (around the level of normal conversation), although this is pretty brief so shouldn’t be too disruptive.
The Qrevo 2 Pro uses dust bags so emptying it of dirt is quick and neat, although that does add ongoing costs to using it. You will also need to empty the waste water and refill the clean water tanks regularly which is easy to do (as long as you leave enough clearance room above the robot) as these lift out of the dock and then can be unclipped open for emptying or filling.
Smart home integration worked well for starting a whole house clean but I did have a little trouble using the room clean function for custom named rooms. Naming a room one of the default names such as Kitchen or Living Room worked fine, but a custom name such as Utility Room sparked a whole house clean instead.
Advertisement
While custom room names would be helpful, even getting default room cleaning to work is not a guarantee with any of the robot vacuum cleaners I have tested so, relatively, this is a success.
Performance score: 4.5 out of 5
Roborock Qrevo 2 Pro: app
Easy setup
Clear house map
Can set frequent types of clean and schedule cleans
The app is simple to use, although I did find it can sometimes get a little lost if you select your cleaning mode too quickly, meaning you have to move to another mode and back again before getting the options you need.
Once you select the robot you are shown the map of your home and have four tabs to select the type of clean you want, ‘Full’, ‘Room’, ‘Zone’ and ‘Routine’. ‘Full’ starts a clean of the whole map and to the left of the play button there is a button for adjusting the type of clean including whether you want to vacuum and mop, just vacuum or just mop. There are also controls for the level of suction, waterflow, amount of times you want the robot to clean the area and the intensity of the cleaning pattern.
Image 1 of 4
The app is simple to use provided you don’t hop between modes too quickly
(Image credit: Future)
Select your robot to see a map of your home
(Image credit: Future)
You can adjust the settings for the vacuum and mop independently
(Image credit: Future)
The ‘Routine’ option allows you to schedule different types of cleaning
(Image credit: Future)
Room allows you to select one or more rooms to clean, while Zones lets you pick multiple rectangular sections of your chosen size on the map for it to clean, allowing you to spot clean specific sections of floor.
‘Routine’ is the final option and allows you to create shortcuts for regular types of clean that will then be available from the opening screen on the app. This is useful for setting up things like zone cleans that focus around a dining table following a meal or if you want a predefined deep clean compared with a light maintenance clean.
Advertisement
Despite the name, ‘Routine’ doesn’t include any scheduling functionality by default. That is hidden somewhat in the settings menu, but can be used with scheduled cleans (if your home doesn’t regularly have bits of Lego on the floor like mine does).
Should you buy the Roborock Qrevo 2 Pro?
Swipe to scroll horizontally
Attribute
Notes
Advertisement
Score
Value for money
Even at full price the Qrevo 2 Pro represents good value and at a discount price it is a fantastic deal. You will need to consider the price of disposable dust bags in the running costs but you’ll be hard pressed to find these features and performance for less.
5/5
Advertisement
Design
The design is more focused on function than form but it is unfussy and designed to fit into most homes. The tall mounting of the lidar scanner will stop it from cleaning under low furniture.
4/5
Performance
Advertisement
Vacuuming performance is good and mopping is excellent although It did have trouble picking up on a charging cable in our object avoidance tests leading it to get stuck.
4.5/5
App
The app makes it easy to control, with simple options for choosing the type and location of cleans as well as a clear map of your home.
Advertisement
5/5
Buy it if
Don’t buy it if
Advertisement
How I tested the Roborock Qrevo 2 Pro
I tested the Roborock Qrevo 2 Pro over a period of over two weeks, using it as an everyday cleaner of a busy household.
As well as day to day use I put it through a series of tests, assessing its performance picking up fine particles and larger debris on carpet and hard floor by having it clean an area with a set amount of rice and tea sprinkled on the surface. Edge cleaning was also tested using tea on the edge of a carpet and hard floor area.
Mopping performance was tested by having the robot clean up a spill of soy sauce, as well as tackling a patch of dried ketchup. After an initial pass on regular settings, this was then retested with cleaning settings set to maximum.




























You must be logged in to post a comment Login