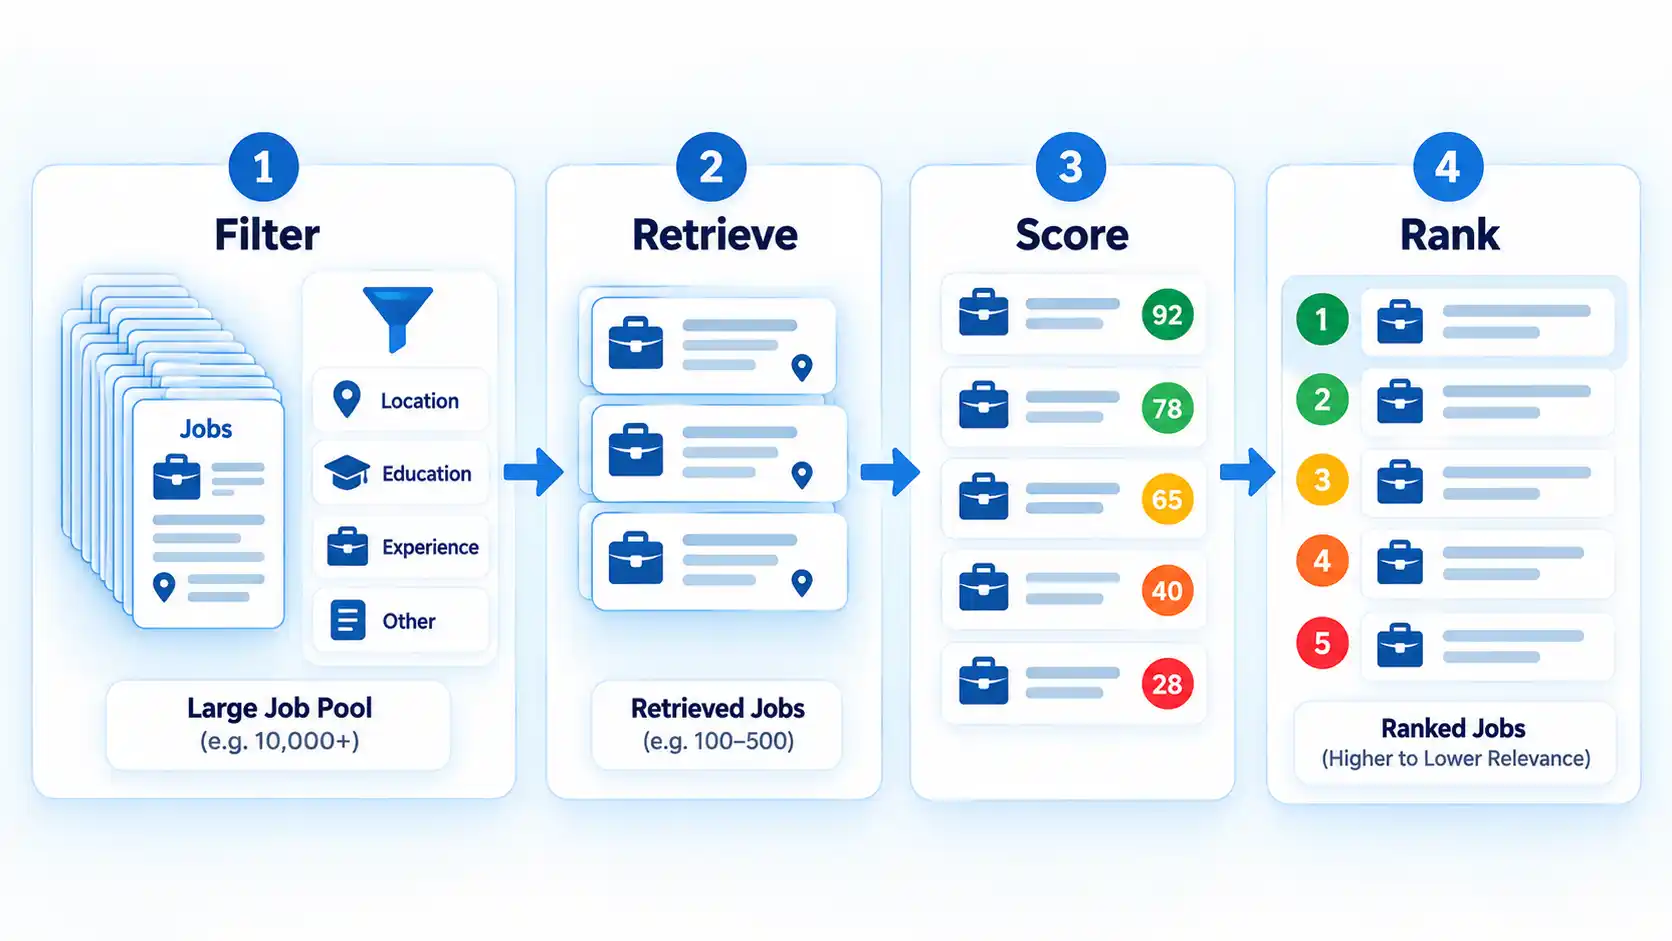
AI job matching turns information about a candidate and a job into signals, narrows the available pool, scores plausible matches, and ranks the results. More advanced systems can also use semantic similarity, behavior, and feedback, but a high-ranked match is still an estimate of relevance rather than proof that a person and job are objectively compatible.
There is no single algorithm that every job platform uses. Different systems can use different data, models, filters, ranking objectives, and feedback signals. The useful way to understand AI job matching is therefore as a common pipeline rather than as one universal formula.
AI Job Matching Is a Ranking Problem, Not a Mind Reader
AI job matching does not understand a person’s career in the same way a human recruiter or career adviser might. Instead, software converts available information about people and vacancies into data it can compare.
A signal is a piece of information a system can use when estimating how relevant a candidate and job appear to each other. Signals can come directly from profile fields, job postings, resumes, search preferences, or interactions with the platform.
Advertisement
Consider a nurse searching for a remote role. The candidate side might contain a nursing qualification, years of experience, location, preferred work arrangement, and listed skills. A vacancy might contain a title, required license, location rules, schedule, experience requirements, and employment type. A matching system can compare some of those details and use the result to narrow or order vacancies.
One important limitation appears before any sophisticated ranking occurs: both sides can be incomplete. A candidate may omit a relevant skill or certification, while a job description may leave an important requirement unstated. Missing information therefore does not necessarily mean the candidate lacks a qualification or that the job lacks a characteristic.
Step 1: Turn Profiles and Job Posts Into Matching Signals
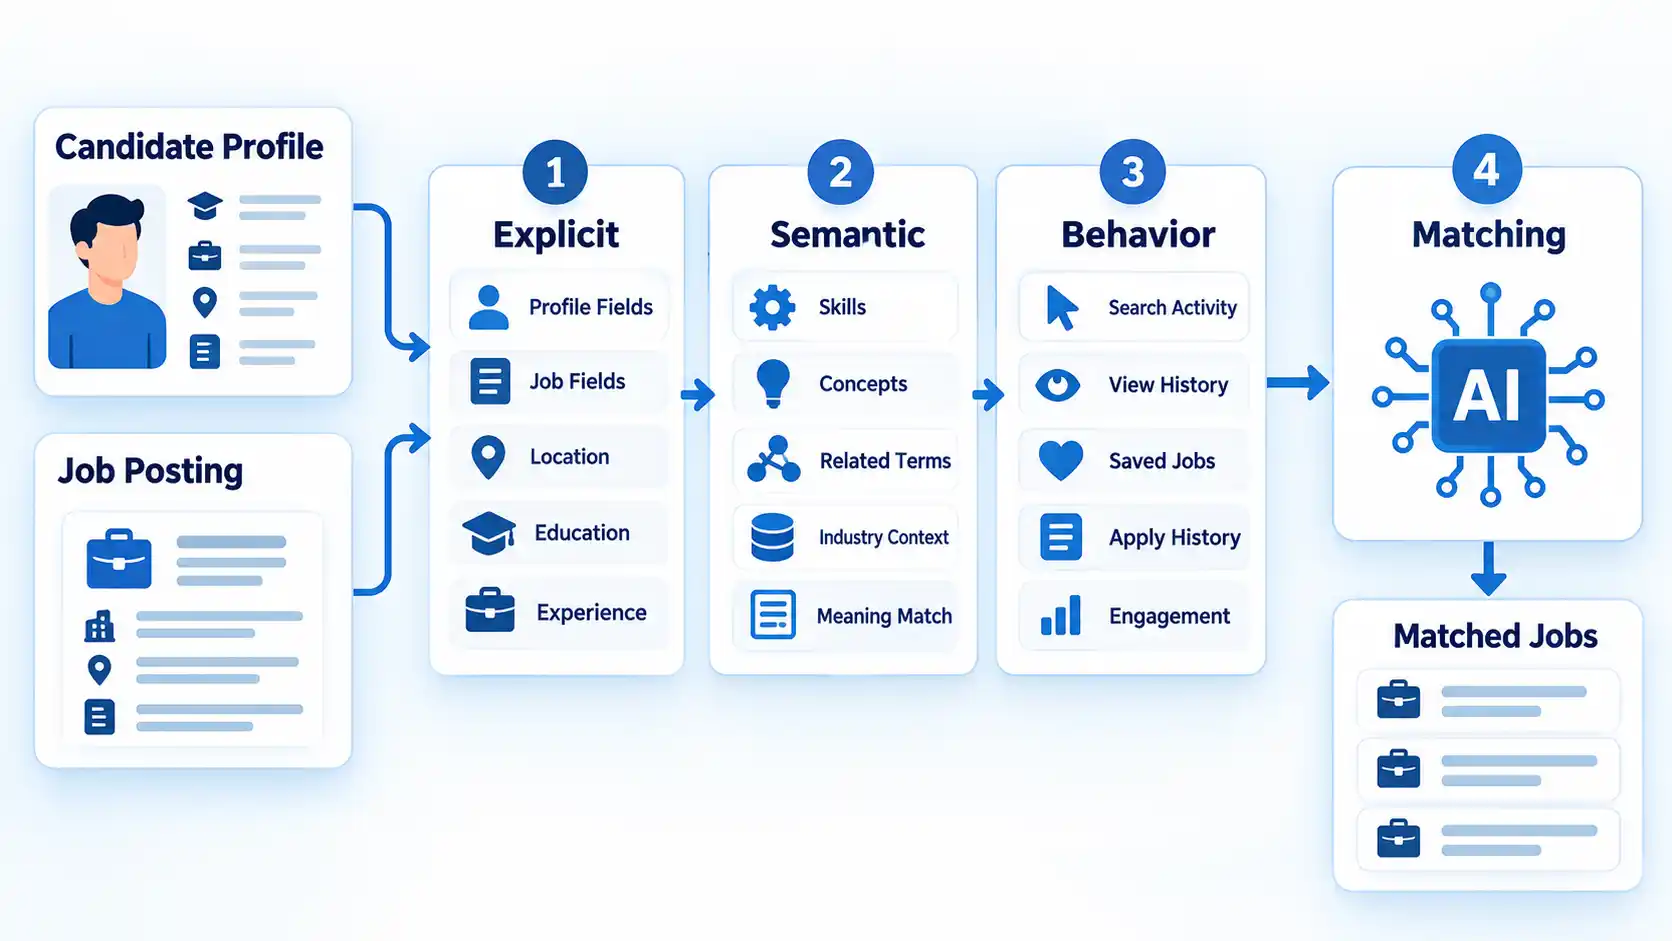
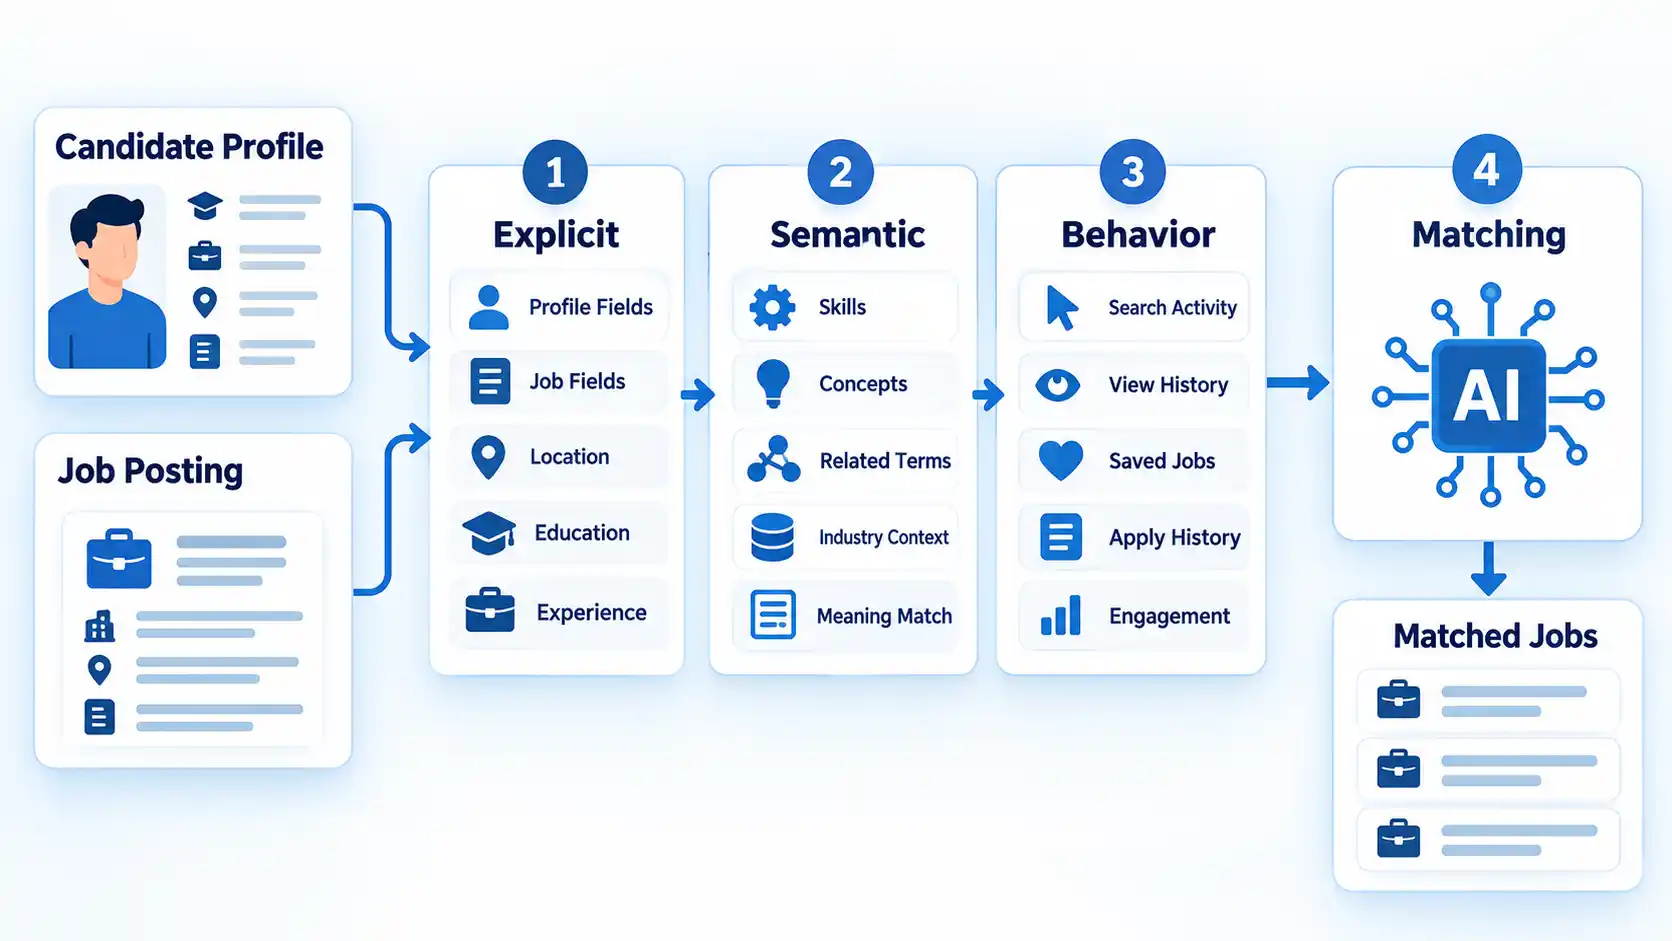
The first technical challenge is converting messy information into signals the system can actually compare. These signals fall into several broad categories, although individual platforms can define and combine them differently.
Advertisement
Explicit signals
Explicit signals are information that a user, recruiter, employer, or platform records directly. Examples include job title, location, employment type, degree, certification, salary preference, years of experience, and whether a person wants remote, hybrid, or on-site work.
LinkedIn’s current job-recommendation documentation says recommendations can use preferences including job titles, locations, location types, and employment types. It also says profile-based recommendations can consider information from a member’s headline, About section, experience, education, and location preferences.
Explicit information is useful because its meaning can be relatively clear. If a person selects remote work, the platform does not need to infer that preference from unrelated behavior. The limitation is that explicitly entered information can be incomplete, outdated, inconsistent, or too broad.
Inferred and semantic signals
Platforms can also derive signals from unstructured text. A skill, occupation, or concept may appear in a resume, profile summary, work history, or job description without being stored as a neatly selected field.
Advertisement
Semantic matching means comparing meaning or related concepts rather than depending only on identical text. For example, “SaaS” and “Software as a service” can describe the same concept even though the wording differs.
LinkedIn’s current Skills filter distinguishes explicit skills from implicit skills extracted or inferred from profile content. It also gives a concrete example in which a search for “SaaS” can return members whose profiles use “Software as a service” instead.
Semantic inference can expand useful matches, but it creates another failure mode: an inferred skill or concept can be wrong. Mentioning a technology in a project description does not always mean the person is proficient in it, and similar terminology can have different meanings in different industries.
Behavioral signals
Interactions can become signals too. Saving a vacancy or candidate, hiding a recommendation, messaging someone, applying for a job, or repeatedly searching for a particular role can provide evidence about likely interest or responsiveness.
Advertisement
LinkedIn’s Recommended Matches says recruiter actions such as saving, hiding, and messaging candidates are used as real-time hiring signals. It also describes job-posting signals such as titles, locations, and skills and member-side signals such as being open to work.
Behavior is useful but ambiguous. A user may ignore a job because it is irrelevant, because important information is missing, because they have already seen it, or simply because they never noticed it. Treating every interaction as a perfect description of preference can therefore teach a system the wrong lesson.
The table below separates the main signal categories from what they can reasonably tell a matching system. Every signal is a proxy for something the platform wants to estimate rather than a complete description of the person or job.
Common signal categories in AI job matching and their main limitations
Directly stated requirements, qualifications, or preferences
Information may be missing, outdated, broad, or entered inconsistently
Inferred or semantic signals
Skills or concepts extracted from profile, resume, or job-post text
Potential similarity even when the same exact words are not used
An inference can misread context or overstate experience
Behavioral signals
Clicks, saves, hides, searches, applications, or messages
Possible interest, disinterest, or responsiveness
An action may have several explanations and may not reflect true preference
Outcome or feedback signals
Employer response, interview progression, hire, or another observed outcome
Whether previous matches led to later-stage outcomes
Historical outcomes can reflect earlier human decisions, unequal exposure, or other biases
Step 2: Apply Constraints and Retrieve Plausible Matches
After signals exist, a platform does not necessarily run its most detailed scoring process against every possible person-job pair. Large marketplaces can contain enormous numbers of profiles and vacancies, so matching can begin by reducing the search space.
Advertisement
A hard constraint is a condition treated as required for a particular search or matching operation. Depending on the system and user-selected filters, examples can include a location requirement, employment type, occupational credential, or another must-have condition.
Retrieval is the stage that finds a manageable set of plausible candidates or jobs before more detailed ranking. It answers a broad question such as “Which possibilities are worth evaluating further?” rather than “Which one should appear first?”
LinkedIn’s current recruiter documentation describes this separation directly: candidates matching requested keywords and facets are selected and then ranked using other factors. Its current AI Search documentation also says natural-language requests can be translated into structured filters such as location, skills, and job titles.
This distinction creates an important failure point. If a strict filter removes someone during retrieval, the later ranking system may never evaluate that person. A qualified candidate can therefore disappear because a requirement was entered too narrowly, a profile field is missing, a job title is unusual, or an equivalent qualification is represented differently.
Advertisement
Retrieval quality matters as much as ranking quality. A ranking model cannot promote a relevant result that was never retrieved.
Step 3: Score and Rank the Remaining Matches
Once the system has a smaller set of plausible matches, it must decide which results deserve the most prominent positions.
A relevance score is a model-produced value used to compare matches under the system’s chosen objective. Its exact meaning depends on the product. A score might reflect similarity, predicted responsiveness, expected usefulness, or a combination of signals.
It should not automatically be interpreted as a probability of being hired.
Advertisement
Current LinkedIn Recruiter documentation provides a concrete example of multi-signal ranking. It says candidates can be ranked using factors including similarity between their work experience or skills and the search criteria, together with the likelihood that an interested candidate will respond. LinkedIn says those factors are weighted using machine-learning models.
A simplified matching system might face a trade-off like this:
Candidate A has very strong skills similarity but does not satisfy the preferred location.
Candidate B has slightly weaker skills similarity but matches the location and employment preferences closely.
Candidate C satisfies the stated search criteria but appears less likely to respond.
These are illustrative examples, not LinkedIn’s published scoring formula. The final order depends on the objectives and weights used by a particular system. Commercial platforms usually do not disclose a fixed percentage for every signal, so it would be misleading to assign arbitrary weights to skills, location, experience, or activity.
Some recommendation architectures use more than one ranking pass. Reranking means taking an already retrieved or initially ordered set and applying another model or scoring stage to refine the order.
A 2026 job-recommendation study, for example, combined metadata filtering, TF-IDF lexical retrieval, Sentence-BERT semantic retrieval, and optional cross-encoder reranking. The research demonstrates one possible hybrid architecture; it does not establish that LinkedIn, Indeed, Lensa, or every commercial job platform uses Sentence-BERT, cross-encoders, or the same model sequence.
Advertisement
Why Keyword Matching and Semantic Matching Produce Different Results
Keyword matching and semantic matching solve related but different problems.
Lexical or keyword matching looks for words, phrases, or standardized terms. It works well when a candidate and job use the same vocabulary. If both contain “project manager,” the connection is straightforward.
The weakness appears when equivalent ideas use different language. A job might request “Software as a service” experience while a candidate writes “SaaS.” A narrow exact-text approach could miss that relationship.
Semantic matching attempts to capture related meaning so concepts can still appear similar without identical wording. This can help retrieve profiles or vacancies that strict text matching might miss.
Advertisement
The two approaches do not have to compete. The 2026 research system cited above combined lexical and semantic retrieval rather than replacing one with the other. Structured filters can preserve precise constraints while semantic retrieval can broaden matching across terminology differences.
Semantic matching also has limits. Two phrases can appear related to a model while carrying different practical meanings. “Machine learning research” and “machine learning operations,” for example, overlap in vocabulary and domain but can require substantially different experience. Better semantic recall therefore does not automatically mean better job fit.
Job Matching Can Be a Two-Sided Recommendation Problem
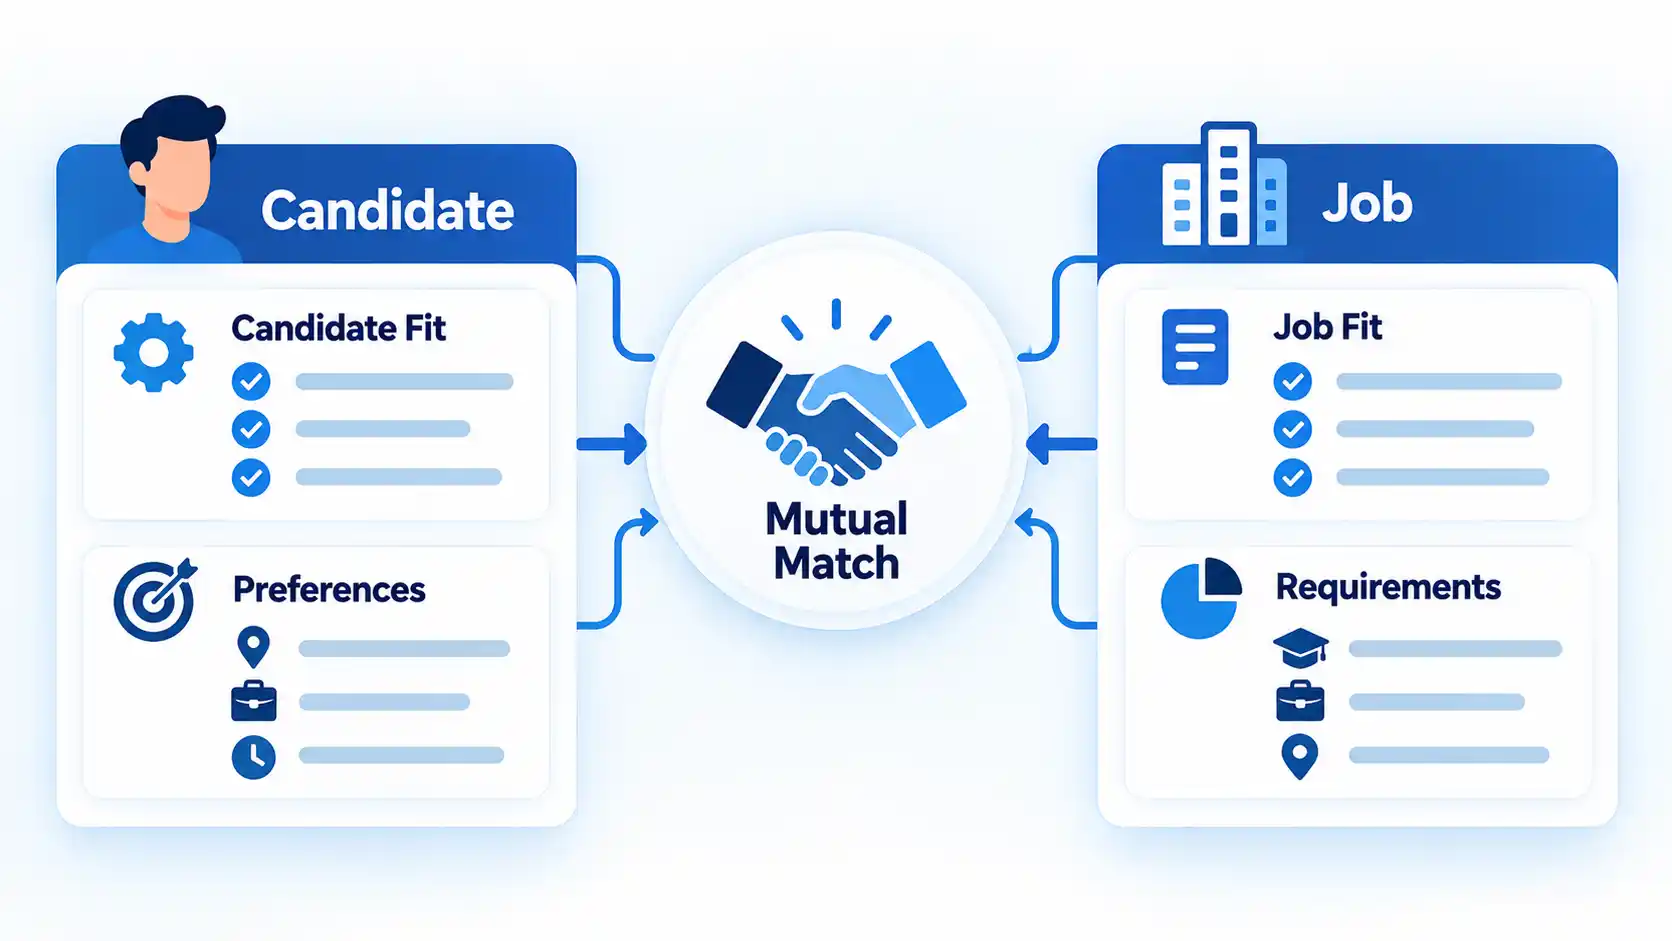
Job recommendation differs from many ordinary recommendation systems because a useful match may depend on both sides of the marketplace. It is not enough for a job seeker to like a vacancy if the role has requirements the person does not meet, and an employer’s preferred candidate may have no interest in the location, schedule, salary, or role.
Researchers often describe this as a reciprocal recommendation problem because relevance can operate in both directions. A review of job recommender-system research identifies reciprocity as an important feature of the domain and also highlights data availability, temporal effects, fairness, and generalizability as evaluation challenges.
Advertisement
Consider two candidates for the same vacancy. Candidate A strongly prefers the job but lacks a mandatory professional license. Candidate B has the license and relevant experience but wants a fully remote role while the vacancy requires daily on-site work. A single similarity measure does not capture both sides of those constraints and preferences.
Indeed’s public explanation of its own matching system similarly describes a two-sided marketplace and a process of understanding people and jobs, narrowing and ranking possible matches, and learning from subsequent outcomes.
This does not mean every platform optimizes the same objective. A system might optimize for a useful recommendation, an application, a response, an interview, a hire, or another measurable outcome. Unless a platform documents its objective, the safest interpretation of a ranking is that the system estimates relevance or expected usefulness according to its own design.
Feedback Can Improve Rankings, but It Can Also Reinforce Mistakes
Matching systems can use what happens after recommendations are shown as additional information. A feedback loop occurs when earlier recommendations generate behavior that later influences future recommendations.
Advertisement
Possible feedback signals include clicking or saving a vacancy, hiding a recommendation, applying, replying to a recruiter, progressing to an interview, or being hired when the platform can observe that outcome.
Indeed says its system uses outcomes including applications, employer interview progression, ignored jobs, and successful hires as feedback for later matching. LinkedIn separately documents recruiter actions such as saving, hiding, and messaging candidates as signals in Recommended Matches.
This can make a system more responsive, but feedback is not neutral ground truth. Suppose a platform initially shows a software engineer mostly fintech jobs. If the person can interact only with the jobs the system exposes, later behavior may appear to confirm a strong fintech preference even if healthcare or education-technology roles were rarely presented.
This illustrates a filter-bubble risk. A 2025 LinkedIn research paper on large-scale job matching explicitly identifies cold start, filter bubbles, and bias as practical challenges in its research context. The paper describes a particular signal-integration system rather than establishing that every production job recommender experiences these problems to the same degree.
Advertisement
Cold start is the related problem that appears when the system has little historical information about a new user, new vacancy, or new type of role. In that situation, profile content, job metadata, skills, titles, or other non-behavioral signals can become especially important.
The Main Limitations of AI Job Matching
AI can make large job markets easier to search, but every stage of the pipeline introduces assumptions and possible errors. These are parallel failure modes, not a ranking of which problem is worst.
Incomplete candidate profiles: a system cannot reliably use qualifications that are missing, outdated, or represented ambiguously.
Weak job descriptions: vague titles, inflated requirements, missing conditions, or unclear working arrangements reduce the quality of the information being matched.
Cold start: a new candidate, employer, vacancy, or occupation may have little interaction history from which to learn.
Incorrect inference: semantic models can infer a skill, occupation, seniority level, or relationship that does not accurately describe the candidate or job.
Feedback loops: future recommendations can become too dependent on what the system previously chose to expose.
Optimizing the wrong outcome: more clicks or applications do not necessarily mean better jobs, stronger fit, better conditions, or successful hires.
Ranking and exposure effects: higher positions receive more opportunity for attention, so ranking affects what users can see and act on.
Bias and proxy variables: harmful patterns can enter through data, labels, system design, human processes, or variables correlated with sensitive characteristics.
Changing labor-market patterns: occupations, terminology, skills, qualifications, and hiring behavior evolve, so relationships learned from older data may become less useful.
Opaque scoring: users may see an ordered list or match label without knowing which signals dominated the result.
Bias deserves especially careful treatment. NIST’s current harmful-bias research page explains that bias can arise from more than training data and that AI systems can perpetuate or amplify harmful patterns. Removing one obvious sensitive field is therefore not enough to establish that a system is fair.
Ranking creates another issue: exposure. A result shown near the top has more opportunity to receive attention than one placed much lower. NIST’s TREC Fair Ranking work explicitly studies systems that balance result quality with fair exposure. That benchmark is not specific to employment, so it is used here only to illustrate the broader ranking principle that ordering affects who or what receives attention.
These concerns become more consequential when automation moves from recommending opportunities toward evaluating applicants. Job recommendation should therefore be separated from AI resume screening, where employer-side systems may evaluate or narrow applicant pools rather than simply recommend vacancies.
Advertisement
What a Match Score Does and Does Not Tell You
A high-ranked job or candidate generally means the system estimates that result to be more relevant under its available signals, filters, data, and optimization objective than at least some of the alternatives it considered.
That is useful, but it is narrower than many people assume. A high match score does not automatically prove that:
the applicant satisfies every meaningful qualification;
the employer will respond or offer an interview;
the person will enjoy the role or workplace;
the employer offers good conditions;
the recommendation is free from bias;
the score represents a probability of being hired; or
the top-ranked vacancy is objectively the best opportunity available.
Real platforms show how these general ideas become product features. Lensa’s AI-assisted job matching, for example, provides a platform-specific case of AI-assisted job discovery and matching, while LinkedIn and Indeed document different combinations of preferences, profile information, search filters, behavioral signals, and ranked recommendations.
The safest way to use a match is as a search aid rather than a verdict. A ranking can reduce the number of possibilities you need to inspect, but broader job search strategies such as checking the employer, tailoring an application, reviewing requirements, and preparing for interviews still happen outside the matching score.
AI job matching is therefore most useful when its output is treated as an informed shortlist. The system can estimate relevance from the information it has, but the candidate and employer still provide context, verification, judgment, and decisions that a ranking cannot fully represent.
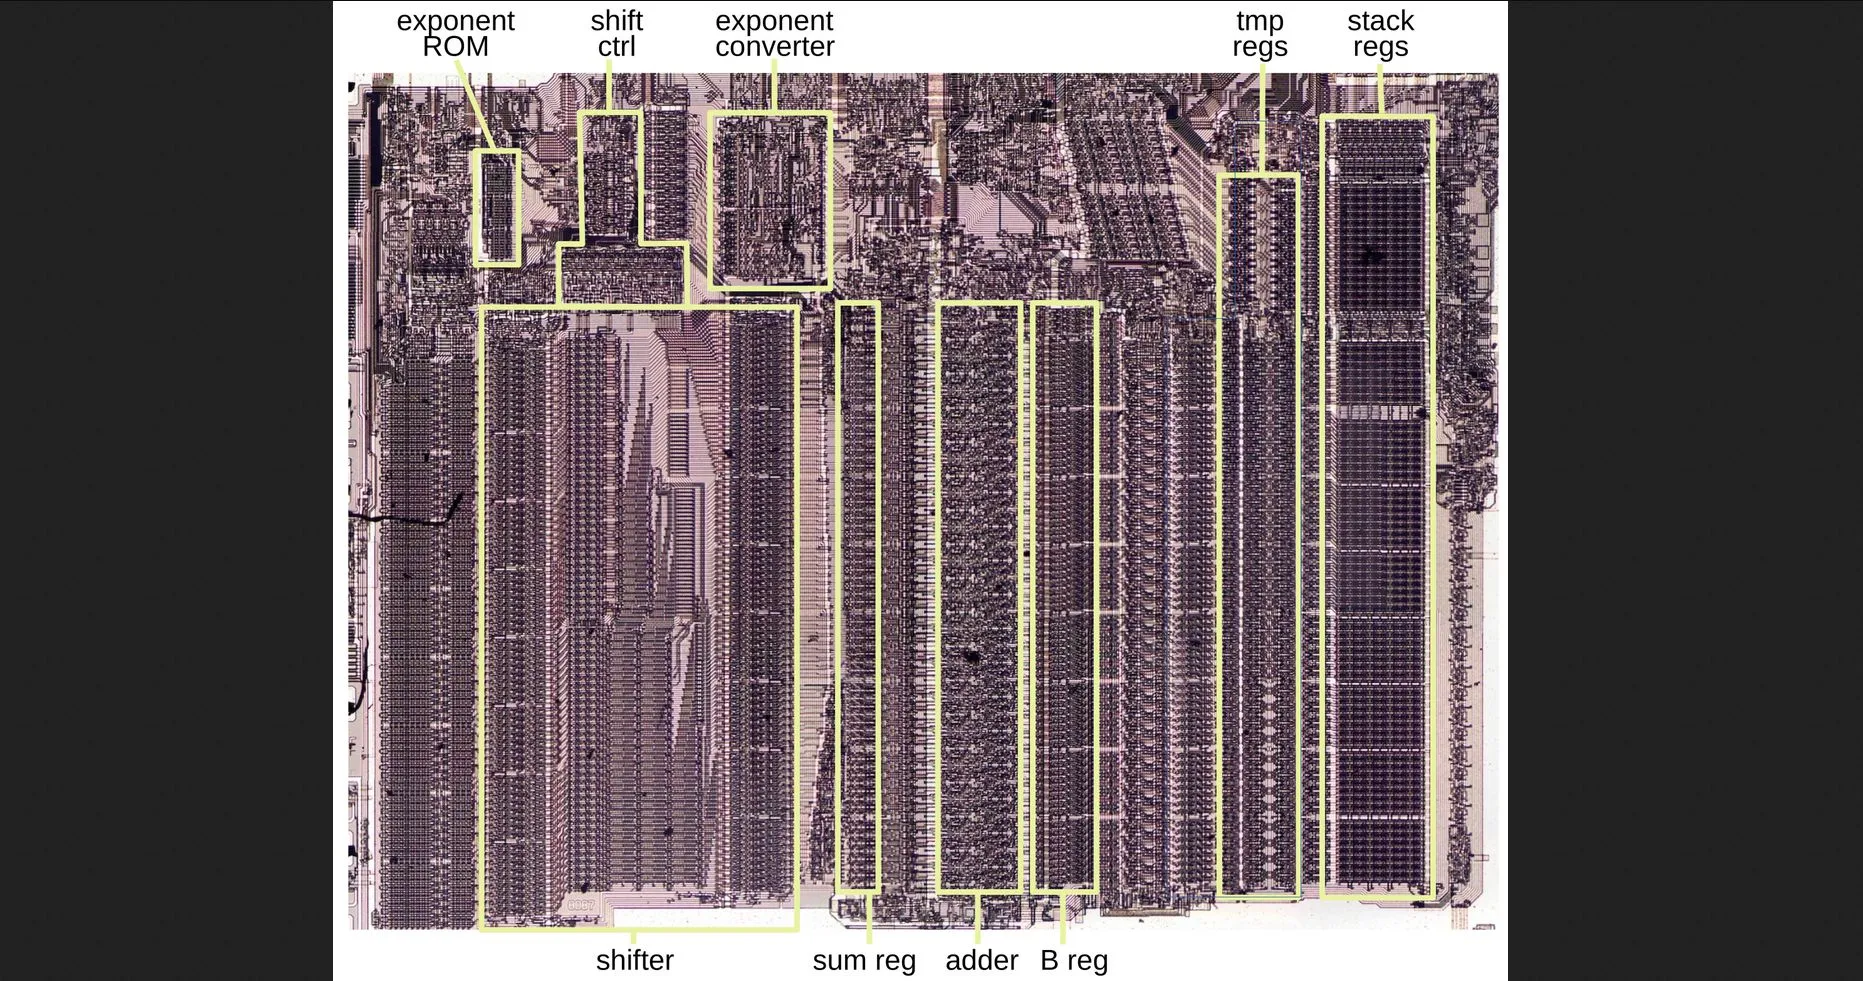
Continuing their reverse-engineering of Intel’s 8087 FPU, [Ken Shirriff] and friends took a look at one of the trigonometric functions, specifically FPTAN. The most exciting part with such reverse-engineering is probably figuring out which algorithm was used in the implementation, while trying to determine the reasoning behind the final hardware design.
If you’re running a simple MCU or MPU like the 6502 or Z80 without hardware functions you’d likely use an algorithm such as CORDIC or similar, as this requires only basic hardware features like addition, subtraction, bitshift, and look-up tables. One can also use polynomial approximation if there’s hardware support for a potential speed-up, or as is the case in the 8087, create a hybrid approach that targets speed and accuracy.
In the article the exact implementation to get to 64 bits of accuracy is detailed, starting with the 16 bits calculated using CORDIC before switching to the Padé approximant technique involving the ratio of two polynomials. Since after calculating the brunt of the final value with CORDIC the remainder is a fairly small value this polynomial approximation not just very accurate but also fast.
This approach allows the FPTAN and similar trigonometric functions in this FPU to hit a very high level of accuracy and not require the look-up table sizes and additional time required to work through the remaining bits with CORDIC. For those who want to see the full algorithm Intel’s engineers used, [Ken] has the full microcode listing with comments in the article as well.
Advertisement
As for the exact speed-up from this approach, [Ken] calculates for one value that FPTAN would spend 33% on CORDIC pseudo-division, 47% on CORDIC pseudo-multiplication and a mere 15% on the polynomial approximation along with about 5% overhead.
With the Pentium series of CPUs Intel moved completely away from CORDIC, as it’s clear that as accurate as it may be, it’s hard to scale to a significant number of bits without incurring significant time penalties. With the introduction of SIMD instructions the x87 ISA has further seen its functionality reduced, but this analysis shows once again why the 8087 made such an impact when it was released.
Good morning! Let’s play Connections, the NYT’s clever word game that challenges you to group answers in various categories. It can be tough, so read on if you need Connections hints.
What should you do once you’ve finished? Why, play some more word games of course. I’ve also got daily Strands hints and answers and Quordle hints and answers articles if you need help for those too, while Marc’s Wordle today page covers the original viral word game.
SPOILER WARNING: Information about NYT Connections today is below, so don’t read on if you don’t want to know the answers.
Advertisement
Latest Videos FromTechRadar
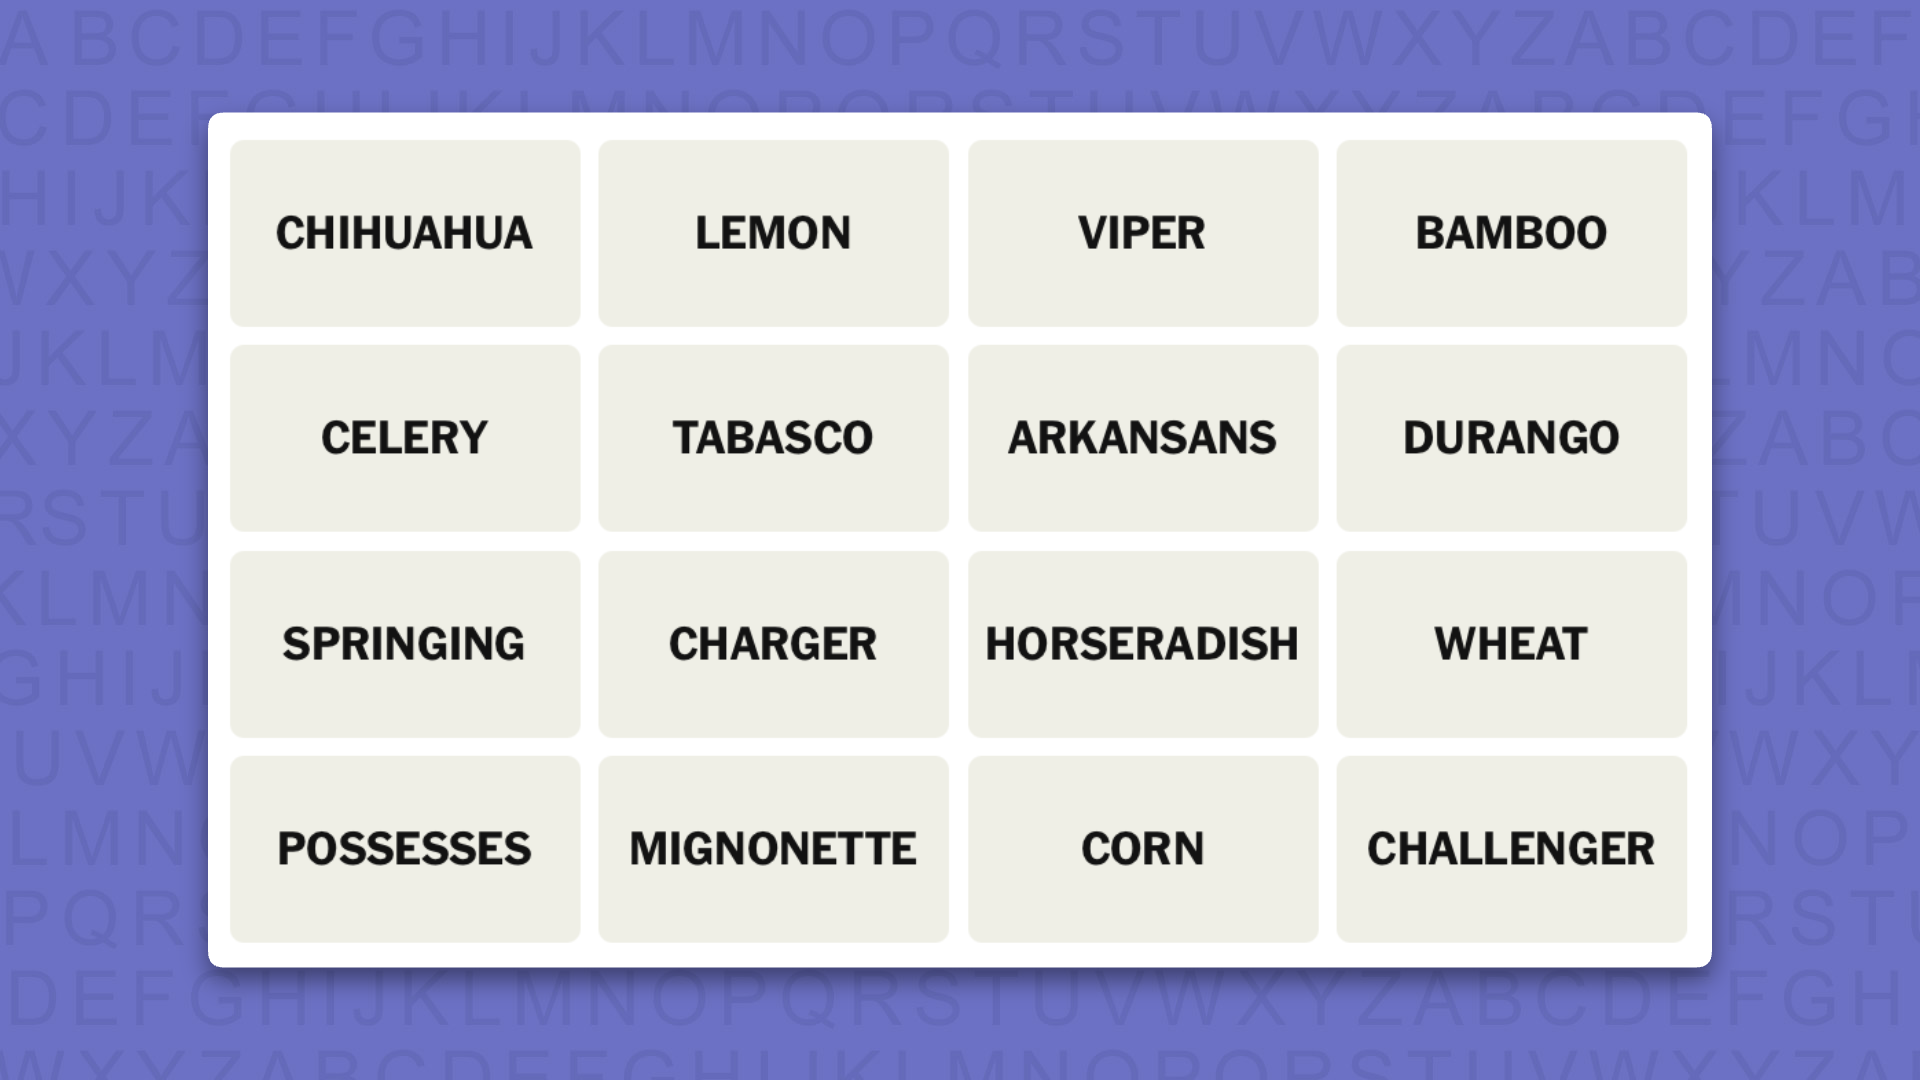
NYT Connections today (game #1205) – today’s words
(Image credit: New York Times)
Today’s NYT Connections words are…
CHIHUAHUA
LEMON
VIPER
BAMBOO
CELERY
TABASCO
ARKANSANS
DURANGO
SPRINGING
CHARGER
HORSERADISH
WHEAT
POSSESSES
MIGNONETTE
CORN
CHALLENGER
NYT Connections today (game #1205) – hint #1 – group hints
What are some clues for today’s NYT Connections groups?
Advertisement
YELLOW: Stick up plants
GREEN: Enhance your seafood with these
BLUE: Types of car
PURPLE: Triple trouble
Need more clues?
We’re firmly in spoiler territory now, but read on if you want to know what the four theme answers are for today’s NYT Connections puzzles…
Sign up for breaking news, reviews, opinion, top tech deals, and more.
NYT Connections today (game #1205) – hint #2 – group answers
What are the answers for today’s NYT Connections groups?
Advertisement
YELLOW: THINGS WITH STALKS
GREEN: OYSTER CONDIMENTS
BLUE: DODGE MODELS
PURPLE: THREE LETTERS PLUS REPEATED TRIGRAMS
Right, the answers are below, so DO NOT SCROLL ANY FURTHER IF YOU DON’T WANT TO SEE THEM.
NYT Connections today (game #1205) – the answers
(Image credit: New York Times)
The answers to today’s Connections, game #1205, are…
Advertisement
YELLOW: THINGS WITH STALKS: BAMBOO, CELERY, CORN, WHEAT
PURPLE: THREE LETTERS PLUS REPEATED TRIGRAMS: ARKANSANS, CHIHUAHUA, POSSESSES, SPRINGING
My rating: Hard
My score: 1 mistake
I have never actually had a Bloody Mary, but I managed to convince myself that CELERY, TABASCO, HORSERADISH and LEMON were all things that you would add to vodka and tomato juice.
Fortunately I soon corrected my error after thinking what CELERY might have in common with some of the other tiles.
The next two groups were put together on hunches — I had no idea about DODGE MODELS, but thought that CHALLENGER, CHARGER, DURANGO and VIPER all sounded like macho names for cars. Finally, I took a gamble that MIGNONETTE was a foodstuff (I now know it’s a type of vinegar) and lumped it in with the other OYSTER CONDIMENTS; I’m a purist myself.
Advertisement
Yesterday’s NYT Connections answers (Sunday, September 27, 2026, game #1204)
PURPLE: ENDING IN CHINESE DYNASTIES: BBQING, HOMING, LOHAN, WU-TANG
What is NYT Connections?
NYT Connections is one of several increasingly popular word games made by the New York Times. It challenges you to find groups of four items that share something in common, and each group has a different difficulty level: green is easy, yellow a little harder, blue often quite tough and purple usually very difficult.
On the plus side, you don’t technically need to solve the final one, as you’ll be able to answer that one by a process of elimination. What’s more, you can make up to four mistakes, which gives you a little bit of breathing room.
It’s a little more involved than something like Wordle, however, and there are plenty of opportunities for the game to trip you up with tricks. For instance, watch out for homophones and other word games that could disguise the answers.
It’s playable for free via the NYT Games site on desktop or mobile.
X-energy has completed the main structure of its Tennessee fuel plant called TX-1
The facility could eventually produce 700,000 TRISO fuel pebbles annually
TX-1 will be America’s first new commercial-scale advanced fuel facility in decades
X-energy has completed the main structure of TX-1, a nuclear fuel manufacturing facility located in Oak Ridge, Tennessee.
The 214,000-square-foot plant, developed by subsidiary TRISO-X, represents the first commercial-scale advanced nuclear fuel facility built domestically in over 50 years.
Clark Construction Group, the contractor handling the project, oversaw this vertical construction phase, clearing the path toward interior systems and eventual equipment installation.
Latest Videos FromTechRadar
Advertisement
Manufacturing capacity built for a growing fleet of reactors
TRISO fuel consists of tiny uranium particles wrapped in multiple carbon- and ceramic-based protective layers for durability.
Those layered coatings contain fission products while letting the fuel withstand temperatures far higher than conventional nuclear fuel typically tolerates.
The TX-1 plant is expected to produce roughly 700,000 TRISO fuel pebbles annually when it commences full operations, consuming about 5 metric tons of uranium, which would supply enough fuel for as many as 11 of X-energy’s Xe-100 advanced reactor units combined.
Each Xe-100 reactor module produces 80 megawatts of electricity, with four combined modules forming one standard 320-megawatt plant.
Sign up to the TechRadar Pro newsletter to get all the top news, opinion, features and guidance your business needs to succeed!
TX-1 will initially supply fuel for X-energy’s planned Xe-100 deployment at Dow’s UCC Seadrift Operations manufacturing site in Texas.
Advertisement
“Completing vertical construction is a major milestone for TX-1 and another tangible demonstration of the progress our team is making in Oak Ridge,” said Joel Duling, president of TRISO-X.
Clark Construction Group will now shift focus toward process equipment, an administration building, and an adjacent graphite matrix powder facility.
Earlier this year, the Nuclear Regulatory Commission granted the plant a 40-year Special Nuclear Material License for operations ahead.
Advertisement
X-energy says this represents the first NRC Category 2 fuel fabrication license issued for processing high-assay low-enriched uranium, known as HALEU.
Expanding beyond one site as demand for advanced fuel grows
TRISO-X has separately expanded its broader Oak Ridge nuclear fuel campus by approximately 70 additional acres of land.
The company also extended its existing research partnership with Oak Ridge National Laboratory while beginning construction on a separate facility.
Advertisement
That new facility, called TX-L, will function as a dedicated research and development site going forward.
Beyond the Dow project, X-energy is pursuing additional Xe-100 deployments with Energy Northwest, Amazon, and Centrica as future customers.
Each new reactor project would add further demand for the specialized fuel TX-1 is being built to eventually produce.
Finishing the building’s main structure does not mean fuel manufacturing can begin immediately at this location.
Advertisement
X-energy must still install specialized production equipment, commission interior systems, and prepare the facility for full commercial operations ahead.
No completion date has been disclosed for TX-1, but when completed, it would give the United States its first new domestic source of advanced reactor fuel in decades.
That outcome would also reduce reliance on foreign uranium suppliers while supporting new clean energy projects already planned with Amazon, Energy Northwest, and Centrica.
111 years ago, American automaker Packard unveiled a new model called the Twin Six. At the time, they were in a heated back-and-forth battle with Cadillac, each marque vying for the number-one spot as America’s premier luxury automaker. Cadillac was riding the high of its first V8, but with the Twin Six, Packard introduced the world to the first production V12.
Since its inception with Packard, the V12 has been lauded as the ultimate form of the combustion engine. Huge power output can be extracted from its high cylinder count; its firing order is inherently balanced, resulting in smooth power delivery and stability in the engine bay; and it’s known for its vocal cords, too. In short, the V12 is perfectly suited to both performance and luxury applications. This grants the V12 a prestige and reputation that is unmatched by any other engine—they’re only found in the world’s finest cars.
The V12 is the statement piece of any automaker’s portfolio, so when you build one, it better be good. Because the V12 holds so much gravity, no holds are barred during its development, and usually, the result is something spectacular. The silky smoothness of a Rolls-Royce V12, or the rabid screams of a Lamborghini V12, are equally distinct, yet successful takes on the engine layout that both perfectly embody their brands’ ethos. However, not every instance is a success story. Here are two of the worst V12 engines ever made, and two of the best.
Advertisement
Worst: Jaguar 5.3L V12
Heritage Images/Getty Images
Today, the Jaguar E-Type is regarded as one of the world’s finest sports cars. Even during its production, the world and Jaguar knew that the E-Type was something special, so when it came time to make a replacement, Jaguar knew they had a near-insurmountable task on their hands. That replacement came in the form of the Jaguar XJ-S, a stately coupe with modernized looks, a relatively cheap price tag, and a 5.3-liter V12. At first, this seemed like a perfectly acceptable successor. A 285 horsepower V12 with a Jaguar badge for just $19,200 felt like a steal, but the truth soon reared its ugly head.
The XJ-S’s V12 was obscenely complex, especially the electronics. One particular problem area was the Marelli ignition system, which functioned as two separate six-cylinder ignitor layouts rather than a holistic 12-cylinder version. The issue was that one half could shut down, leaving unlit fuel in the banks that the working half could ignite at any moment, leading to engine fires. U.S. spec models also had the catalytic converters mounted too close to the exhaust manifolds, which could lead to engine fires.
Advertisement
Beyond the fire problems, a Road & Track owner’s survey also reported issues with the brakes, alternator, cooling system, fuel pumps, instruments, and more. These engines required constant, expensive maintenance to prevent catastrophic damage, making this V12 a stain on Jaguar’s legacy and adding to their reputation for poor reliability.
Advertisement
Worst: Lincoln Zephyr V12
Paul Brady Photography/Shutterstock
Despite entering the market at the tail end of the Great Depression, Lincoln decided to introduce its new V12-powered car, the Zephyr, in 1936. Regardless of the V12’s status as a range-topping engine, the Zephyr was meant to help Lincoln expand their market and move away from the low-volume, coachbuilding model it had followed up until this point. From the outside, the Zephyr is a wonderful thing to look at. Although the looks were polarizing at the time, its streamlined lines and teardrop proportions gave it an undeniable Art Deco panache.
Under the hood, though, the engine couldn’t match the exterior’s confidence. The Zephyr’s V12 had many similarities to Ford’s flathead V8, including its L-head valvetrain layout and twin-water-pump cooling system, but it failed to match Ford’s reliability. Almost all of the issues were caused by, or stemmed from, overheating. Thin cylinder walls that poorly withheld combustion heat, along with an underpowered crankcase ventilation system, made these engines run extremely hot. The water-cooling pathways were too small, further exacerbating heat buildup, which cooked the engine oil into sludge that could damage the engine and sap power. Even in a well-functioning example, the small bore and displacement meant these engines produced only 110 horsepower, which, even for the day, was underwhelming for a V12.
The car was a perfect example of 20th-century American elegance, but its underwhelming, problematic engine held it back, and it faded into obscurity as one of the forgotten cars of the 1930s.
Advertisement
Best: Ferrari F140
yousang/Shutterstock
The V12 engine is steeped in the very essence of the Ferrari brand. Since the beginning of the prancing horse, the V12 has been the continuous masterpiece of Maranello, constantly evolving and improving. Each iteration improves upon the last, so it’s no surprise that its most recent version is the best the world has ever seen. Developed in 2002 for Ferrari’s fourth ultimate supercar, the Enzo, the 6-liter V12 was dubbed F140. The engine was pure Formula One, utilizing a 65-degree bank angle that allowed for a larger bore, more space for the intake manifolds, and a shorter engine height, resulting in a lower center of gravity and a compact package. In the Enzo, this naturally aspirated V12 produced 651 horsepower and an operatic shriek.
The F140’s involvement in the Enzo project alone makes it legendary, but that’s just the beginning. Ferrari upped displacement to 6.3 liters, and tossed the F140 in the F12. Later, in the Enzo’s successor, they bumped the power up to 800 horsepower and added an electric motor and a KERS system, introducing the LaFerrari as the brand’s first hybrid. Then, Ferrari updated the engine again for the 812, increasing displacement to 6.5 liters and boosting power to 819 horsepower. This most recent version powers all 812 variants, the Daytona SP3 and other Icona series cars, and the Purosangue, Ferrari’s first SUV. The F140 is the mascot of Italian, high-performance V12s, and it’s been blessing the hearts and ears of Ferrari fans since 2002.
Advertisement
Best: Mercedes M120
Agitator/Shutterstock
The M120 was developed with similar vigor as the F140, but its goal was different from the beginning. In the late 1980s, Mercedes was due for a new S-Class. An S-Class has to be solid and silky, and that includes the engine; it has to be solid and effortless. This quest for a smooth and stable powerplant gave rise to the M120 V12, and Mercedes brought out all the stops in its development. The engineers wanted power but opted for a naturally aspirated configuration over forced induction, as they felt the linear power delivery of an NA engine was better suited to the S-Class’s task.
Mercedes wanted nothing to come in the way of the M120’s longevity, and meticulously engineered and tested each component until they could comfortably withstand more stress than would ever be placed on them in regular use. Its cooling and oil circulatory systems were simple and robust, as was the rest of the engine. Its 390 horsepower was doled out smoothly and predictably, with torque available across the rev range. In the S-Class, the M120 was like a Navy SEAL playing paintball. It was so capable that you never had to worry about it, and its performance potential was quickly realized, too. Mercedes used an AMG-tuned version of the M120 in the fabled CLK-GTR, as did Pagani in the Zonda. The M120 was solid as a bank vault door, and it conquered both the luxury and performance arenas of V12 greatness.
Advertisement
Methodology
Heritage Images/Getty Images
The V12 engine family is known for excelling as a powerplant for both luxury and performance cars. In luxury applications, their inherent balance between cylinder banks and firing orders lends itself well to smooth running and stability in the engine bay even at high revs. Their high cylinder count means combustion overlaps almost constantly, making the powerband linear and acceleration predictable and easy to control.
As for performance applications, this linear powerband is also beneficial, eliminating power jumps or drops that could disrupt a driver’s instincts. Their high cylinder count and displacement mean their horsepower ceiling is very high as well, without the need for forced induction.
Engines on this list were chosen based on their adherence or lack thereof to these characteristics. Engines that exemplify the benefits and exceed the expectations of a V12’s capabilities were chosen as the best, while engines that fell short of said capabilities and expectations were chosen as the worst. Beyond V12-specific criteria, engines were also ranked based on general metrics like reliability and maintenance needs.
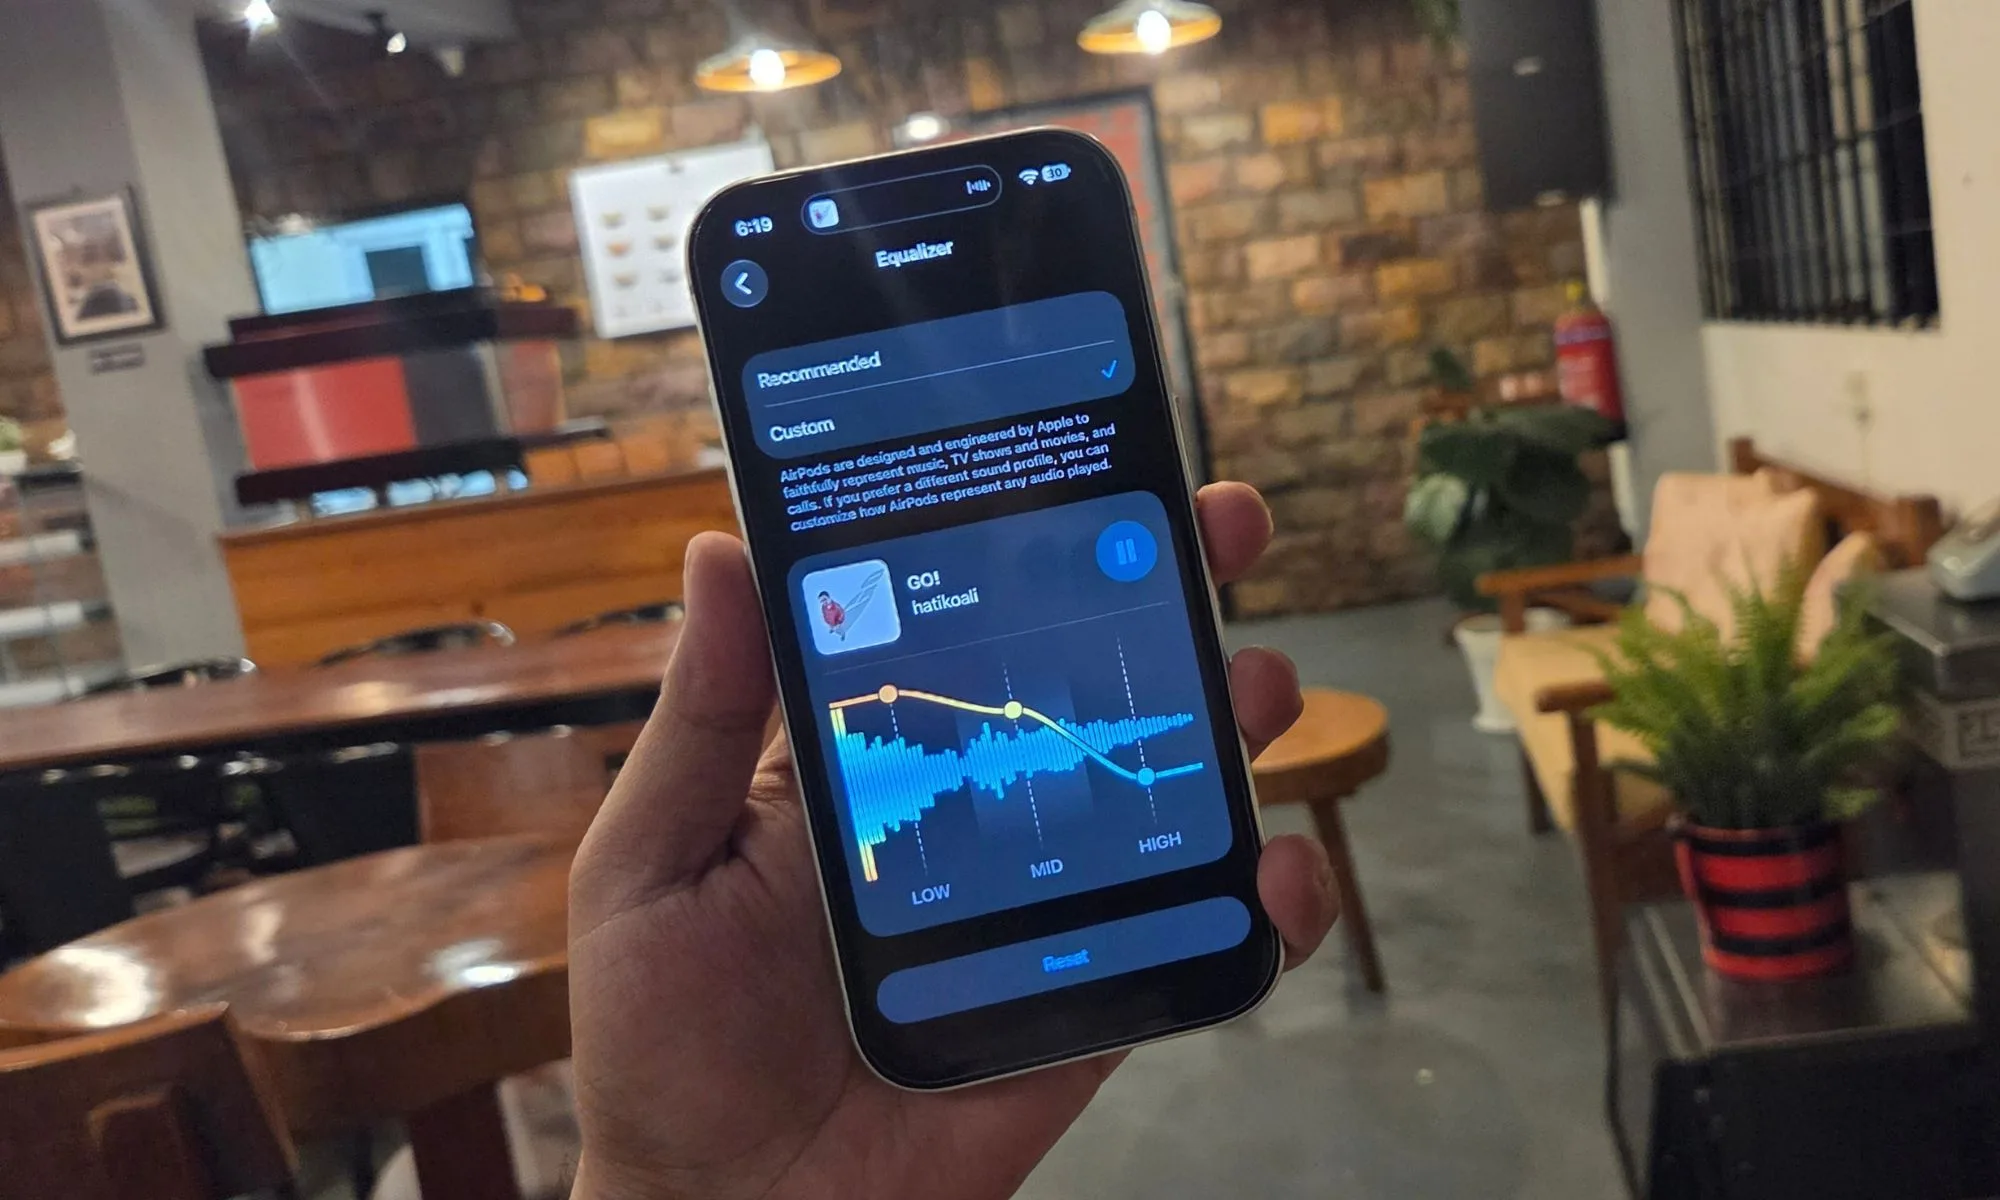
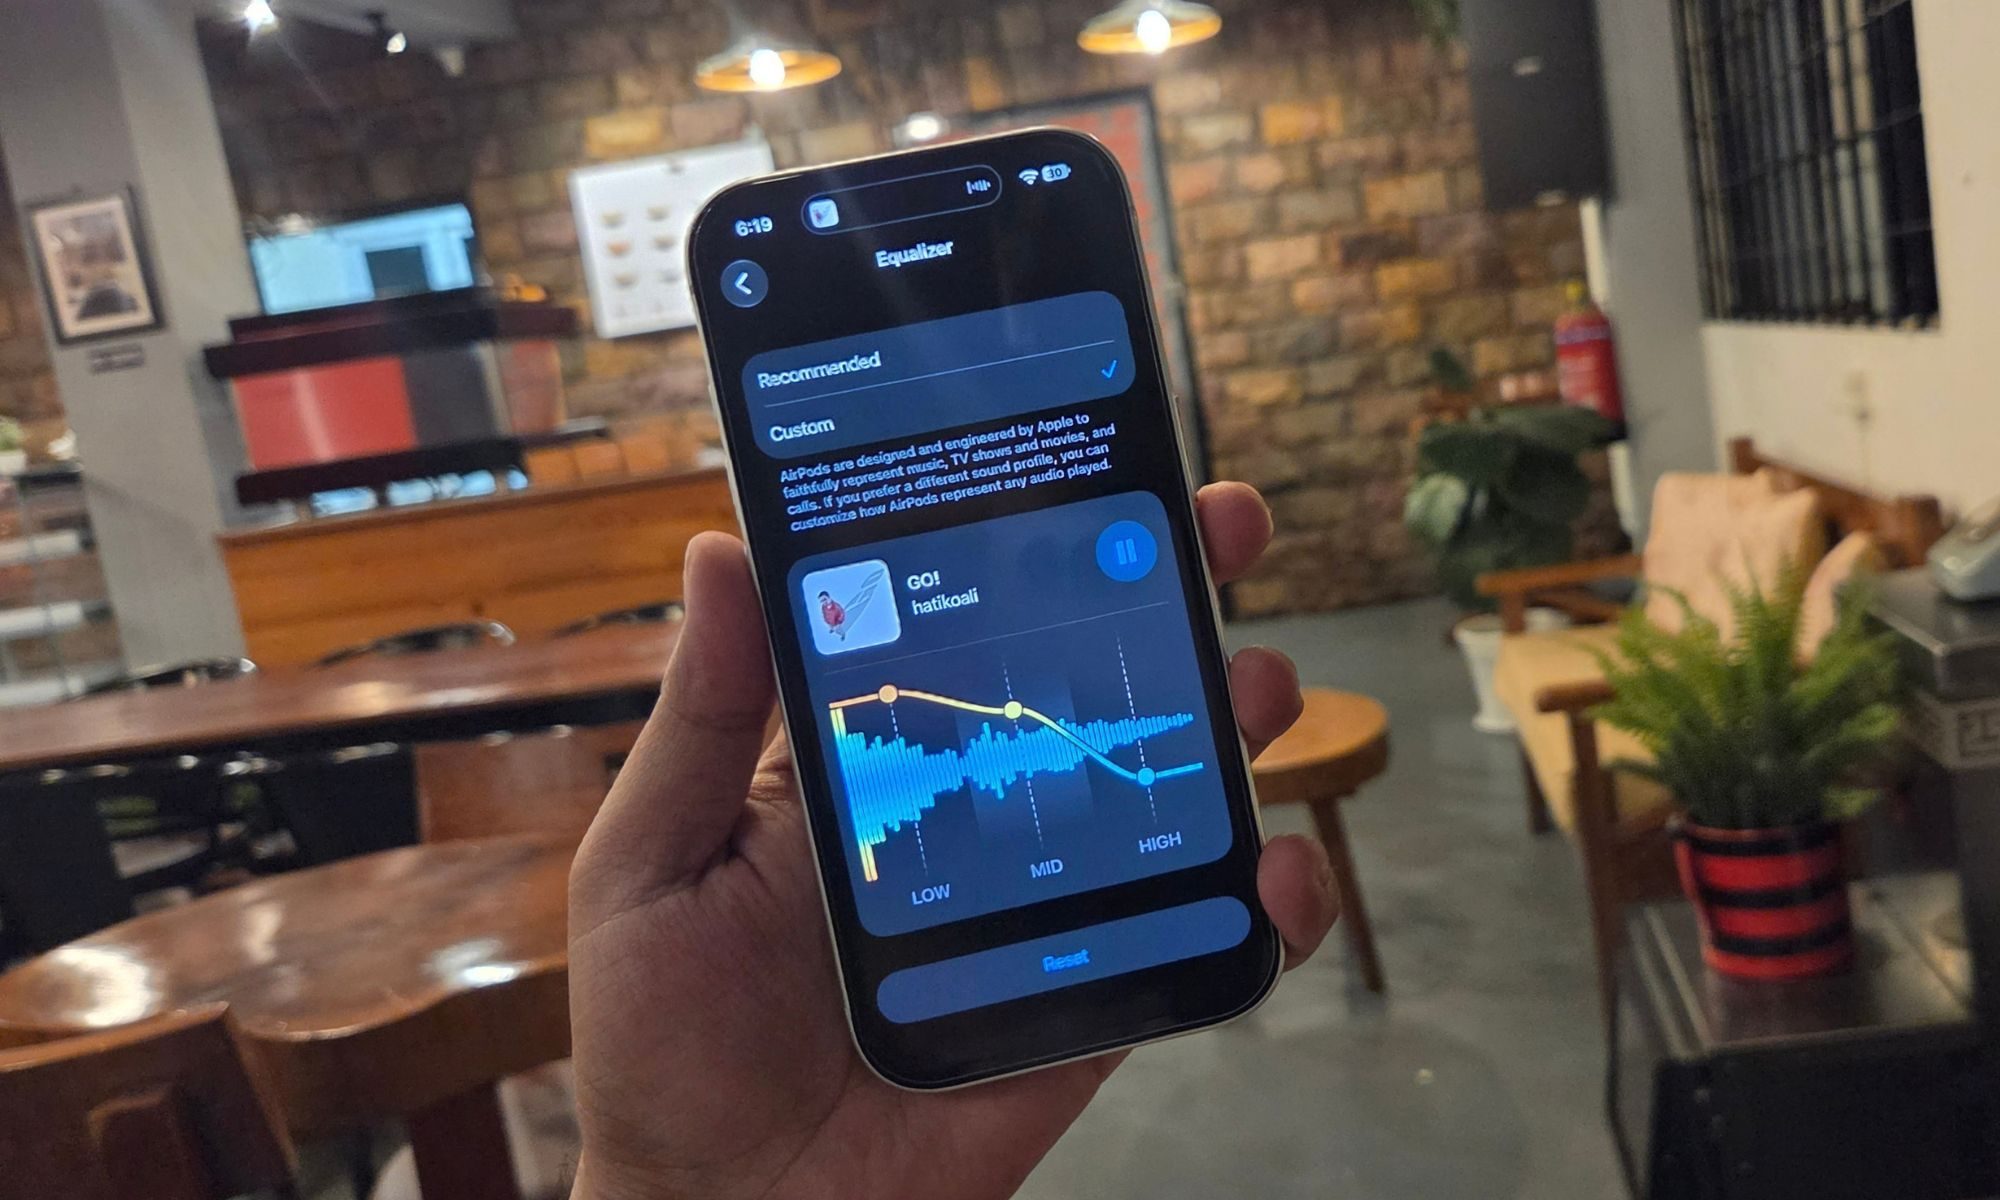
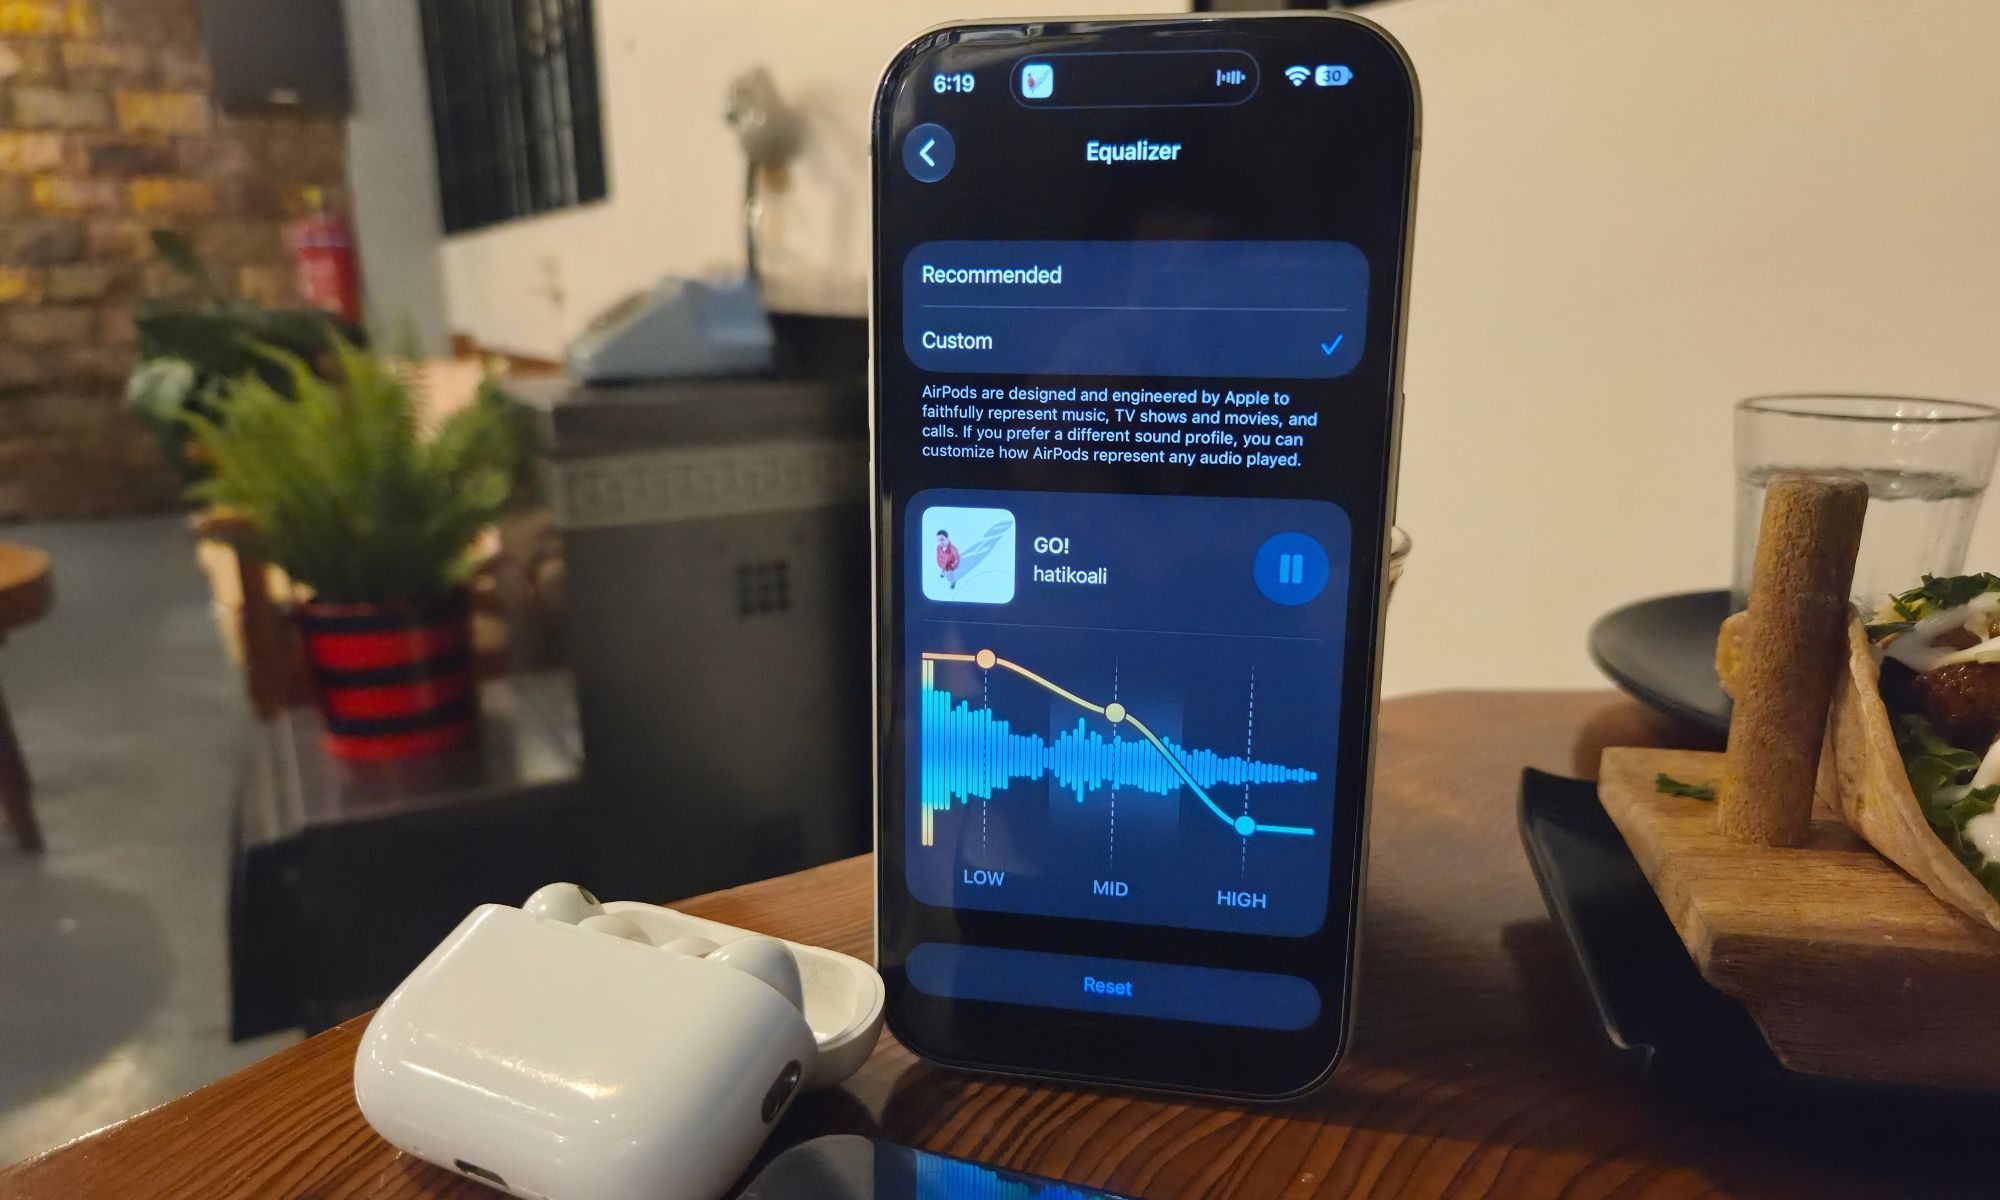
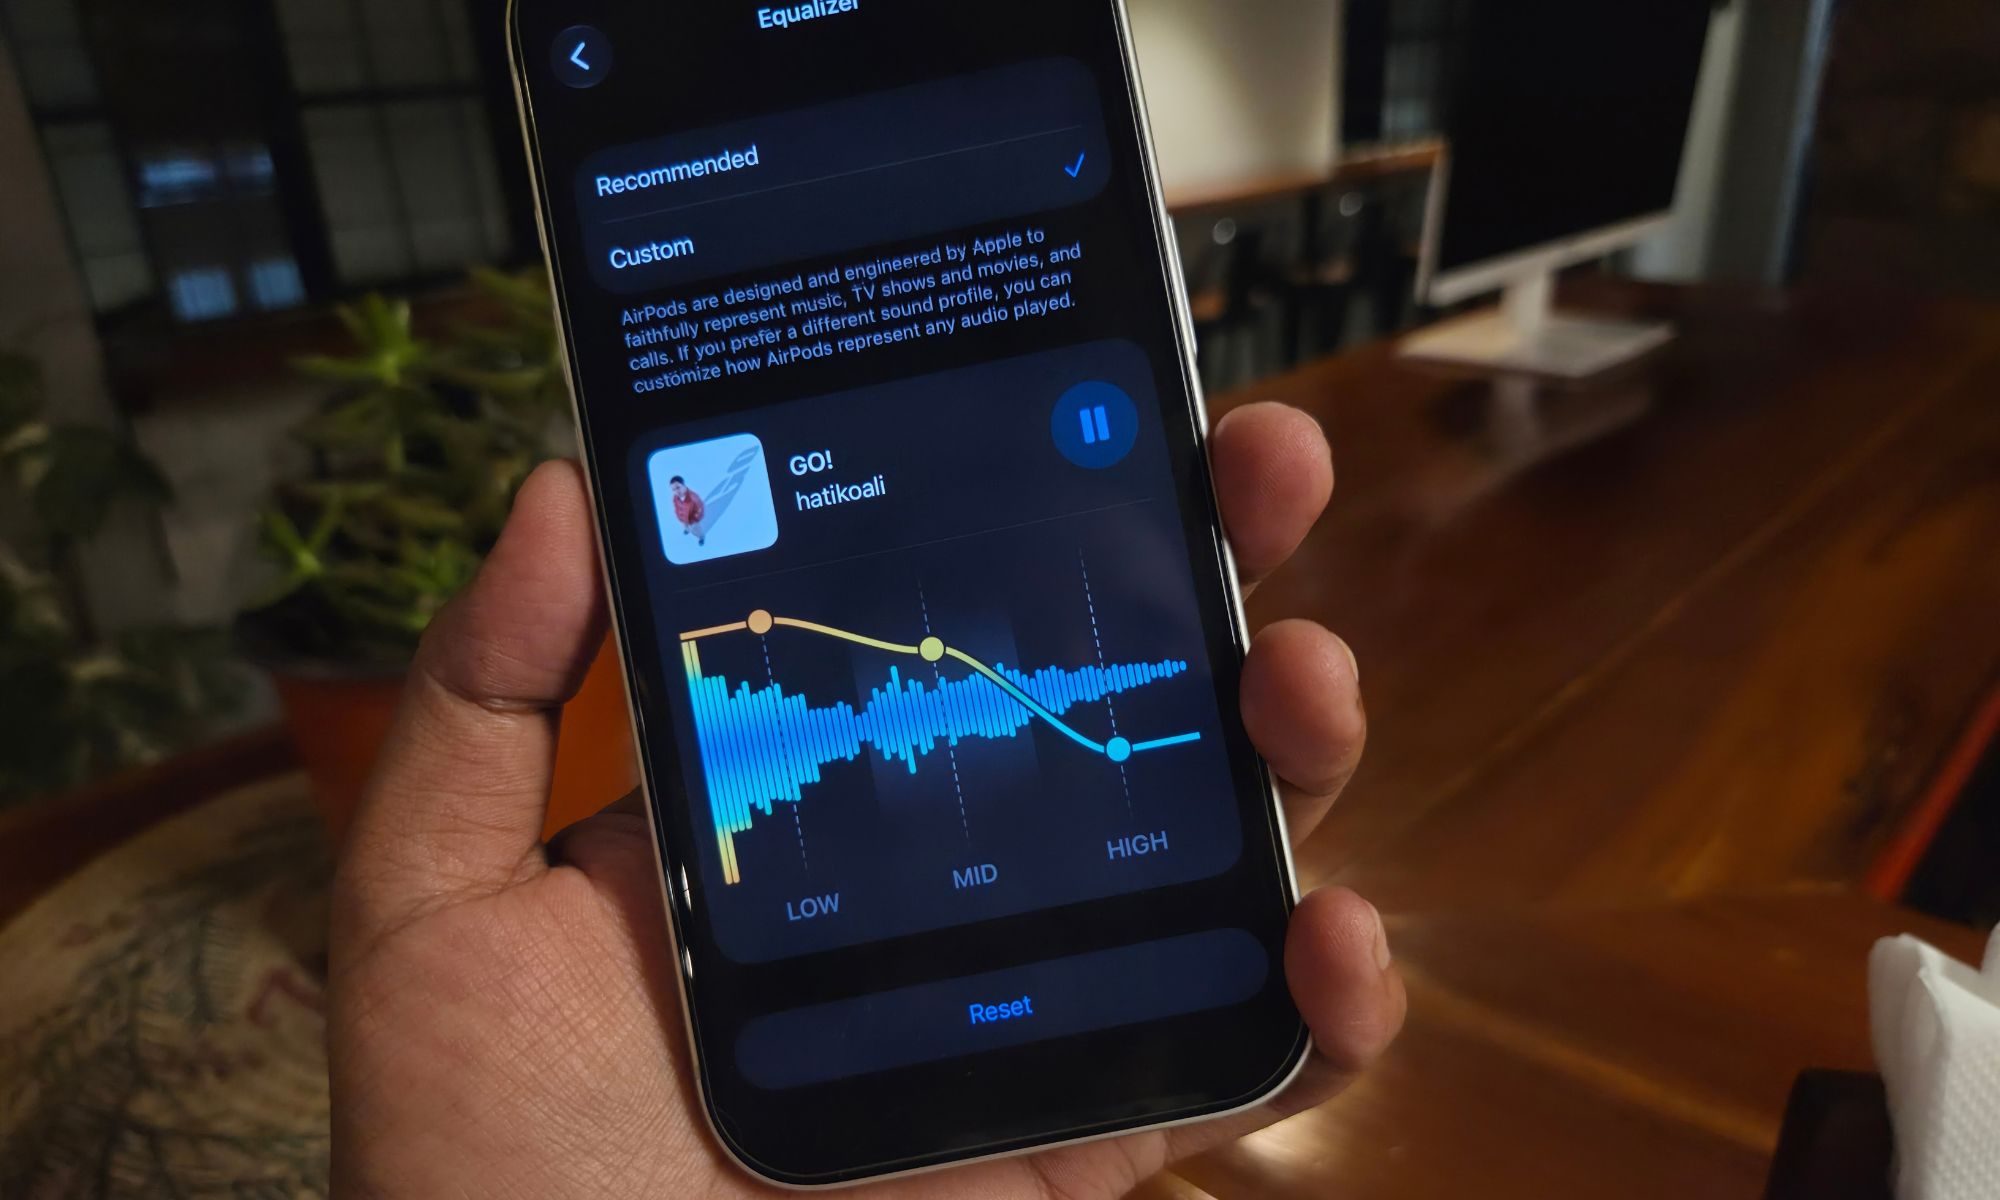
I just adjusted the frequency response to my favorite Kazakh Hip-Hop track, and my AirPods Pro obliged, blasting soul-pleasing bass beats in my ear canals. In hindsight, I think this is how “Go” by Hatiko Ali was always meant to be listened to. Wading into an entirely different world, I slightly raised the mids and found myself lost in the melodious voice of Shafqat Amanat Ali.
Just over a week ago, that wouldn’t have been possible. But thanks to iOS 27, and the latest AirPods firmware, Apple has finally added a custom tri-band EQ to give users a flexibility that they’ve been asking for years. It’s not as fleshed out as what you get with the likes of Sony, but the difference is easily noticeable, and utterly satisfying.
So, what’s the big deal?
Nadeem Sarwar / Digital Trends
It won’t be an overstatement to say that Apple put true wireless earbuds into the mainstream. It’s next to impossible to walk in a buzzy place, a workspace, or even on public transport, and not see a few skulls rocking the distinctly white earbuds sold by Apple. And for good reason. They pair seamlessly, offer a bunch of cool features such as Find My tracking, and deliver fantastic noise isolation.
Of course, they sound pretty good. Apple, however, has also been pretty stubborn in the sound department, preventing audiophiles from customizing how the AirPods sound. For years, Apple has maintained that the AirPods have been tuned by experts and that they sound just fine out of the box. Apple never served a custom EQ (aka equalizer) for its earbuds, something nearly every other major audio brand offers.
With the release of iOS 27, Apple has finally made a course correction. So far, you could only pick between three presets in the name of customization: Balanced Tone, Vocal Range, and Brightness. Annoyingly, these settings were buried under Headphone Accommodations. That’s not a name where I would ever go looking to tweak the audio profile of my AirPods. And yeah, it wasn’t enough.
Advertisement
Does it make a difference though?
Absolutely.
Look, I won’t mince words here. Everyone has a different taste in music, and even when it comes to the same band — or even a track — what you like in a particular song is going to be different from the next person. Likewise, given the flexibility, you might occasionally want to enhance a certain element of a track, like the vocals raised and the background instruments suppressed, in a song.
Nadeem Sarwar / Digital Trends
I know. I know. Music purists are going to balk at the idea. They would say you should listen to a song the way it was intended to be listened to. Or, to put it more accurately, listen to it the way a music artist is serving it. Simply put, just enjoy it in its pristine state. I disagree with that notion. You should listen to a song in the unique flavor that pleases your senses. There’s a reason lo-fi and slowed-reverb tracks are all the rage. Apple’s tri-band EQ finally gives you that freedom.
While listening to Nine Inch Nails’ “As Alive As You Need Me To Be” from the “Tron: Ares” soundtrack, I always felt it was a tad chaotic. I wanted to hear the rock ferocity of Reznor’s voice on this track, without it being suppressed by the background instruments. Well, on the EQ page, I pulled down the high-band while raising the mid and low band output. That changed the entire song’s vibe.
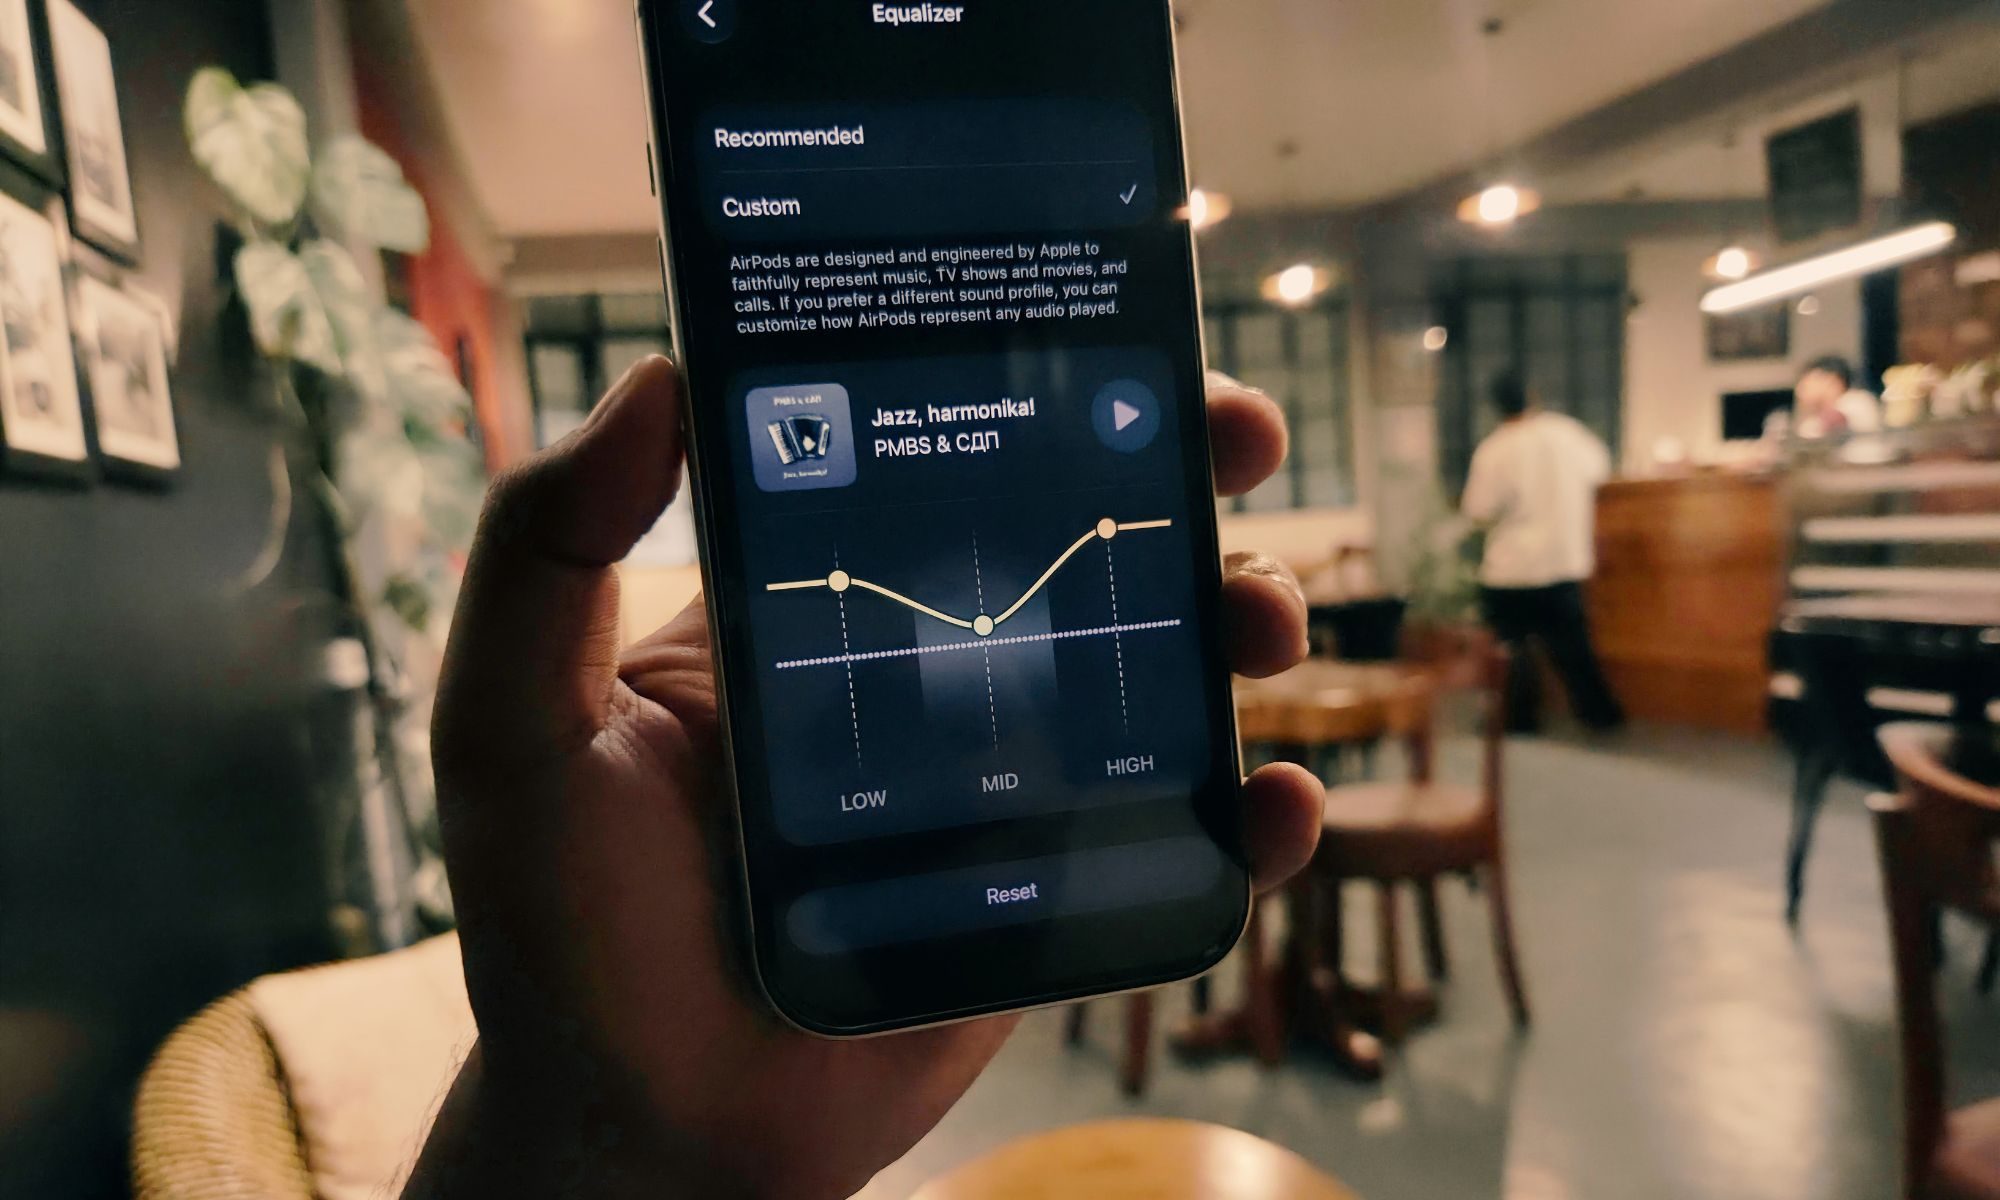
The distinct mechanical grit in Reznor’s voice became more obvious, with all its visceral aggression and layered vocal texture — all against a more pronounced bass chorus. Moving over to “A Drowning” by How to Destroy Angels, an inverted V-shaped EQ graph (bring down the low and high bands, enhance the mids) is the best way to enjoy Mariqueen Maandig’s vocals in all their controlled elegance and chilling precision against the dark backdrop.
But how?
Nadeem Sarwar / Digital Trends
Well, as mentioned above, make sure your iPhone is running the latest iOS 27 build, and you have the updated firmware installed on any of the AirPods models listed below:
Next, pair the AirPods to your iPhone and follow this path:
Advertisement
Settings > (Name of your AirPods) > Audio & Routing > Equalizer > Custom.
Thankfully, the EQ changes you make on your iPhone will also reflect when the AirPods are connected to your iPad or Mac. “Custom EQ settings are stored on your AirPods and carry over to any other paired devices,” explains Apple.
Nadeem Sarwar / Digital Trends
As mentioned above, you don’t necessarily have to go down the path. The AirPods (especially the Pro and Max) are tuned pretty well, and if you just want to enjoy music without losing brain cells over mids, lows, and highs, stick with the pre-applied “Recommended” profile. But if you ever wondered what a track would sound like if certain melodious or instrumental elements were adjusted, head over to the EQ page and play around. Trust me, it’s a rewarding exercise.
In JD Power’s 2026 U.S. Tech Experience Index (TXI) Study, the company took a closer look at the smart technology in new vehicles — the technology that “makes everyday driving easier without demanding the driver’s attention”, like a big infotainment screen. When it comes to smart technology innovation, Hyundai has ranked the highest for mass-market car brands seven years in a row — and the tied runner-ups, GMC and Kia, are not very close. Its three-row mid-size SUV, the Palisade, received JD Power’s mass-market Advanced Technology Award in the Driver Assist category specifically for its blind-spot camera.
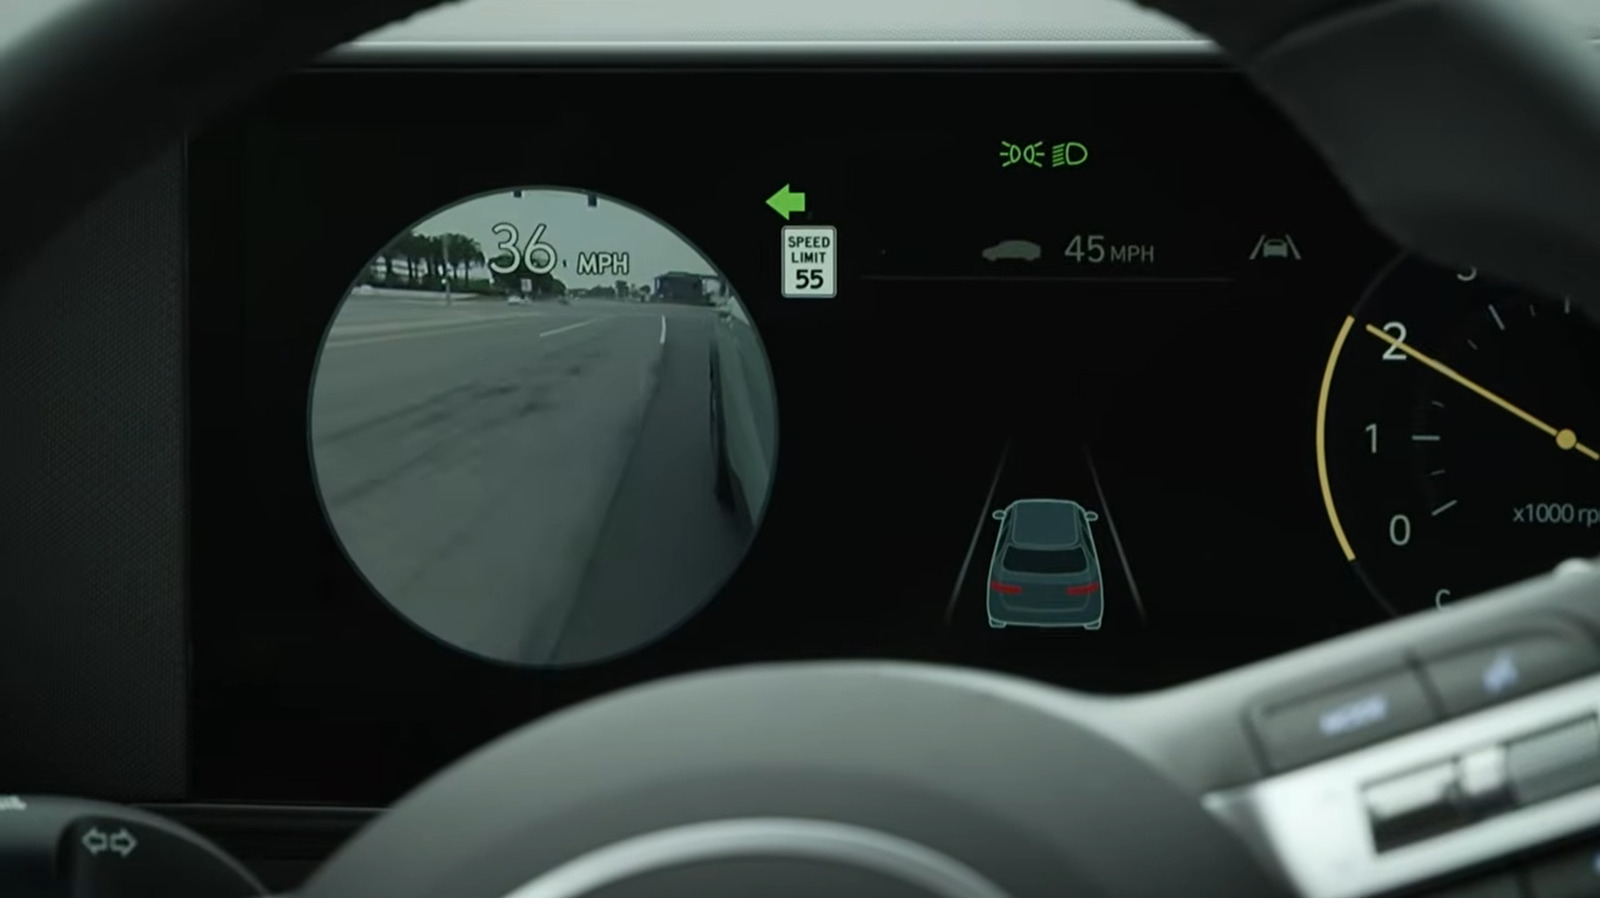
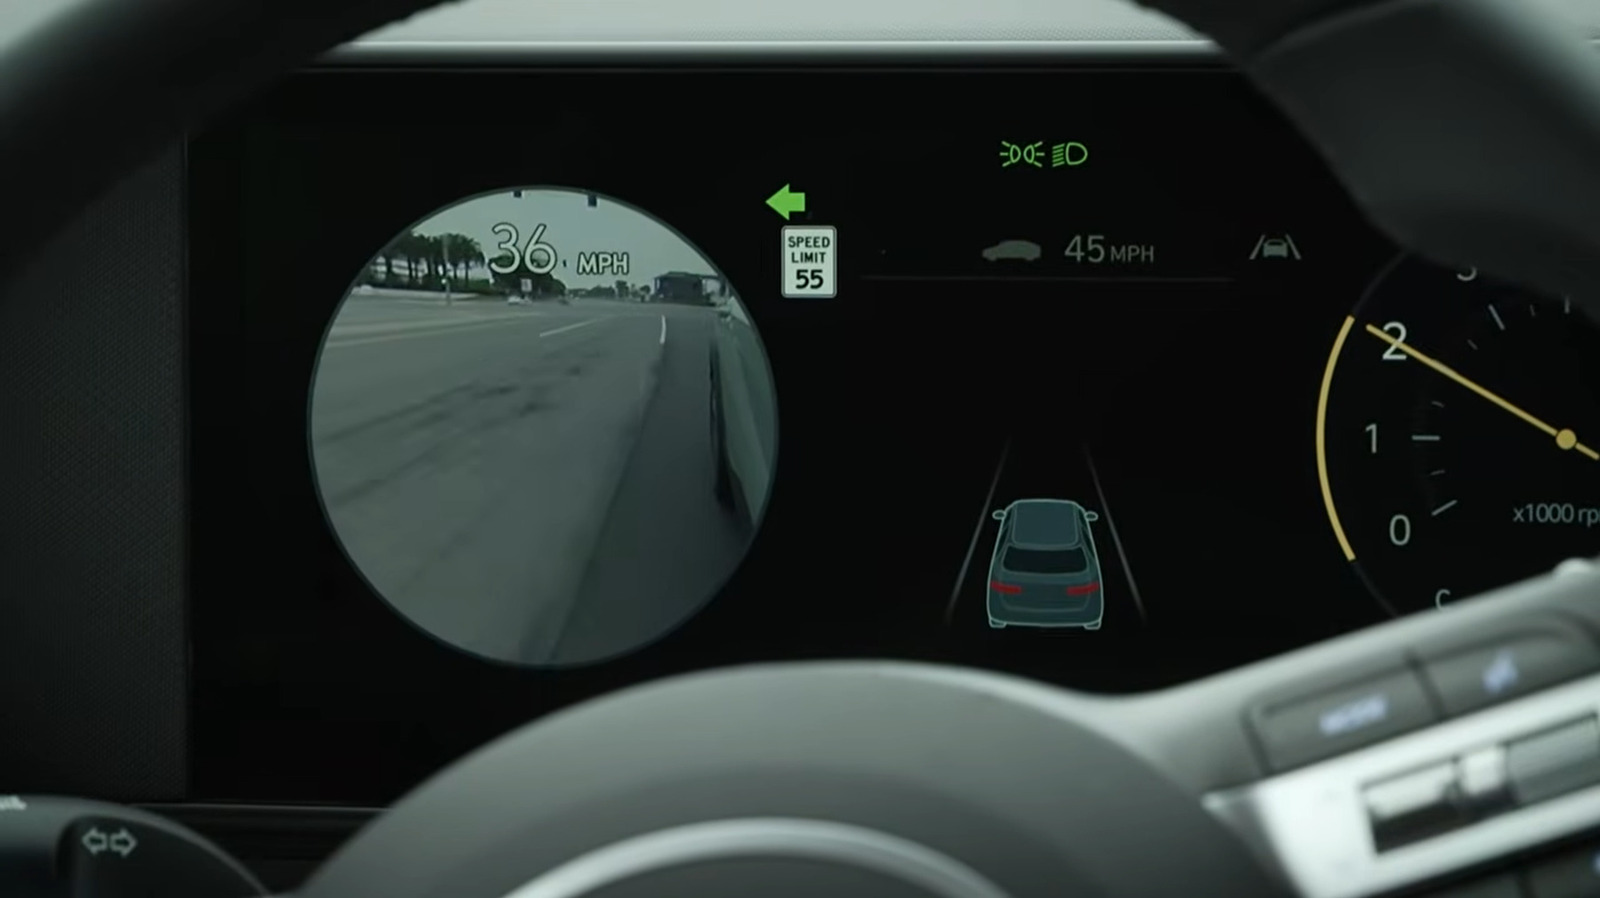
Most vehicles have blind-spot monitoring these days, but the Palisade displays a live camera feed of your blind spots right in the vehicle’s digital instrument cluster every time you use a turn signal. The Blind-Spot View Monitor (BVM) has a camera feed for both the left and right turn signals. Once the turn signal is shut off, the images will disappear from the display.
Advertisement
Depending on the trim, the Hyundai Palisade also comes with the automaker’s SmartSense, its safety-focused technology suite. This includes Highway Driving Assist, which keeps you at a safe distance and speed from other vehicles on the highway. Lane Keeping Assist can guide you along your chosen lane. It also has Forward Collision-Avoidance Assist 2, which applies the brakes after warning you of a potential collision with another car or pedestrian. Similarly, Blind Spot Collision-Avoidance Assist will warn you of possible dangers while merging lanes, and Reverse Parking Collision-Avoidance Assist ensures that everything is clear while you back into a parking spot.
Advertisement
What are the key findings of JD Power’s 2026 TXI study?
When it comes to technology, JD Power’s 2026 U.S. TXI Study revealed that drivers prefer smart technology features to passenger screens and more complex features, like hands-free driving. When it comes to the passenger screen, 35% of surveyed drivers have never used it, with most saying it’s one of the more problematic features in vehicles with an abundance of screens and technology. There’s a reason automakers are starting to back away from screen-focused cabins.
Level 2 driving assistance programs, which still require drivers to pay attention to the road, are preferred to Level 2+ systems, which let you take your hands off the wheel. According to Doron Hikry, JD Power’s Director of Customer Success, this could be due to drivers being less comfortable with more automation (which can also be seen with self-driving robotaxis).
Instead, the study found that drivers prefer smart tech that stays in the background, providing more comfort and fewer problems. One of the highest-ranked smart tech features was smart ignition, which turns the car on and off without a key in the ignition. “The technology customers value most is often the technology they barely notice because it simply works,” said Hikry.
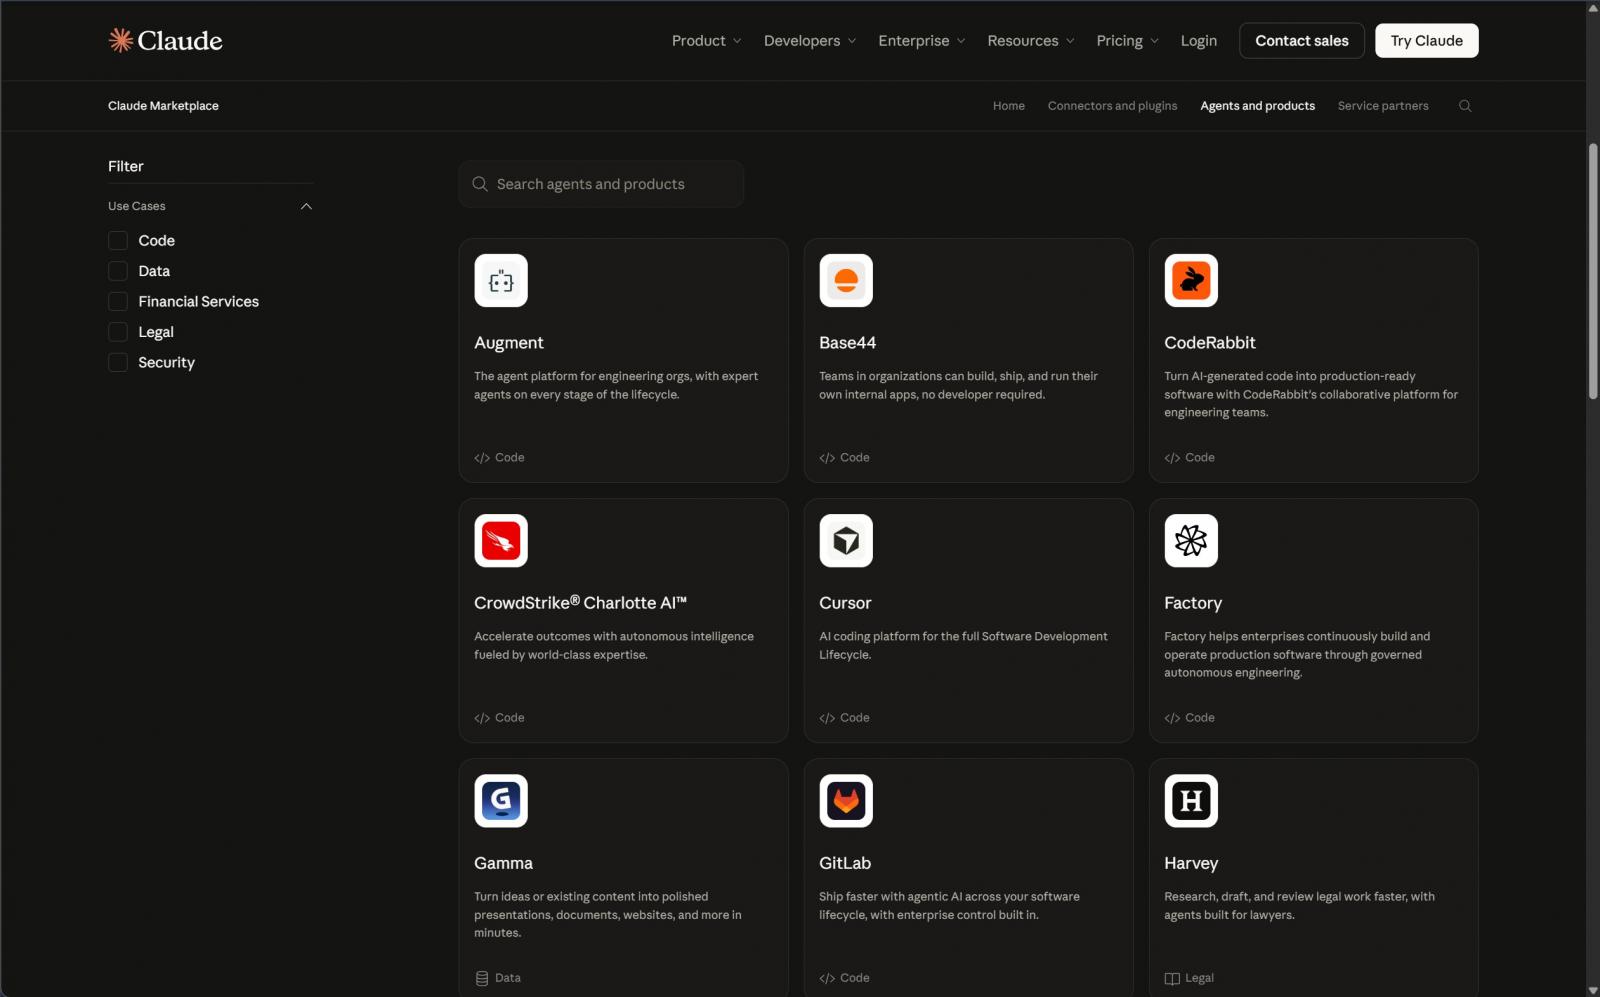
Anthropic has just announced a new Claude Marketplace, and it brings all AI-related tools into one place, including plugins, connectors, agents, and more.
Claude’s marketplace is already public, and Anthropic says it’s already offering more than 2,000 connectors and plugins.
These plugins or connectors are available from companies like Atlassian, Google, Microsoft, Notion, Salesforce, and others, so it’s not just Anthropic filling up the marketplace.
Anthropic is also allowing companies to buy Claude-powered agents and products from partners such as CrowdStrike, Cursor, Harvey, Legora, Lovable, and Snowflake.
Advertisement
In a blog post, Anthropic noted that Claude Marketplace also includes consulting and systems integration partners.
This includes Accenture, Boston Consulting Group, and Deloitte, for companies that want help deploying Claude across their organization.
Claude has always allowed users to connect more of the apps they already use, but having a marketplace similar to the Play Store allows you to go beyond basic integrations.
Anthropic also wants developers to build for Claude
Having Microsoft or Google’s support alone may not be enough for the marketplace to succeed, and we have seen similar problems when OpenAI launched an apps marketplace. It didn’t work out, and Anthropic wants to avoid that mistake by allowing anybody to publish their products.
Advertisement
If you’re a developer, you can create connectors and plugins using Model Context Protocol (MCP) and Agent Skills, while companies selling Claude-powered software can apply to have their products listed.
Anthropic says the goal is to make it easier for teams to discover products that already work with Claude, while giving developers and partners a direct way to reach existing Claude customers.
In a way, Anthropic is building a Google Play Store for AI-related features, but only time will tell if it works out.
Join Mikko Hyppönen and security leaders from the NFL, CHANEL, and Atlassian for a two-hour digital summit on what AI-speed attacks change, what defenders should stop doing, and how to validate, decide, fix, and re-validate at machine speed.
When people study World War II and the overall conflict, it’s not uncommon to focus one’s attention on tanks, airplanes, and massive ships like the Essex-class aircraft carriers used by the United States Navy. It’s easy to focus on these impressive pieces of military machinery and the people who operated them, but there’s one aspect of that historical conflict that’s rarely discussed: fuel. They say an army marches on its stomach, which remains true of the people doing the fighting, but when it comes to moving massive warships, you need fuel.
Modern warships primarily use three fuel sources: gasoline, diesel, and nuclear power. Yet one of those technologies wouldn’t arrive until the world’s first nuclear submarine, the USS Nautilus (SSN-571), entered the fleet in 1954. A decade earlier, WWII warships used a variety of fuels to move across the water, depending on a ship’s age and who operated it. There were four main fuel types that WWII warships used, including diesel fuel, gasoline, fuel oil, and coal.
Advertisement
Coal was mostly gone by the time the war ended, but some of the older ships used in the conflict continued to feature coal furnaces. The U.S. Navy used two of the weirdest ships in the fleet during the conflict: two converted paddle-wheel steamers to train personnel, and both used coal. Most vessels used diesel or heavy fuel oil, while smaller vessels like PT boats used 100-octane aviation gasoline. German U-boats, which caused widespread disruption throughout the Atlantic Ocean, used diesel fuel, as did American subs, so there was a variety of fuel types utilized throughout the conflict.
Advertisement
The many fuels of WWII warships
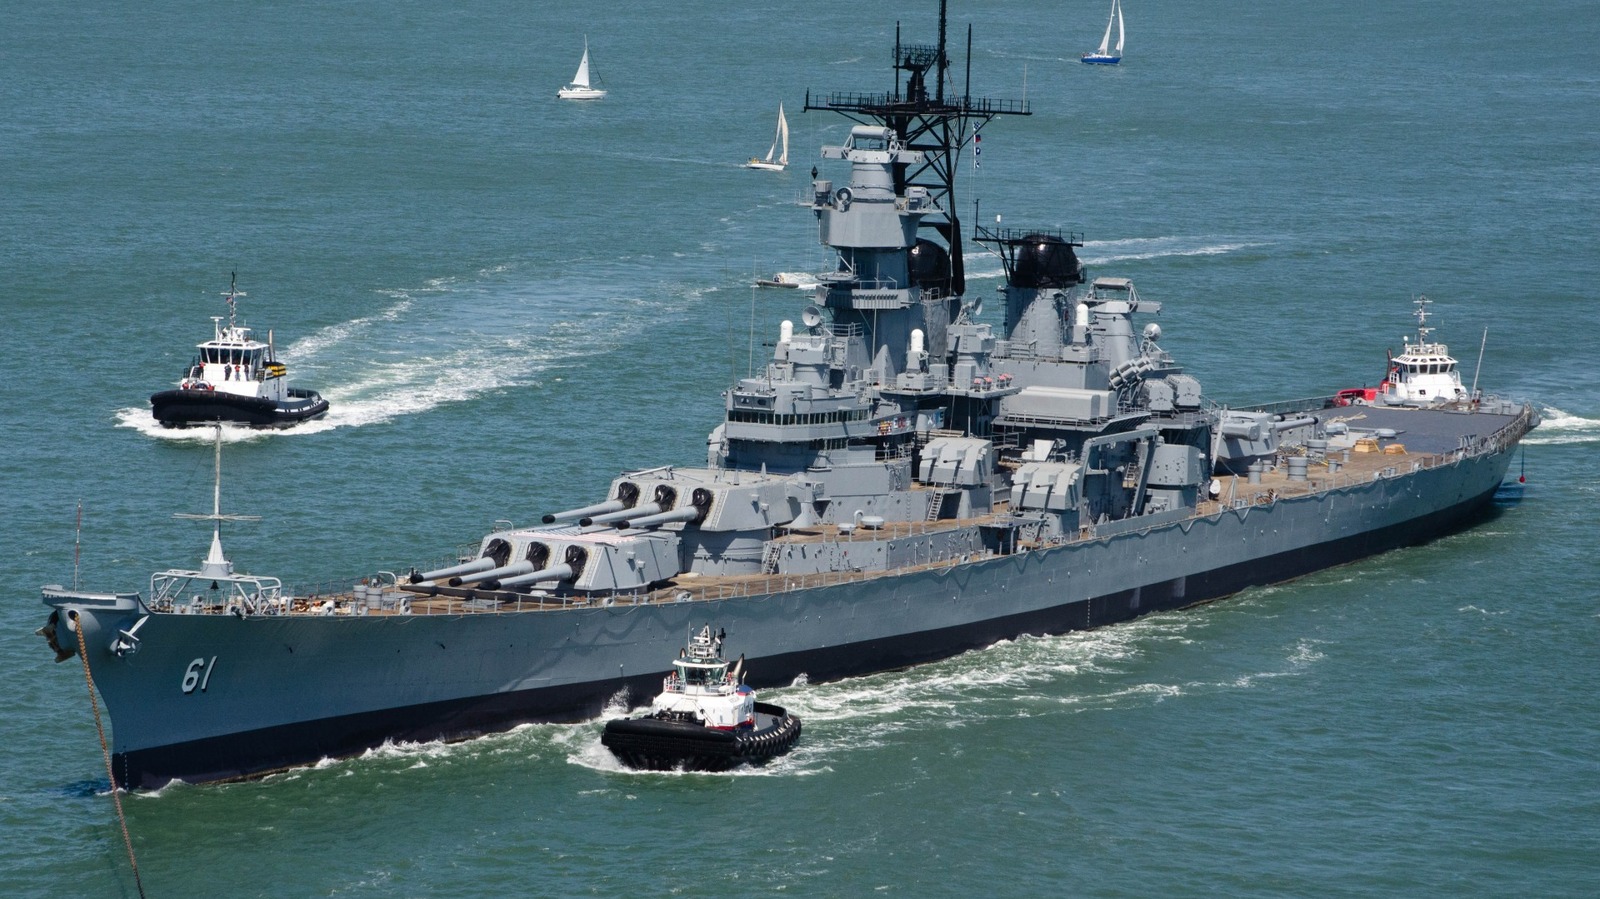
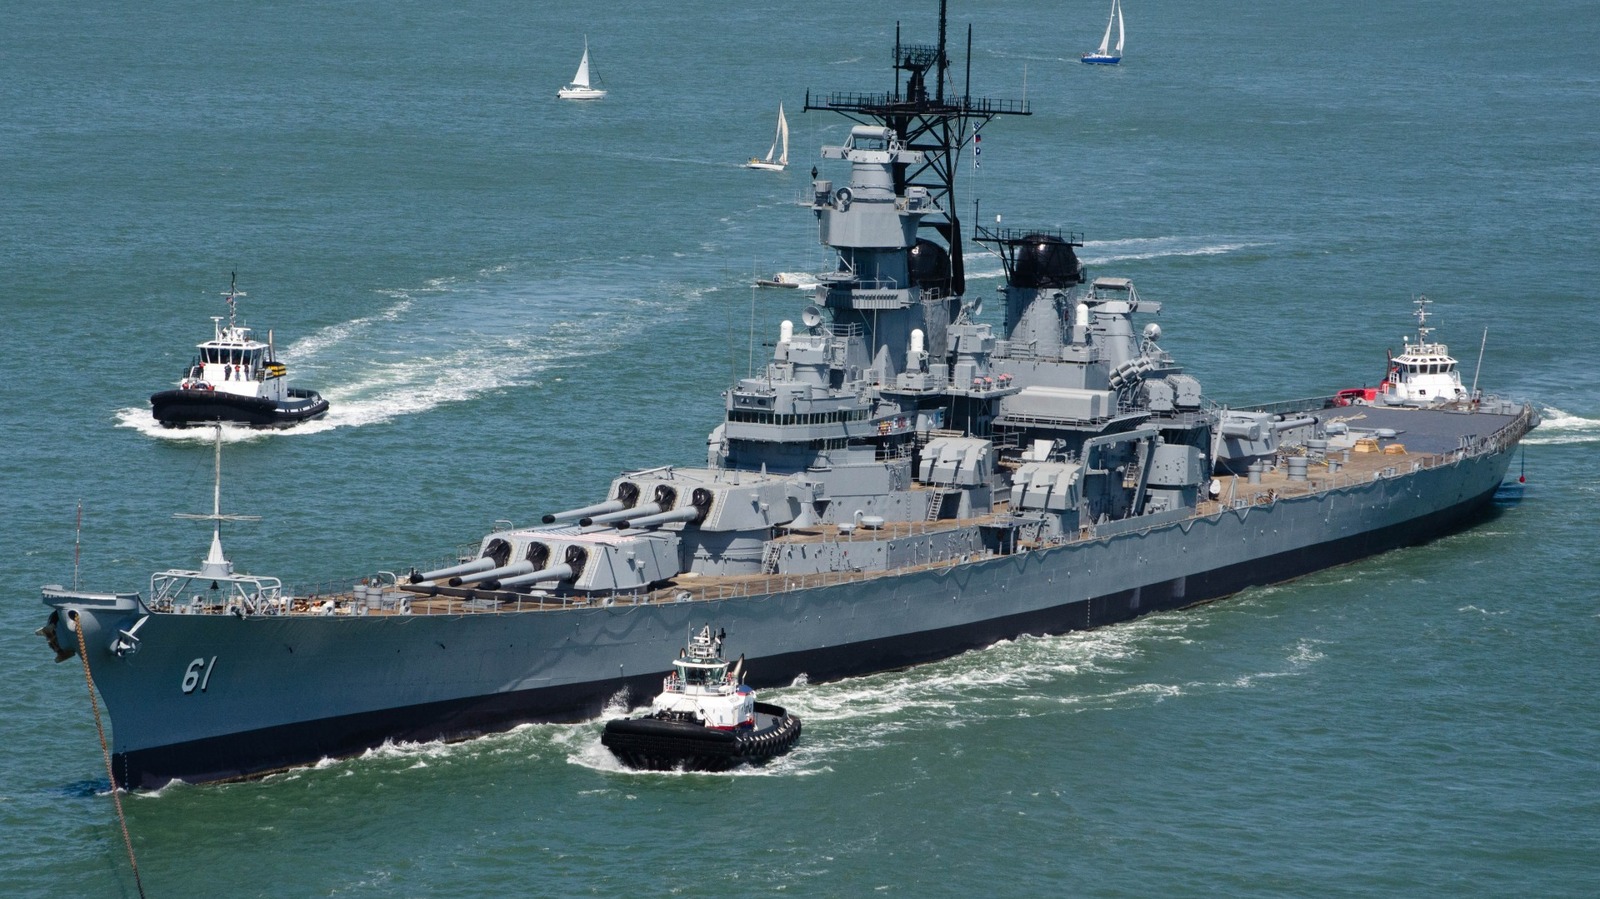
Most of the ships that used coal in the early 20th century had either been decommissioned or converted by the time WWII rolled around. The last U.S. Navy battleship fueled by coal was the USS Texas (BB-35), but it was converted to oil-fired boilers in 1925. After coal was largely abandoned for fuel oil, battleships like the USS Iowa (BB-61) had much better fuel efficiency, allowing for larger, faster vessels. The USS Iowa carried 2.5 million gallons of fuel oil to power the mighty warship, and the same fuel kept aircraft carriers in operation.
Essex-class carriers carried 1.5 million gallons of fuel oil, not to mention the 240,000 gallons of aviation fuel needed for their air wing. German U-boats, as well as Allied submarines, used diesel fuel while on the surface for propulsion, which also charged their batteries. While submerged, submarines used their batteries to power electric motors, as their diesel engines needed air to function. Regarding fuel oil, it was the most common energy source for WWII warships on all sides, as most surface vessels used it by 1939.
This included destroyers, frigates, cruisers, corvettes, and more. The world’s navies used different forms of fuel oil for various ships, all of which were distilled from crude oil. Regardless of the type, fuel oil was used to power ships via their steam boilers, and the U.S. Navy didn’t switch from Naval Special Fuel Oil (NSFO) until it adopted the NATO standard F-75/76 in 1969, so NSFO was its primary fuel source throughout WWII.
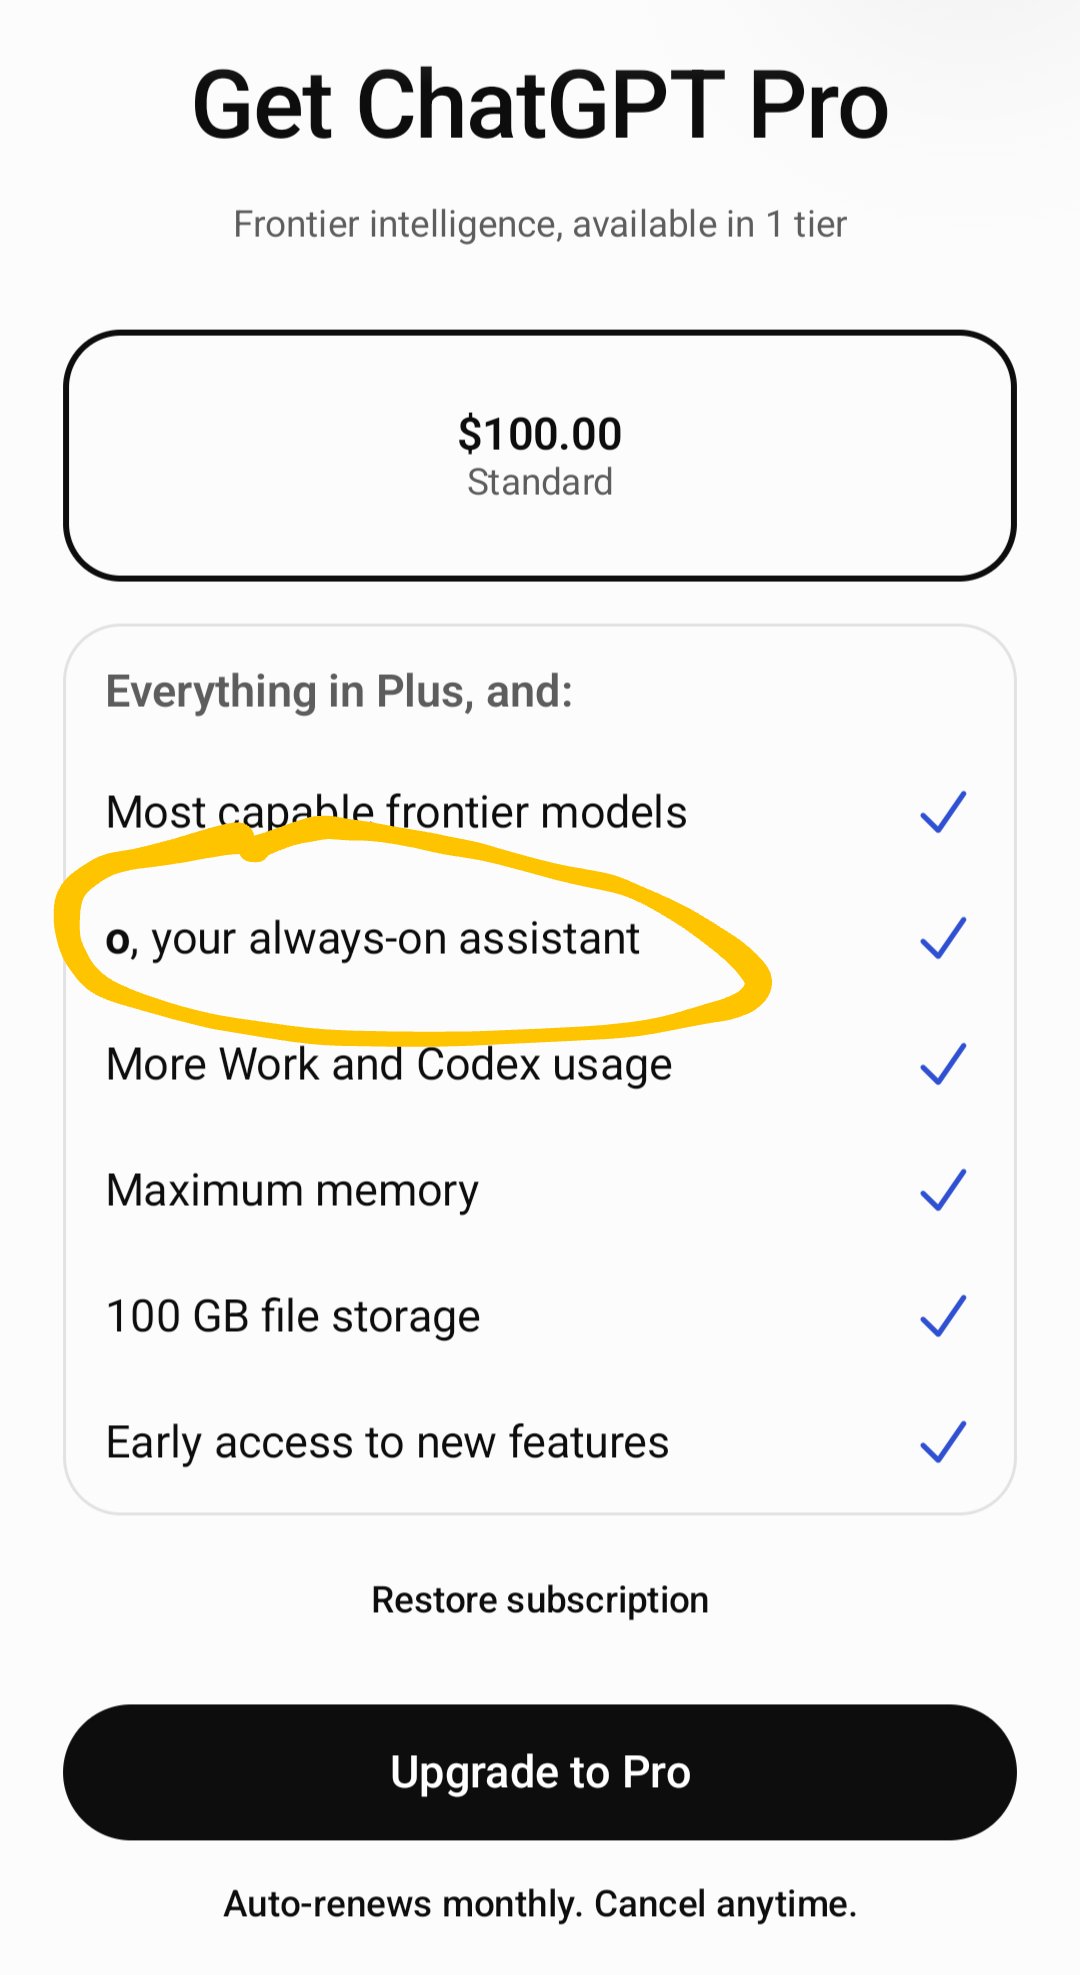
OpenAI is testing a new always-on assistant called “o”, and references to the unannounced feature briefly appeared online.
OpenAI hasn’t confirmed or denied that it’s working on a new always-on assistant, but as some users spotted on X, “o, your always-on assistant” was briefly listed as one of the benefits of the $100 ChatGPT Pro plan.
This feature was listed alongside more Work and Codex usage, maximum memory, 100GB of file storage, and early access to new features.
Moreover, there’s a dynamic configuration with a reference to display_name: "o" alongside an email_suffix: "-o", and this seems to suggest that the assistant could eventually have some form of email capability or identity.
That makes sense for an “always-on” assistant, which could continue helping with your tasks when you’re not actively using ChatGPT, but we don’t yet know exactly what OpenAI has planned.
Advertisement
OpenAI could reveal more at DevDay
OpenAI has already confirmed it’s hosting DevDay 2026 on September 29 in San Francisco, and it’s expected to announce a number of new features.
The event would give us a closer look at what its teams are building, along with technical sessions, demos, and new tools, so I wouldn’t be surprised if we hear more about “o” there.
There have also been references to an internal “Aeon” system around custom agents for ChatGPT workspaces, but “o” appears to be a separate consumer-facing experience.
Join Mikko Hyppönen and security leaders from the NFL, CHANEL, and Atlassian for a two-hour digital summit on what AI-speed attacks change, what defenders should stop doing, and how to validate, decide, fix, and re-validate at machine speed.
The staggering $900 discount delivers the lowest price on record for the M5 Max MacBook Pro 16-inch.
Amazon has issued a steep price cut on Apple’s high-end 16-inch MacBook Pro with an M5 Max chip. This laptop in Apple’s silver finish has an 18-core CPU and 32-core GPU, along with 36GB of unified memory and a spacious 2TB SSD.
Retailing for $4,399, the $900 discount brings the price down to $3,499, the lowest on record. To put the value of the deal in perspective, Amazon is charging $300 for the exact same spec in Space Black.
Advertisement
Units are in stock and ready to ship at press time, with delivery as soon as tomorrow for Prime members depending on your delivery address.


























You must be logged in to post a comment Login