A ton of attention was paid recently to some offhand statements from OpenAI and Microsoft employees that surfaced in filings in the NY Times’ ongoing case against OpenAI, which has been consolidated into a much larger class action lawsuit. As I argued earlier, that struck me as something of a nothingburger of a story, because it should have no impact on the actual legal questions regarding copyright infringement and fair use. However, on Wednesday evening, OpenAI and Microsoft filed something far more stunning, accusing Susman Godfrey (which represents the plaintiffs in the consolidated case) of effectively end-running basic rules of discovery and evidence by (1) paying for research to supply evidence its clients lacked, (2) hiding from the defendants that it had paid for that research, and (3) sneaking the paid-for research into the case outside the normal expert process.
This filing should be seen as the massive bombshell (if not fraud on the court) that people tried to make out that earlier filing to be. Professor Ed Lee, who runs ChatGPT is Eating the World (which tracks all of the various AI lawsuits), has called this an “explosive motion.” But it’s a little bit complex to understand why, which is why it will not get nearly as much attention as some offhand comments by a Microsoft employee.
To understand why this is such a big deal, we need to take a few steps back to explain. There are a bunch of different cases going on in the US regarding whether or not AI training is “fair use” and therefore not a copyright infringement. There were two important rulings in California last year, one after the other, where one judge (William Alsup) found training to be somewhat obviously fair use, while the other judge (Vince Chhabria) found it to be somewhat obviously not fair use.
As often happens in fair use cases, a lot of time is spent on the “effect on the market” argument, and part of that is whether or not the new works “dilute” the market for earlier works. In the Anthropic case, Alsup didn’t buy the claims of dilution, which is maybe not surprising, since he found training to be fair use. But perhaps more interesting is that in the Meta case, Chhabria — even as he found against fair use — wasn’t persuaded about the “dilution” argument:
Advertisement
As for the potentially winning argument—that Meta has copied their works to create a product that will likely flood the market with similar works, causing market dilution—the plaintiffs barely give this issue lip service, and they present no evidence about how the current or expected outputs from Meta’s models would dilute the market for their own works.
That was a federal judge signalling to potential plaintiffs, if you’re bringing infringement cases like this, maybe find some evidence of dilution?
And… that happened. Earlier this year, a preprint came out on Arxiv seemingly providing evidence on that specific point, claiming that “Generative AI floods and dilutes the market for books” written by four researchers, most notably Jane Ginsburg, who is one of the most famous copyright scholars around (though is also well known as one of the most extreme copyright maximalists, not to mention a general hater on a broad interpretation of fair use). But the lead name on the paper is Tuhin Chakrabarty, a recent PhD. (2024) grad who is now a computer science professor at SUNY Stony Brook. Chakrabarty received his PhD. from Columbia University, where Ginsburg teaches.
A friend had sent me that report when it came out and I found the analysis… perplexing. I had put it on my list of things to write about, but never got to it. Thankfully, Thad McIlroy, who runs “The Future of Publishing” and has been a long term contributing editor at Publishers Weekly, took it upon himself to examine the paper and found it deeply problematic, mainly because they relied on Kindle Unlimited to get copies of the books that they used for the analysis. But as McIlroy points out, that’s distortionary for many reasons regarding how KU works, and suggests that many of the underlying assumptions in the paper simply don’t hold up to scrutiny:
But the author earns income on KU solely on the number of actual pages of their book that are read by a subscriber. Just getting downloaded provides no income. The complex formula is well-described here. There is no method available to estimate the page reads for a book, nor the KU income. Chakrabarty writes, “We measure Kindle Unlimited as whether a title is available on the service, not as how much of it readers actually read. The panel does not tell us whether a given unit is a Kindle Unlimited borrow, a page read allocation, or an ordinary purchase.”
An interesting aspect of KU is that a book’s income there may relate far more closely to quality than it does under royalty systems. If a reader downloads a low-quality AI-generated book on KU, starts to read it, and recognizes the low quality, they will stop reading and move onto another book. The author will earn an insignificant amount of money. On the other hand, if a reader buys the same book, the author receives their full royalty (unless the reader goes to the trouble of returning the book and seeking a refund).
Advertisement
An AI-generated book on KU will only earn significant page revenue if readers find it to be of quality sufficient to match the genre books they are used to reading on the platform.
With these factors in mind, the prevalence of Kindle Unlimited titles in this study appears to be a distorting influence. First, AI-generated books are more likely to appear on Kindle Unlimited than they are more broadly on the Amazon Kindle platform. Second, there is no clear method available to estimate a book’s actual KU income.
Even more bizarre, when McIlroy shared a copy of his critique with Chakrabarty, he was dismissed on moral grounds, because McIlroy has argued for ethical ways to use AI in publishing, which Chakrabarty claims is “morally not okay with me.” That alone should raise some serious red flags about the objectiveness of Chakrabarty in this research. He did not come to this with an open mind. He came bearing a grudge.
A few months earlier, Chakrabarty and Ginsburg (along with Xinyue Liu, who was also an author of the paper above, and who appears to be a first or second year PhD. student working for Charkrabarty) put out another paper called “Alignment Whack-A-Mole: Finetuning Activates Verbatim Recall of Copyrighted Books in Large Language Models.” That piece claimed there was evidence that AI models “store copies of copyrighted works” and even pointed out that this “undermine[s] a key premise of recent fair use rulings.” Indeed, it calls out the Alsup and Chhabria rulings in the paper itself, and effectively notes that they’re responding to the judge’s concerns regarding the effect on the market.
Advertisement
In short, Chakrabarty, Liu, and Ginsburg have been publishing research that attempts to fill in the gaps that multiple judges had called out, and to help plaintiffs argue that training is not fair use. This was especially important because if such evidence was widely available, other plaintiffs would have brought it up. But they have not. Likely because it doesn’t really exist unless you stretch your methodology to its breaking point.
Of course, my biases are known: I’m quite convinced that training AI on copyrighted works is fair use, and I find the argument that slop books “dilute” non-slop books to be beyond nonsensical. Similarly, knowing a little bit (just enough to be dangerous) about how LLM training works, makes it difficult for me to believe that models are, in fact, holding full copies of works they are trained on. That’s just not how they work. But you don’t have to take my word for it. A. Feder Cooper, a well-known computer science professor at Yale who has (somewhat famously) done research on getting LLM’s to spit out “memorized books,” or other full works, had some pretty blunt criticisms of the “whack-a-mole” paper:
As will become clear soon, I think the paper has significant methodological and presentation problems. I’ve spent considerable time reviewing and re-reviewing the paper, and have consulted with two trusted senior colleagues who are experts on memorization to gut-check my reading. And, in brief, I’m confident that Alignment Whack-a-Mole’s headline claims are incorrect. These results rest on aspecific memorization metric and elicitation methodologythat I don’t think hold up to scrutiny, anddon’t support the broad claimsthe paper makes. At best, I think the claims are seriously overstated; at worst, the large majority are wrong. I can’t tell which because the paper doesn’t report enough detail to distinguish the two.
That alone should be concerning, but the media — including the NY Times — really loved to report on these studies, even as their methodology seemed questionable to some experts, and despite the clear potential conflict of interest.
Now, that takes us to the claims in the OpenAI filing from earlier this week: it’s that the plaintiffs’ lawyers at Susman Godfrey secretly paid at least Chakrabarty to do these studies, hid that fact, and then took further steps to launder the studies as non-biased expertise. It appears this wasn’t just a conflict of interest at work, it was a conflict piled upon a conflict, and then potential fraud on the court.
Advertisement
Unable to muster any evidence of harm after years of discovery, Class Plaintiffs’ counsel Susman Godfrey L.L.P. (“Class Counsel” or “Susman”) paid Stony Brook University professor Dr. Tuhin Chakrabarty to research “[h]ow AI generated books dilute the market for human authors.” Declaration of Victor Chiu ISO Motion to Strike (“Chiu Decl.”), Ex. A. Dr. Chakrabarty then coauthored a working, non-peer-reviewed paper purporting to show exactly that (the “Chakrabarty Paper”). The paper was initially self-published on July 22, 2026. Susman had disclosed Dr. Chakrabarty and one of his co-authors as retained experts months earlier—but the resumes Susman provided omitted that Susman had funded Dr. Chakrabarty’s research. Neither Dr. Chakrabarty nor the other disclosed expert ever served an expert report in this case. And after Defendants specifically objected that Dr. Chakrabarty’s resume was incomplete, Susman provided what it represented was an “updated resume” that still omitted Susman’s own funding of his market-dilution research.
Now, some people will point out that it’s not uncommon for companies to pay for research and then use that research elsewhere in ways that are beneficial to them. That’s absolutely true. The problem here isn’t who paid for the research, but the lengths the plaintiffs’ lawyers went to in hiding who paid for it from the court (and from OpenAI and Microsoft)… and how the evidence was laundered into the case long past the normal deadline where it could have been challenged.
Normally, if you bring expert witnesses into a case, the other side gets to challenge their expertise and any research findings that they’re providing. But here, the class plaintiffs’ lawyers took a bunch of steps that at least suggest they deliberately sought to make that effectively impossible with this bit of research. They had named Chakrabarty as a potential witness, providing an incomplete resume for him, but then didn’t use him as such. Instead, they did a kind of evidence two step to get it into the case in a way that would make it harder to challenge:
On July 22, 2026—after the deadlines for all expert reports had passed—Dr. Chakrabarty, Dr. Dhillon, Xinyue Liu, and Professor Jane Ginsburg uploaded to the internet a working paper titled “Generative AI floods and dilutes the market for books.”… They then uploaded two subsequent versions of the paper on July 26, 2026 and August 3, 2026, respectively…. The paper remains identified as a “Working Paper Under Review.” …
The Chakrabarty Paper purports to “measure[] how generative AI” impacts “a real book market once its output reache[s] the catalog and compete[s] for sales.” … Its abstract asserts that the research “bear[s] directly on the market-effect question at the center of the fair use defense to copyright infringement.” … The July 22 and July 26 versions of the Chakrabarty Paper did not disclose that it was funded by Susman and did not make any of its underlying data available. … The August 3 version of the Chakrabarty Paper again did not disclose its funding source. …
[…..]
Advertisement
On Sunday, August 2, 2026, the afternoon before Mr. Lasinski’s deposition, Class Plaintiffs served a supplemental report devoted entirely to the Chakrabarty Paper and which cited the July 26, 2026 version. … At his deposition the next day, Mr. Lasinski testified that he did not analyze any of the data underlying the Chakrabarty Paper…. Mr. Lasinski also testified that he had never spoken with Dr. Chakrabarty or any of his co-authors “about this paper or any other matters related to this litigation.” … When Mr. Lasinski was asked whether he understood that Dr. Chakrabarty and Dr. Dhillon “were retained as experts by Plaintiffs in this matter,” counsel from Susman objected: “I’m not sure why this is appropriate to ask Mr. Lasinski about.” … Mr. Lasinski ultimately testified that he did not “know that this means that [Dr. Chakrabarty and Dr. Dhillon] were retained.”
Mr. Lasinski likewise did not know who had funded the research he was relying upon. When asked whether “the study was funded by Plaintiffs in this case or the Susman Godfrey firm,” Mr. Lasinski testified: “I don’t know the funding sources,” but “to be clear . . . funding something like this would be inconsistent with what I’ve known the Susman Godfrey firm to do.” … Counsel from Susman, who was defending the deposition, did not correct the record or comment on the issue of funding.
Got that? After the deadlines for expert reports were past, the Susman lawyers filed a “supplemental report” from a different expert, Lasinski, which was all about this report that Chakrabarty et al had only just published, effectively getting it into evidence after the deadline passed, and through a non-author of the paper, who had little actual knowledge of the paper’s methodology or data. And, yes, it’s notable that Lasinski said it would be “inconsistent” with what he knew of Susman Godfrey for the firm to fund something like this. Meanwhile, the Susman lawyers in the room objected to questions about whether the paper’s authors were retained experts, and then said nothing at all when Lasinski vouched that the firm wouldn’t fund such research. How… interesting.
There’s also the bit about how the lawyers for OpenAI and Microsoft figure this out:
Advertisement
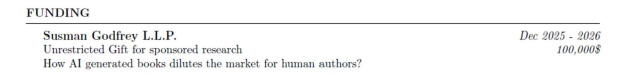
After Mr. Lasinski’s deposition, OpenAI independently located a substantially similar version of Dr. Chakrabarty’s resume on his website…. Unlike the “updated” resume Susman provided in February, however, the version OpenAI found contains a section specifying $100,000 in “Funding” from Susman in December 2025:
The resume identifies the $100,000 as an “Unrestricted Gift for sponsored research” on “How AI generated books dilutes the market for human authors?”—the same subject covered in the Chakrabarty Paper and in Mr. Lasinski’s supplemental report….
Thus, according to Dr. Chakrabarty’s own resume, Susman’s funding had begun approximately two months before Susman provided Defendants with his supposedly “updated” resume, and the stated subject of that funding was the same market-dilution issue addressed by the Chakrabarty Paper and Mr. Lasinski’s supplemental report. Neither of the resumes Class Plaintiffs provided in February disclosed that the research was sponsored or the source of funding...
That looks bad! This looks worse:
Two days later, on August 27, 2026, Dr. Chakrabarty changed the resume on his public-facing website and removed the reference to Susman’s $100,000 gift. Chiu Decl. ¶ 15, Ex. M. The revised resume now states, in fine print and barely legible font, that “[a] previous version of [Dr. Chakrabarty’s] resume stated that [he] received an unrestricted gift for sponsored research from Susman Godfrey LLP in the amount of $100,000. This was incorrect as the research was done for In re Mosaic LLM litigation for which [his] institution was compensated in a lesser amount:”
Even taken at face value, the revised resume does not deny that Susman funding facilitated the research presented in the Chakrabarty Paper. Whether the money was nominally earmarked for this MDL or the In re Mosaic LLM Litigation case, it supported the same researcher investigating the same market dilution question that is the subject of the Chakrabarty Paper, which in turn is the subject of Mr. Lasinski’s supplemental report.
OpenAI and Microsoft have asked the court to toss the paper entirely, and it’s the plaintiffs’ key evidence on dilution, the exact thing Chhabria said was missing in the Meta case. But also, they point out that this appears to be an attempted fraud on the court.
The Lasinski Supplement is not just late; it instead appears to be a deliberate effort to gain an advantage by evading Rule 26. “It is troublesome, to say the least, for a party to engage a consulting, non-testifying expert; pay for that individual to conduct and publish a study, or otherwise affect or influence the study; engage a testifying expert who relies upon the study; and then cloak the details of the arrangement with the consulting expert . . . in order to conceal it from a party opponent and the Court.” … To make matters worse, Susman appears to have concealed its funding of the Chakrabarty Paper from Class Plaintiffs’ own expert, Mr. Lasinski, despite asking him to rely on it. Dr. Chakrabarty himself was also apparently ignorant of the fact that the tens of thousands of dollars Susman was funneling his way to conduct market-dilution research and publish papers was tied to a specific litigation, much less which one. And Class Plaintiffs have now completed the maneuver: their summary judgment submissions rely extensively on the Chakrabarty Paper and describe it to the Court simply as an “academic stud[y],” without disclosing that their own counsel funded the underlying research.
This maneuver deprived Defendants of the opportunity to fully analyze and rebut the Chakrabarty Paper—and the Court of the ability to properly assess its reliability. Had Class Plaintiffs properly disclosed the Chakrabarty Paper and underlying data and materials, Defendants would have evaluated the data on which the study is based, deposed Dr. Chakrabarty and his co-authors, and tested the study’s methodology and conclusions through the ordinary discovery process. Instead, Defendants were only able to depose Mr. Lasinski, who knew nothing about Dr. Chakrabarty’s underlying data and who mistook the Chakrabarty Paper to reflect neutral, independent research.
Advertisement
Courts recognize that it is “fundamentally unfair” for a party “to supplement the record with reports of alleged ‘consulting experts’”—like Dr. Chakrabarty here—“whose identity and opinions have been shielded [from disclosure].”
The Court also has the inherent authority to preclude the Lasinski Supplement and Chakrabarty Paper to “prevent [Class Plaintiffs] from perpetrating a fraud on the court,” Yukos Capital S.A.R.L. v. Feldman, 977 F.3d 216, 235 (2d Cir. 2020), or interfering with the judicial system’s ability to impartially adjudicate this action. Such interference includes concealing counsel’s role in creating purportedly neutral scientific evidence. See Hazel-Atlas Glass Co. v. Hartford-Empire Co., 322 U.S. 238, 251 (1944) (vacating judgment obtained using an article ghostwritten by counsel but presented as the work of a disinterested expert).
That is what Susman did here. When disclosing Dr. Chakrabarty as an expert, Susman omitted that it funded the research subject of the Chakrabarty Paper, continued to omit that funding even after providing what it represented was an “updated resume,” and allowed Mr. Lasinski to testify at his deposition that Susman would not provide such funding. And even since its funding of the research has come to light, Susman has refused to answer straightforward questions about the nature of its relationship with Dr. Chakrabarty and his co-authors. As Mr. Lasinski himself acknowledges, it would be “inconsistent” for a law firm to fund a study for litigation and then present it through an expert as neutral academic literature.
Once again, the issue isn’t even that the research is sketchy (although… it is). Nor is it that the research was paid for by an interested party (though… it was). The main issue is that the funding appears to have been deliberately hidden from the defendants, and then the sketchy, paid-for research was laundered into the case through a different expert after the deadline for expert reports had passed.
Advertisement
Literally everything about this bit of research — which is a key plank in the anti-fair use argument — comes out of this as suspect.
If you own a Honda that has been recalled in 2026, then you know how frustrating the situation can be, especially as the automaker’s problems continue to make headlines. But when it comes to one specific recall involving rearview camera failures, the NHTSA has finally closed its investigation. They found that the replacement wire harness installed under a 2022 recall was not expected to develop the same wear-related failure during a reasonable vehicle lifespan.
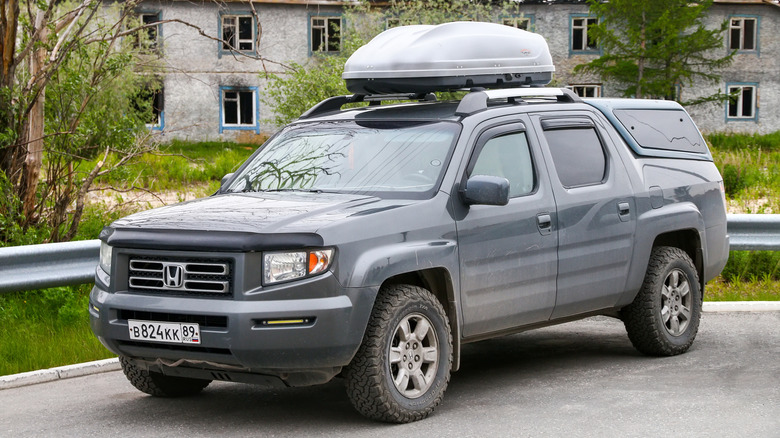
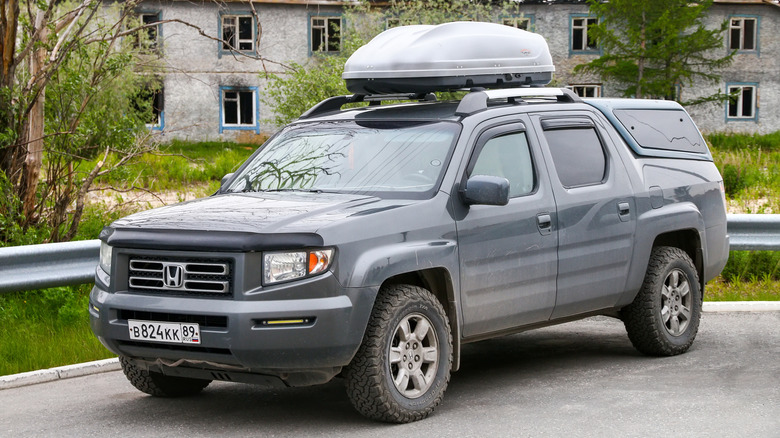
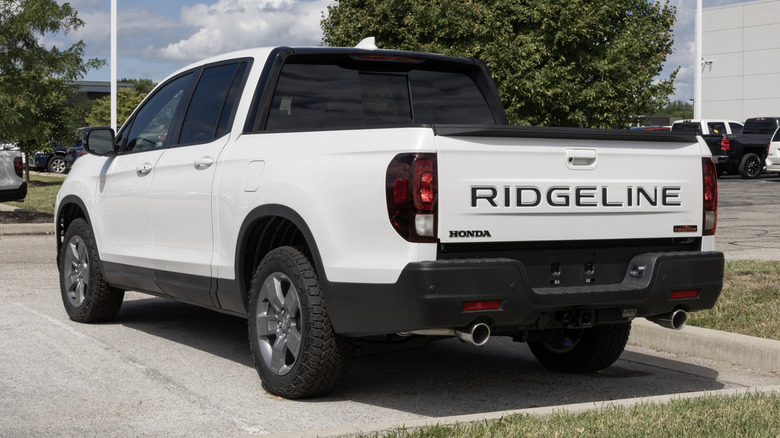
The NHTSA’s Engineering Analysis covered 129,092 trucks and was prompted by questions about whether the recall repair would hold up over time. That concern actually stemmed from the original problem, which could cause the rearview camera’s tailgate wire harness to wear down and break. This could happen after repeatedly opening and closing the tailgate. Honda’s 2022 recall covered over 117,000 Ridgelines and called for the harness to be replaced with an improved part.
The NHTSA didn’t open its own Recall Query until June 26, 2024, nearly two years after Honda’s original recall action. That review was upgraded to an Engineering Analysis on February 11, 2025, as the agency continued examining whether the replacement harness could eventually experience the same type of failure. The NHTSA’s findings mean that there is no additional action coming from this investigation, and it ultimately closed its Engineering Analysis.
Advertisement
What the recall means for owners
Jetcityimage/Getty Images
As part of its investigation into Honda’s rearview camera recall, the NHTSA took a closer look at the vehicles and the wire harness itself. The agency’s Vehicle Research and Test Center surveyed Ridgeline owners in Ohio, inspected select vehicles from those responses, and conducted durability testing to try and replicate the original failure. The NHTSA could not duplicate the problem, and it also found that most of the reported camera issues were caused by different problems unrelated to the harness.
Honda’s original 2022 recall perhaps wasn’t as straightforward for some Ridgeline owners in terms of correcting the problem. Honda initially told owners in January 2023 that the replacement parts needed for the repair were not yet available. That remained the case until August of that year when the automaker finally gave the greenlight, notifying customers to schedule a free repair at an authorized dealer. The repair itself involved replacing the RVC tailgate harness with an improved part, which Honda estimated would take about an hour and a half.
Advertisement
For Ridgeline owners who need to check the current status of the recall, the process is fairly simple. The Honda Service Center recall lookup allows vehicle owners to enter their 17-digit VIN to see if there are any active Honda recalls for their specific model. Owners can then schedule the repair through an authorized Honda dealer, where recall-related repairs are done at no charge. That gives Ridgeline owners a way to move forward and get the recall addressed.
A graphics card is rarely bought in isolation. It has to fit the case, the cooling system, the display, the games or applications that will run on it, and increasingly, the kind of work a PC is expected to handle. A compact 1440p gaming machine has little in common with a 4K enthusiast build, while a workstation running local AI models can make entirely different demands on its GPU.
ASUS’s Radeon range reflects those differences rather than trying to force every buyer toward the same specification. The lineup stretches from the Radeon RX 9060 XT through the RX 9070 GRE and RX 9070 XT, with different card designs addressing everything from compact systems and carefully matched white builds to demanding gaming and local AI workloads. All of the graphics cards covered here also come with a three-year warranty, which matters when a GPU is likely to remain one of the most substantial components in a PC for several years.
ASUS
Choosing between them, then, is less about finding a universally superior card and more about understanding where each one makes sense. The RX 9070 XT is built for buyers who want serious 1440p and 4K gaming performance. The RX 9070 GRE occupies a more measured position for 1440p systems, while the RX 9060 XT makes a stronger case where size and compatibility carry more weight. The Turbo Radeon AI Pro R9700 sits outside that gaming hierarchy altogether, targeting users who need the memory and compute capability for local AI and other demanding workloads.
Start with the kind of PC you are building
ASUS
A graphics card can be powerful on paper and still be the wrong choice for a particular PC. Case dimensions, cooling, noise, display resolution and the kind of software you use all matter once the card is installed.
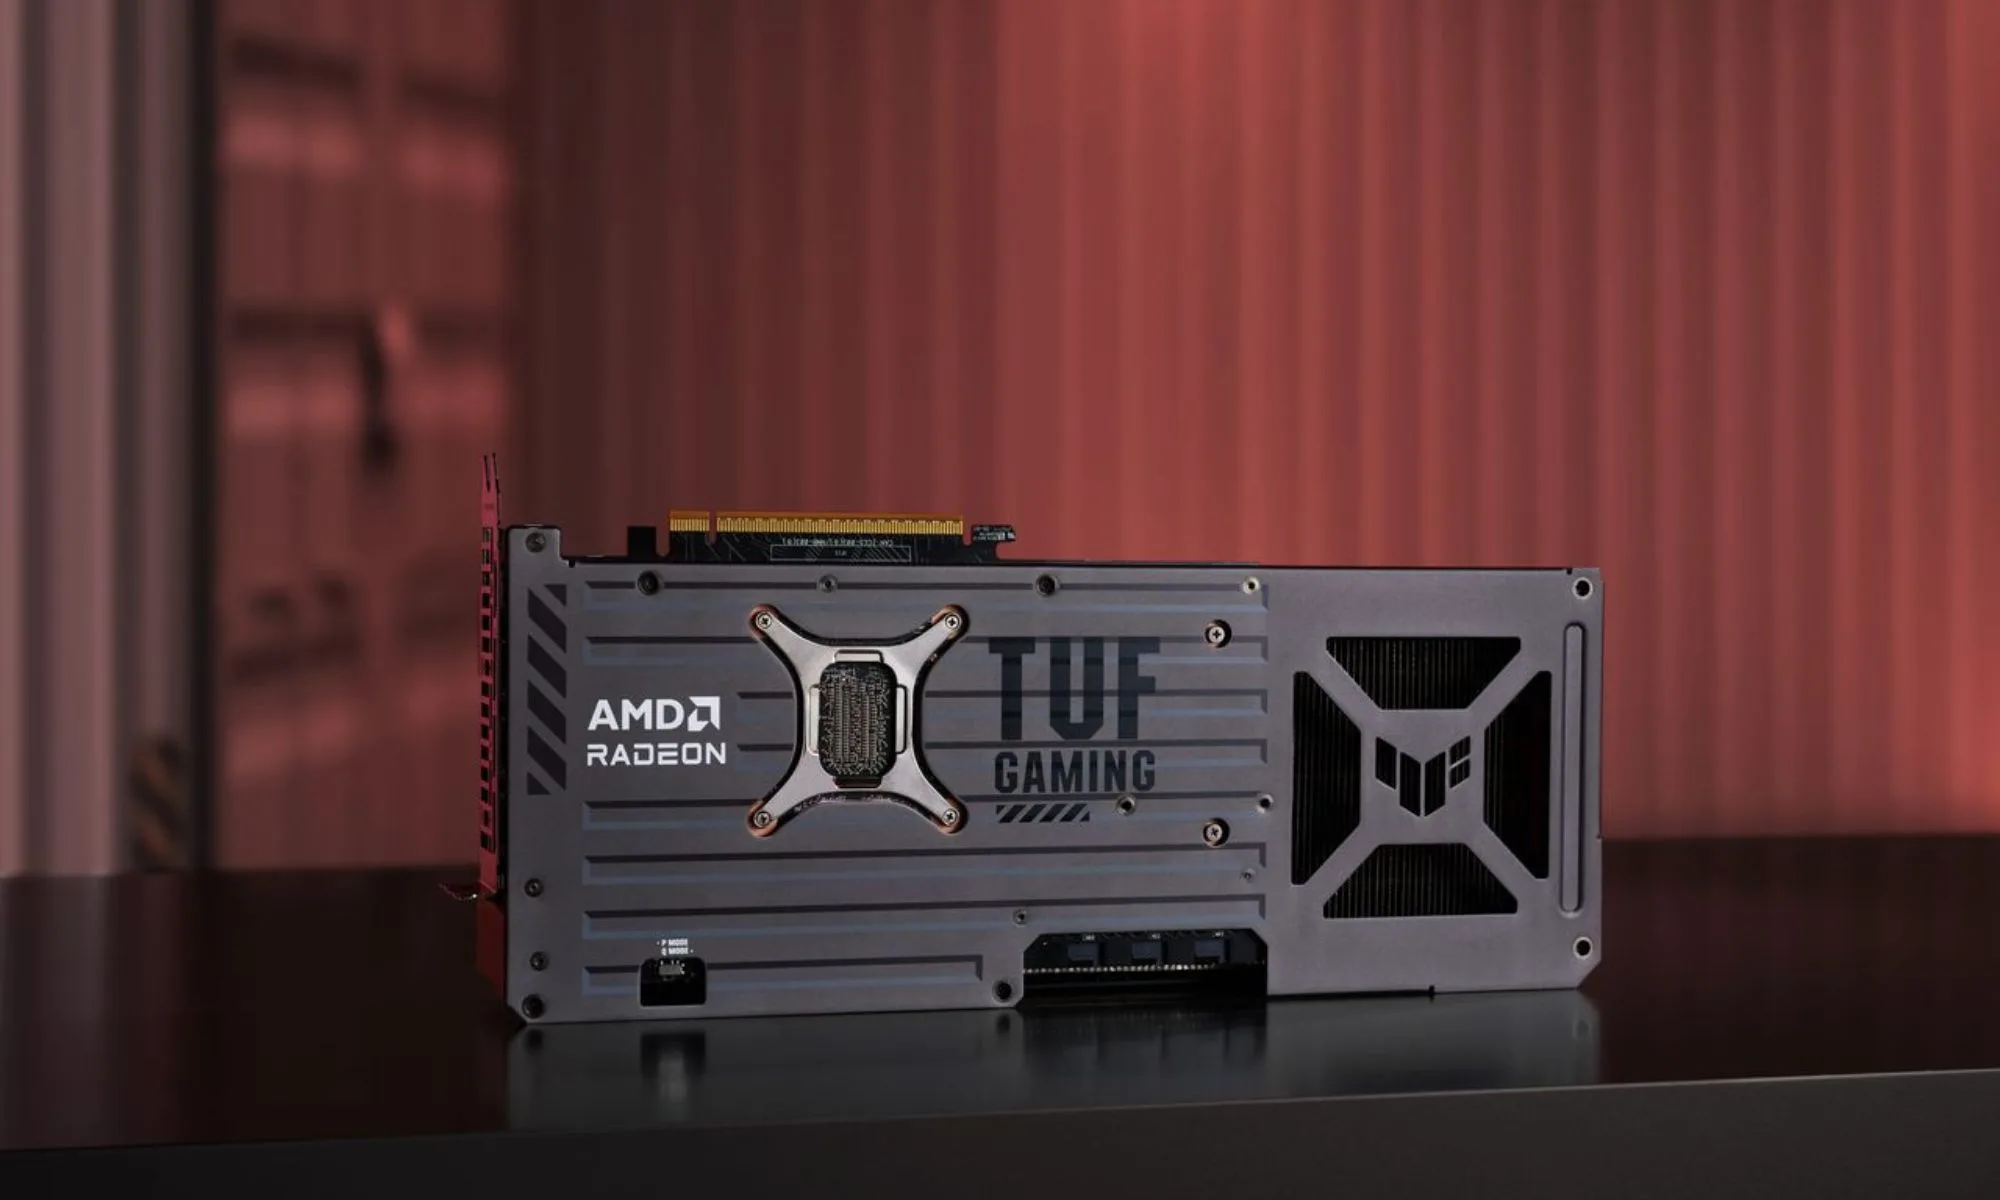
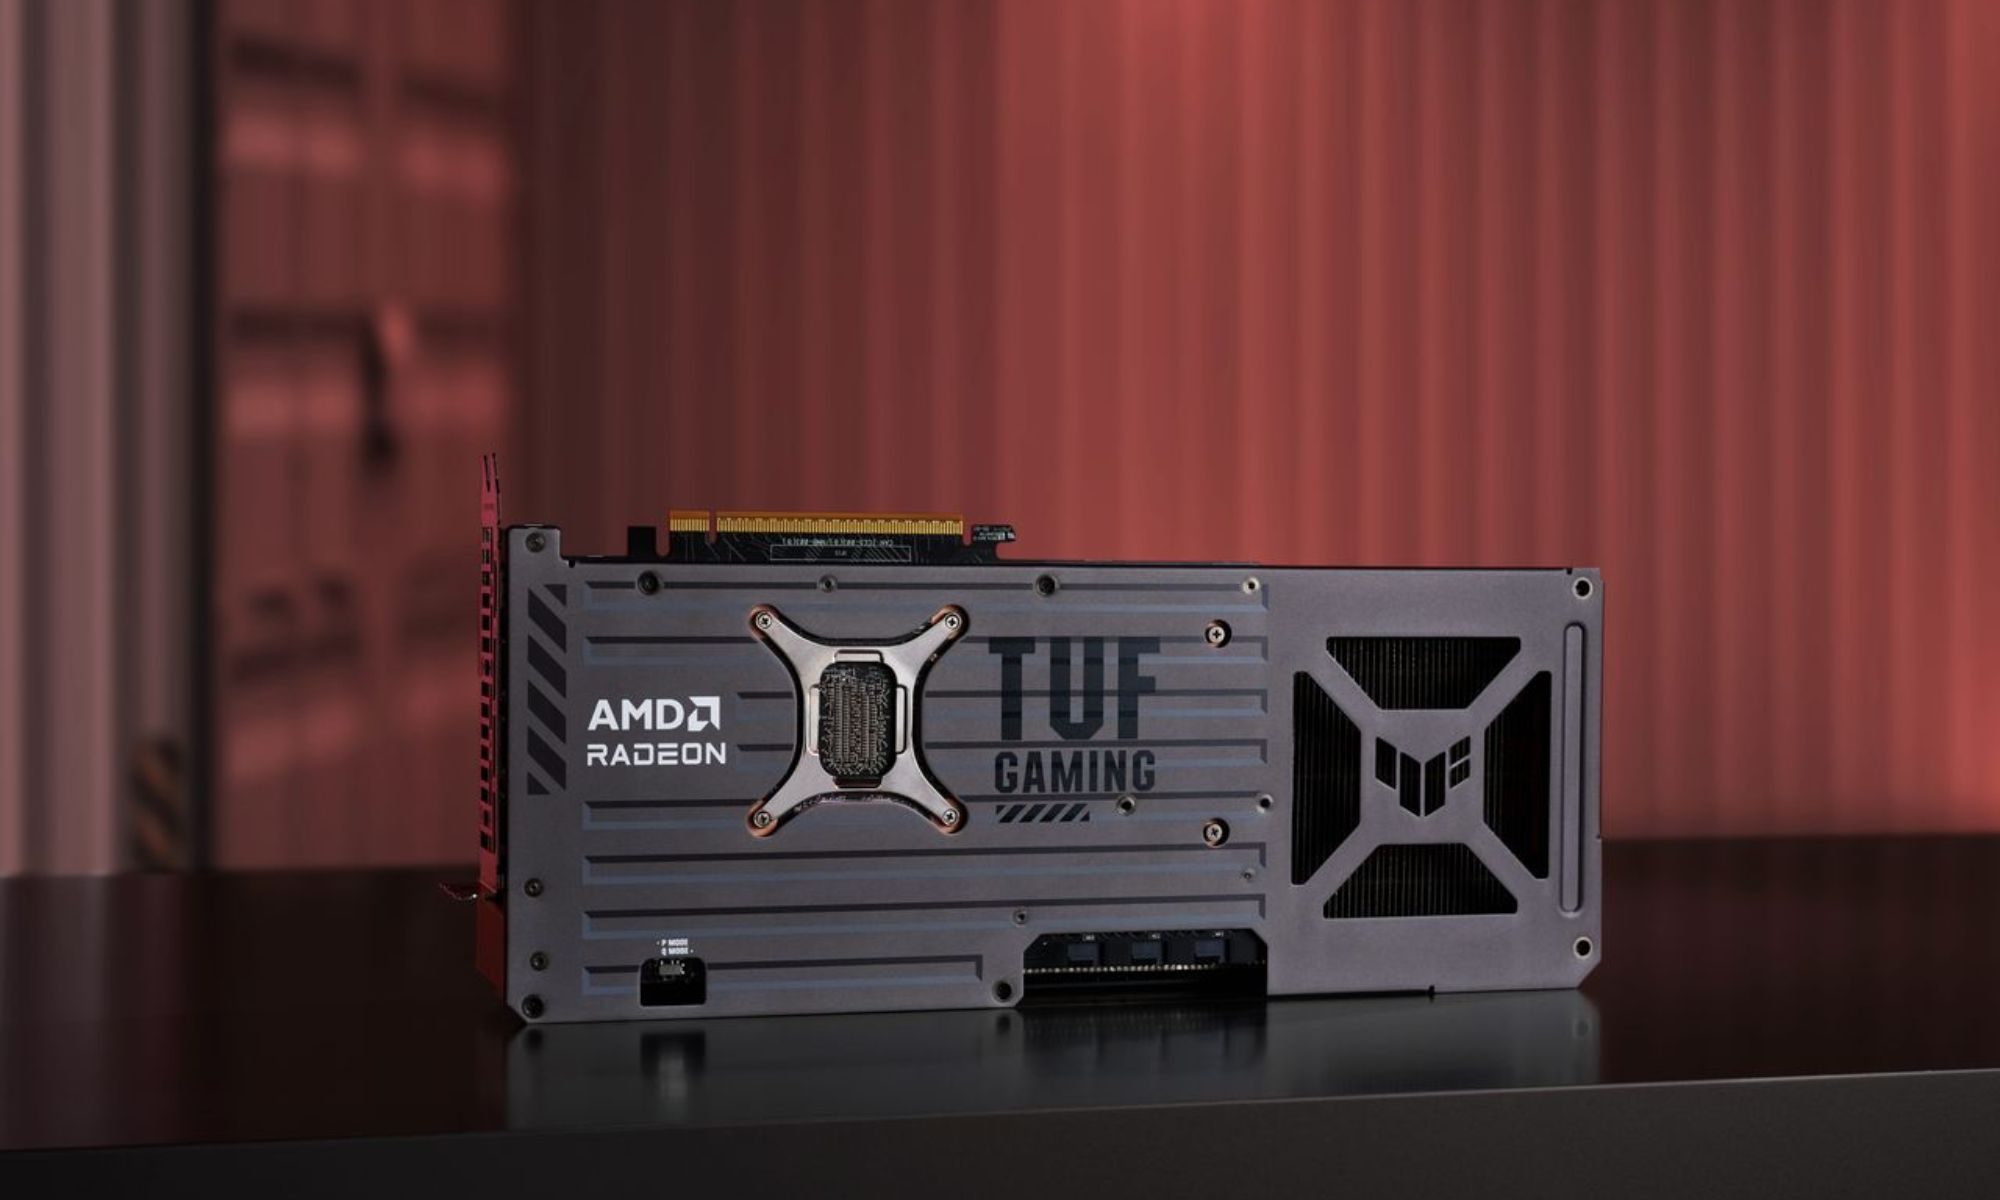
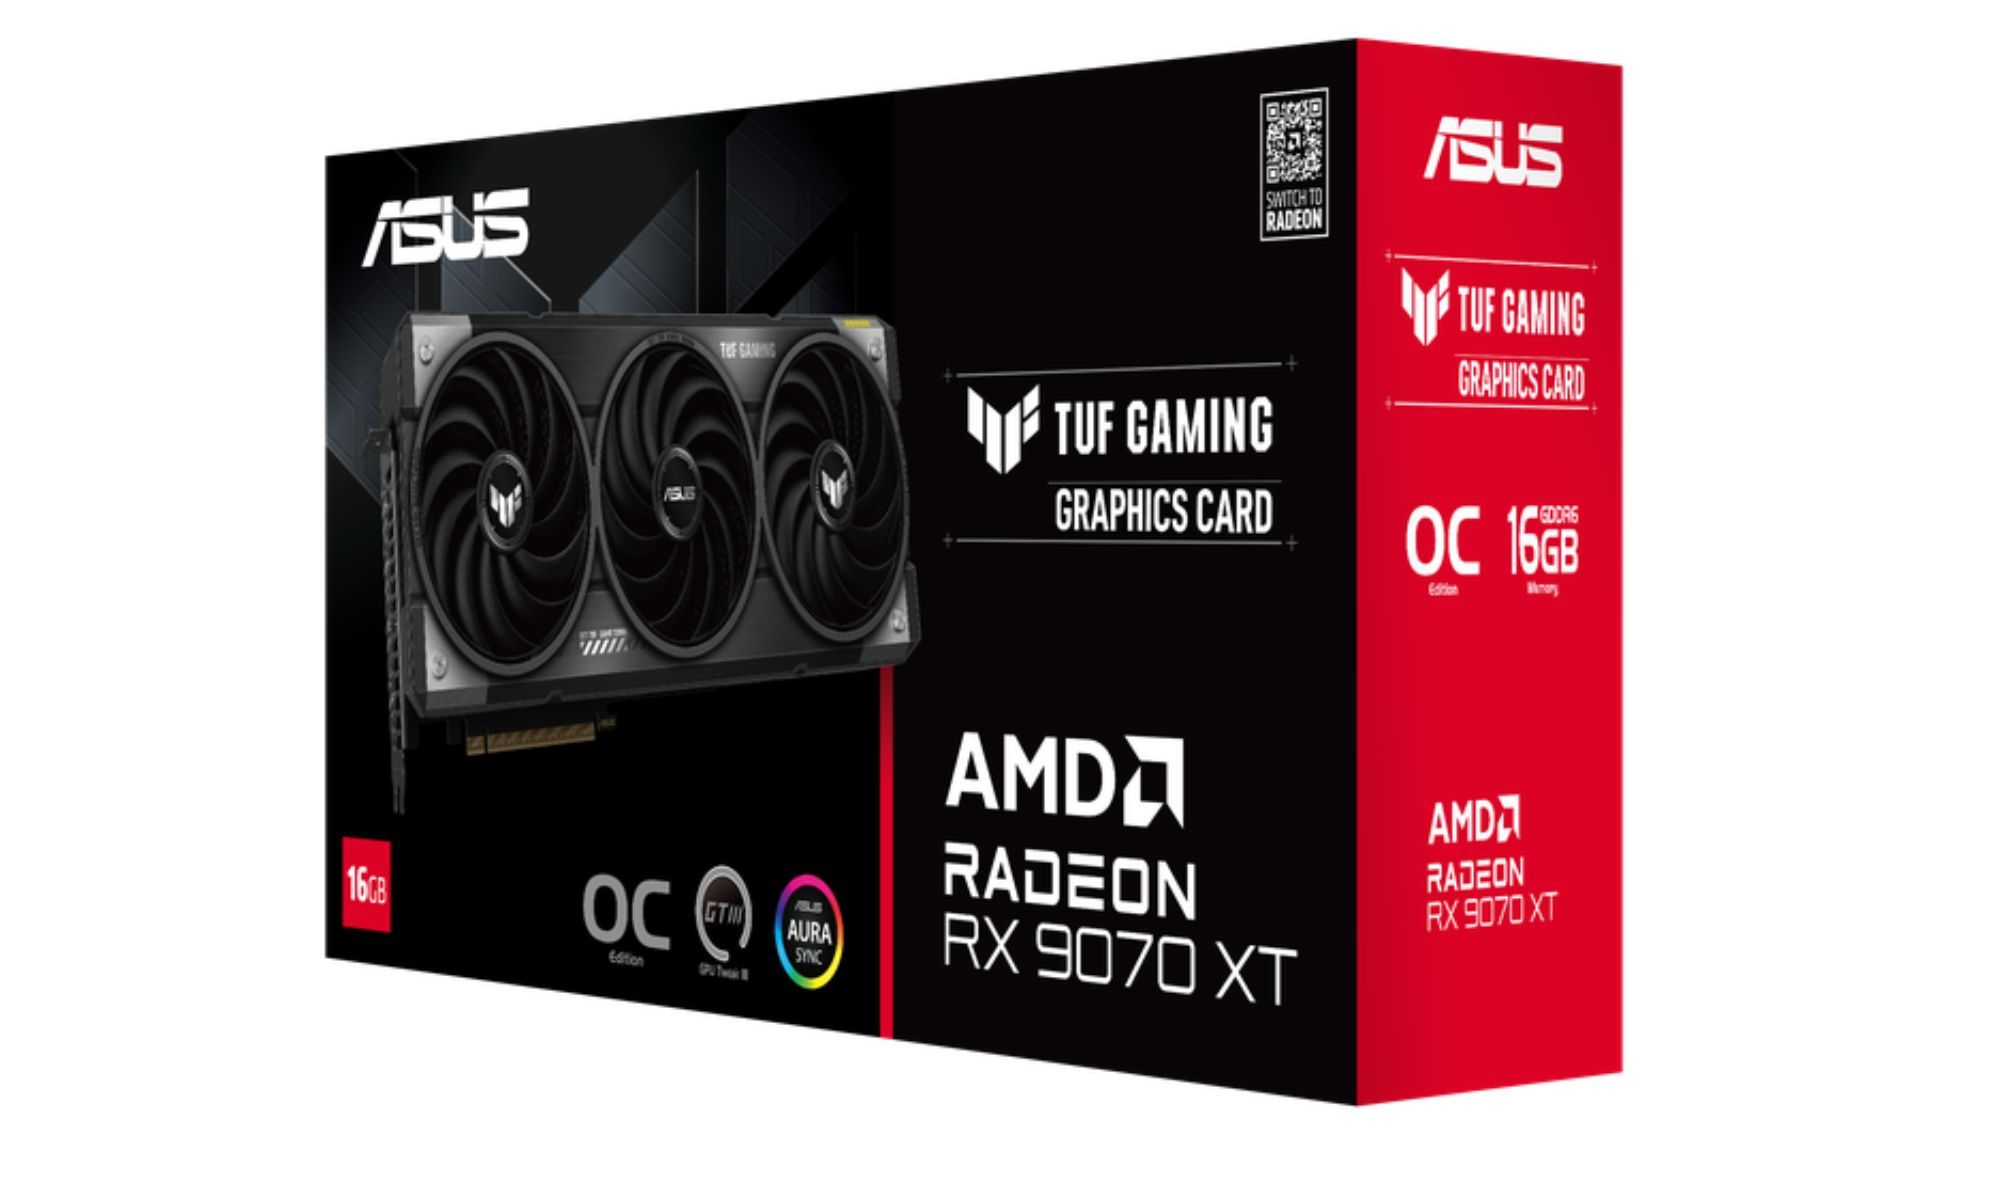
The ASUS TUF Gaming Radeon RX 9070 XT OC Edition is the straightforward choice for someone who wants to push gaming performance without treating the rest of the card as an afterthought. It is built around 16GB of GDDR6 memory and is designed for strong 1440p gaming as well as 4K, with an OC mode reaching up to 3080 MHz boost and 2540 MHz game clock according to ASUS.
The TUF’s cooling system is a major part of the card’s overall proposition. Its 3.125-slot design uses three Axial-tech fans, a large fin array and a phase-change GPU thermal pad, while dual-ball bearings are designed for long-term use. A metal exoskeleton adds rigidity while also allowing additional ventilation. The result is a card that makes sense when performance is the priority and the PC has enough room to accommodate a substantial cooler.
Advertisement
The TUF model also adds features not found on the Prime or Dual cards, including an illuminated TUF logo and a protective PCB coating designed to help guard against short circuits caused by moisture, dust and debris. ASUS also uses military-grade components designed to support long-term durability and reliable power delivery.
ASUS
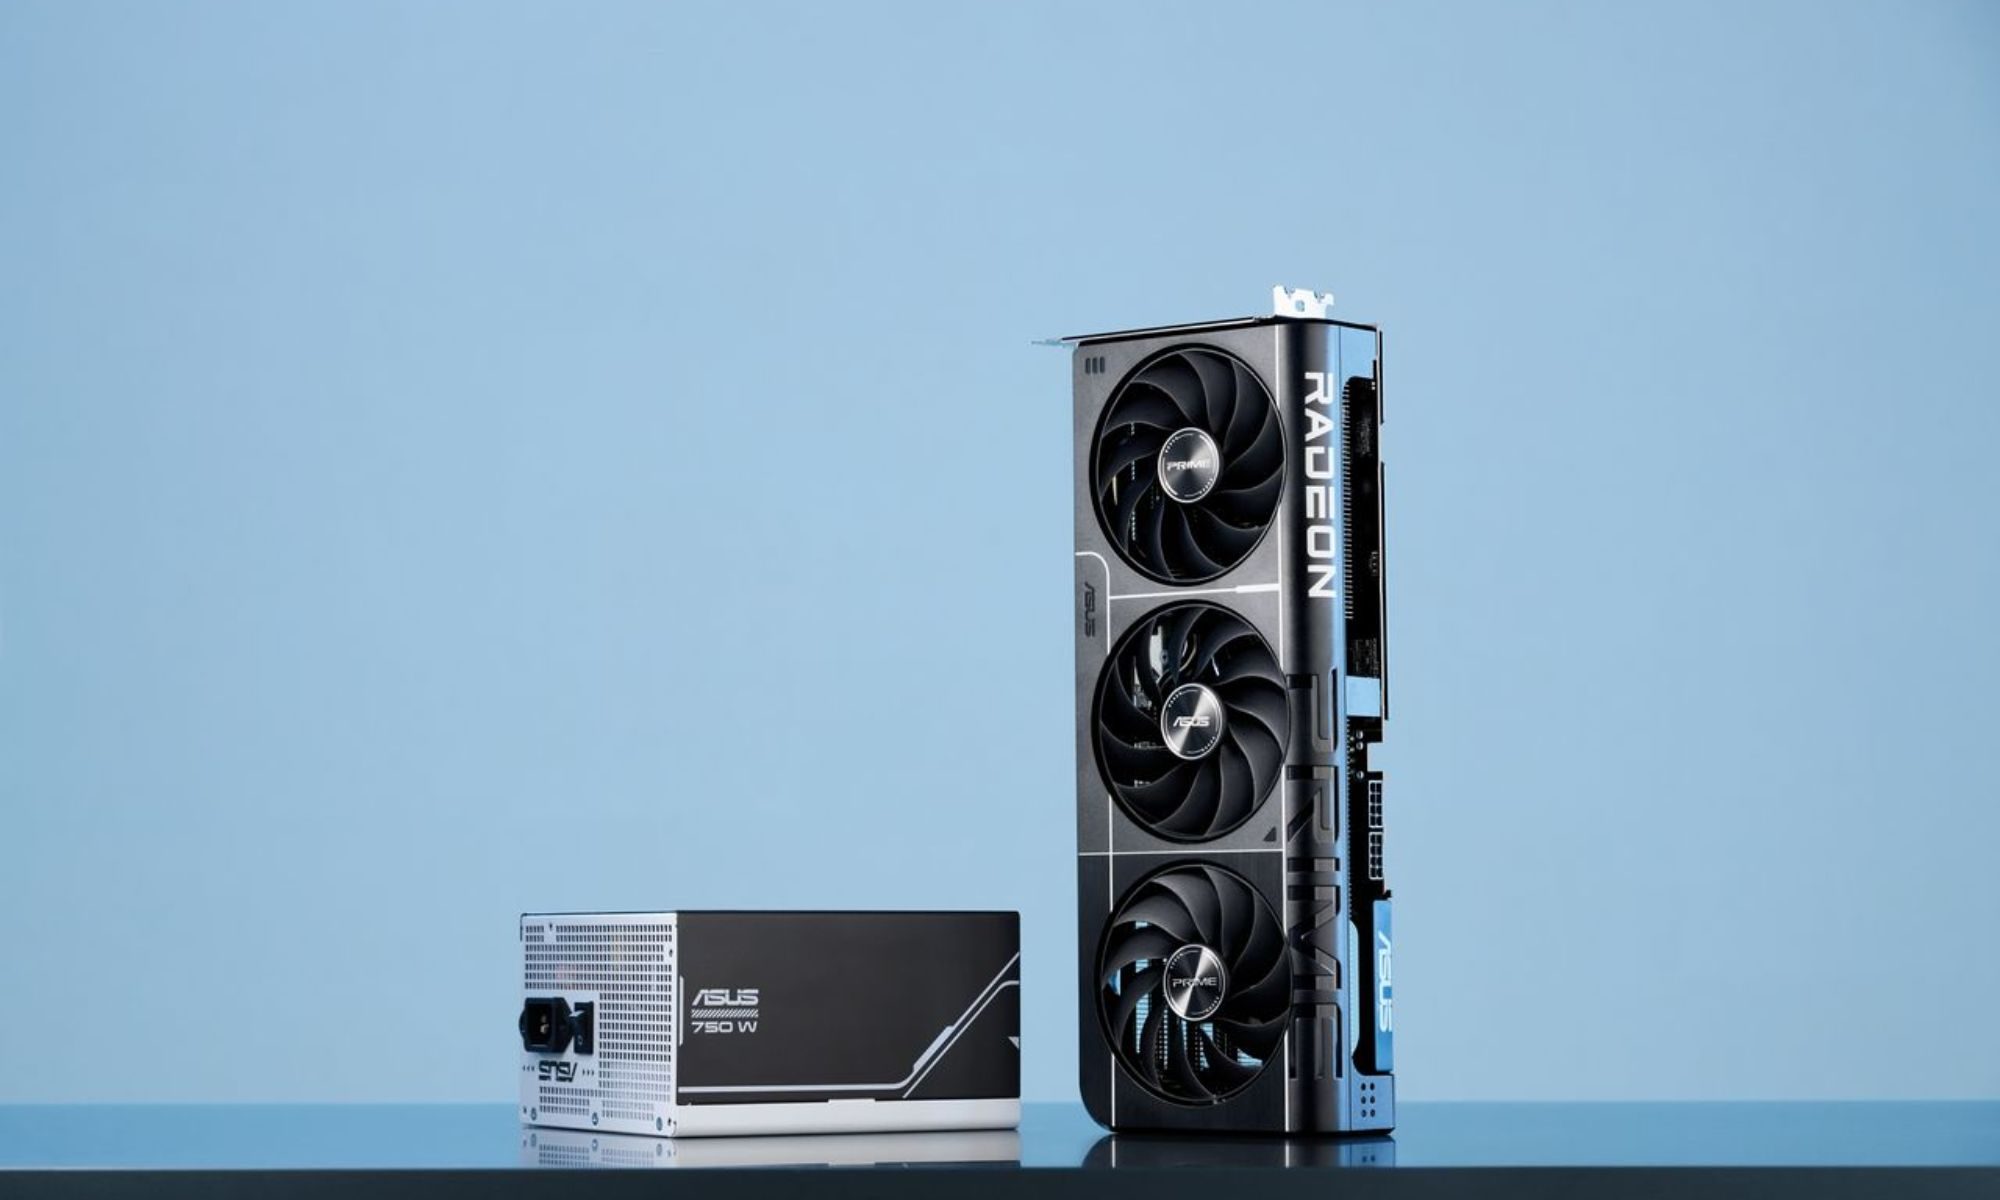
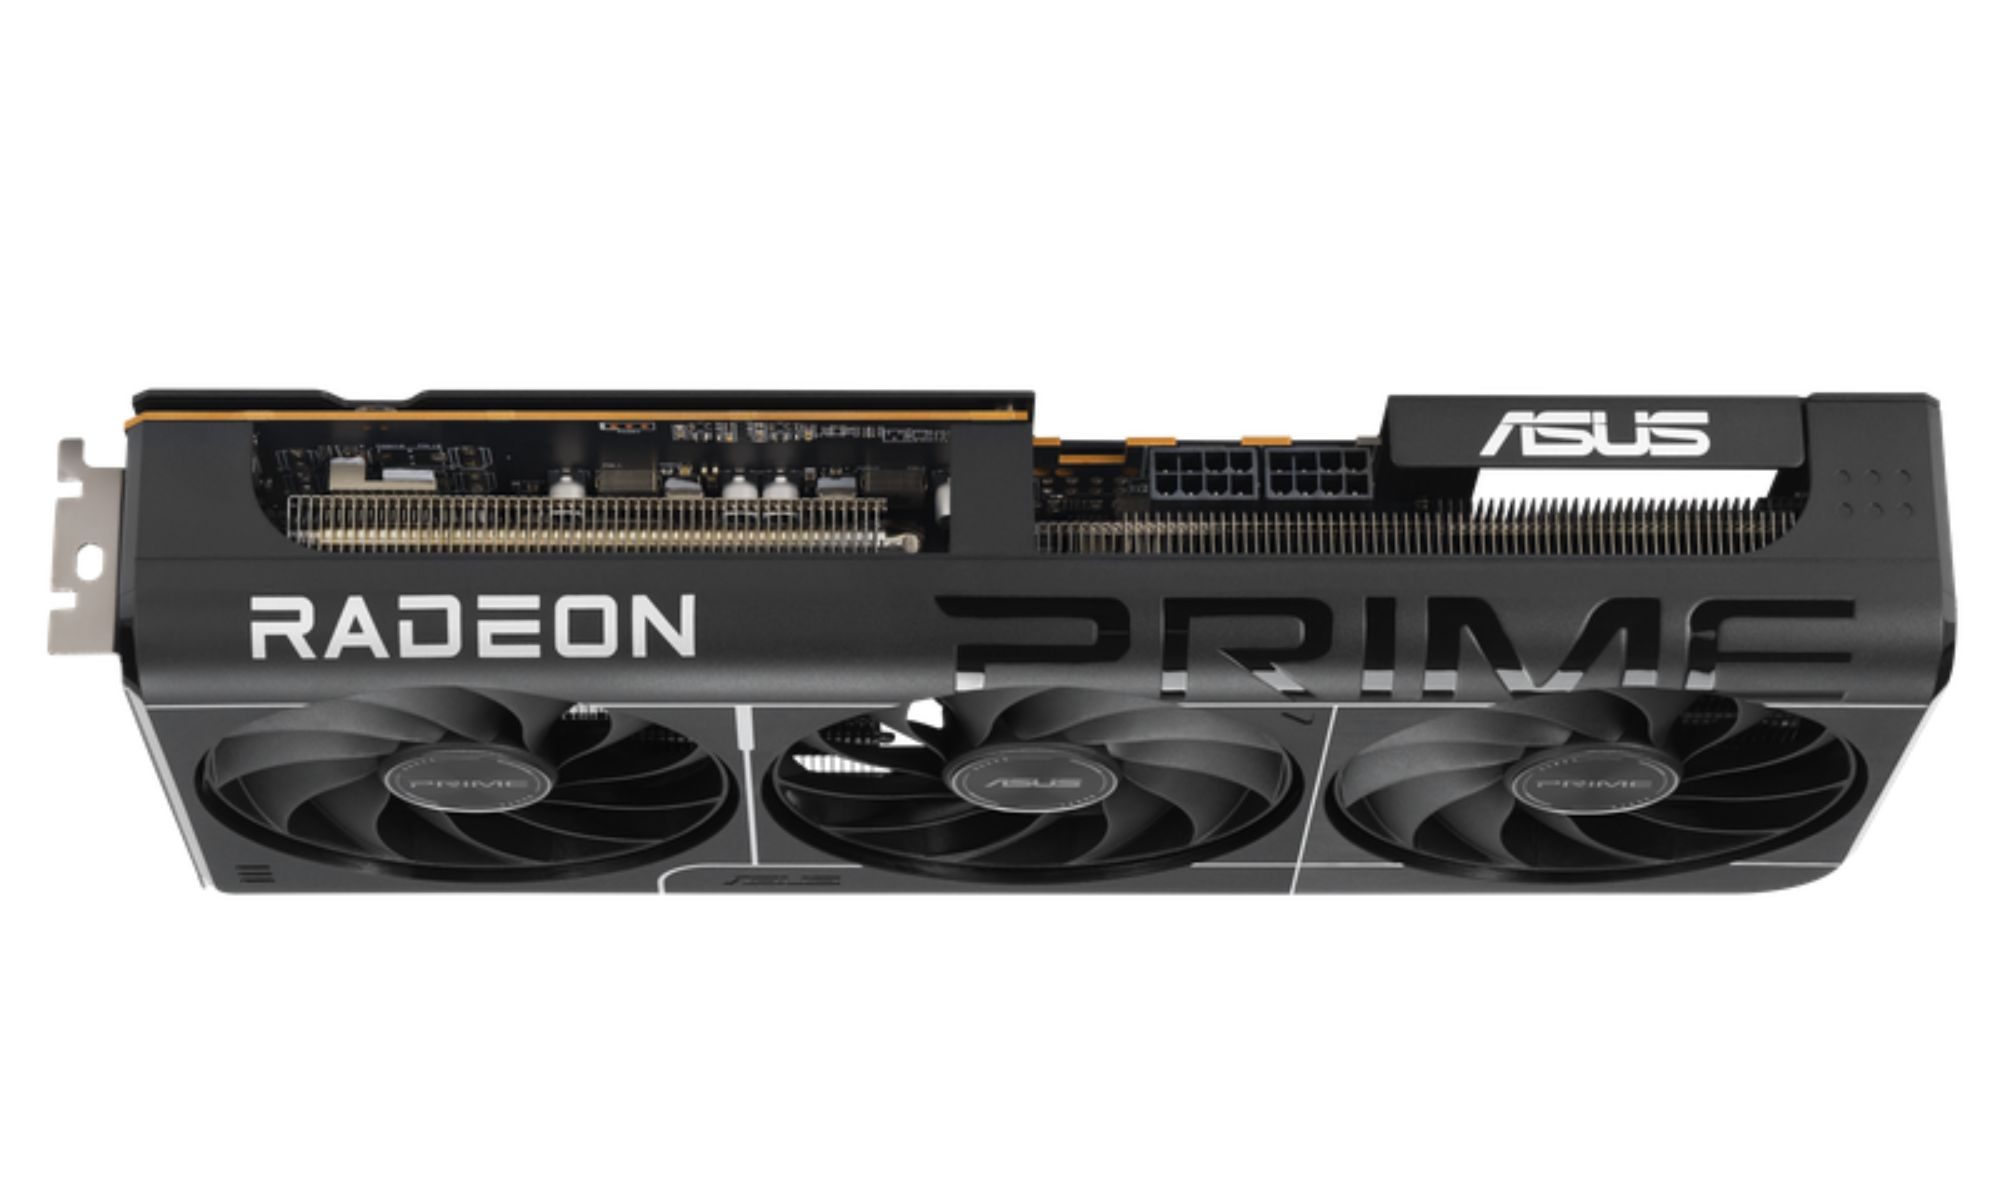
The ASUS Prime Radeon RX 9070 XT OC Edition takes much of the same performance proposition and puts it into a smaller package. It retains 16GB of GDDR6 and is built for 1440p and 4K gaming, but its 2.5-slot design gives compact builds more breathing room. Its OC mode reaches up to 3030 MHz boost and 2480 MHz game clock, while Axial-tech fans, a phase-change GPU thermal pad and dual-ball bearings handle the cooling.
The distinction between TUF and Prime is therefore less about raw performance than the space available inside the case. TUF gives the cooling system more room to work; Prime gives the builder more room to work around the GPU. For a large enthusiast build, TUF’s substantial cooler is an easy trade. In a more compact system, Prime’s smaller footprint can matter considerably more.
Gaming and AI workloads call for different priorities
Not every demanding GPU workload is a gaming workload. A card that makes sense for high-refresh 1440p or 4K gaming can have very different strengths from one designed to run large AI models locally, and the difference becomes particularly important once memory capacity enters the equation.
The ASUS Turbo Radeon AI Pro R9700 is built for that second category. Its 32GB of GDDR6 memory, 256-bit memory interface and bandwidth of up to 640GB/s are aimed at workloads that can quickly outgrow the memory available on a conventional gaming card. The card is designed for local LLMs, Stable Diffusion and Flux, AI development, content creation and other memory-heavy compute tasks.
Advertisement
Its specifications are tailored accordingly. The card uses RDNA 4 with 128 AI accelerators and up to 1,531 TOPS of INT4 performance, while PCIe 5.0 support and a 2-slot design make it suitable for dense multi-GPU workstation configurations. Its cooling system is also designed around sustained compute rather than short bursts of gaming, combining a diecast shroud and backplate with a wave-pattern design that ASUS says can reduce memory temperatures by up to 16%.
For a gaming PC, the RX 9070 XT and the other Radeon gaming cards make more sense because their strengths are aligned with that workload. The Turbo Radeon AI Pro R9700 becomes the more relevant choice when the machine is expected to handle local AI, large models or sustained GPU compute, where 32GB of VRAM and dedicated AI capability can matter far more than gaming-oriented specifications.
1440p gaming does not always require the biggest card
The step down from the higher-end gaming cards does not mean stepping away from serious 1440p performance. The mid-range options in this lineup are aimed at systems where smooth gaming matters, but power consumption, physical size and overall build balance deserve more attention.
ASUS
With 12GB of VRAM and an OC mode reaching up to 2880 MHz boost and 2300 MHz game clock, the Prime Radeon RX 9070 GRE EVO OC Edition is built around that balance. Its 2.5-slot design measures 304 × 126 × 50mm, making it slightly smaller than the Prime RX 9070 XT. Lower power consumption within the 9070 tier also makes the EVO a practical fit for a build where the GPU does not need to dominate the entire system.
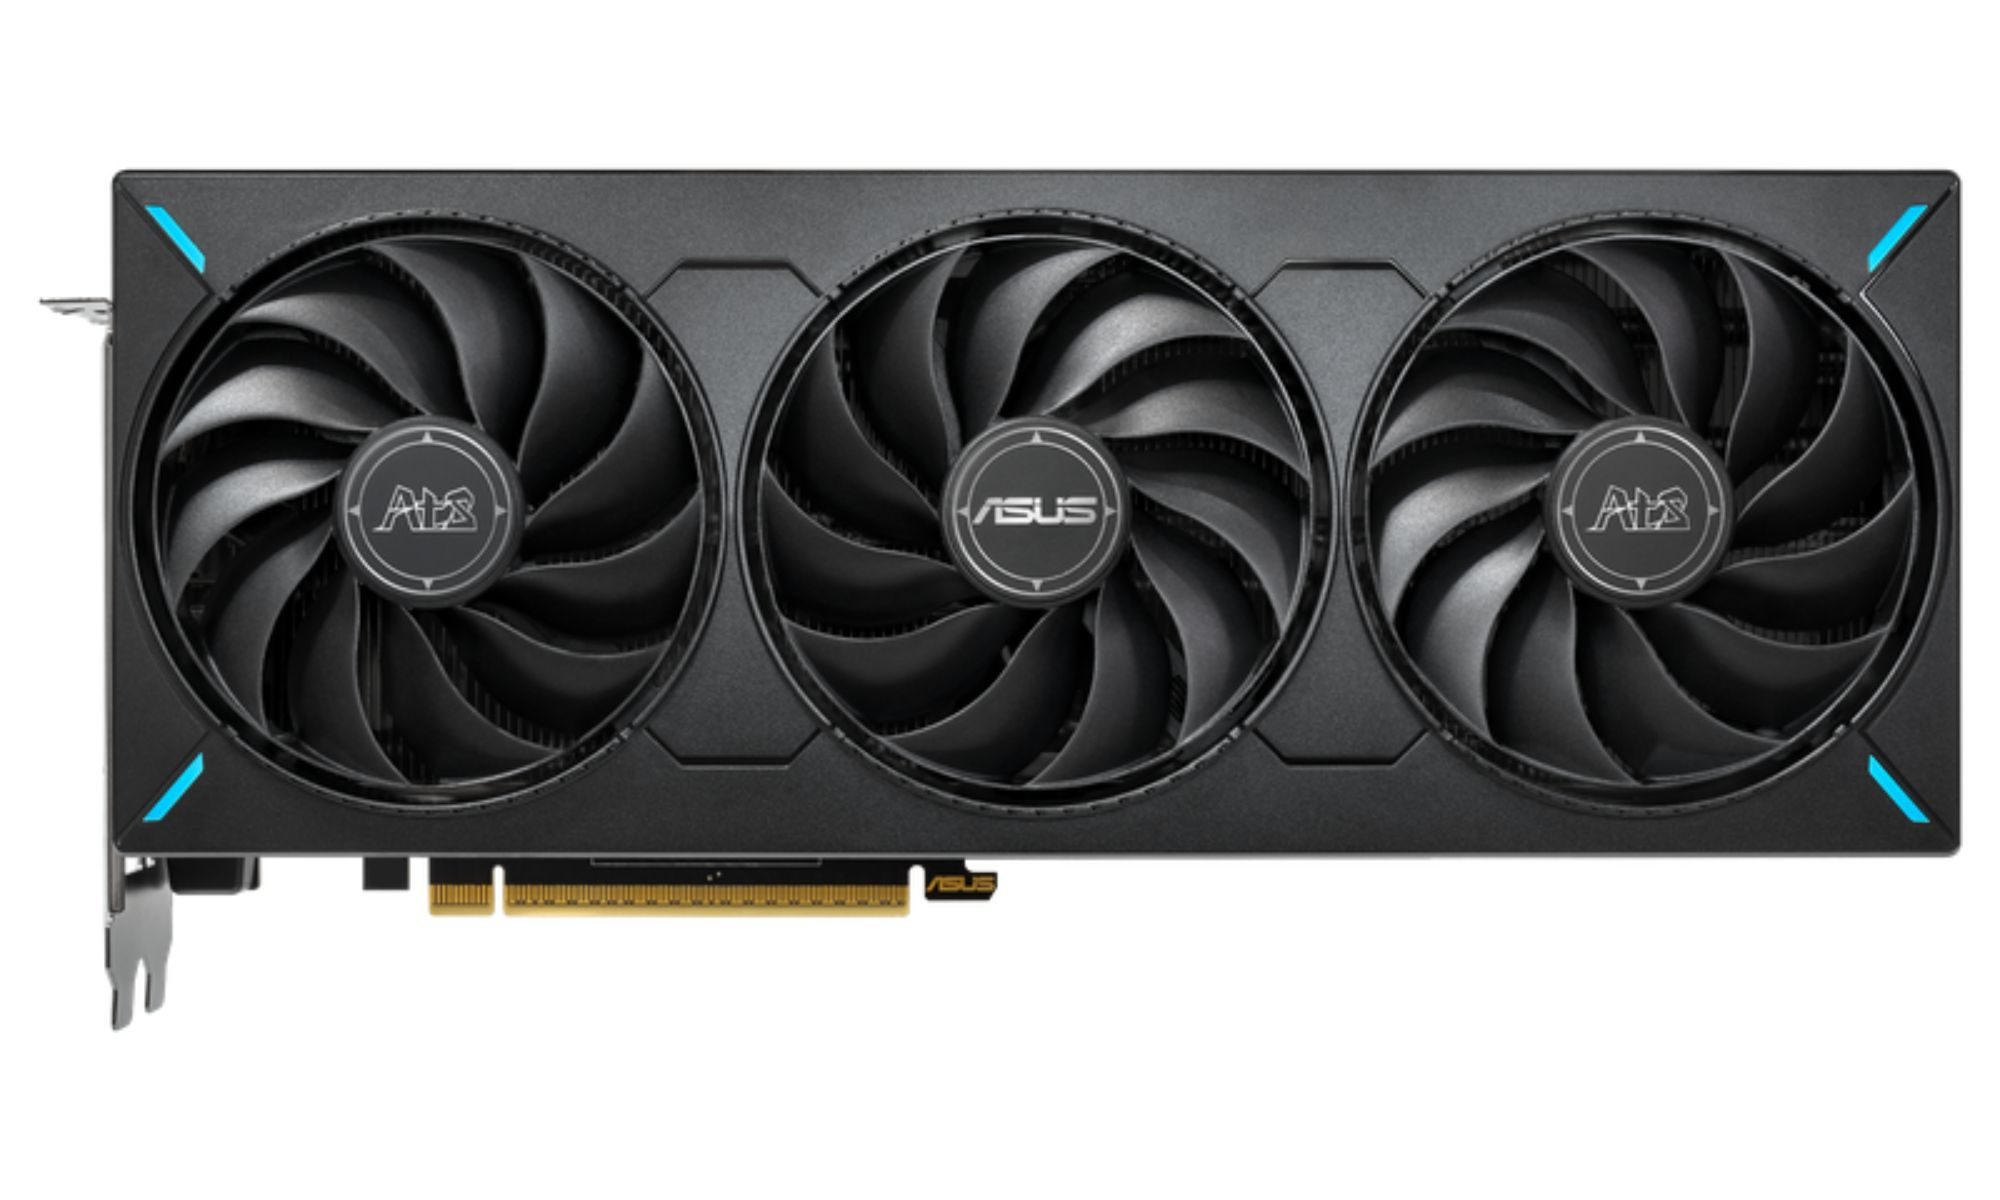
A similar approach carries over to the ATS Radeon RX 9070 GRE OC Edition, which reaches the same 2880 MHz boost and 2300 MHz game clock figures and measures 305 × 126 × 50mm. Both cards use Axial-tech fans, a phase-change GPU thermal pad, dual-ball bearings and 0dB technology, so there is little value in repeating the same cooling specification list for each model.
Advertisement
ASUS
For a 1440p gaming PC, these cards occupy a useful middle ground. They offer the performance needed for that resolution without moving into the larger footprint and higher-end positioning of the RX 9070 XT, making them worth considering when the rest of the system needs to stay compact and balanced.
When size and design become part of the decision
ASUS
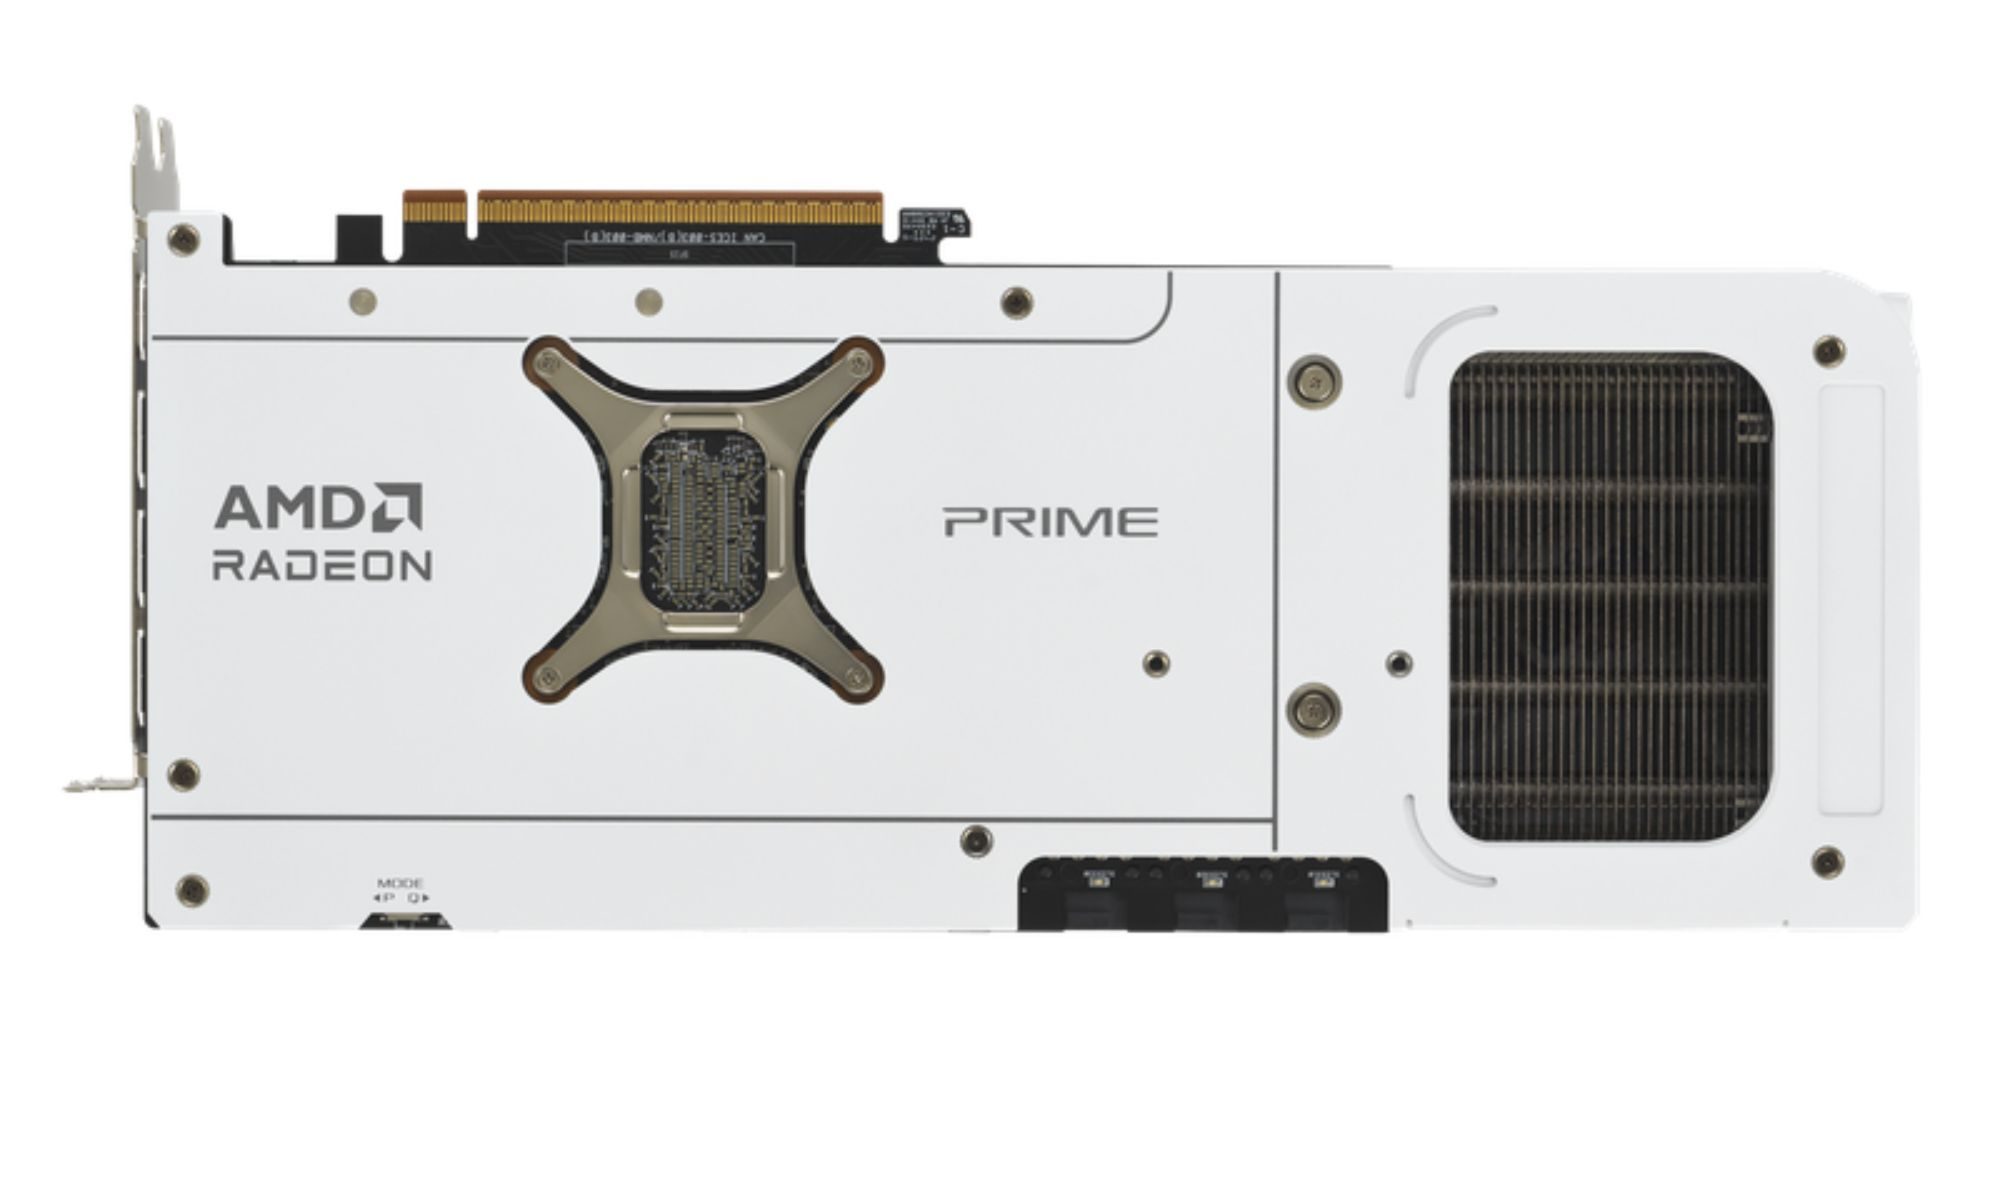
Physical compatibility is not always about fitting the largest GPU into the smallest case. In some builds, the graphics card also has to work with the visual language of the rest of the system. ASUS offers a white version of the Prime Radeon RX 9070 XT for precisely that kind of build, retaining the same 2.5-slot format as the standard Prime model.
There is no need to treat the white edition as a different performance tier. Its appeal is the white finish and sleek design, while the underlying cooling and performance proposition remains broadly aligned with the standard Prime RX 9070 XT.
A similar white edition is also available for the Radeon RX 9060 XT, giving buyers building smaller or more affordable systems another way to keep the graphics card consistent with an all-white setup.
Smaller builds still have options
ASUS
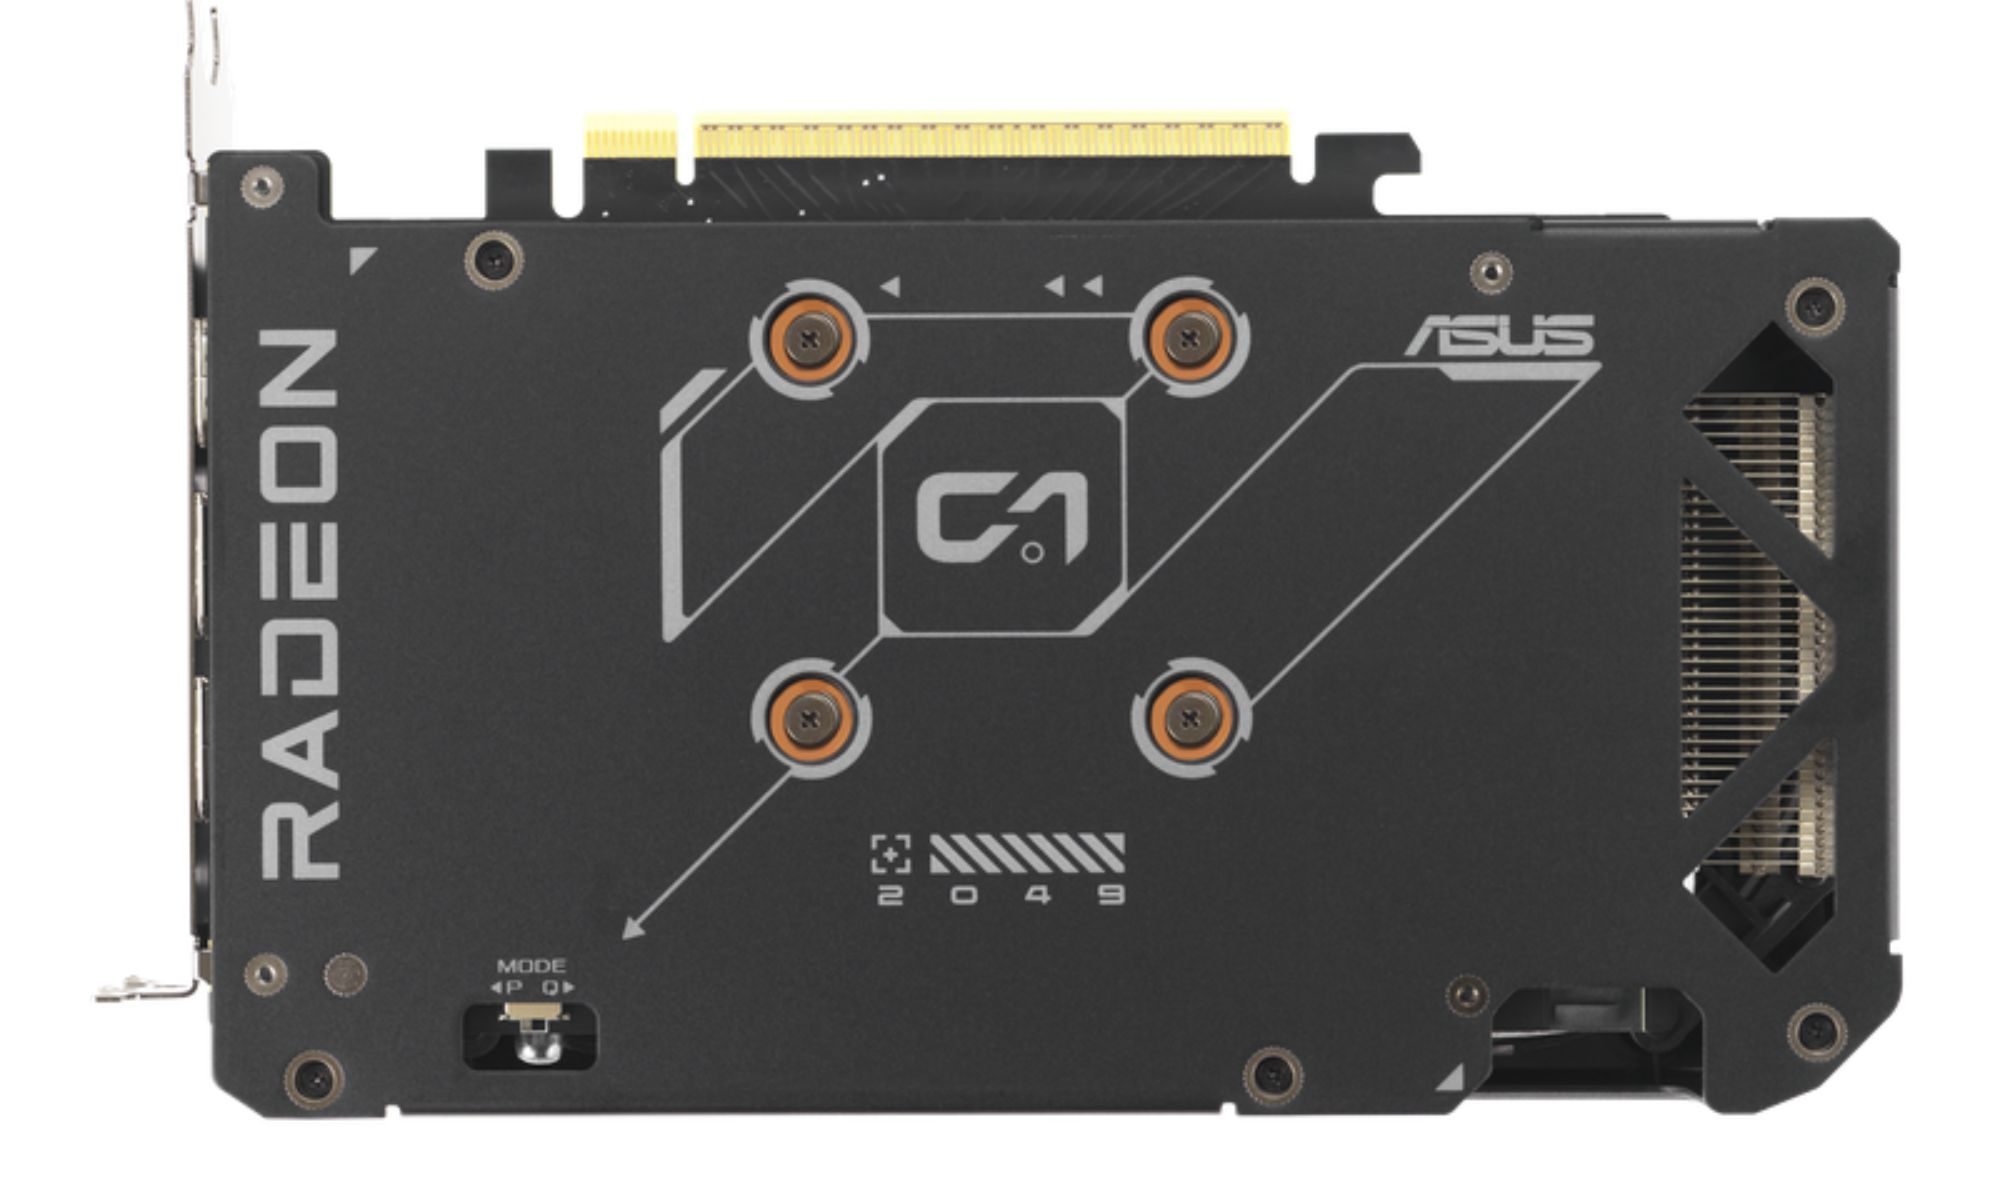
A compact PC does not necessarily mean settling for a compromised graphics card. The ASUS Dual Radeon RX 9060 XT 16GB GDDR6 is aimed at buyers who need to make better use of limited space, including those building in smaller form factor cases.
Its 2.5-slot design is intended to balance compatibility with cooling, while the Axial-tech fan design uses a smaller hub and longer blades to maintain airflow through the card. 0dB technology also allows the fans to remain off during lighter workloads, while dual-ball bearings are designed for long-term durability.
In a compact build, those dimensions can have consequences beyond the graphics card itself. A GPU that occupies less space leaves more room to work around adjacent components and makes overall component selection less restrictive. That makes the Dual Radeon RX 9060 XT a practical choice when building around a smaller chassis is the priority, rather than trying to squeeze a larger card into a case that was never designed for it.
Advertisement
GPU control does not end when the card is installed
ASUS also has a software layer that runs across much of this lineup. GPU Tweak III provides access to OC and Silent modes, fan controls, thermal settings and system monitoring, allowing users to adjust the behaviour of the card rather than treating its factory configuration as fixed. Profiles can store preferred voltage and clock settings, while the hardware monitor can track fan RPM and system power metrics.
Dual BIOS provides another level of control on the supported cards, allowing users to switch between Quiet and Performance profiles. The Turbo Radeon AI Pro R9700 is the exception in this lineup, with the supplied ASUS brief specifying that Dual BIOS is not available on that model.
The result is a lineup that is easier to understand when viewed through the PC being built rather than through a simple hierarchy of numbers. TUF is about substantial gaming performance and cooling. Prime RX 9070 XT makes high-end performance easier to fit into a compact build. Prime White is for buyers who want the graphics card to complement the rest of the system. The two RX 9070 GRE cards occupy the 1440p middle ground, while the RX 9060 XT brings dedicated graphics into smaller systems. Turbo AI Pro R9700 takes the conversation beyond gaming altogether.
Explore the ASUS Radeon graphics card range to compare the models and find the card that fits your build, workload and priorities.
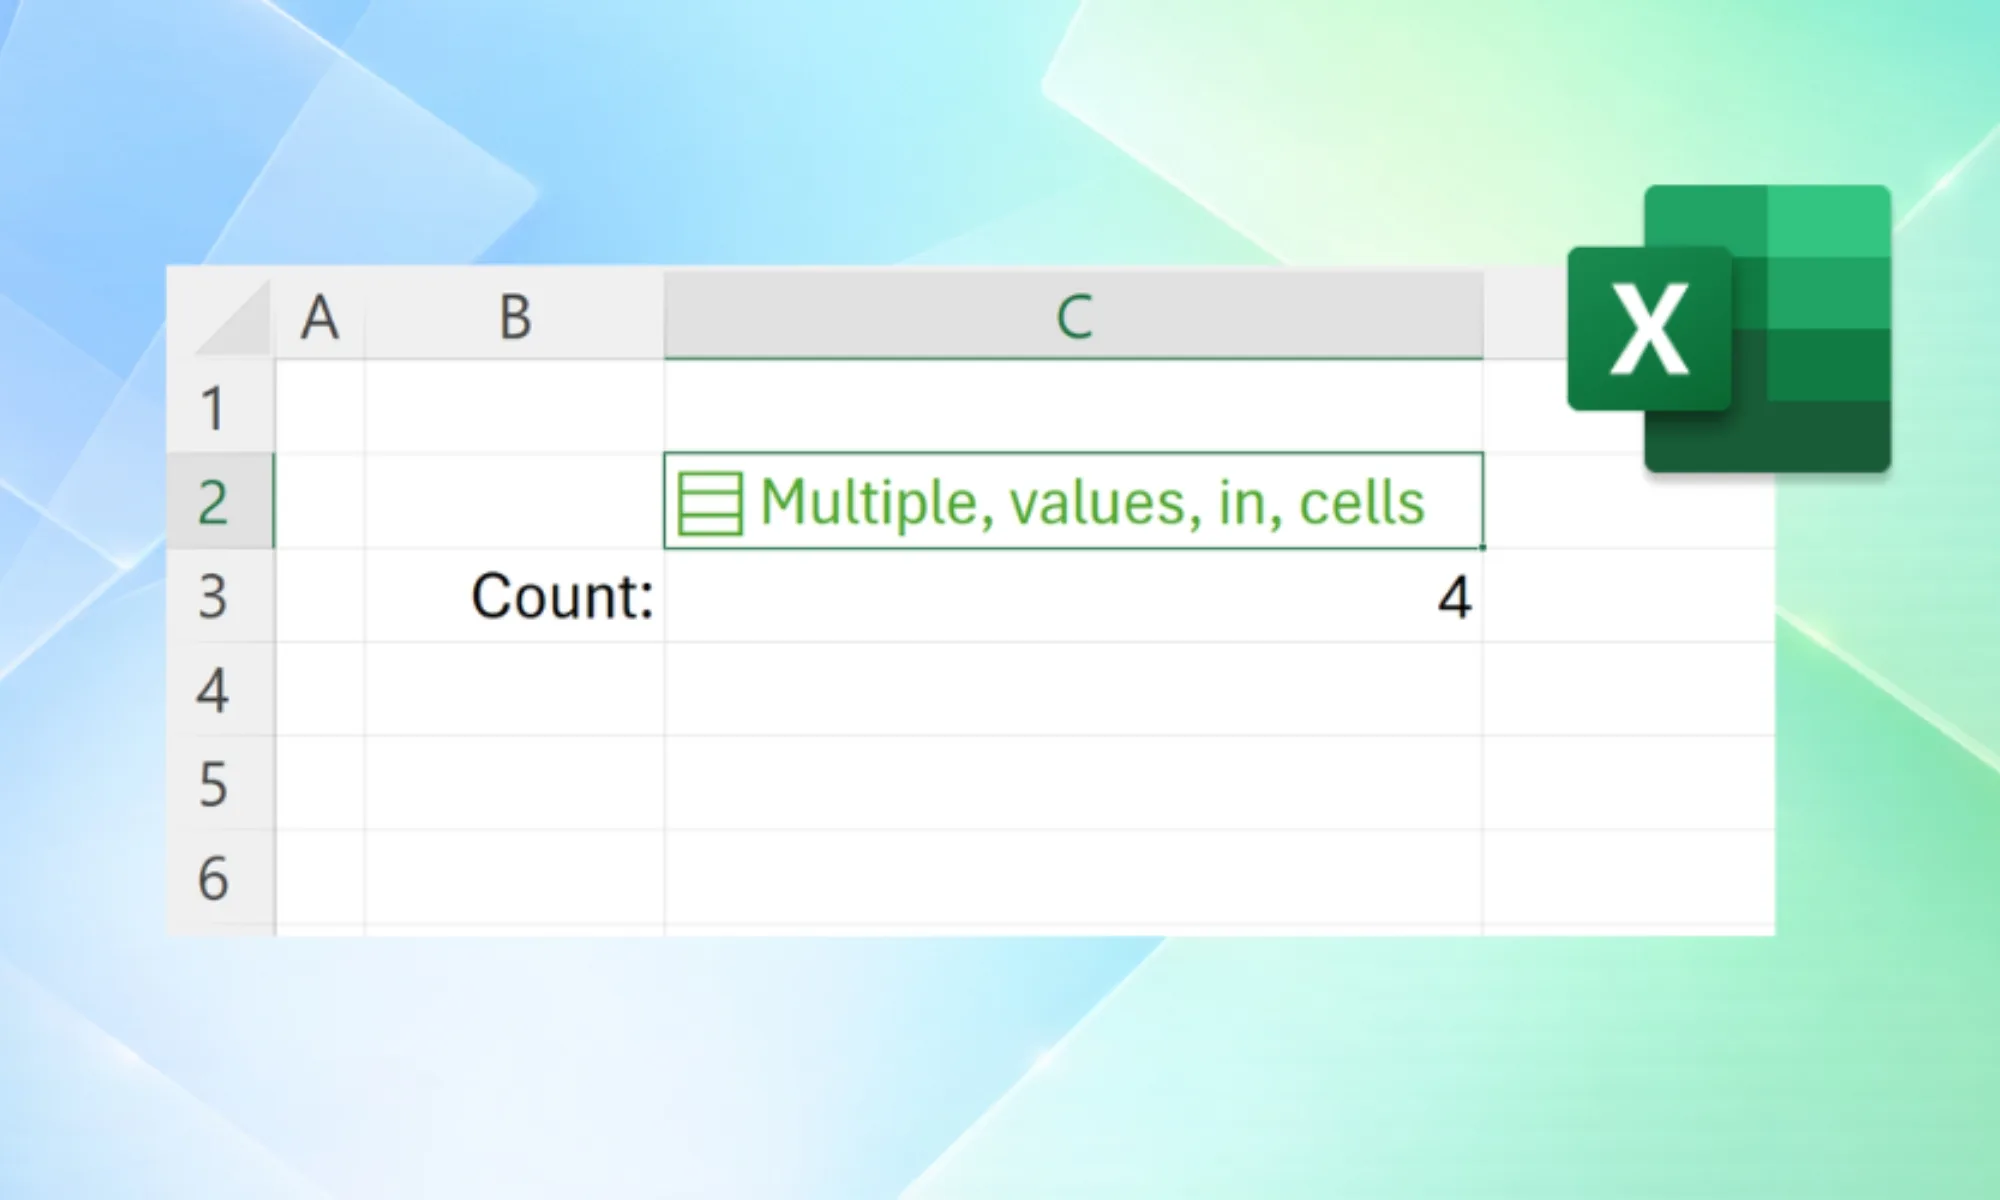
Microsoft is changing one of Excel’s most familiar rules: a cell no longer has to contain just one value. The company has introduced lists, arrays in cells and nested arrays, giving users new ways to keep multiple pieces of information together without turning them into a single block of text.
The features are currently rolling out as previews to Excel for Windows and Mac Beta Channels. Microsoft says the behaviour may change before general availability and recommends against using the features in important workbooks at this stage.
Excel lists make multiple values easier to manage
The simplest part of the update is the new Lists feature. Instead of putting several values into separate cells or combining them into ordinary comma-separated text, users can store multiple individual values inside one cell.
For example, a project could have several owners listed in a single cell, while a survey response could contain multiple appointment times. With lists, Excel keeps those entries separate internally, allowing users to filter individual values and use them in calculations.
Advertisement
Microsoft
Creating a list involves selecting Insert > List or pressing Ctrl+J, then entering or pasting items separated by commas or semicolons, depending on regional settings. Users can later edit individual entries by double-clicking the cell or pressing F2.
The feature also changes how filtering works. Instead of treating a comma-separated cell as one large piece of text, Excel can filter by individual items. Referencing a list can also return all its values, allowing them to spill into separate cells when needed.
That could make spreadsheets containing project assignments, survey responses or other multi-value data considerably easier to organise.
Arrays bring a much bigger change to spreadsheets
Microsoft is also introducing arrays directly inside cells, including nested arrays. Arrays can now exist as values or formula results inside a single cell and can have different sizes and shapes. Users can also wrap spilling formula results in braces to keep the entire result inside one cell.
Nested arrays take this further by allowing arrays to exist inside other arrays. Microsoft says formulas that previously returned truncated results or a #CALC! error in some array-of-array situations can now return the complete nested result.
Advertisement
To work with these structures, Excel is gaining four new functions: FLATTEN, HAS, HASANY and HASALL. FLATTEN can remove levels of nesting, while the HAS functions can check whether a particular value, some specified values or all specified values appear within an array.
Unsplash
For power users, the change could open up new spreadsheet designs. Microsoft demonstrates a run tracker where different numbers of kilometre splits can be stored in the same row while statistics are calculated alongside them.
There are still limitations. Conditional formatting, data validation, charts, PivotTables, Power Query and Find & Replace do not yet fully support list and array values. The features currently require specific Beta Channel builds, and nested-array calculations require Compatibility Version 3.
For now, Microsoft is treating this as a preview rather than a finished Excel feature. But if the rollout goes smoothly, the humble spreadsheet cell is about to become considerably more capable.
Panasonic Let’s Note SC7 weighs just 919 grams but passed drop tests from both 76 and 30 cm
The chassis meets the US military’s MIL-STD-810H toughness standard
Battery testing returned nearly 23 hours of continuous everyday use
Japanese manufacturers have long built a reputation for producing remarkably light business notebooks, with some models weighing under a kilogram entirely.
Panasonic has now expanded that lightweight lineup with the Let’s Note SC7, a compact notebook weighing just 919 grams total.
The company also carried over its distinct circular wheel pad, letting users scroll by tracing a finger along the pointing device’s outer rim.
Latest Videos FromTechRadar
Advertisement
Packs a full-day power into a small frame
The SC7 features a 12.4-inch display with a 3:2 aspect ratio, taller than the widescreen format common on most rival laptops today, showing more vertical content at once, improving efficiency when editing spreadsheets, documents, or browsing lengthy web pages daily.
Inside sits an Intel Core Ultra 5 325 processor paired with a 47 TOPS neural processing unit for on-device AI tasks.
The low-end version of this device comes with 16GB of LPDDR5X RAM and 512GB of internal storage – however, users can choose models with 32GB or 64GB of RAM and 1TB or 2TB of internal storage depending on the buyer’s needs.
Let’s Note SC7 ships with Wi-Fi 7, Bluetooth 5.4, two Thunderbolt 4 ports, two USB 3.2 Gen 1 ports, HDMI, and Gigabit Ethernet.
Sign up to the TechRadar Pro newsletter to get all the top news, opinion, features and guidance your business needs to succeed!
Under the hood, this notebook uses a 56Wh removable battery, which is attached with two screws rather than a latch.
Advertisement
According to Panasonic, this battery lasts roughly 17.7 hours during video playback and 32.4 hours in idle mode under JEITA 3.0 standards, and charging through the bundled 65W USB PD adapter reaches about 46% capacity within 30 minutes.
A magnesium alloy body measuring 273.2 x 208.9 x 19.9 mm combined with internal ribbing keeps the notebook sturdy, though it still appears slim.
Advertisement
Sturdiness, software, and benchmark results that support the design
Panasonic subjected the SC7 to internal drop tests from 76 centimeters and 30 centimeters across 26 separate directions during development.
The chassis also passed a 100 kgf pressure vibration test and met the US Department of Defense’s MIL-STD-810H toughness standard – few compact business notebooks built outside Japan undergo this level of physical stress testing before reaching commercial release.
The built-in NPU meets requirements for Microsoft‘s Copilot+ PC program, enabling both cloud-based and local artificial intelligence processing directly on device.
PCMark 10 testing showed the processor performing at full capacity, aided by Panasonic’s proprietary MaxPerformer heat and power tuning system.
Advertisement
On Geekbench 7, the Let’s Note SC7 scored 2354 points on single-core tasks and 10437 points on multi-core benchmarks.
Battery testing under PCMark 10’s Modern Office profile returned roughly 22 hours and 59 minutes of continuous everyday use.
For security, this device includes facial recognition through an infrared camera alongside a fingerprint sensor built into the power button.
It is currently available in gray, black, rose, and deep indigo, but there is no indication that this device will sell outside Japan.
Advertisement
All these capabilities do not come for cheap, as Panasonic lists this device for 298,100 yen, which is about $1,880.
Ripple effect: Microsoft may be backing away from the Copilot+ PC branding, but it’s doubling down on the bigger idea behind it: turning AI into a layer that actively runs your computer and gets work done for you. Its latest Copilot overhaul pushes that vision further than before, combining Office, coding tools, and autonomous agents into what CEO Satya Nadella calls a “new OS for work.” Public testing begins in the coming weeks.
Microsoft recently unveiled a major overhaul for Copilot’s business tools. The new suite hands the AI assistant more control in Office, embeds GitHub Copilot’s functionality into professional toolchains, and automatically coordinates tasks between team members.
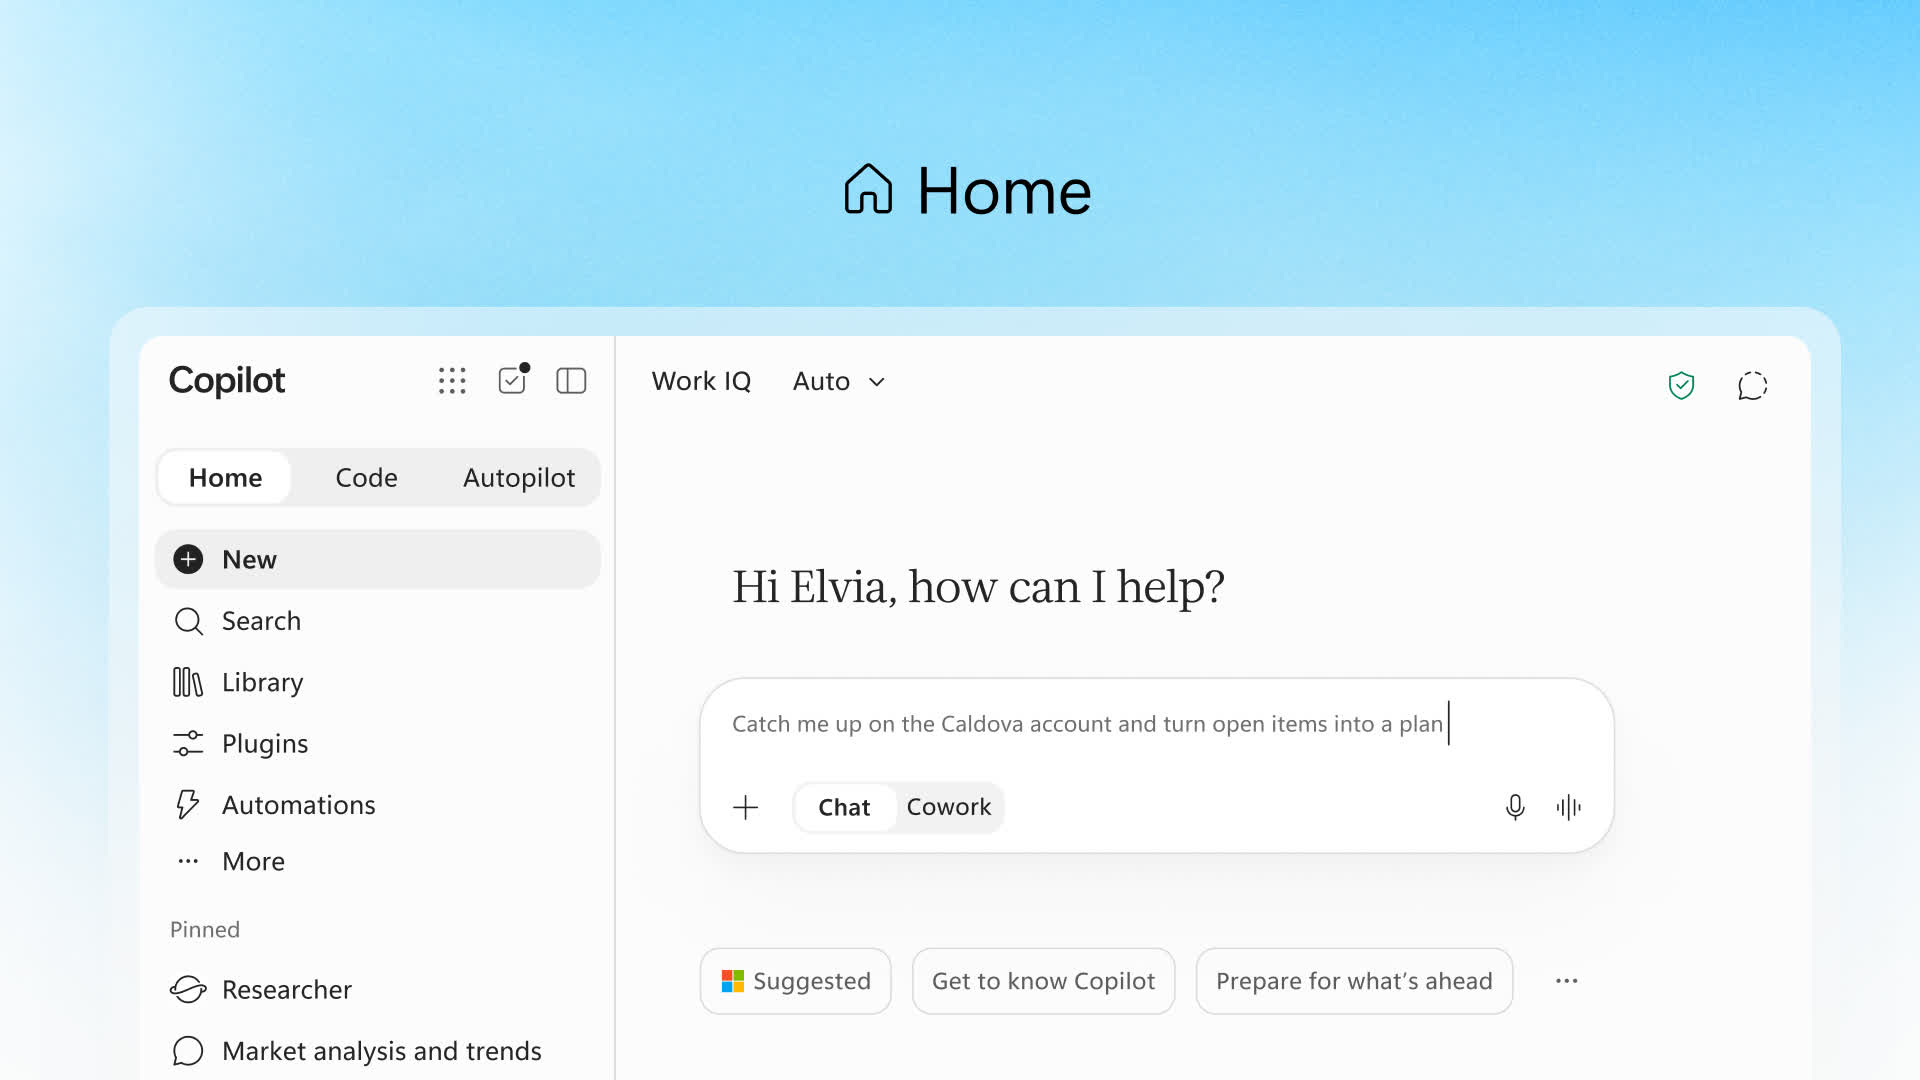
The new Copilot implementation, which Microsoft CEO Satya Nadella calls a “new OS,” consists of several parts. One of them, simply called Home, lets users chat with Copilot as it examines files to offer recommendations on how it can help. Home can also take over Office 365 apps such as Word, Excel, and PowerPoint to automatically draft files for users to edit.
Another tool, Code, builds apps based on natural-language prompts using the same tools as GitHub Copilot. Microsoft claims that Code uses Microsoft IQ to maintain contextual knowledge of users’ work environments beyond what it currently sees onscreen.
Advertisement
Lastly, Autopilot, a rebrand of Scout, offers the highest level of automation. After users provide it with a role and an objective, Autopilot handles various tasks such as scheduling meetings, following up with contacts, watching channels, starting and resuming projects, and more, all without further human input. The cloud-hosted feature also works 24/7, working across Teams, Outlook, documents, and other programs while remaining in constant contact with teammates.
Home and Code will enter Microsoft’s Frontier program in the coming weeks, while Autopilot will be available in private preview at the end of this month. Another aspect of Home, called Today, will enter private preview in October. Today aims to show users a unified information space with details from emails, Teams chats, meetings, and other sources while also drafting documents and proposing schedules.
Nadella’s “Copilot OS” claim sounds a lot like the supposedly defunct Project Aion, which would have become a separate OS built around Copilot running within an Edge shell. Users would operate apps and create documents by chatting with Copilot instead of controlling them directly. Although Microsoft might have shelved Aion, a video demonstration of the new Copilot update closely resembles certain aspects of it.
Advertisement
Notably, this latest push to embed Copilot in users’ systems follows an admission from Microsoft and Qualcomm that the Copilot+ PC brand has been abandoned, with the companies acknowledging that consumers simply don’t care about “AI PCs.” It remains unclear whether Home, Code, and Autopilot will be next in a growing trail of shelved AI initiatives such as Copilot+ PCs and Recall.
Oxford has let OpenAI use old texts from its Bodleian Library to train its AI models, according to internal papers seen by the Guardian. Ethan Penny and Dan Milmo broke the story on Saturday.
The papers say texts that OpenAI scanned at the library went into the firm’s training data.
Oxford made its deal with OpenAI public in March 2025. At the time, it said OpenAI’s tools would help scan rare texts so more students and scholars could read them. It did not say the texts would be used to train AI.
By June 2025, the Bodleian had sent OpenAI 125,000 scans of old PhD theses, the Guardian reported. They include theses written at European and US universities in the 19th and 20th centuries.
Advertisement
Notes from staff meetings, which the Guardian got through a freedom of information request, show some staff had doubts. They worried about harm to Oxford’s name and about the energy use of AI.
However, Oxford said the scans were small in scale, out of copyright and not exclusive to OpenAI. The library keeps the rights and will start to post the scans online in the next few months, a spokesperson said.
The spokesperson also said the AI training side had not been hidden. Scanning was Oxford’s main goal, but staff had been open that the texts would also be used to train models.
“With more than a billion people using this technology in everyday life, it’s important it reflects different cultures, histories and perspectives,” an OpenAI spokesperson told the Guardian.
Oxford is the only UK member of OpenAI’s NextGenAI group. Other members include Boston Public Library, Caltech, MIT and the University of Michigan.
Advertisement
The deal comes as AI firms buy printed books for slop-free training data, since the web is now full of AI-made text. Some buyers cut books apart to scan them, which has upset secondhand booksellers.
In August, 404 Media tracked a box of rare books to an Amazon site that scans and destroys books for AI. The Bodleian’s books stay whole under its deal, the Guardian reported.
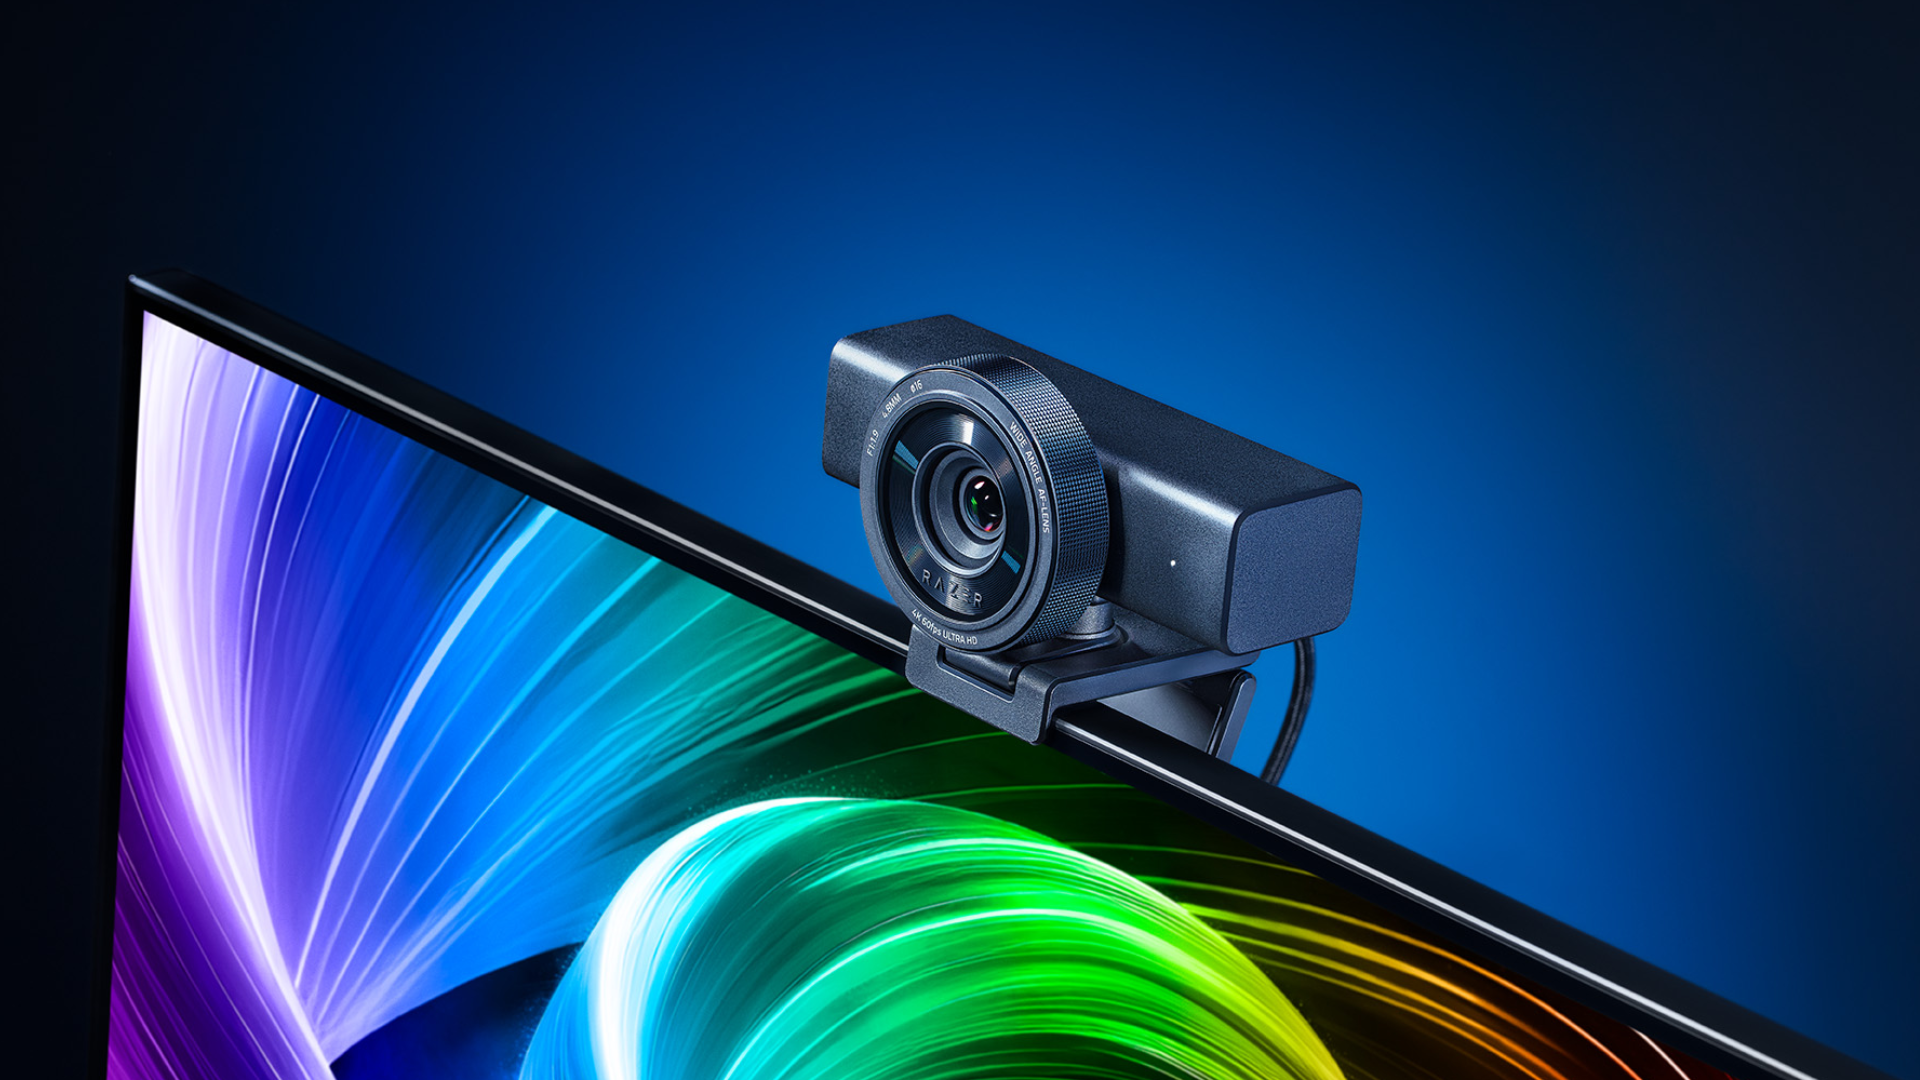
Razer’s new Kiyo V2 Pro webcam uses Sony’s 8.3-megapixel STARVIS 2 sensor and costs $300.
Sony’s STARVIS 2 sensor also enables the headline feature here: 4K video capture at up to 60fps, a specification most consumer webcams still limit to 1080p or 1440p once frame rates climb above 30fps.
Razer pairs that sensor with a lens capable of an f/1.9 aperture, a wider opening than most webcams offer and one that should improve low-light clarity while producing a stronger background blur behind the subject.
AI and imaging features
Beyond the optics, the Kiyo V2 Pro introduces automatic framing, a feature that uses pan, tilt and zoom to keep a speaker centred in the frame, similar to the tools Apple already offers on recent iPhones during FaceTime calls.
Advertisement
Razer has also carried over the one-click output enhancement feature from its microphone lineup, and the camera automatically adjusts exposure, white balance and noise levels to match whatever environment it sits in.
Advertisement
The Kiyo V2 Pro also captures ultra-high dynamic range footage that pulls out more shadow and highlight detail, and Razer has narrowed the field of view from 93 degrees on the original V2 to 86 degrees on the Pro model.
That narrower angle helps the sensor maintain sharper detail at the full 4K resolution and reduces the fisheye distortion that often appears at the edges of a wide-angle frame during video calls.
Advertisement
Software support for the webcam extends to Razer Synapse, which lets users manually fine-tune settings such as ISO and shutter speed rather than relying solely on the automatic modes built into the camera itself.
Razer ships the Kiyo V2 Pro with both a clamp for monitors and laptop lids and a universal tripod mount, alongside an integrated privacy shutter built to resemble a camera’s own shutter mechanism.
Availability and pricing
The webcam is available now through Razer.com and other retailers, and its $300 price places it among the pricier options in the current webcam market.
Razer has not confirmed a UK release date or local pricing for the Kiyo V2 Pro, though the webcam’s US launch suggests a wider rollout is likely to follow in the coming months.
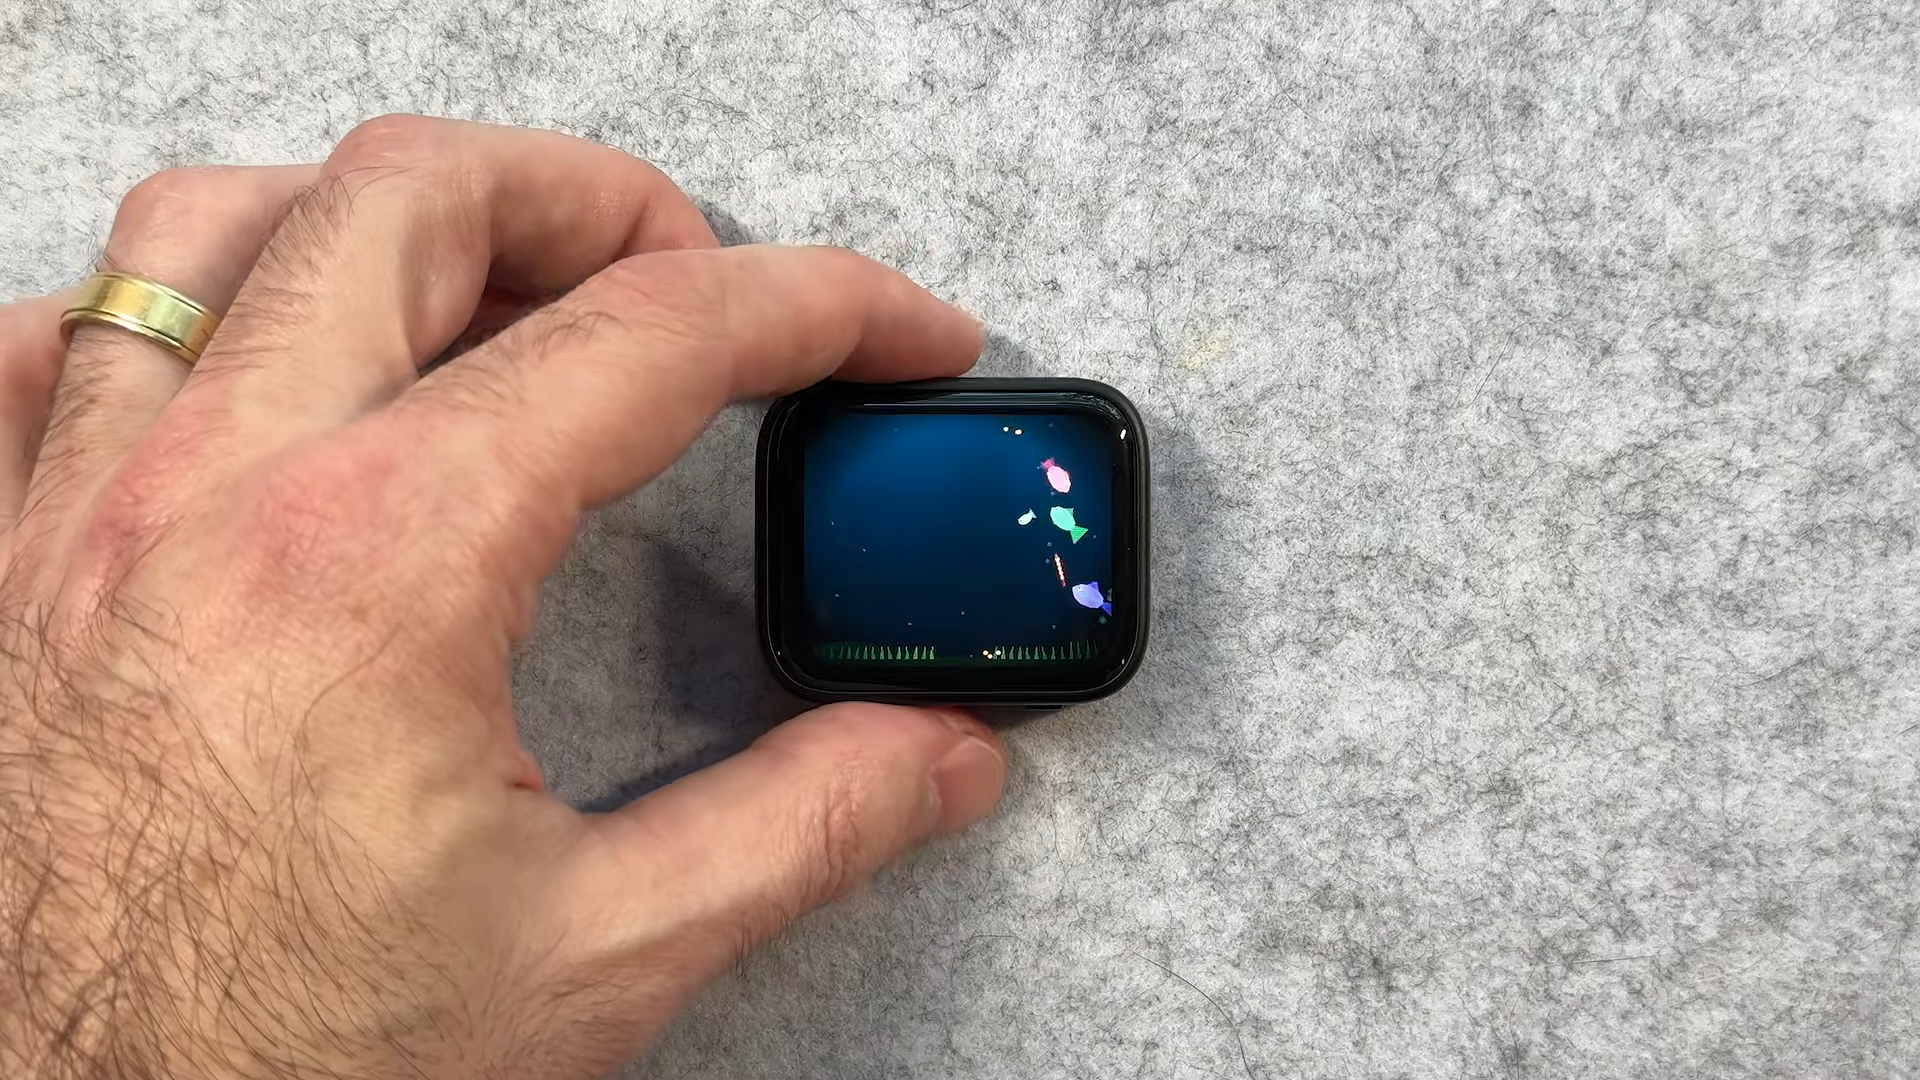
The concept behind Pocket Tank is relatively simple—it’s a small device that displays a virtual tank with a bunch of little fish swimming around inside. It’s based on the Waveshare ESP32-S3-Touch-AMOLED-1.8, which, if you’re wondering, is an ESP32-S3 with a 1.8″ screen attached, all wrapped up in a convenient plastic housing.
Thanks to the powerful microcontroller, there’s plenty of grunt on tap to run and display a small simulated fish tank. [StratoBuilds] whipped up a system wherein fish movement and animations are handled by regular code running at 25-30 fps, while the fish’s decision making is handled by a custom large language model that was condensed down to run on the ESP32 itself. As the fish swim around the tank, the situation is observed by the LLM and the fish’s current goals are changed accordingly depending on what’s going on. Much like a Tamogotchi, there are regular maintenance tasks for the user to handle, too, like cleaning the tank and feeding the fish to keep them alive.
Advertisement
The blog post and YouTube video do a great job of explaining the project; files are on GitHub for those that wish to tinker more directly. It’s funny, because when we normally look at fish tanks, we’re talking about real ones.
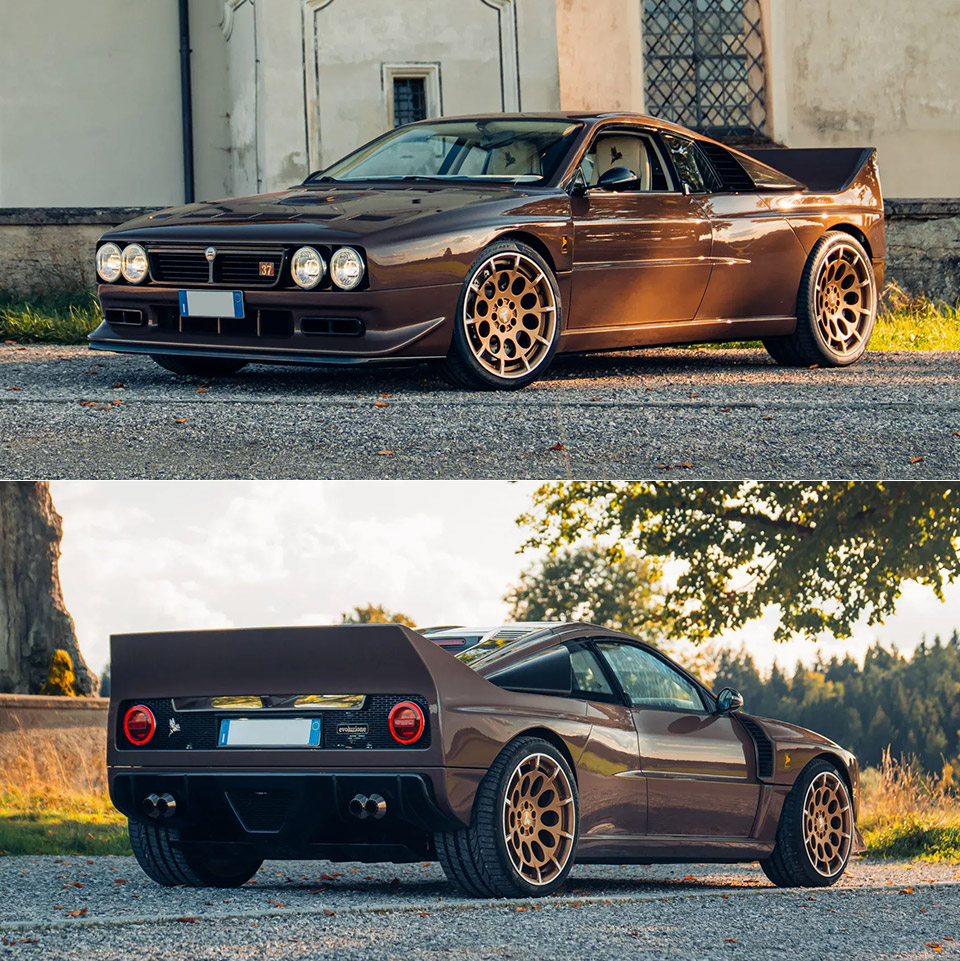
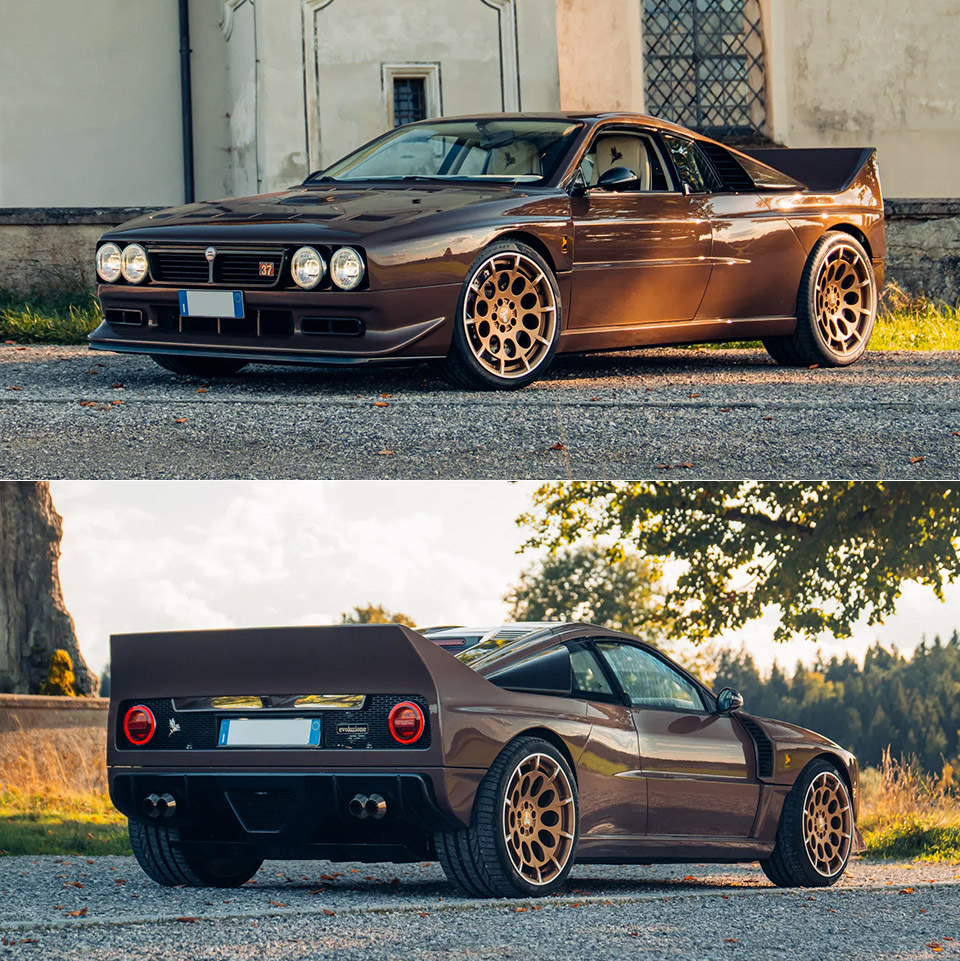
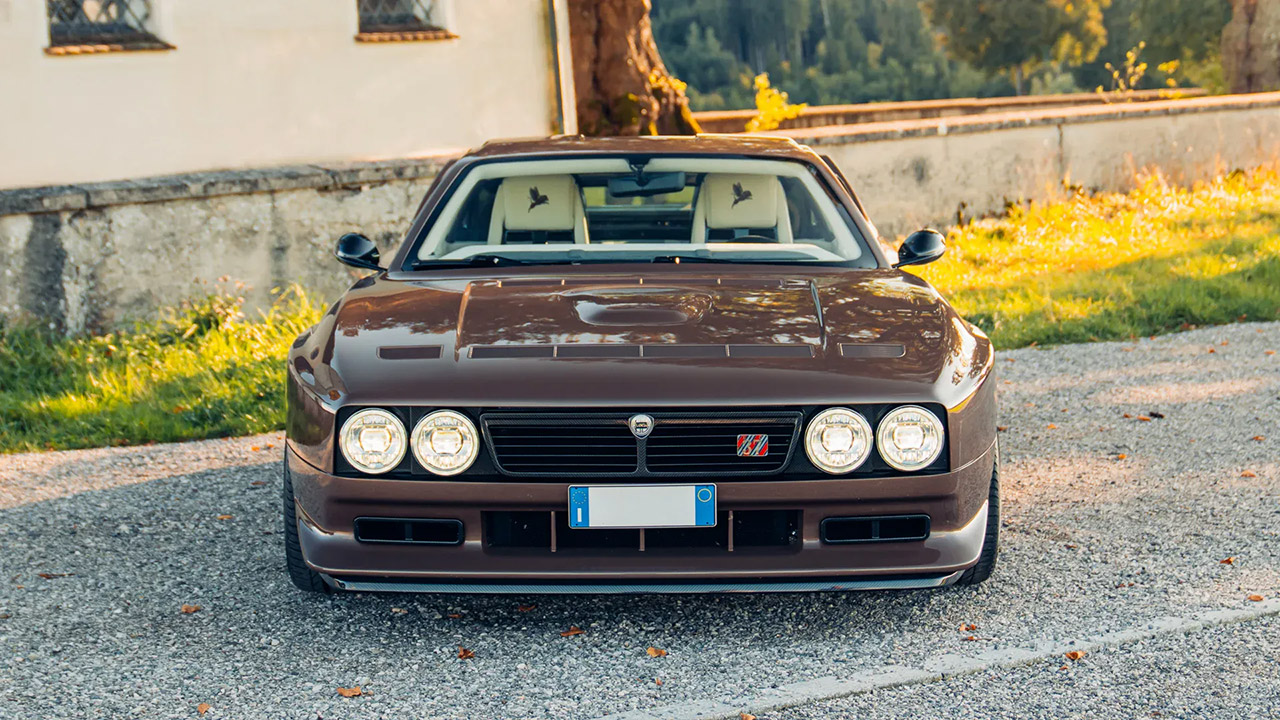
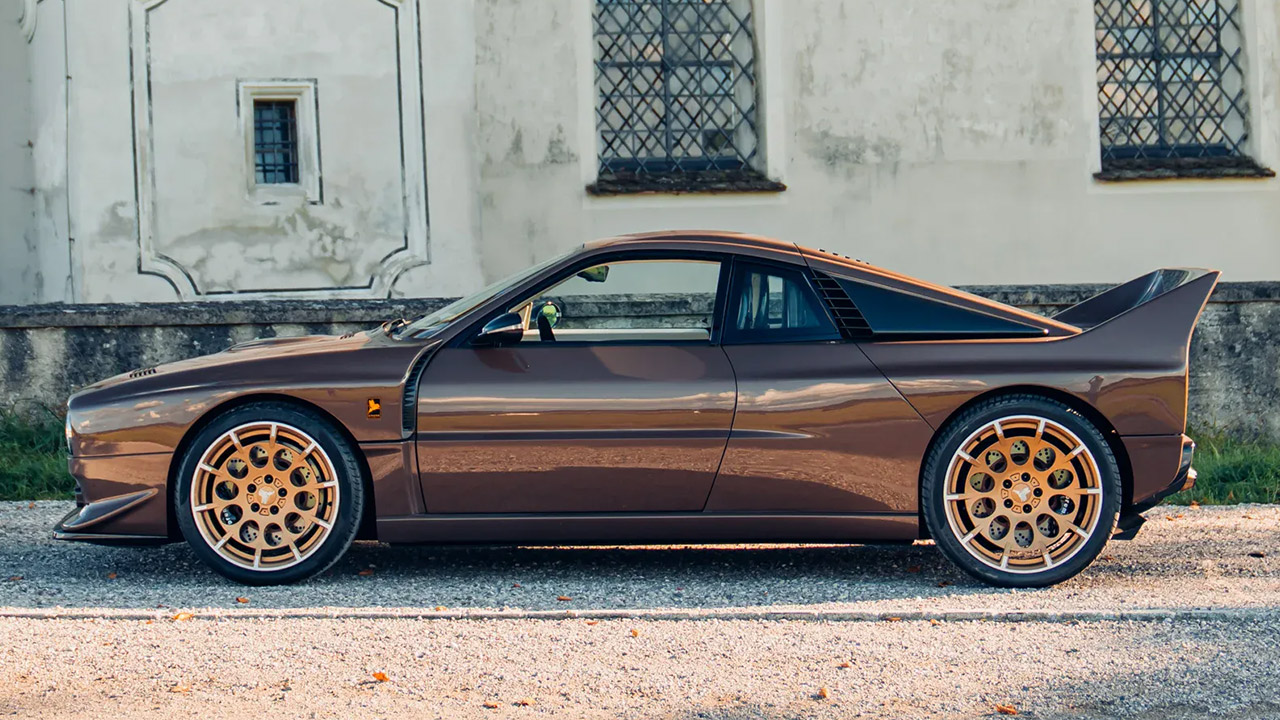
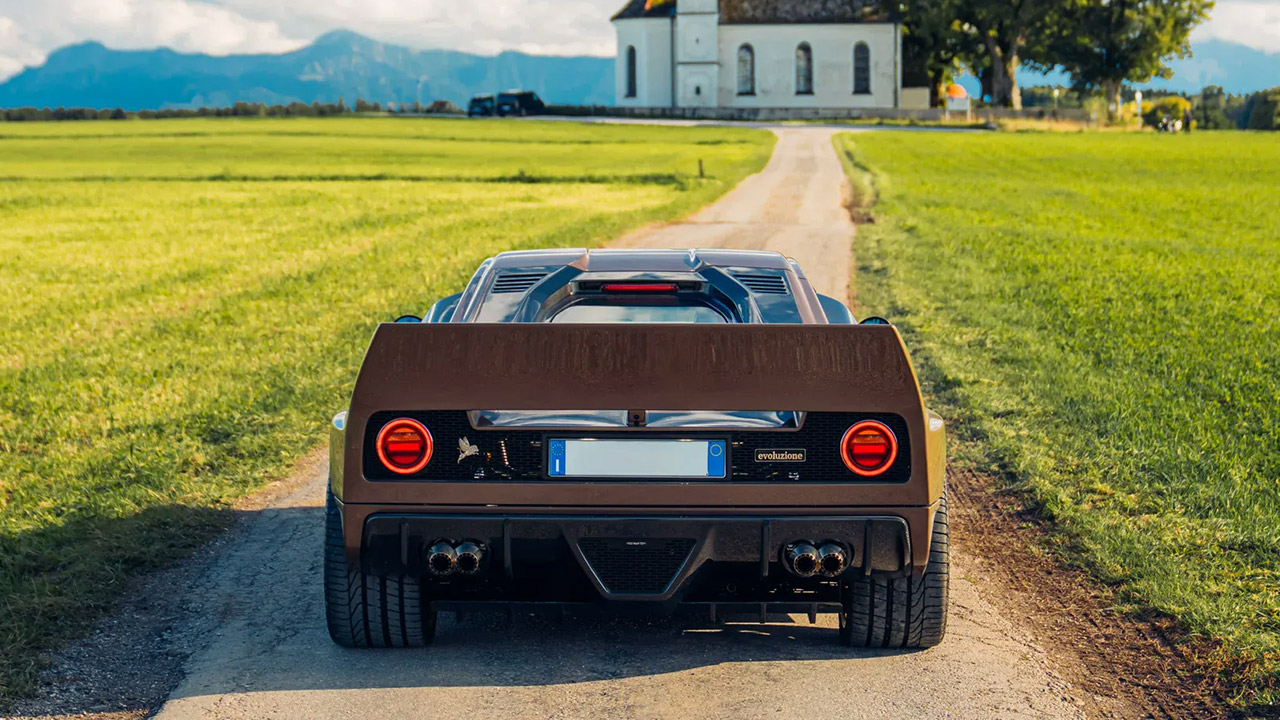
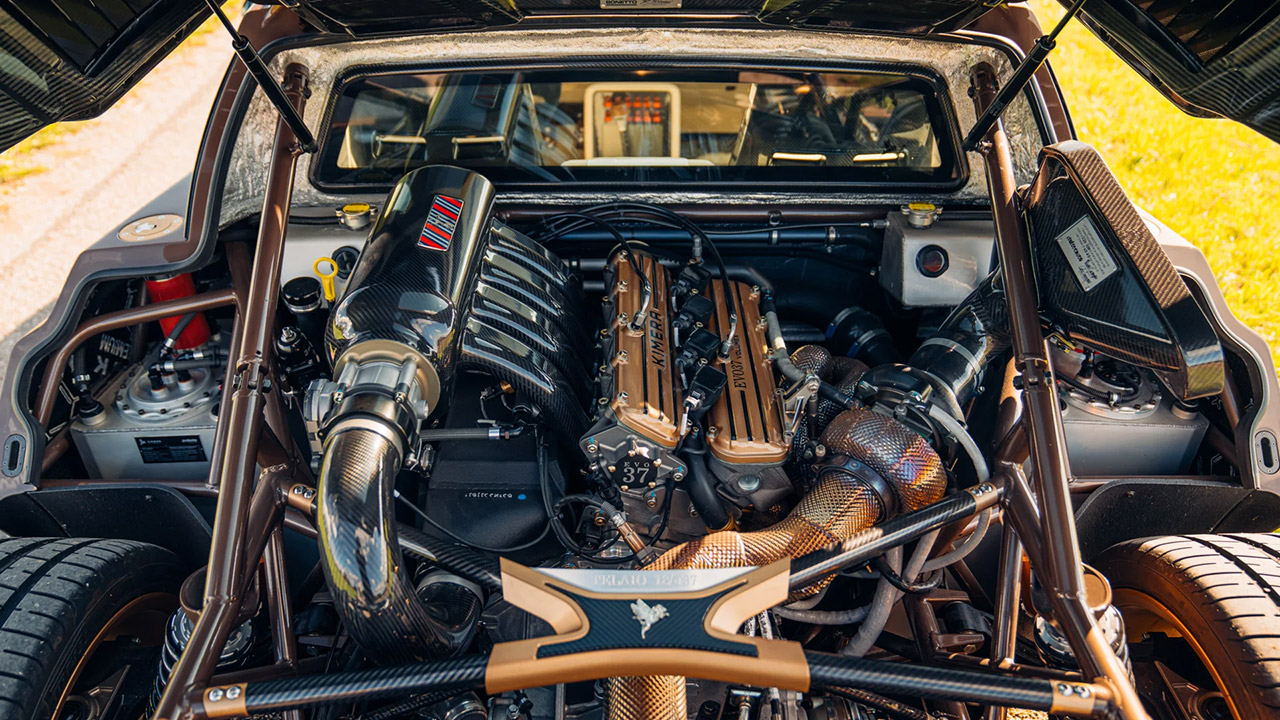
Four decades after Walter Röhrl and Markku Alén drove Lancia’s Rally 037 to the 1983 World Rally Championship, a small Italian workshop in Cuneo has given that last rear-drive title winner a second life. Kimera Automobili, run by former rally driver Luca Betti from Villa Kimera about 100 kilometers south of Turin, limited the EVO37 to 37 cars. Number 018 now sits in Broad Arrow’s catalog as lot 158 for the Zoute Concours Auction on Friday, October 9, 2026, at Approach Golf in Knokke-Heist, Belgium.
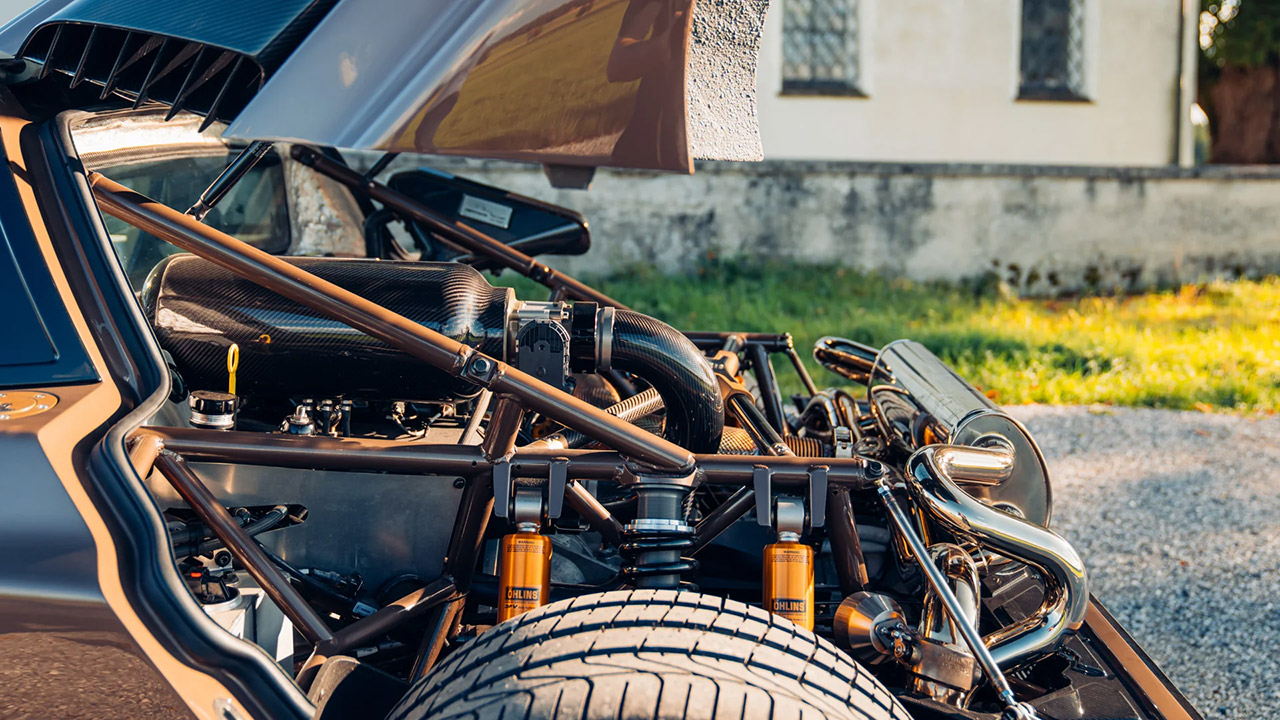
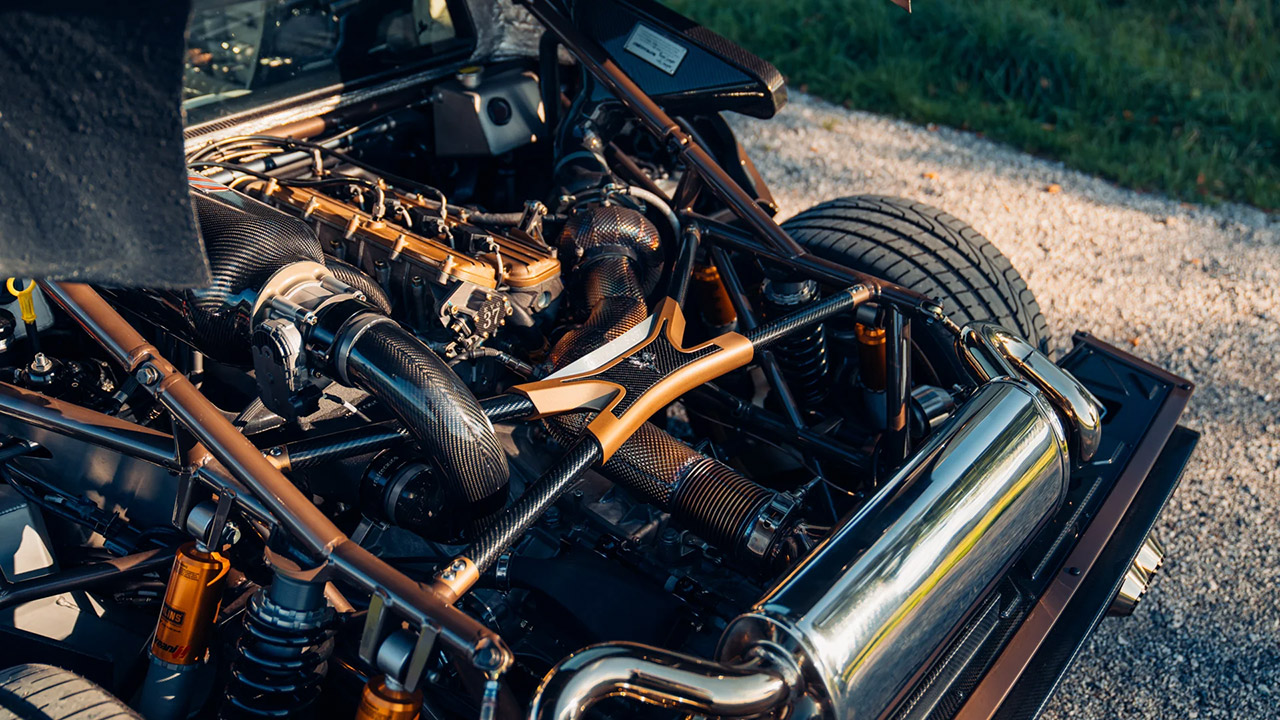
Kimera used the same starting point as the original manufacturer and ran with it: the donor Lancia Beta Montecarlo center section was stripped, reinforced, and improved with a glossy new carbon-fiber shell. Behind all of this was a crew that knew what they were doing, including Sergio Limone, the man who had led the 037 and Delta S4 to great success, and Claudio Lombardi, Lancia’s former rally engine designer who had gone on to do the same for Ferrari in F1, both of whom gave the project their approval. The bodywork was then bolted to the chassis, and Italtecnica created a brand new 2.1 liter, 16 valve four-cylinder engine from the ground up. They preserved the 037’s supercharged configuration but added a turbocharger, resulting in a snappy 505 PS and 550 Nm of torque sent to the rear wheels via a fast six-speed Dana Graziano manual gearbox. The top speed is rated as 310 km/h, with a 0-100 km/h time of just 3 seconds, which is not bad. The vehicle features Öhlins double-wishbone suspension and Brembo carbon-ceramic brakes with four-piston calipers for stopping power.
CUSTOM MUSTANG RACE CAR – This LEGO Speed Champions Ken Block’s ’65 Ford Mustang Hoonicorn V1 (77262) building toy for boys and girls ages 9 years…
AUTHENTIC DETAILS – Builders will recognize cool features from the car’s debut in the 2014 Gymkhana SEVEN film, including exposed velocity stacks on…
KEN BLOCK MINIFIGURE – The included Ken Block minifigure features a Hoonicorn hat and jacket, plus an extra helmet accessory for added play value
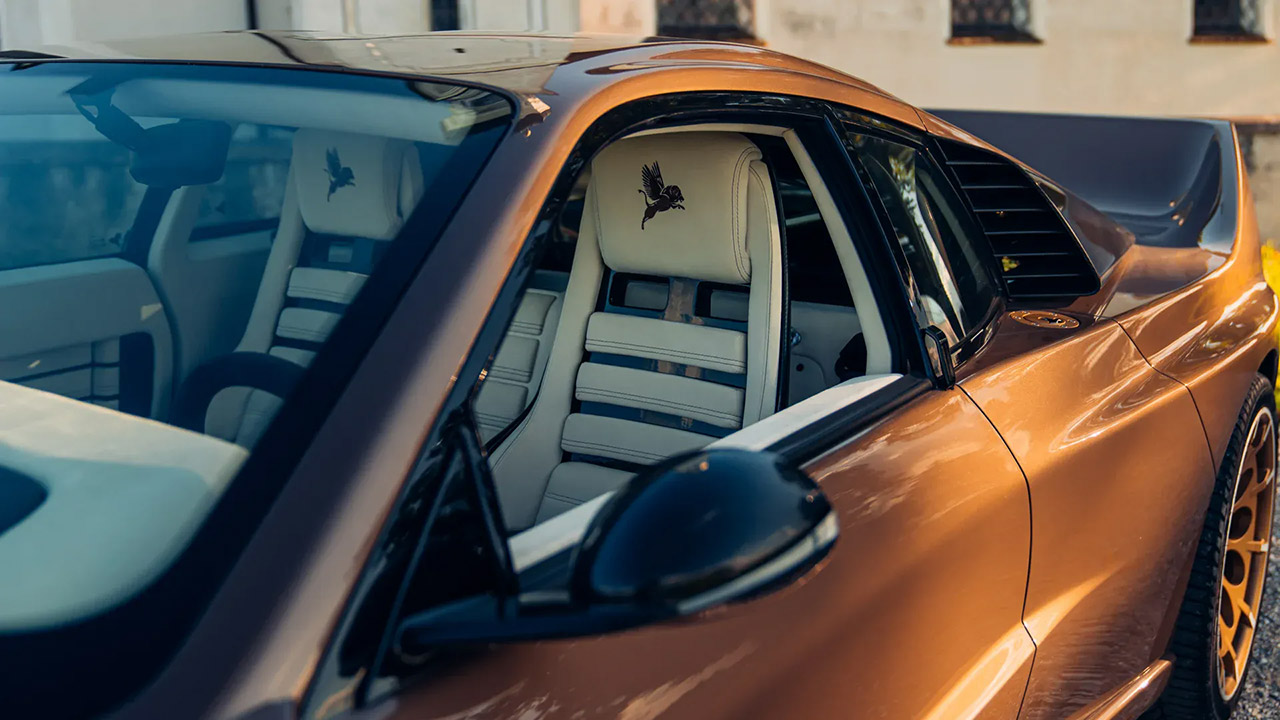
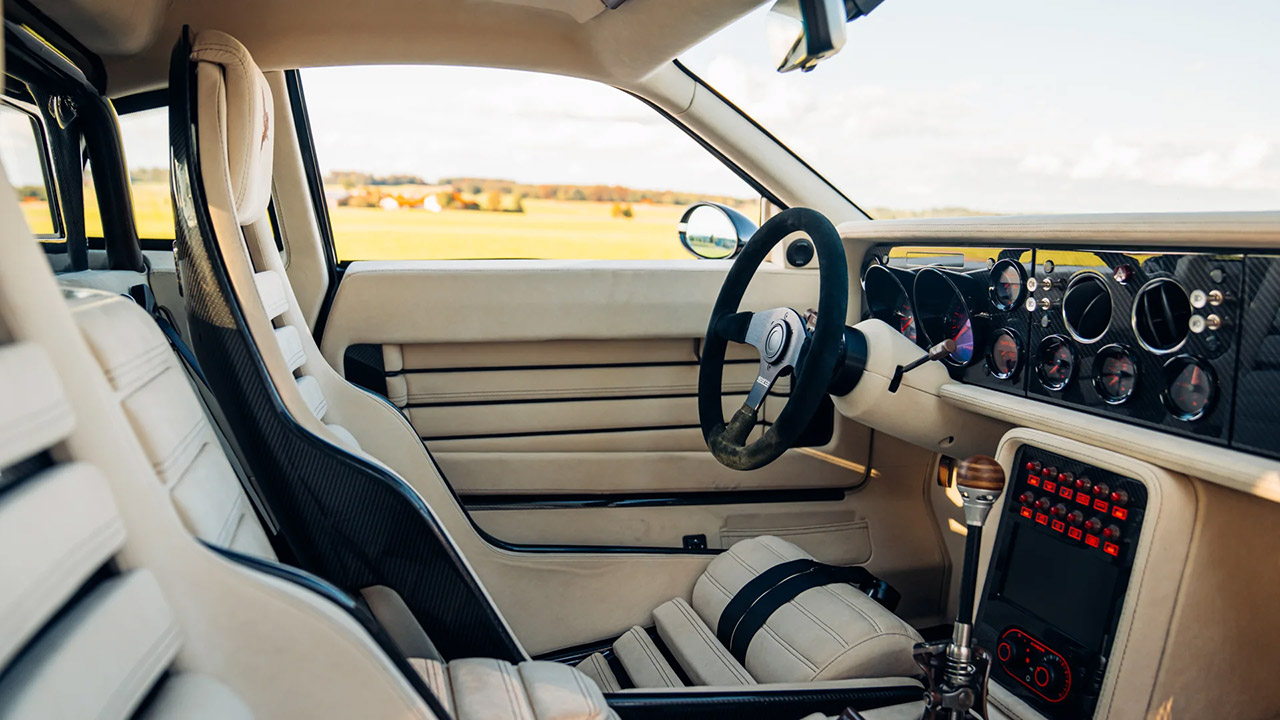
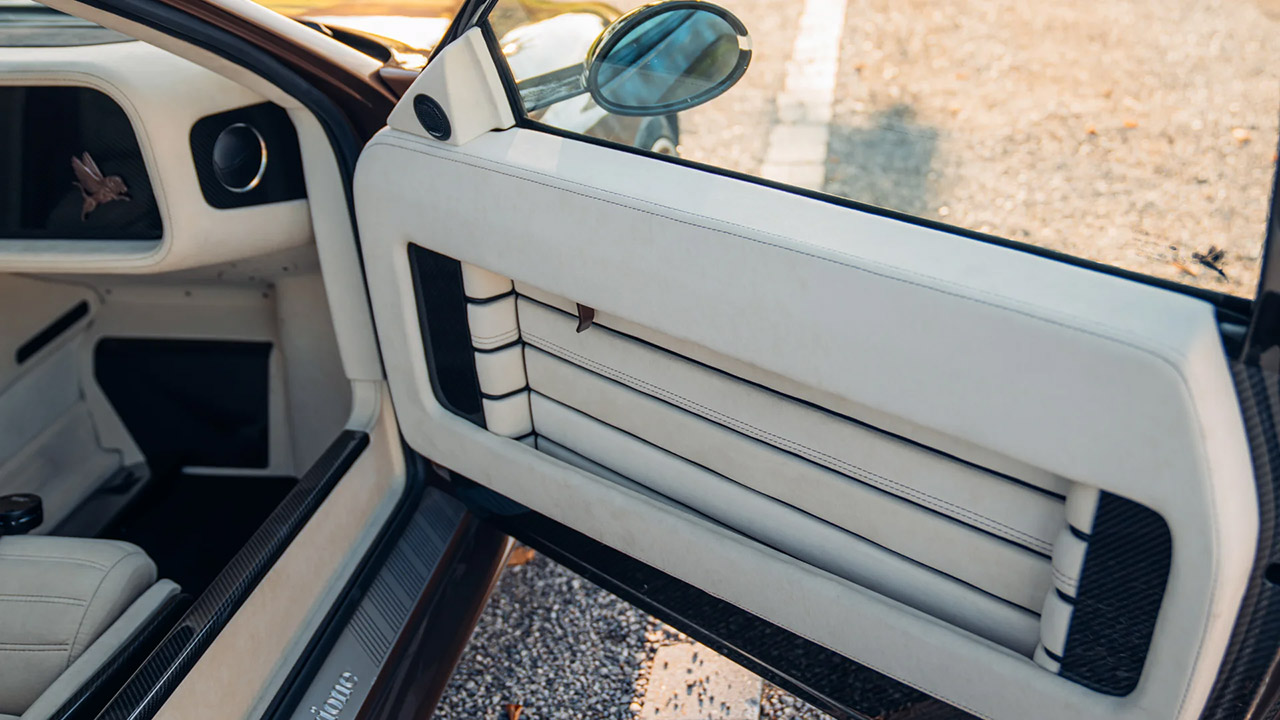
This vehicle left the workshop in March 2025 and has since traveled a total of 237 kilometers. Kimera’s Luci del Bosco paint job is a deep, rich metallic brown inspired by the old Lamborghini Miuras and Countachs. The gold wheels and beige leather upholstery over carbon fiber chairs give the cabin a relaxed feel, while the exposed gearlever is adorned with a wooden gear knob. LEDs light the road up front, and there’s air conditioning, ABS brakes, a digital rear view camera, and parking sensors to keep things polite without interfering with the exposed carbon, which is exactly what you want to see.
When this project first got off the ground in 2021, the asking price ranged between €450,000 and €480,000. Since then, the market has moved on, and Broad Arrow thinks that this particular specimen, number 018, is now valued between $950,000 and $1,150,000. Kimera has informed the Broad Arrow team that they will gladly assist with import and registration if the future owner is in Europe or the United States, and will even adjust the specifications to suit the buyer if they prefer something different. The tax issue is equally easy; because this is a VAT-qualifying sale, both the hammer price and the buyer’s premium are subject to tax.
The auction of this car will take place on October 9, 2026 as part of the Zoute Grand Prix Car Week, with a public viewing on the 7th and 8th and bidding beginning in the afternoon of the ninth. It’s a rare opportunity to own an original 037 Stradale that is this new and in this condition, and if that’s not enough, Kimera is still willing to re-spec the thing if the buyer has any other ideas. [Source]
Renault is bringing one of its most recognisable performance cars into the electric era with the Renault 8 Gordini Concept, a two-seat electric coupé inspired by the rear-wheel-drive icon that debuted in 1964.
The concept combines the visual language of the original R8 Gordini with a much more aggressive modern design. It has a low, wide stance, motorsport-inspired proportions and a 270hp electric motor. Renault says the project is part of its wider effort to revisit important models from its 128-year history through one-off creations.
Renault unveiled the concept on September 24 at Renault Carwalk, and it is scheduled to appear at the Paris Motor Show from October 12 to 18.
The classic Gordini gets a radically different electric makeover
The original Renault 8 Gordini arrived in 1964 with a 95hp rear-mounted engine and rear-wheel drive. It became known for delivering racing-inspired performance in an affordable package and served as a training ground for drivers including Jean Ragnotti. Its distinctive double white stripe eventually became a defining visual feature.
Advertisement
The new concept keeps the rear-wheel-drive character but replaces the petrol engine with a 270hp electric motor. Measuring 4.12 metres long, 1.88 metres wide and 1.27 metres tall, the coupé sits on 19-inch front and 20-inch rear wheels. Its proportions are deliberately closer to a modern rally car than the four-door original.
Renault 8 Gordini Concept
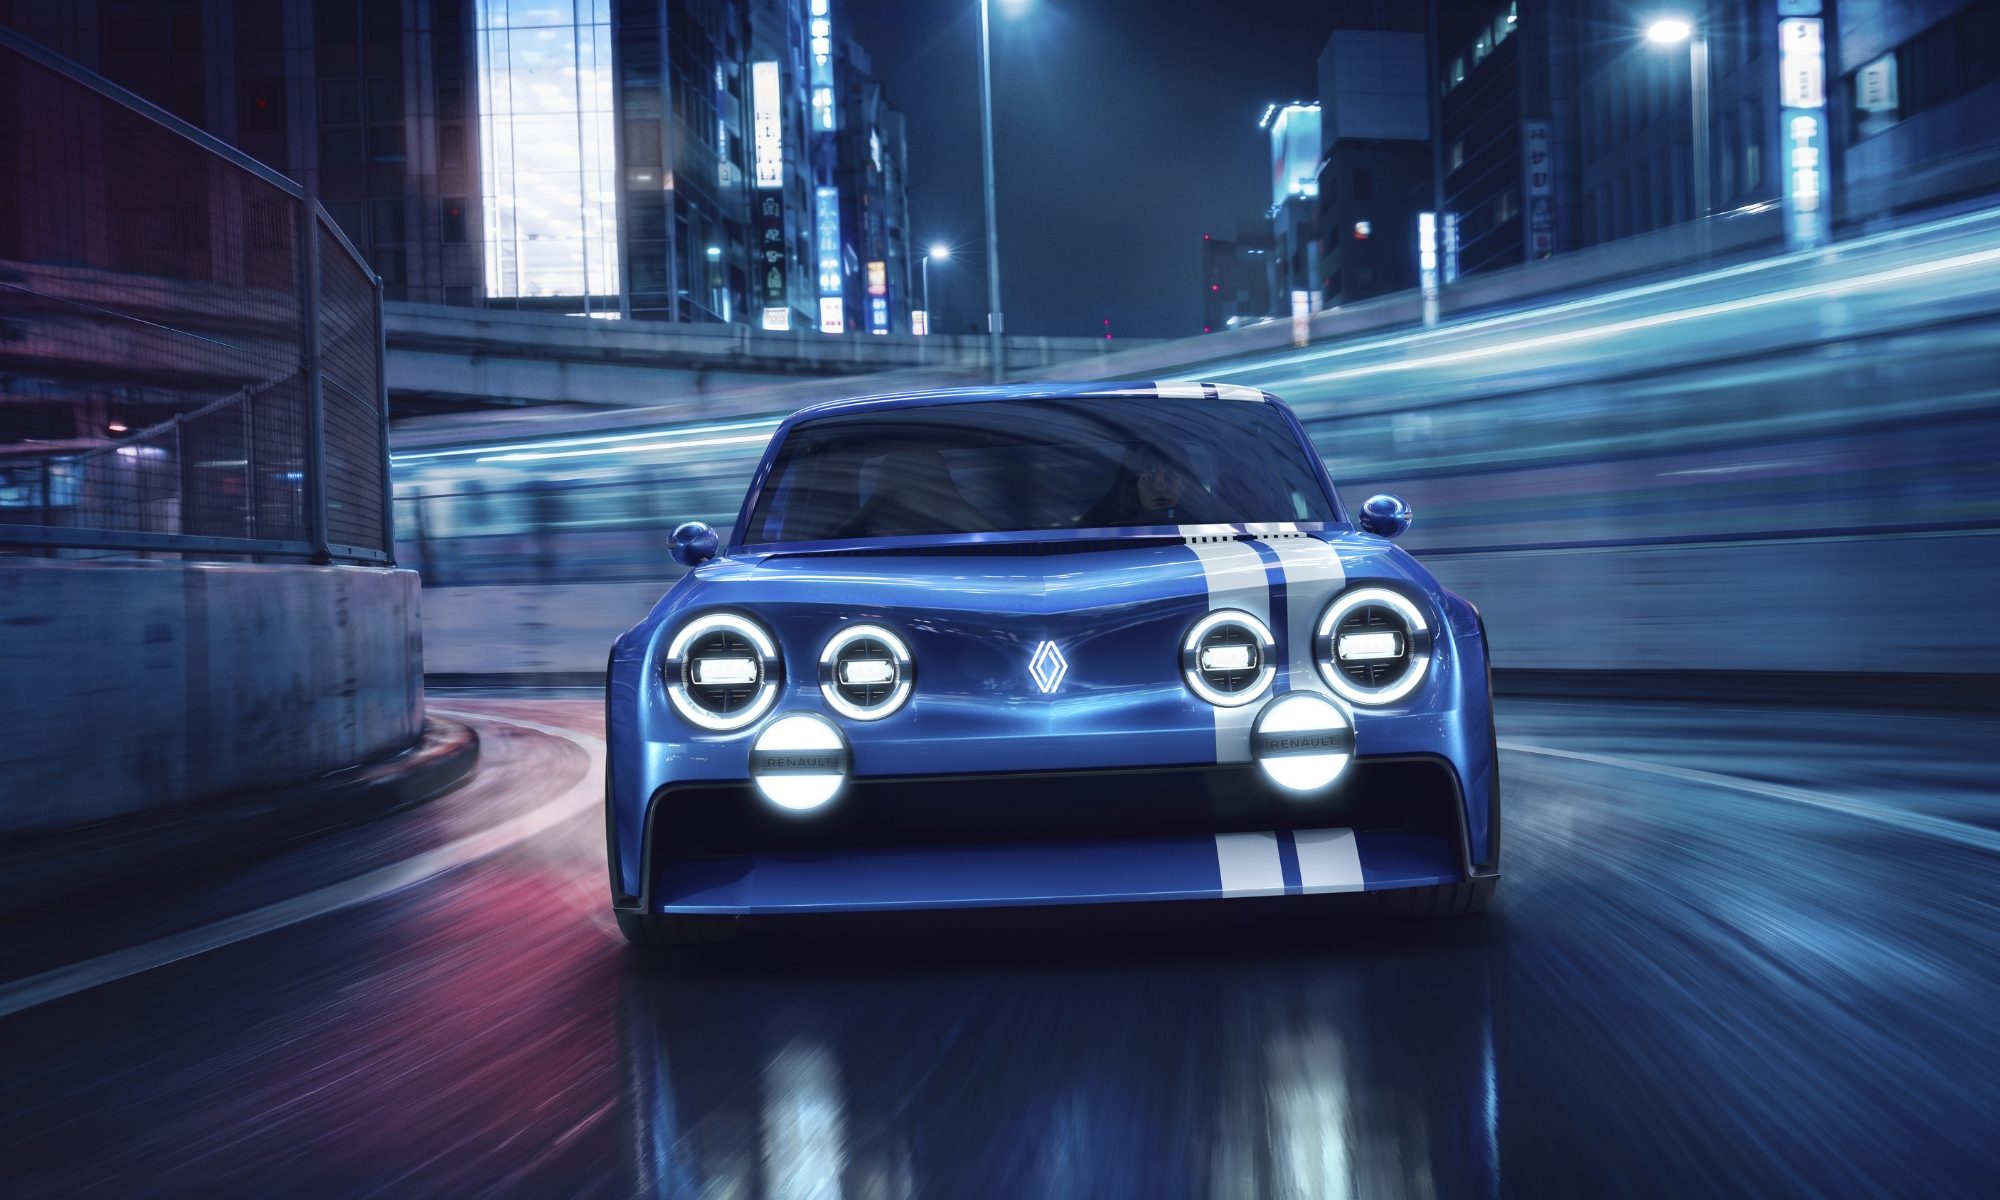
Renault has also carried several familiar details into the new design. The car gets six round headlights, squared-off wheel arches, a modernised Gordini badge and the iconic double white stripe. The stripe is no longer simply decorative, with Renault incorporating it into various structural and design elements of the car.
The design was created entirely in-house. More than 300 sketches were submitted during an internal Renault Design competition before two proposals were developed into scale models and combined into the final concept.
A two-seat EV focused on driving rather than practicality
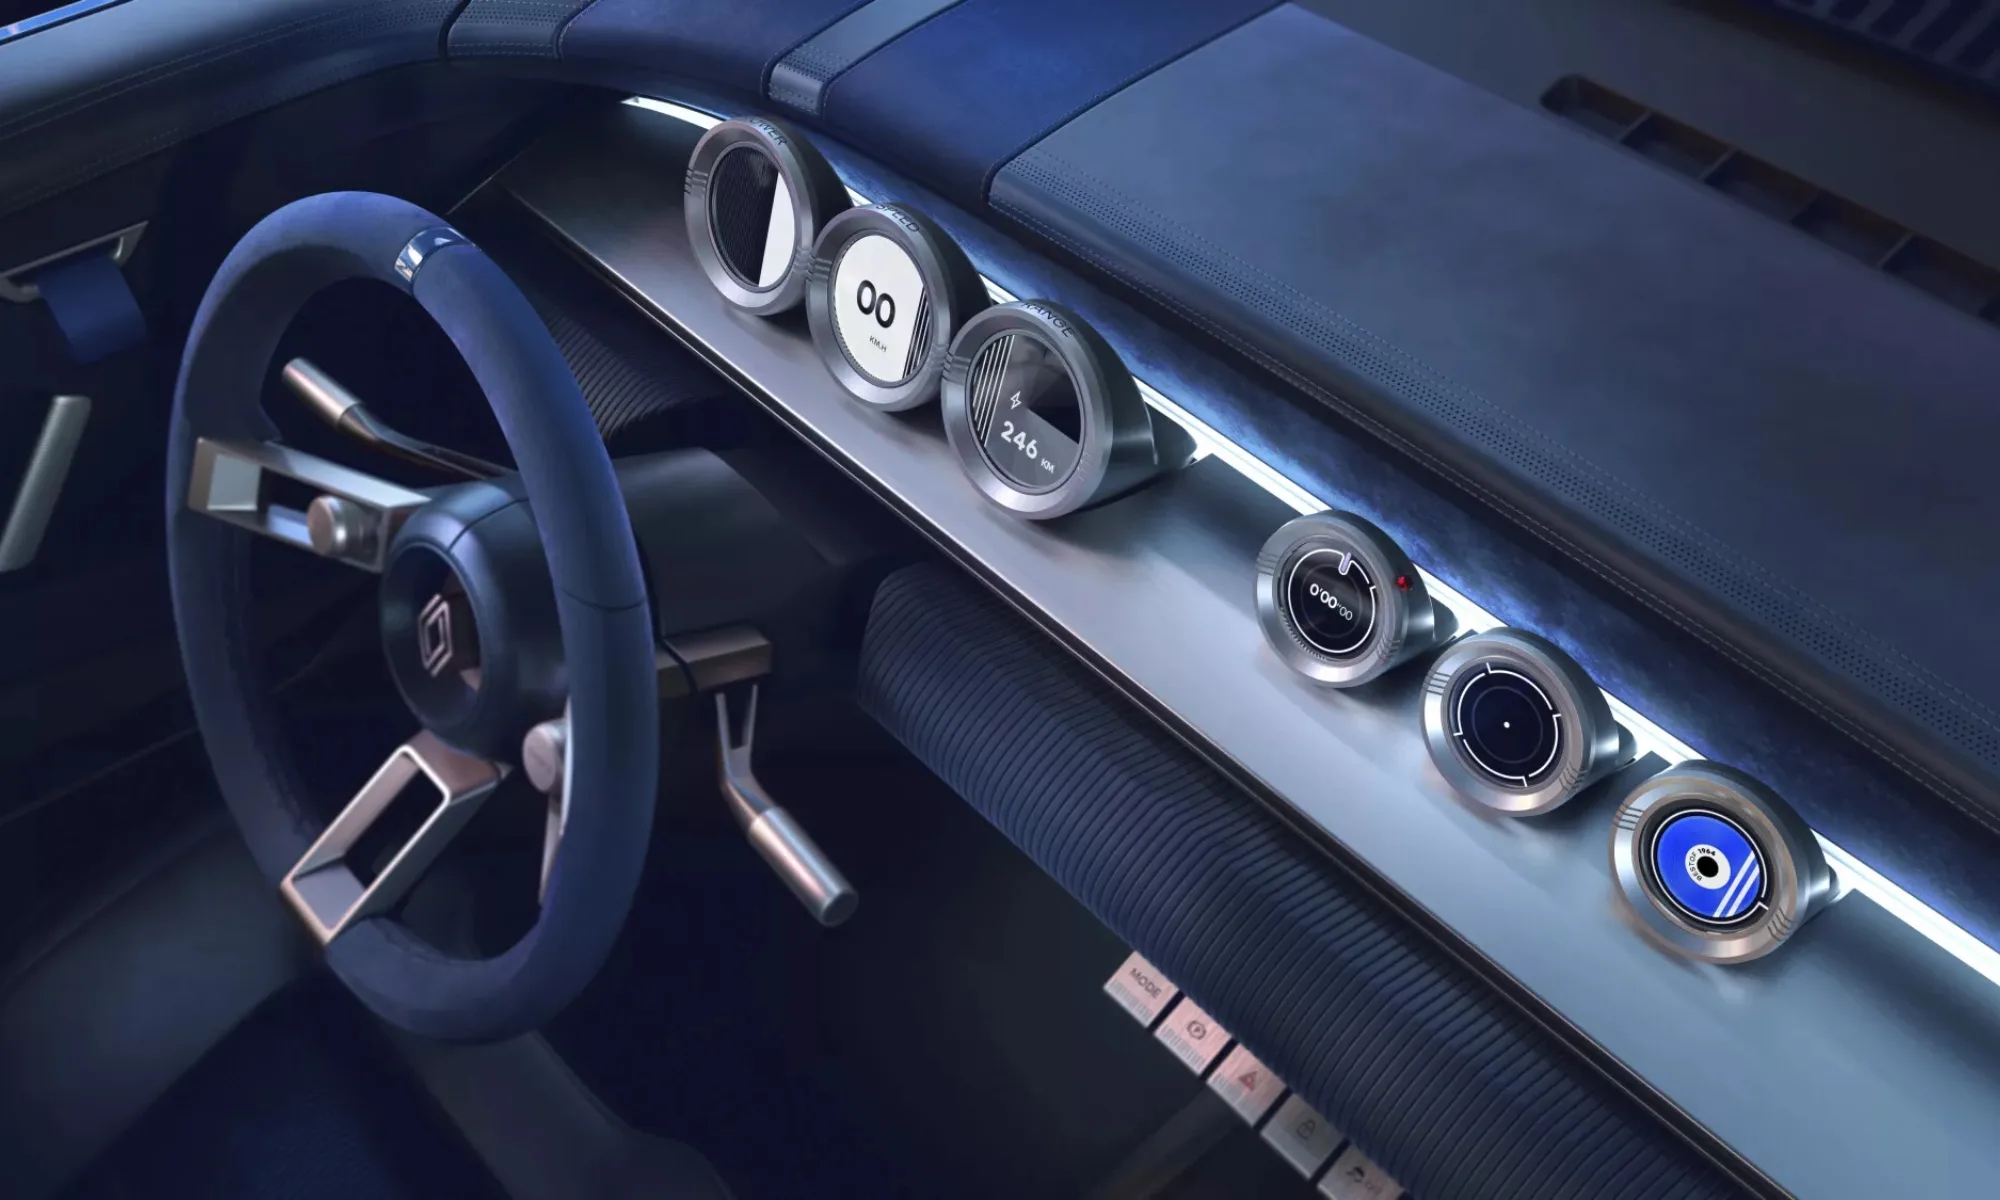
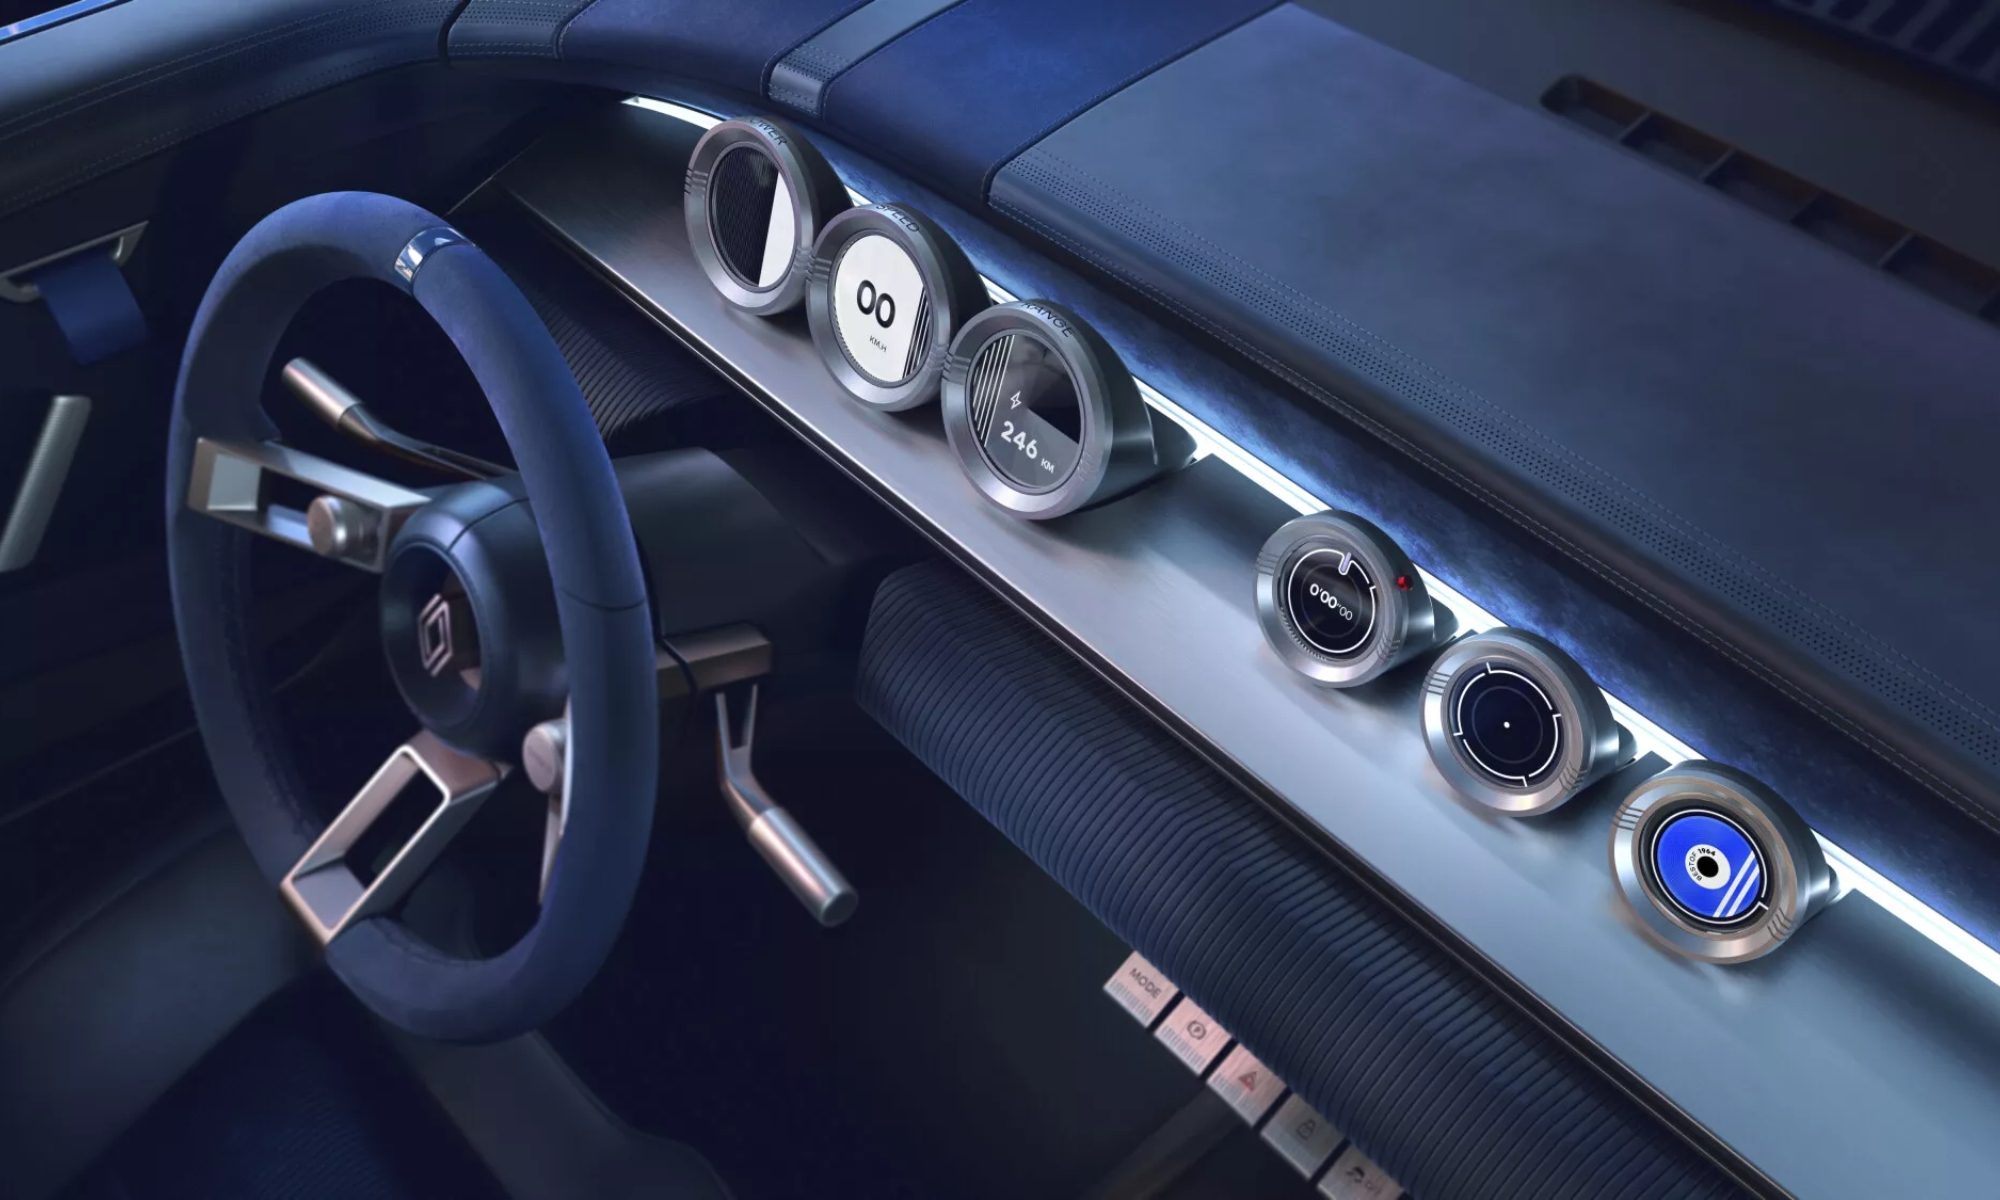
Inside, Renault has taken a similarly minimalist approach. The cabin features brushed aluminium across the dashboard and controls, contrasted with Alcantara upholstery. Digital round displays echo the circular headlights, while bucket seats and a prominent stopwatch button reinforce the car’s motorsport-inspired character.
Renault describes the concept as part of its effort to connect its heritage with future design rather than simply recreate old cars. The R8 Gordini follows previous projects including the R17 electric restomod x Ora Ïto and Renault 5 Diamant.
Advertisement
Renault 8 Gordini Concept
For now, this remains a concept car, and Renault’s media page does not confirm that it will enter production. The company does say the concept will become part of its historical collection, alongside other vehicles and archive material at the future Renault Collections museum in Flins, expected to open in around 15 months.
So while you probably won’t be ordering one from a Renault showroom anytime soon, the electric R8 Gordini shows how Renault is imagining its performance heritage in an EV era.















































You must be logged in to post a comment Login